Rivet Documentation
Rivet exports data from PostgreSQL, MySQL, SQL Server, and MongoDB to Parquet/CSV files on local disk, S3, GCS, Azure Blob Storage, or stdout.
Install from Rust: cargo install rivet-cli (crates.io name is rivet-cli; the binary is rivet). Other install options live in the repo README.
This folder contains modular guides for running exports, a complete configuration and CLI reference, an architecture overview, and the full set of architecture decision records.
Why teams pick Rivet
Three properties, each measured, not asserted:
- Source-safe under load — the batch export holds no long-running query on the source (0.00 s vs 7.7–94.6 s for the field); CDC reads the log, not your tables.
- Flat memory at any scale — a steady 57 MB peak RSS (2×–63× smaller than the field), flat from 10 k rows to a field-proven 454 M-row table with no OOM.
- CDC cost, per engine — an honest per-engine account of the one operational hazard (PostgreSQL slot retention) and why MySQL / SQL Server / MongoDB can’t fill the source disk.
Supported database versions
PostgreSQL and MySQL run the full end-to-end suite on each release; SQL Server and MongoDB carry their own scope and CI coverage:
| Engine | Versions covered by CI matrix |
|---|---|
| PostgreSQL | 12, 13, 14, 15, 16 |
| MySQL | 5.7, 8.0 |
| SQL Server | 2022 |
| MongoDB | 4.4, 5.0, 6.0, 7.0, 8.0 (dedicated nightly matrix; batch + CDC) |
See reference/compatibility.md for the version-support policy, the exact test matrix, and notes on engine-specific features.
Start here
Pick one — they’re ordered shortest to deepest. Read top-to-bottom, then come back to this index when you need a reference.
| Guide | What it gives you | Time |
|---|---|---|
| Who is Rivet for? | Yes / no fit-check with named alternatives (Debezium / Airbyte / Fivetran / dbt / DuckDB) | ~1 min |
| Getting Started | Install + your first export from a real table | ~3 min read · ~5 min hands-on |
| Concepts glossary | One-page orientation: run_id, cursor, chunk, manifest, journal, progression | ~3 min |
| Pilot guide | Operator runbook — full flow on your own database, production-ready guardrails | 1–2 sessions |
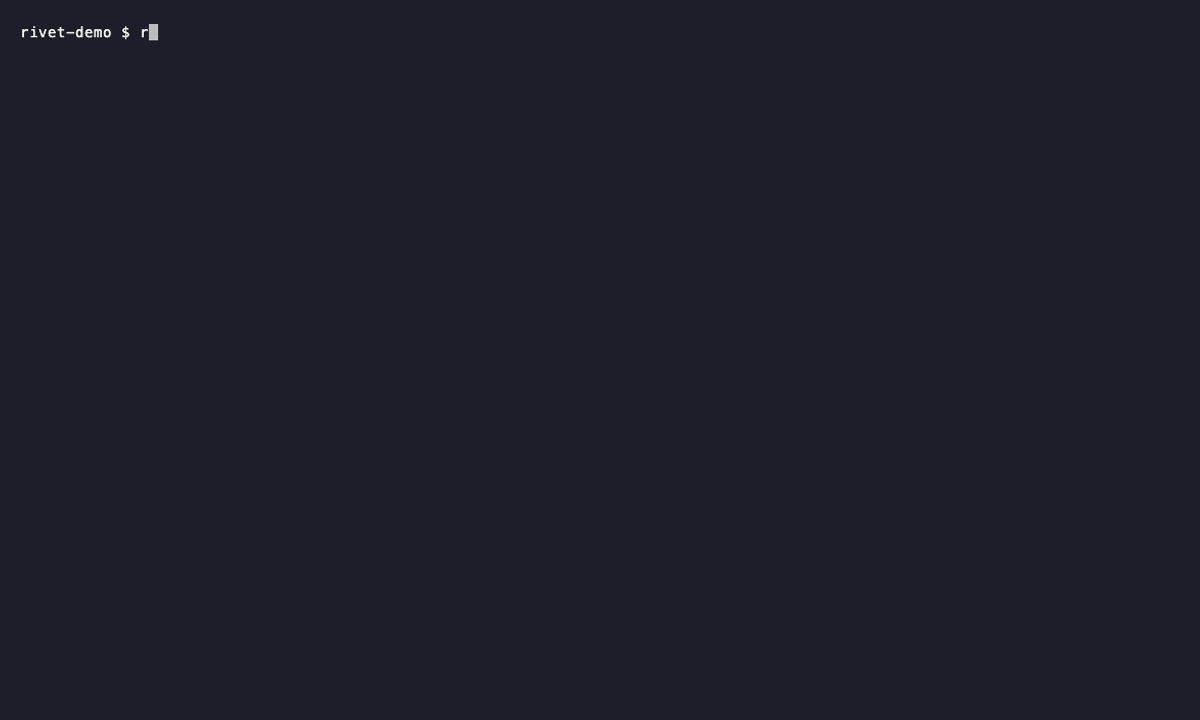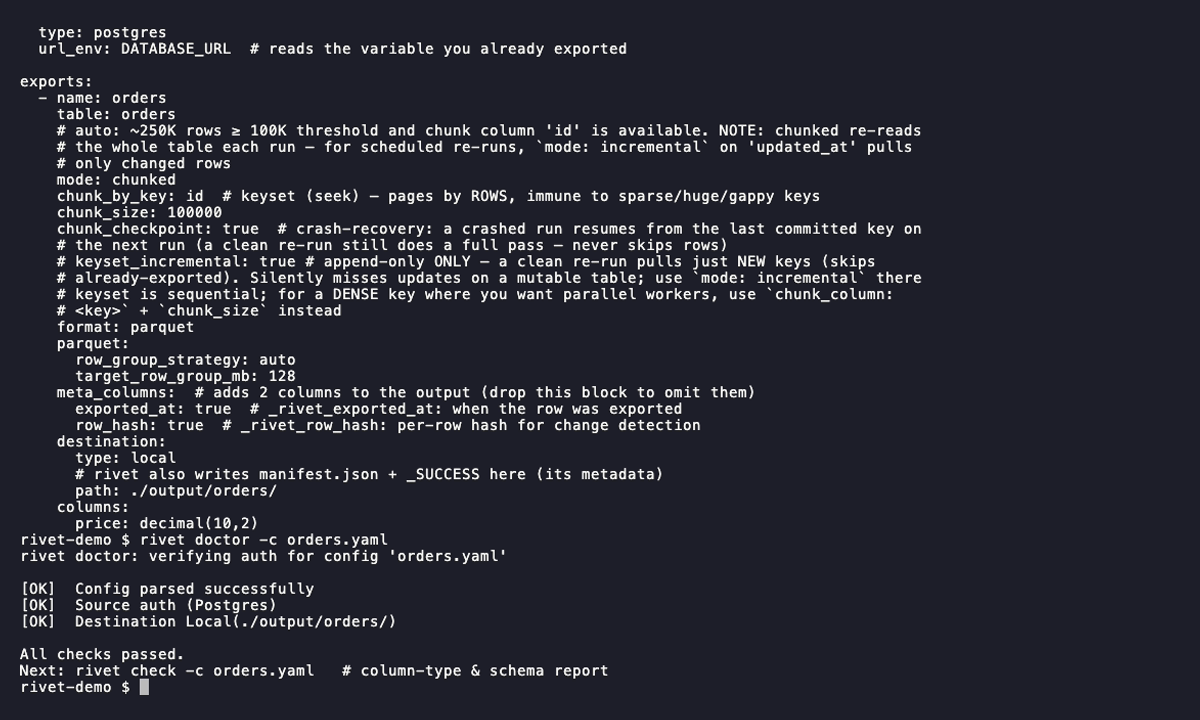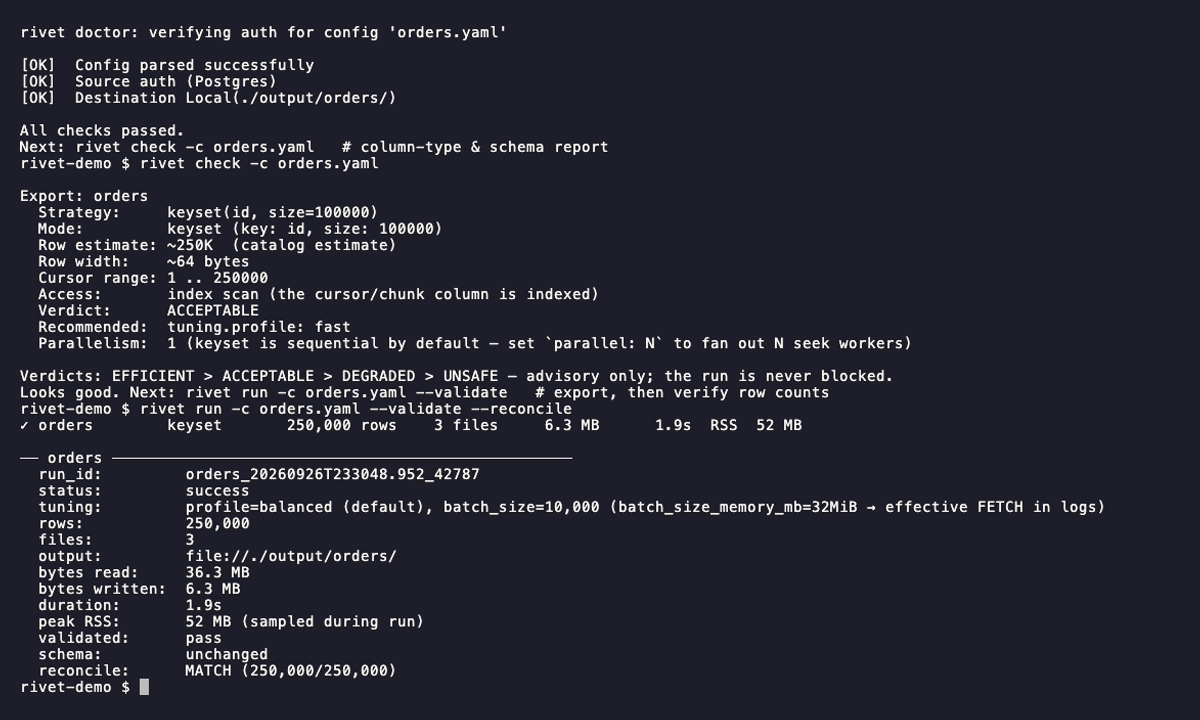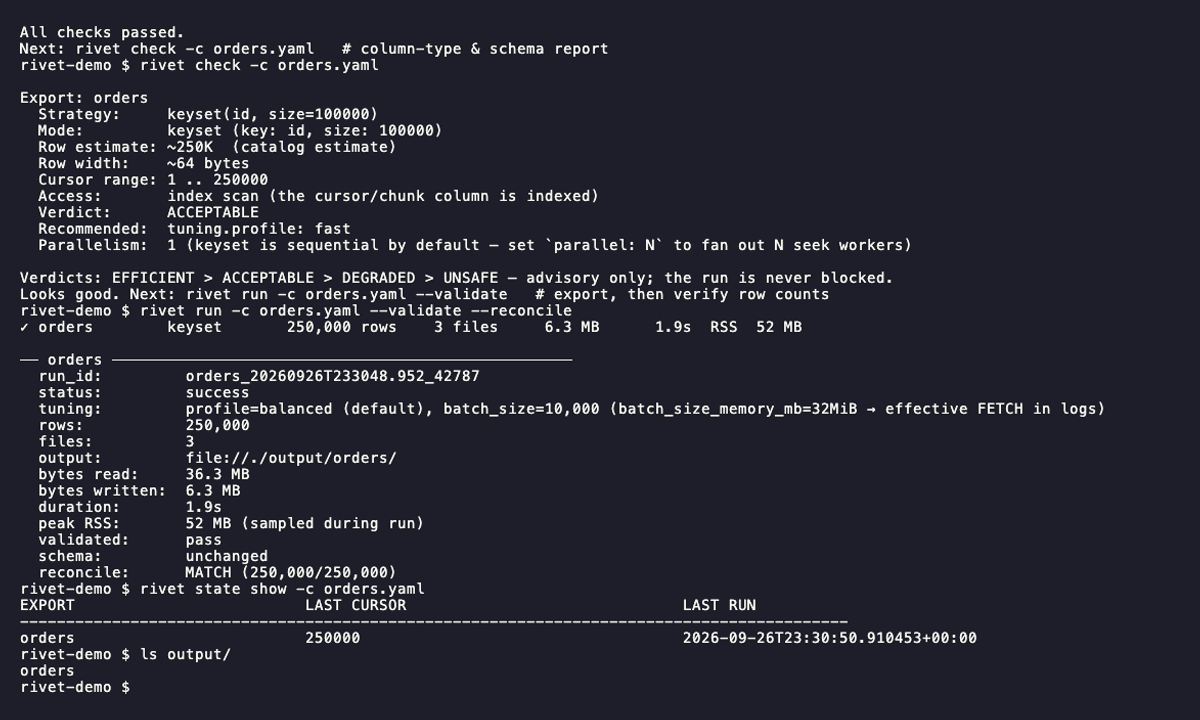
Short terminal walkthroughs in gifs/:
- gifs/basic.gif — scaffold config, preflight, run, inspect state (≈25 s)
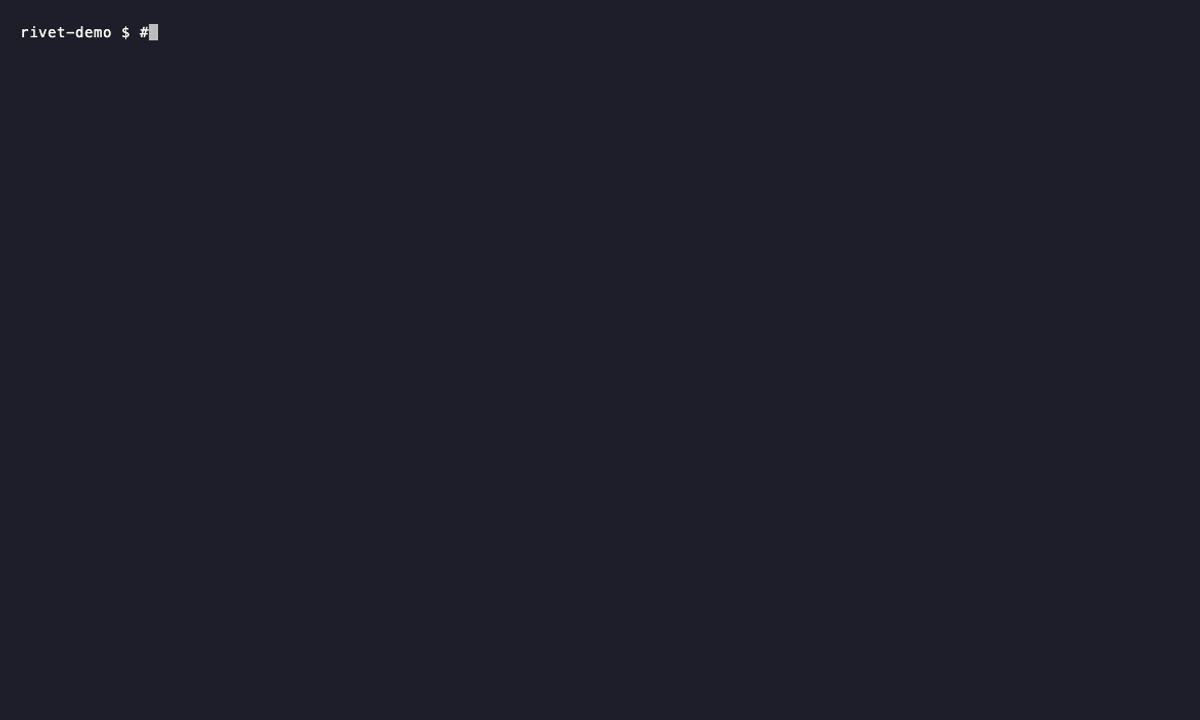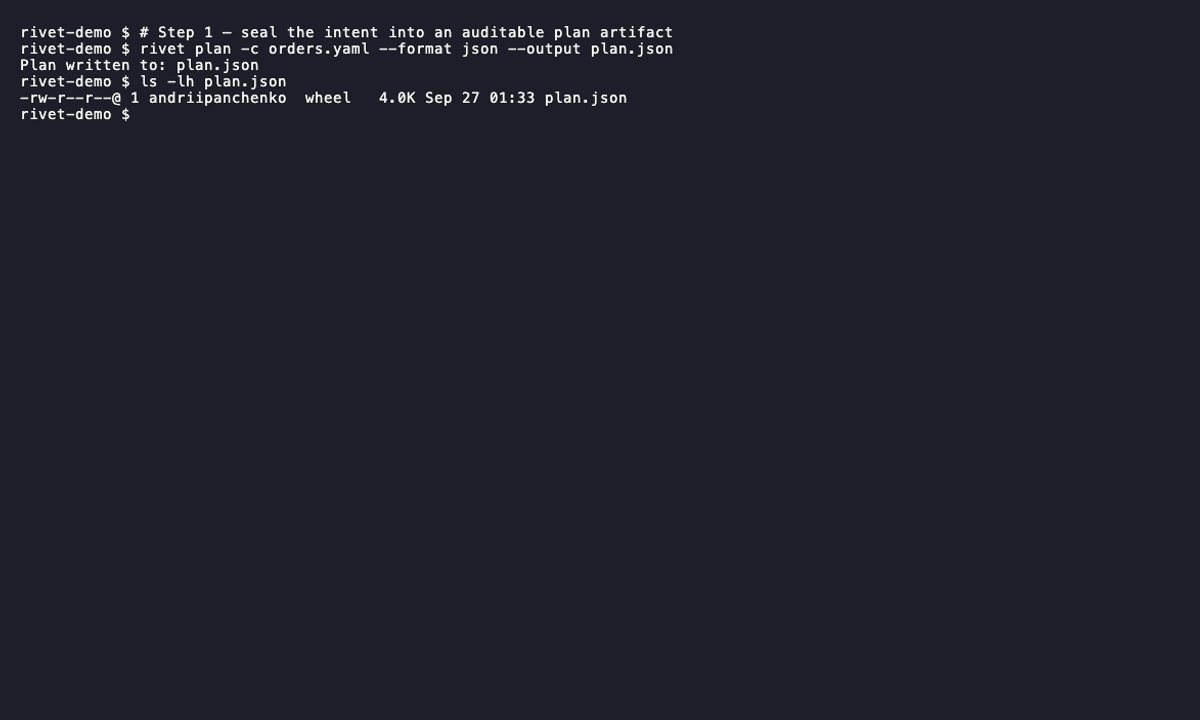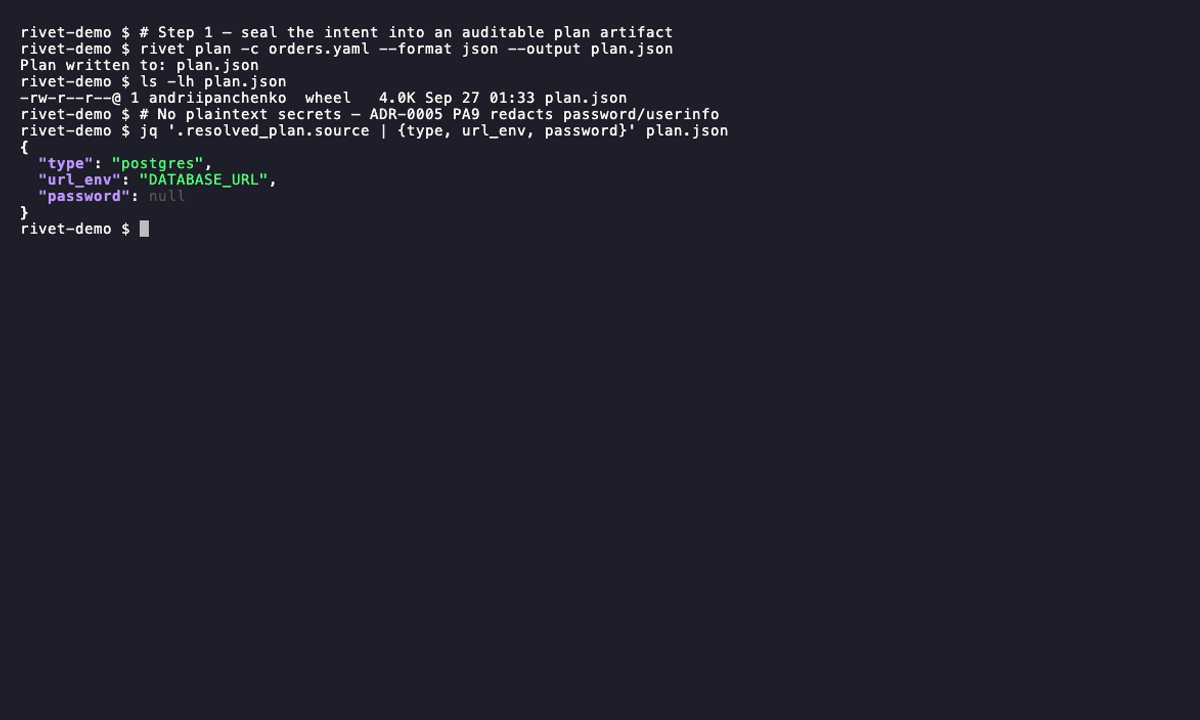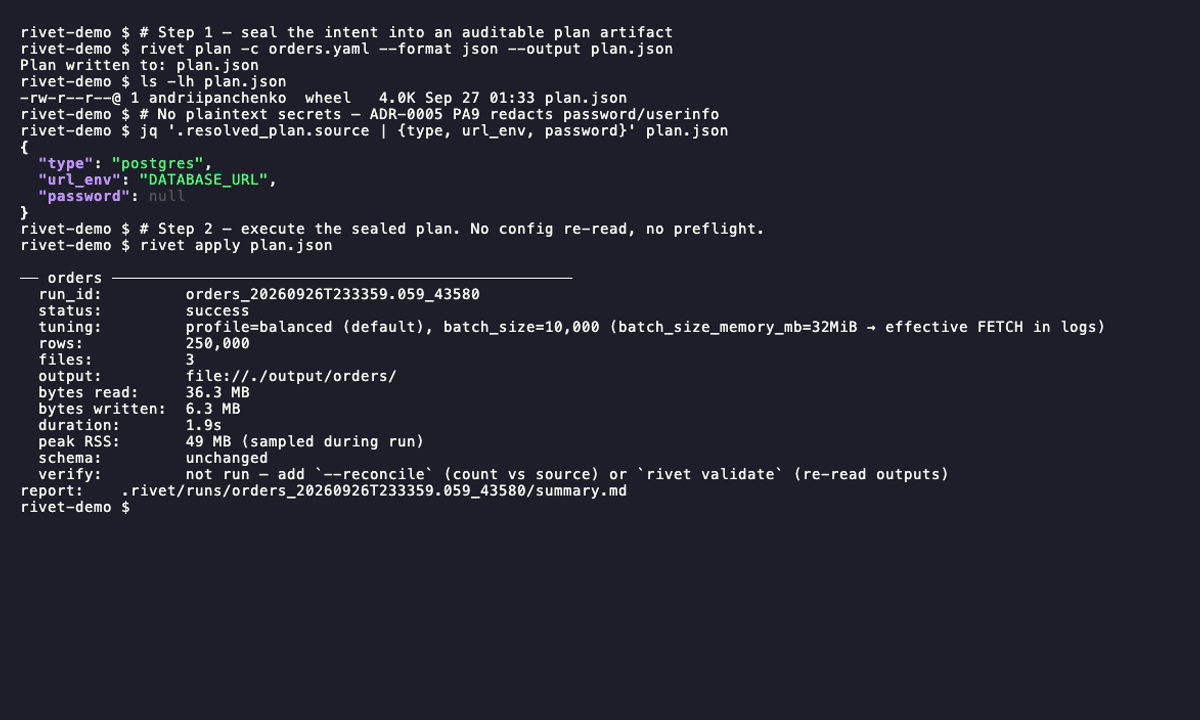
- gifs/plan-apply.gif — sealed plan/apply with credential redaction (≈20 s)
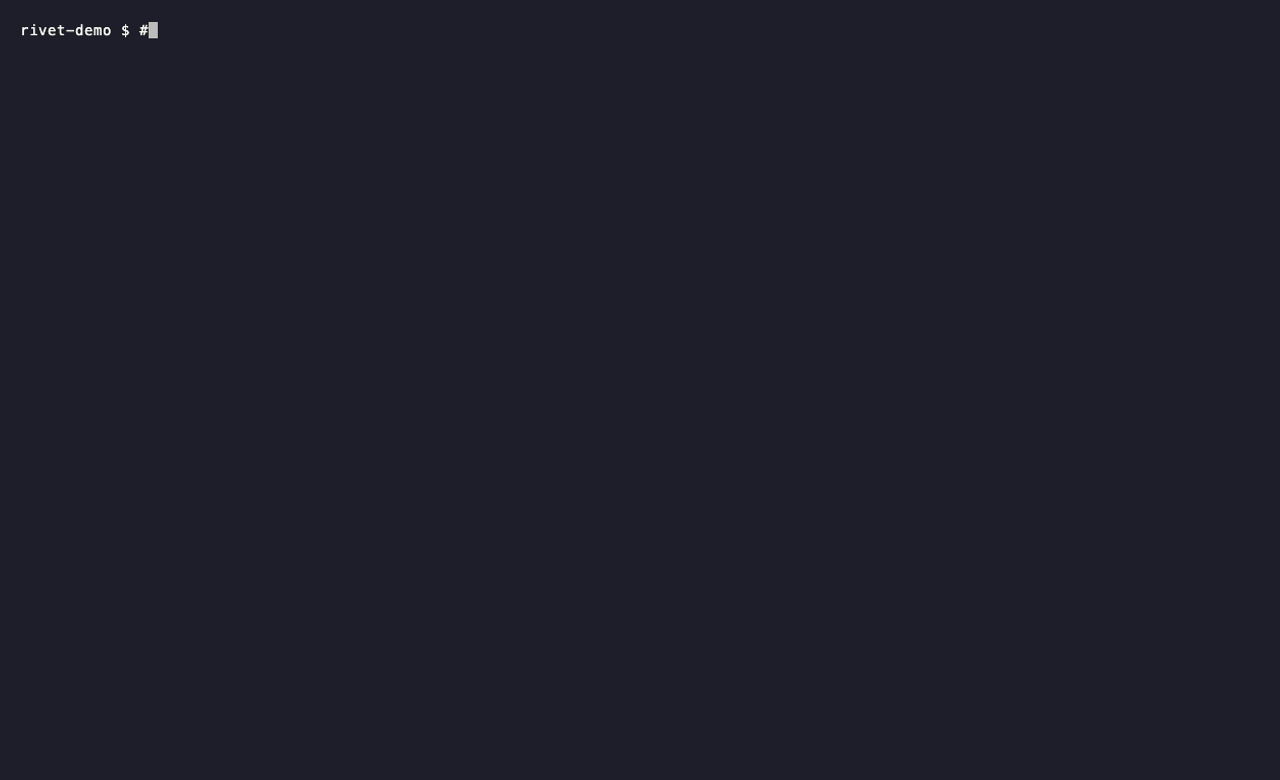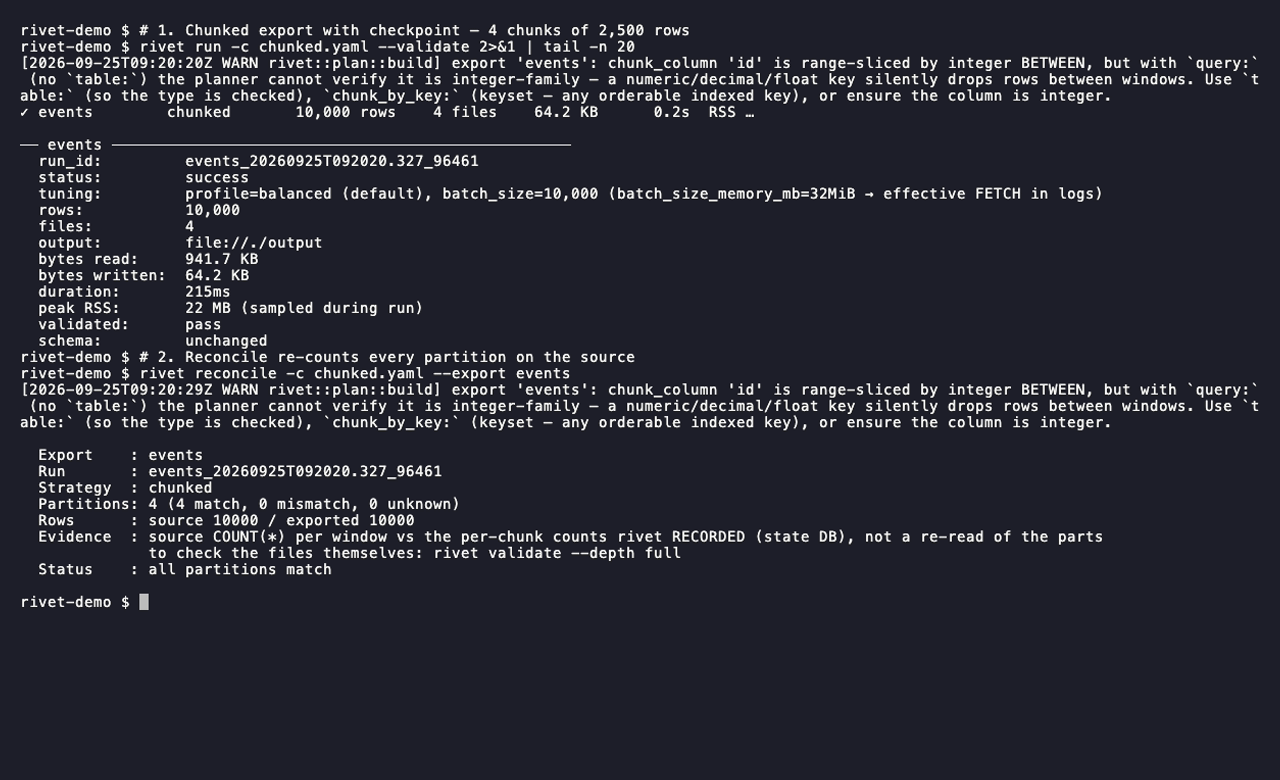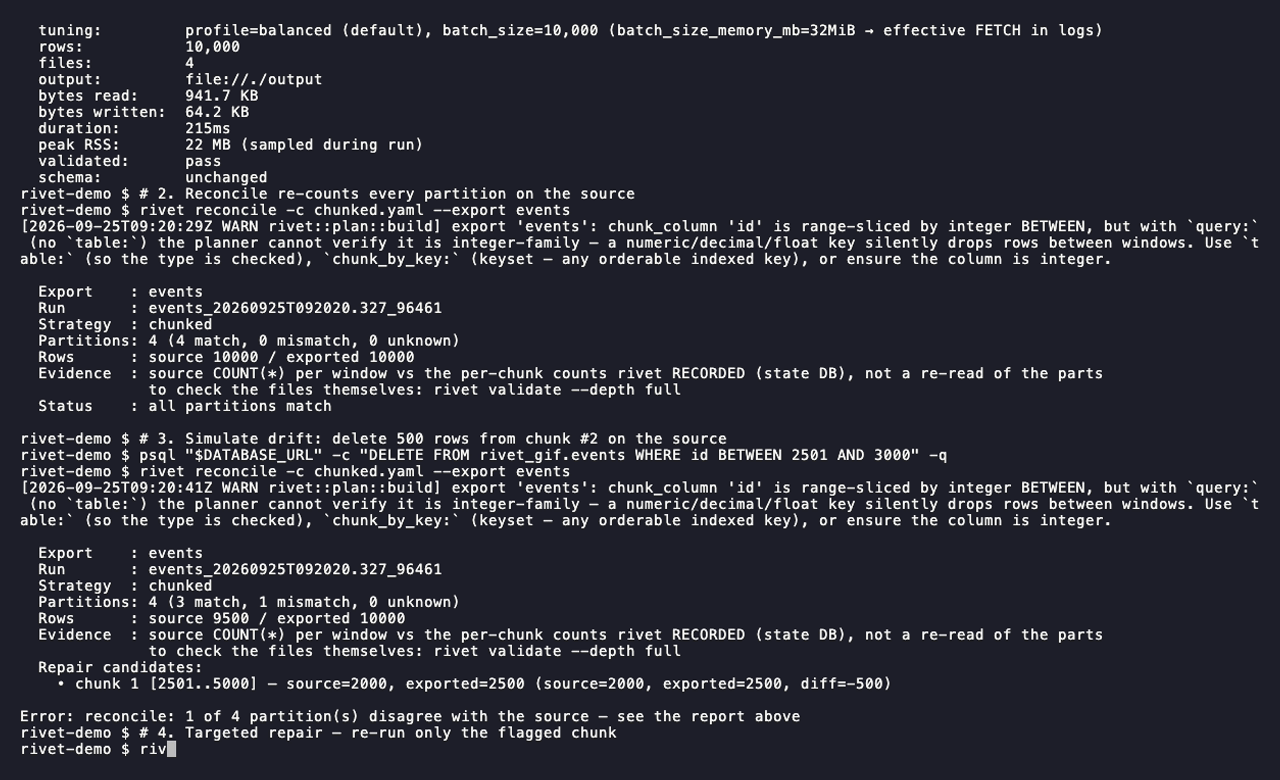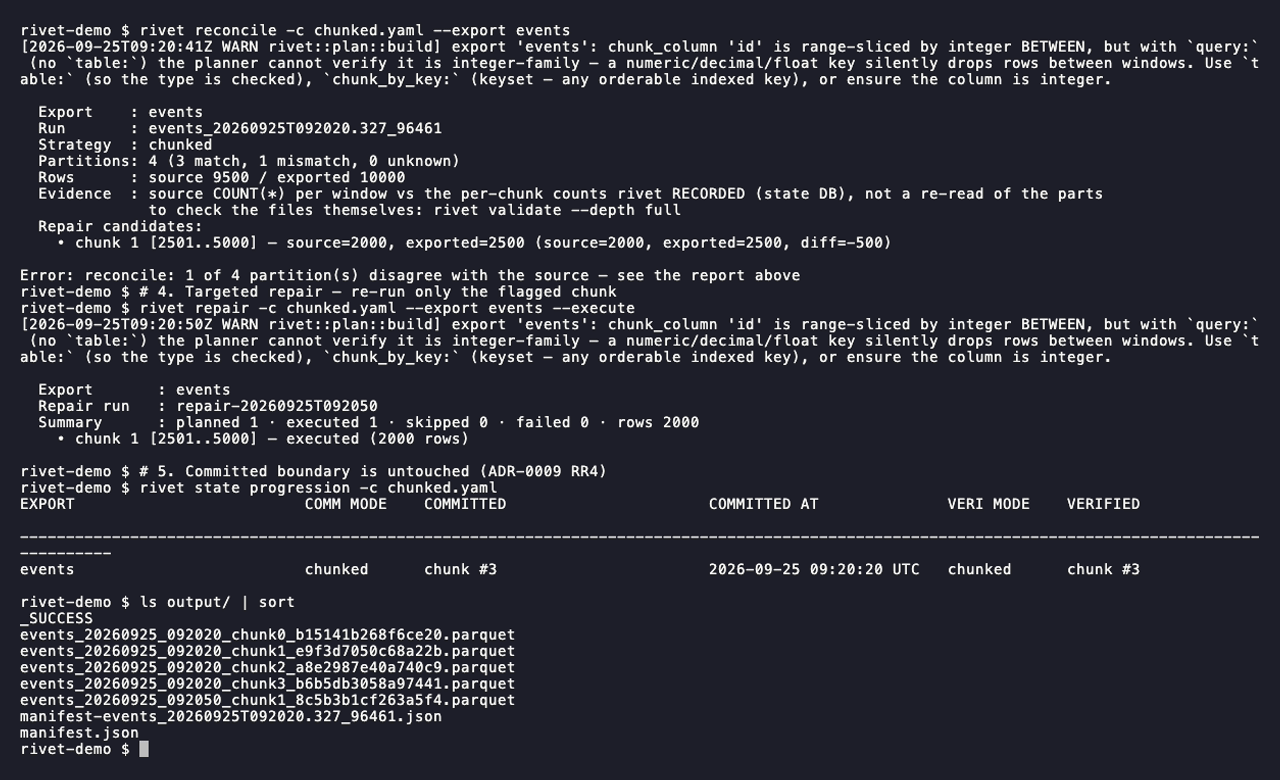
- gifs/reconcile-repair.gif — chunked + reconcile + targeted repair (≈35 s)
Export Modes
| Mode | When to Use | Guide |
|---|---|---|
| full | Snapshot the entire result set each run | modes/full.md |
| incremental | Only export rows newer than the last cursor | modes/incremental.md · composite cursor |
| chunked | Split large tables into parallel ranges by ID, or by date (chunk_by_days: 365 → one chunk per ~year, >= AND < semantics); checkpoint + --resume for crashed runs | modes/chunked.md |
| time_window | Export a rolling N-day window | modes/time-window.md |
| cdc | Stream INSERT/UPDATE/DELETE from the transaction log (MySQL binlog / PostgreSQL logical slot / SQL Server change tables / MongoDB change streams / Oracle LogMiner, preview) as typed Parquet/CSV — source-safe, at-least-once | reference/cdc.md |
Destinations
| Destination | Guide |
|---|---|
| Local filesystem | destinations/local.md |
| AWS S3 / MinIO | destinations/s3.md |
| Google Cloud Storage | destinations/gcs.md |
| Azure Blob Storage | destinations/azure.md |
| Stdout (pipe) | destinations/stdout.md |
Cloud auth & trust: cloud-auth.md — per-backend credential-flow matrix (AWS / GCS / Azure incl. SAS) · cloud-destinations.md — the cloud write trust contract (manifest, quarantine, support matrix).
Output layout
| Feature | What | Guide |
|---|---|---|
partition_by | Split rows into Hive-style col=value/ sub-folders by a date column (day/month/year); NULLs → __HIVE_DEFAULT_PARTITION__; orthogonal to mode | partitioning.md |
Reference
| Topic | Guide |
|---|---|
| Complete YAML config reference | reference/config.md |
| CLI commands and flags | reference/cli.md |
| Tuning profiles and parameters | reference/tuning.md |
rivet cdc — log-based change data capture: per-engine grants/prereqs, output shape, why it’s gentle on the source | reference/cdc.md |
MongoDB — the JSON-blob model, batch + CDC walkthroughs, source.mongo.* config, type fidelity + warehouse portability | reference/mongodb.md |
rivet init — scaffold YAML from the database | reference/init.md |
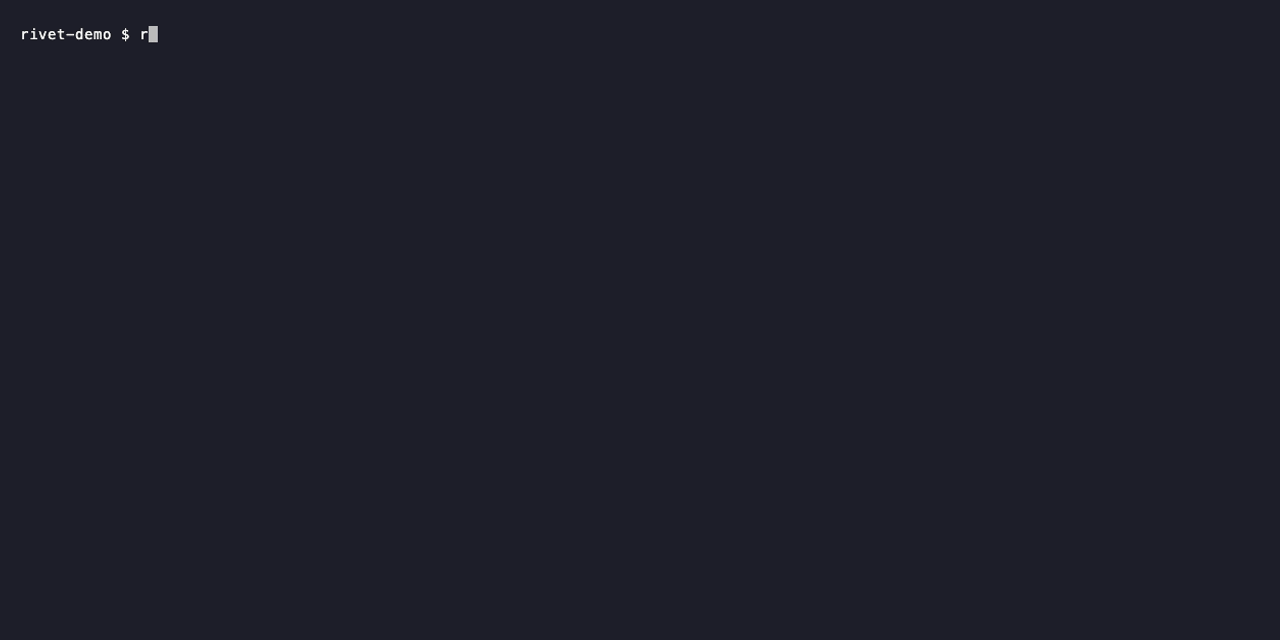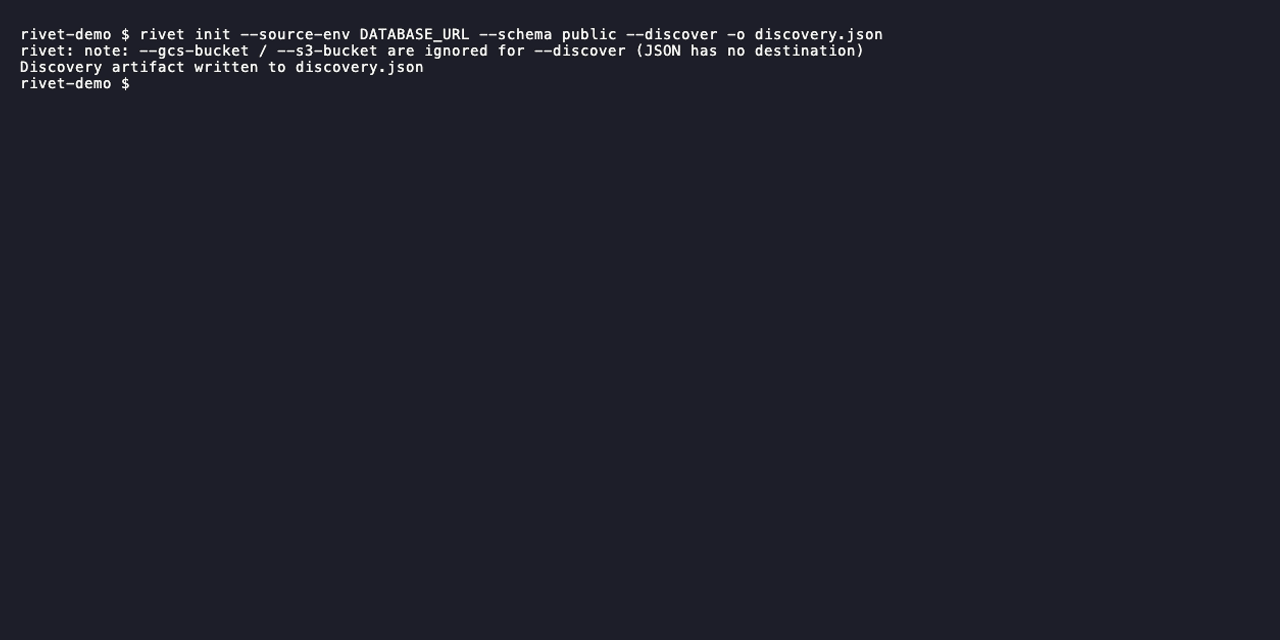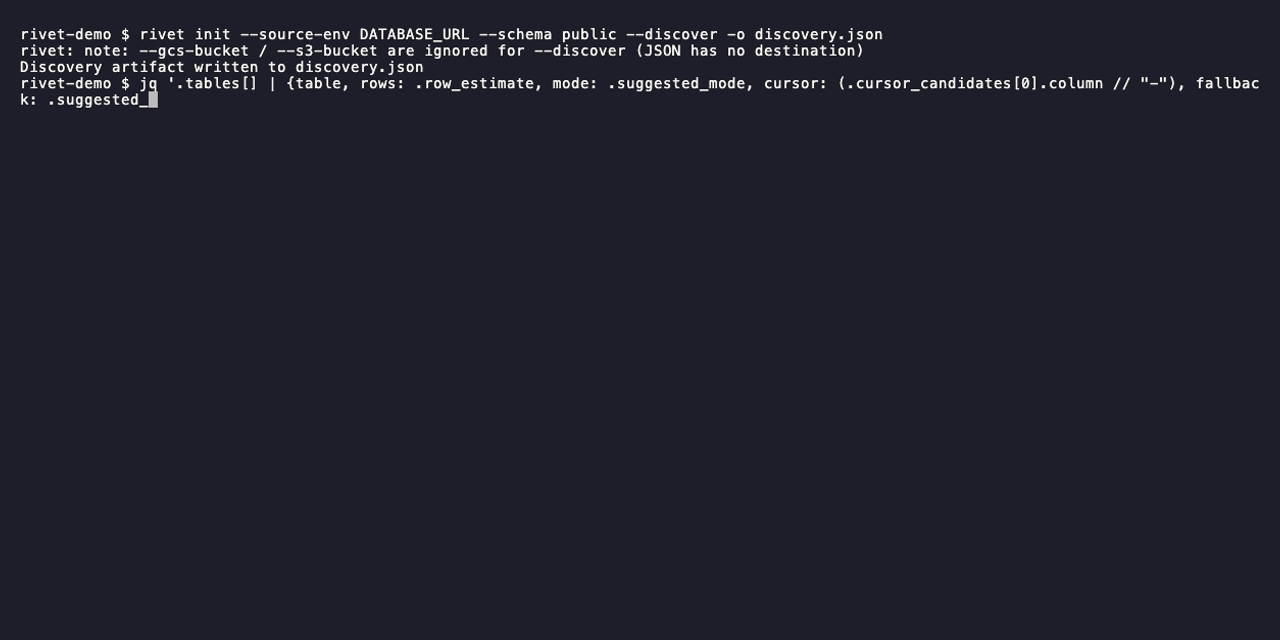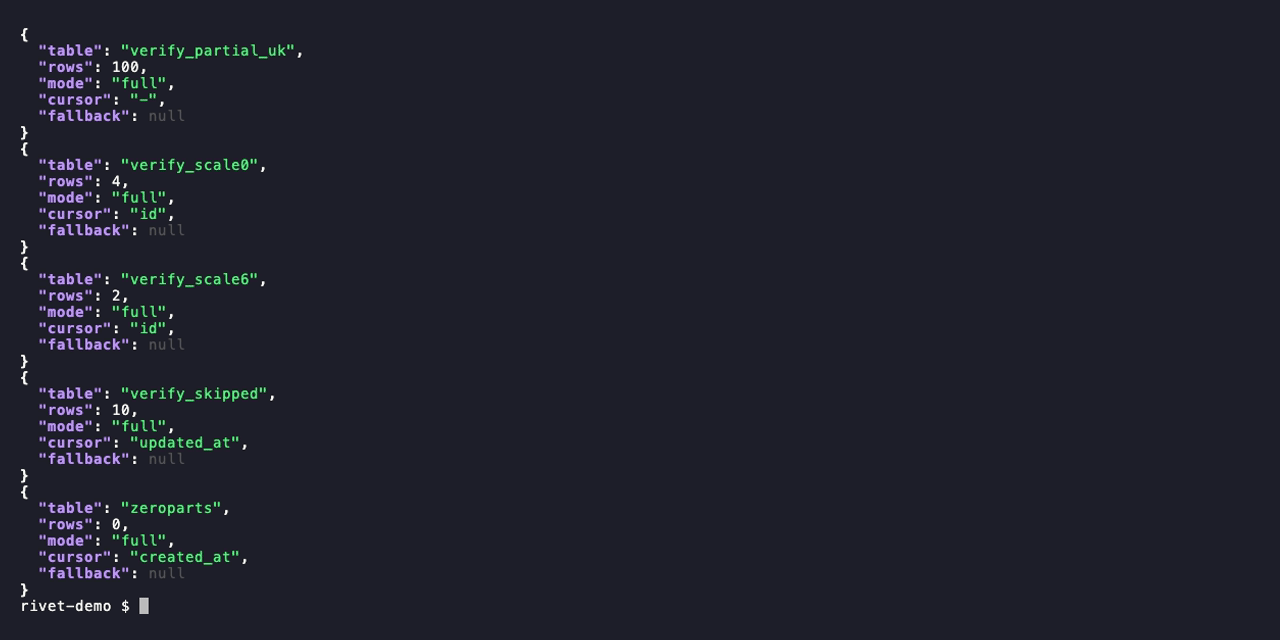
rivet init --discover — machine-readable JSON discovery artifact (ranked cursor / chunk candidates, row estimates, on-disk sizes) for automation and code review | reference/init.md#discovery-artifact—discover · gifs/discover-artifact.gif |
rivet check --type-report --target bigquery — per-column type fidelity report + warehouse compatibility (NUMERIC / BIGNUMERIC / TIMESTAMP overflow warnings); --strict exits non-zero on lossy mappings | reference/cli.md#rivet-check |
| Type mapping — per-engine source-type → Arrow/Parquet contract + warehouse-target fidelity (BigQuery / Snowflake / DuckDB / ClickHouse) | type-mapping.md |
| CDC failure modes & recovery — symptom → cause → fix per engine (slot / binlog / LSN / resume-token) | reference/cdc-failure-modes.md |
CDC change ordering — why (__pos, __seq) is the total change order (design rationale) | cdc-seq-ordering.md |
| Supported PostgreSQL / MySQL / SQL Server / MongoDB versions and test matrix | reference/compatibility.md |
| Offline + live test matrix, harness, fault-injection hook | reference/testing.md |
Trust contracts
The five surfaces a serious operator inspects before adopting Rivet. Same five rows, same order, are mirrored at the top of the project README.
| Topic | Guide |
|---|---|
| Execution semantics — retry, crash, resume, repair, reconcile, known non-guarantees | semantics.md |
| Reliability matrix — what runs in PR CI vs nightly vs manual; pgBouncer & ProxySQL coverage | reliability-matrix.md |
| Cloud smoke tests — last-verified real-cloud matrix per release (S3 / GCS / Azure) | cloud-smoke-tests.md |
| Release checklist — every gate every tag must clear before publish | release-checklist.md |
| Cloud permissions — least-privilege IAM / RBAC / SAS scopes for each backend | cloud-permissions.md |
| Security policy — what Rivet can access, sensitive artifacts, credential handling, reporting | ../SECURITY.md |
| Compatibility matrix — PG 12–16, MySQL 5.7 / 8.0, SQL Server 2022, MongoDB 4.4–8.0 actually exercised in CI | reference/compatibility.md |
| Cross-tool benchmark harness — reproducible PG/MySQL → Parquet vs sling, dlt, duckdb, clickhouse-local, odbc2parquet (defaults + steelman) | bench/README.md |
Best Practices
Practical guides explaining why settings matter and when to use them.
| Guide | What it covers |
|---|---|
| Resource-aware extraction | Memory budgets, warn/fail/auto_shrink policies, RSS formula |
| Parquet tuning | Row group strategies, target sizes, downstream read implications |
| Compression profiles | Profile-to-codec mapping, CPU/size trade-offs |
| Quality checks | Row count gates, null ratio, uniqueness cap (unique_max_entries) |
| Low-memory runners | Settings for 512 MB–4 GB hosts; auto_shrink guarantees and caveats |
| Recovery and resume | --resume semantics, crash recovery, state inspection |
| Benchmark methodology | How to run and interpret E2E and Criterion benchmarks; version comparison |
| Benchmark report v0.5.0 (historical) | Measured results — v0.5.0, pre-streaming; pending a 0.18 re-measure: compression profiles, row group targets, batch memory policies |
Architecture
| Topic | Guide |
|---|---|
| Data flow, pluggable traits, memory model, source layout | architecture.md |
| Source-aware extraction prioritization (advisory) | reference/prioritization.md |
Production
| Topic | Guide |
|---|---|
| Production checklist | pilot/production-checklist.md |
| UAT checklist (pilot sign-off) | pilot/uat-checklist.md |
| Plan/Apply for auditable extraction | reference/cli.md#rivet-plan · adr/0005-plan-apply-contracts.md |
| Reconcile / targeted repair | reference/cli.md#rivet-reconcile · adr/0009-reconcile-and-repair-contracts.md |
| Committed / verified progression | reference/cli.md#rivet-state-progression · adr/0008-export-progression.md |
Operator recipes
Action-first cookbooks for the most common production scenarios.
| Recipe | What it covers |
|---|---|
| recipes/recover-interrupted-run.md | Resume after kill / crash, drive validate / reconcile / repair, unstick a stalled state DB |
| recipes/idempotent-warehouse-load.md | Build an idempotent BigQuery / Snowflake loader on top of manifest.json + _SUCCESS |
| recipes/clickhouse-load.md | ClickHouse load (preview) — rivet run + rivet load per cycle, no compact step; what lands, known limits |
| reference/oracle.md | Oracle source (preview) — batch modes, bounded LogMiner CDC to files, types, known limits |
| recipes/airflow/ | Run Rivet on Airflow — a wave-aware DAG generated from rivet plan (heavy tables isolated, light ones parallelised, a barrier between waves), with per-table retries and a row-count reconcile gate |
Architecture Decision Records
| # | Title |
|---|---|
| 0001 | State update invariants (I1–I7) |
| 0002 | CLI product vs library |
| 0003 | Layer classification |
| 0004 | Destination write contracts |
| 0005 | Plan/Apply contracts (PA1–PA9) |
| 0006 | Source-aware extraction prioritization |
| 0007 | Cursor policy — single-column / coalesce (CC1–CC10) |
| 0008 | Committed / verified progression (PG1–PG8) |
| 0009 | Reconcile and targeted repair (RC1–RC6, RR1–RR8) |
| 0010 | Two parallel engines (in-process scoped threads vs subprocess fan-out) |
| 0011 | Source: Send (not Sync) — one connection per chunk worker |
| 0012 | Cloud manifest contract (M1–M9) |
| 0013 | Trust flag contract (--validate, --reconcile, --resume) |
| 0014 | Target type materialization (interchange vs native load; DuckDB/BQ/…) |
Example Configs
Ready-to-use YAML templates live in the examples/ directory. To scaffold YAML from a live database (rivet init), see reference/init.md and the root docker-compose.yaml.