Rivet Documentation
Rivet exports data from PostgreSQL, MySQL, SQL Server, and MongoDB to Parquet/CSV files on local disk, S3, GCS, Azure Blob Storage, or stdout.
Install from Rust: cargo install rivet-cli (crates.io name is rivet-cli; the binary is rivet). Other install options live in the repo README.
This folder contains modular guides for running exports, a complete configuration and CLI reference, an architecture overview, and the full set of architecture decision records.
Why teams pick Rivet
Three properties, each measured, not asserted:
- Source-safe under load — the batch export holds no long-running query on the source (0.00 s vs 7.7–94.6 s for the field); CDC reads the log, not your tables.
- Flat memory at any scale — a steady 57 MB peak RSS (2×–63× smaller than the field), flat from 10 k rows to a field-proven 454 M-row table with no OOM.
- CDC cost, per engine — an honest per-engine account of the one operational hazard (PostgreSQL slot retention) and why MySQL / SQL Server / MongoDB can’t fill the source disk.
Supported database versions
PostgreSQL and MySQL run the full end-to-end suite on each release; SQL Server and MongoDB carry their own scope and CI coverage:
| Engine | Versions covered by CI matrix |
|---|---|
| PostgreSQL | 12, 13, 14, 15, 16 |
| MySQL | 5.7, 8.0 |
| SQL Server | 2022 |
| MongoDB | 4.4, 5.0, 6.0, 7.0, 8.0 (dedicated nightly matrix; batch + CDC) |
See reference/compatibility.md for the version-support policy, the exact test matrix, and notes on engine-specific features.
Start here
Pick one — they’re ordered shortest to deepest. Read top-to-bottom, then come back to this index when you need a reference.
| Guide | What it gives you | Time |
|---|---|---|
| Who is Rivet for? | Yes / no fit-check with named alternatives (Debezium / Airbyte / Fivetran / dbt / DuckDB) | ~1 min |
| Getting Started | Install + your first export from a real table | ~3 min read · ~5 min hands-on |
| Concepts glossary | One-page orientation: run_id, cursor, chunk, manifest, journal, progression | ~3 min |
| Pilot guide | Operator runbook — full flow on your own database, production-ready guardrails | 1–2 sessions |
Short terminal walkthroughs in gifs/:
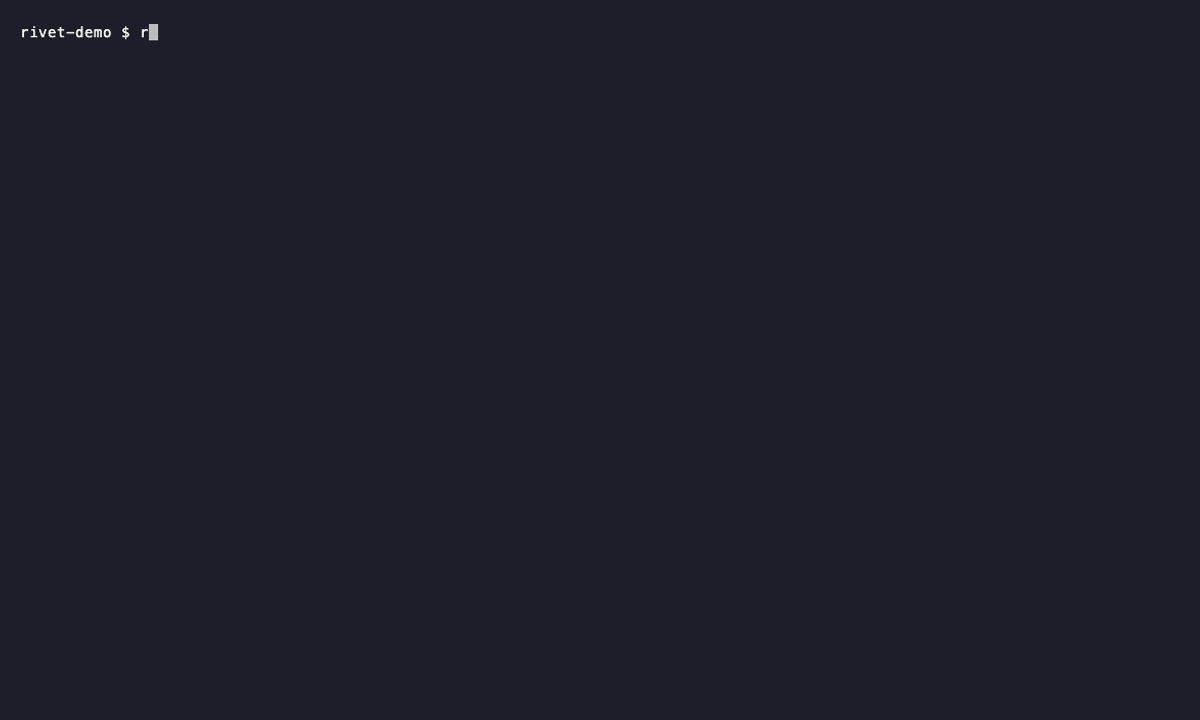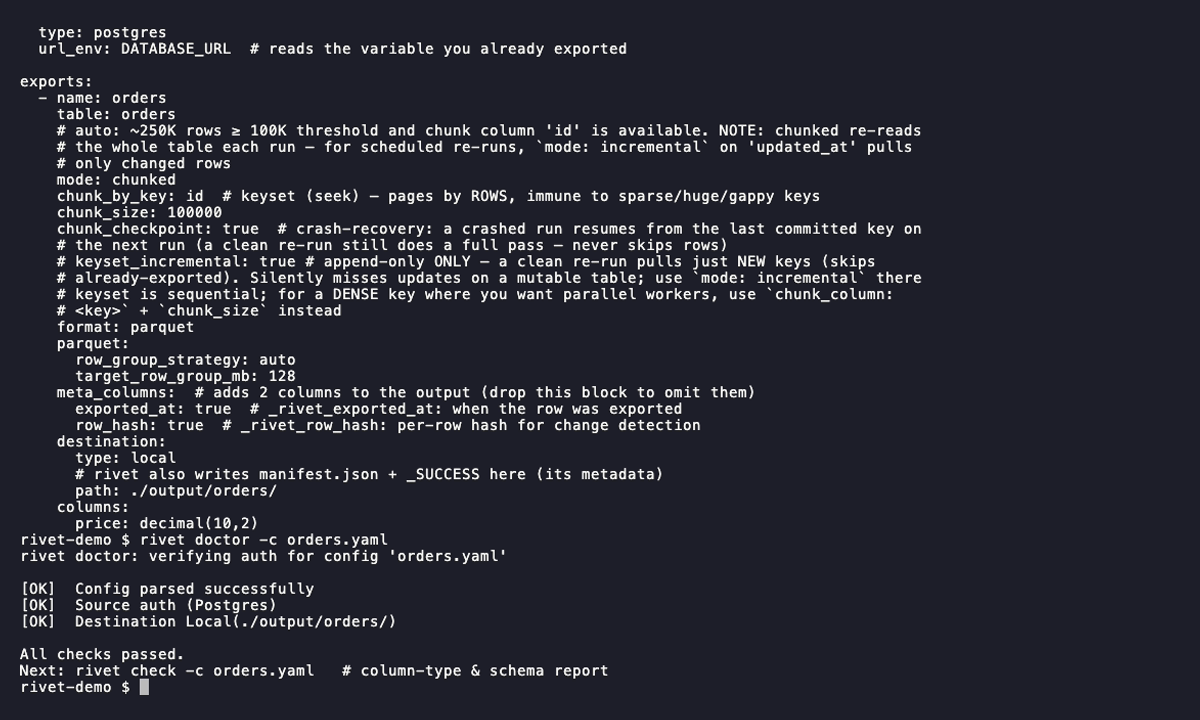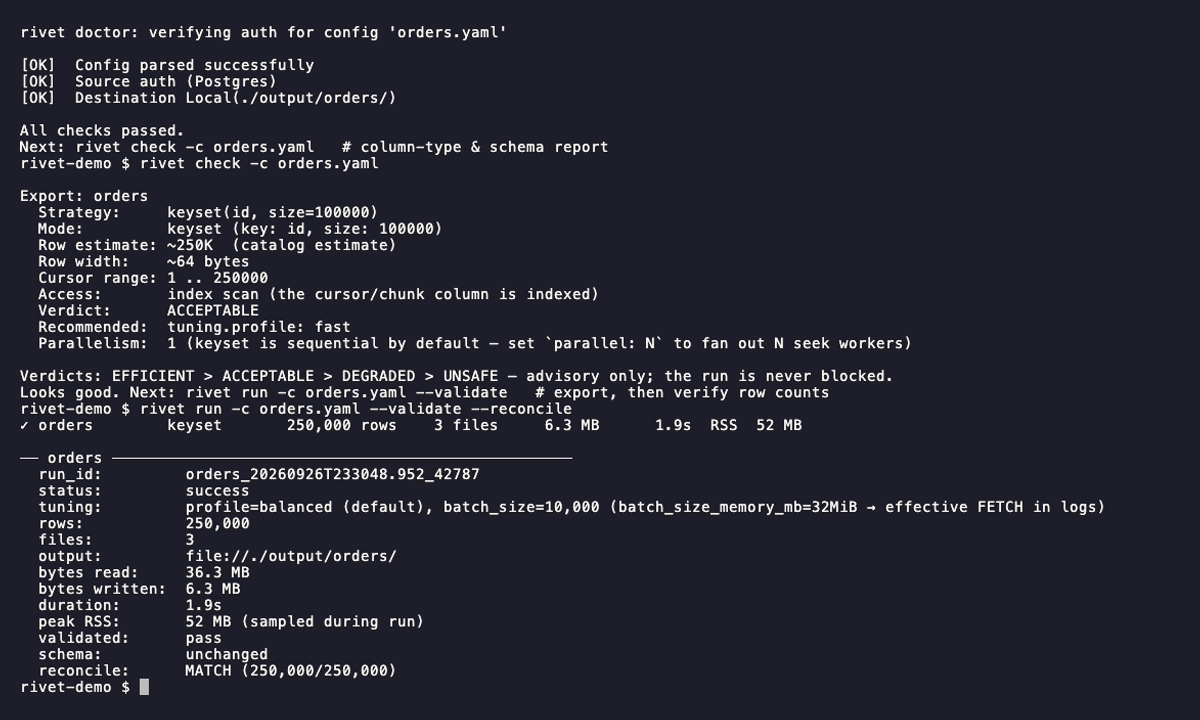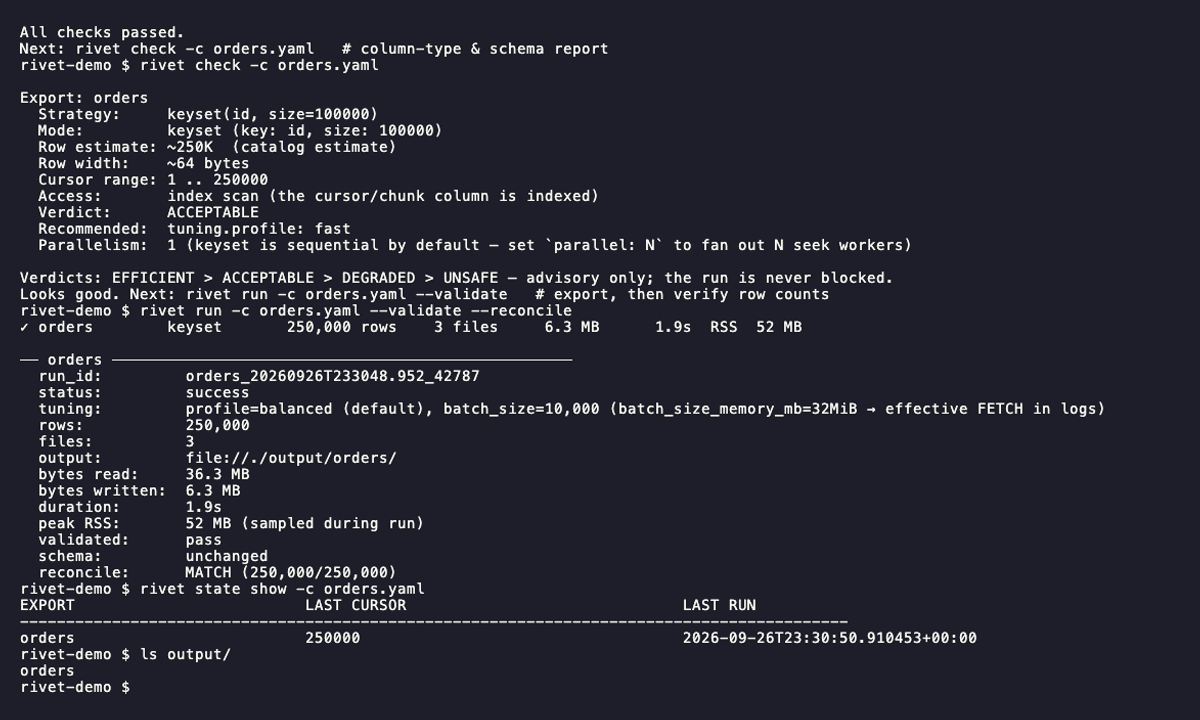
- gifs/basic.gif — scaffold config, preflight, run, inspect state (≈25 s)
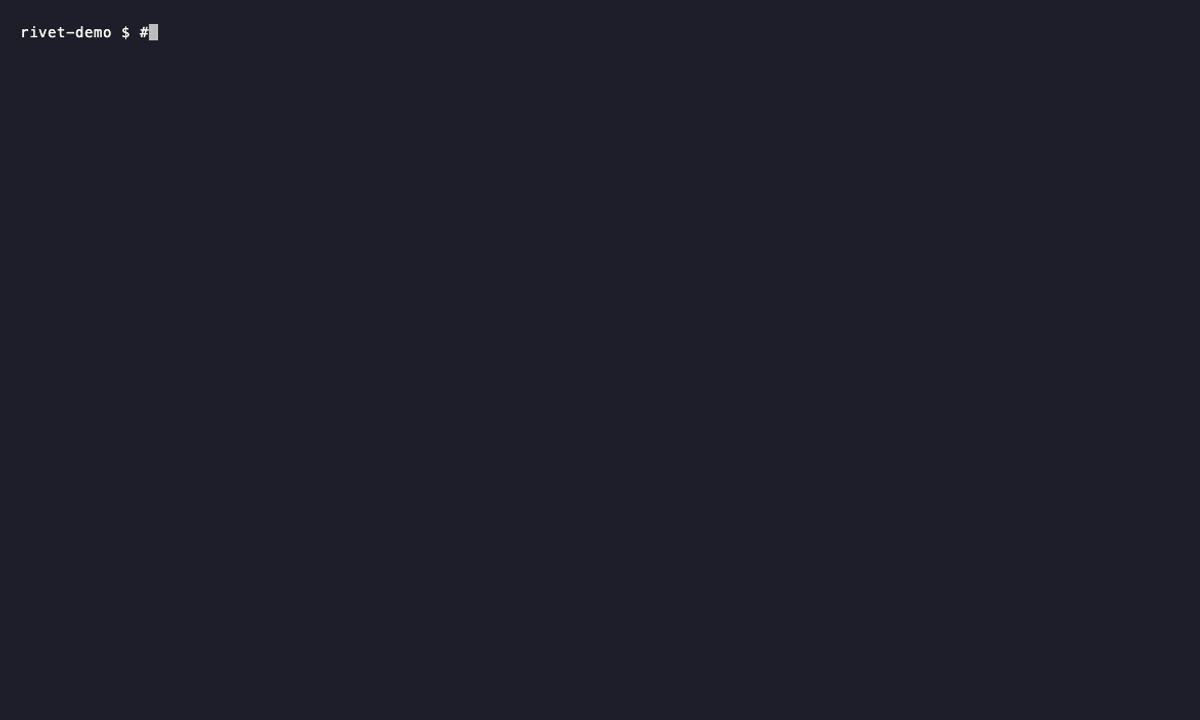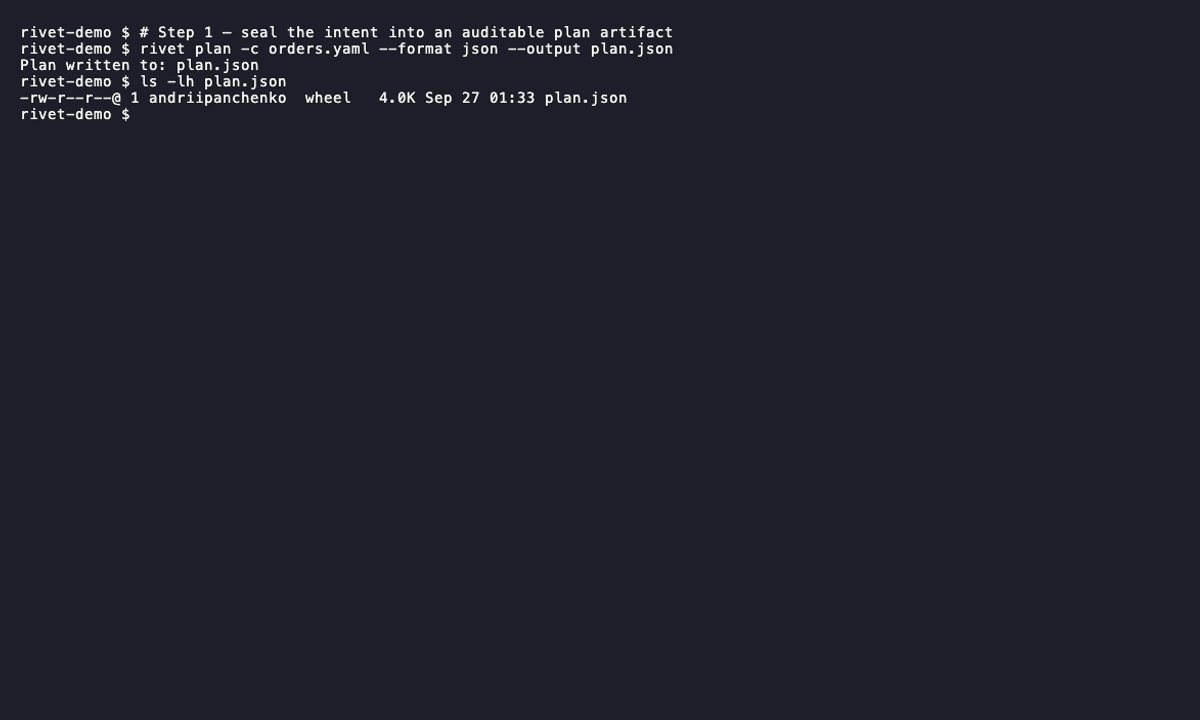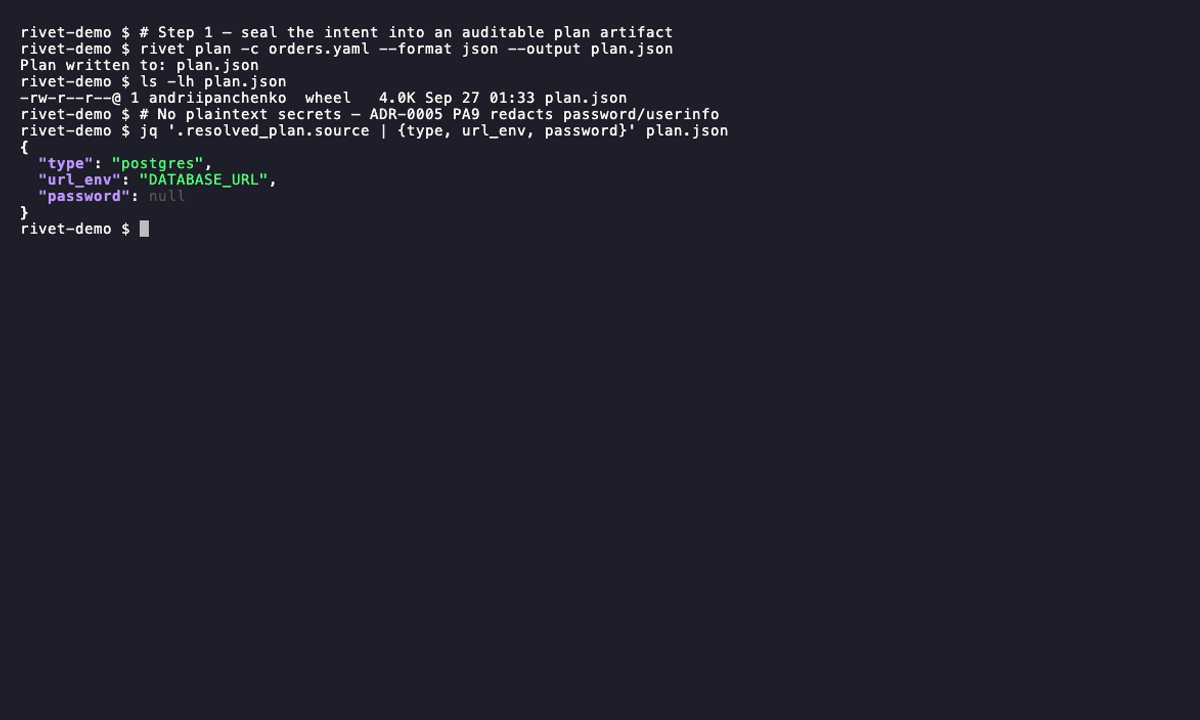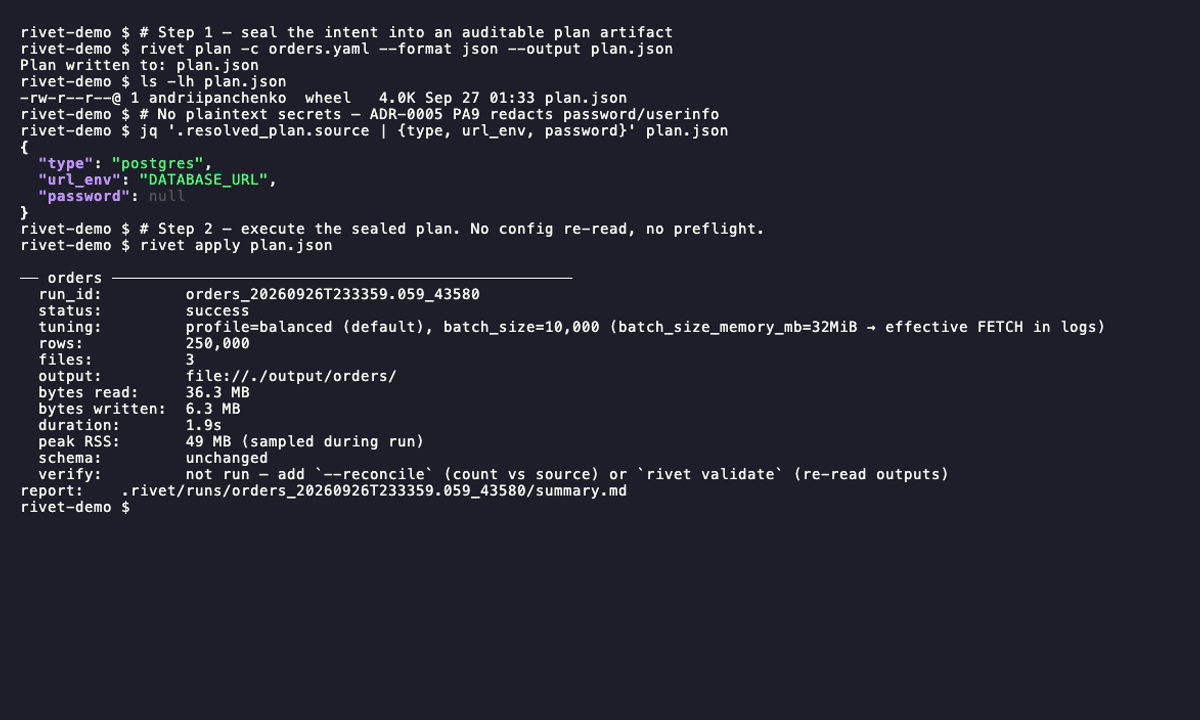
- gifs/plan-apply.gif — sealed plan/apply with credential redaction (≈20 s)
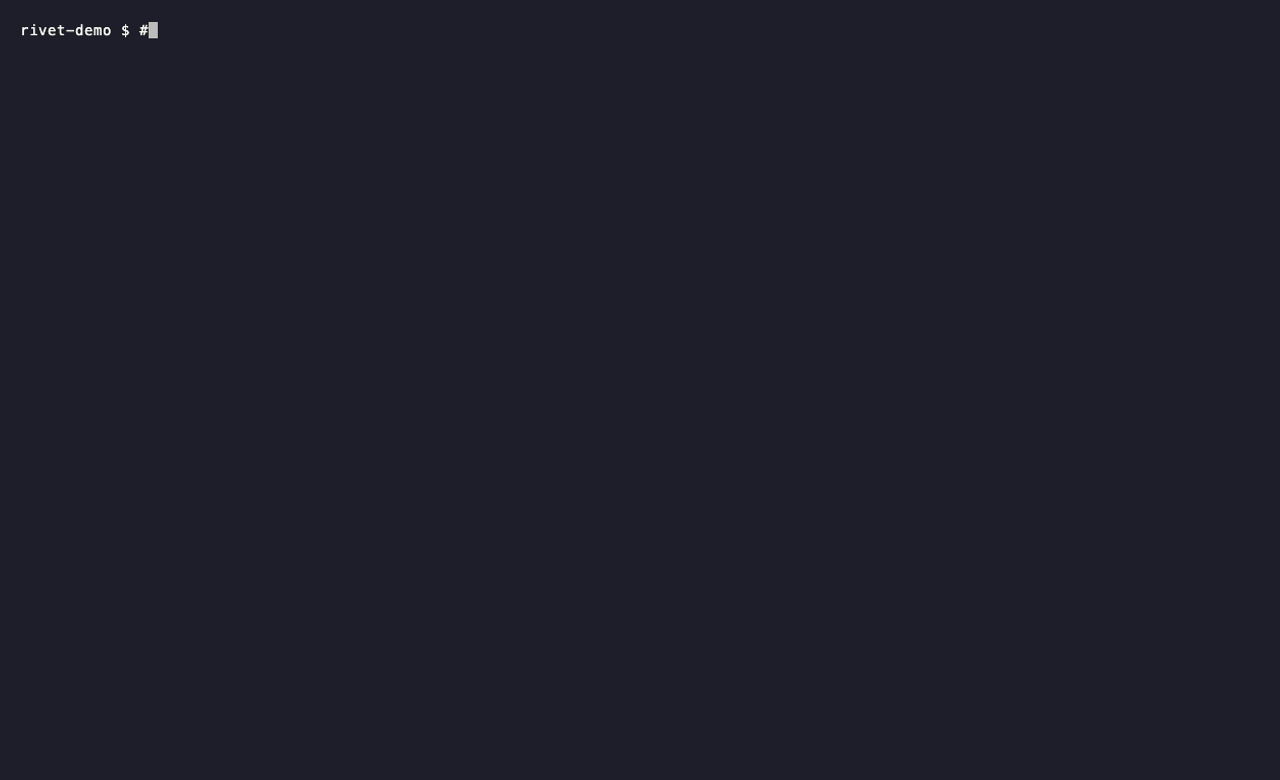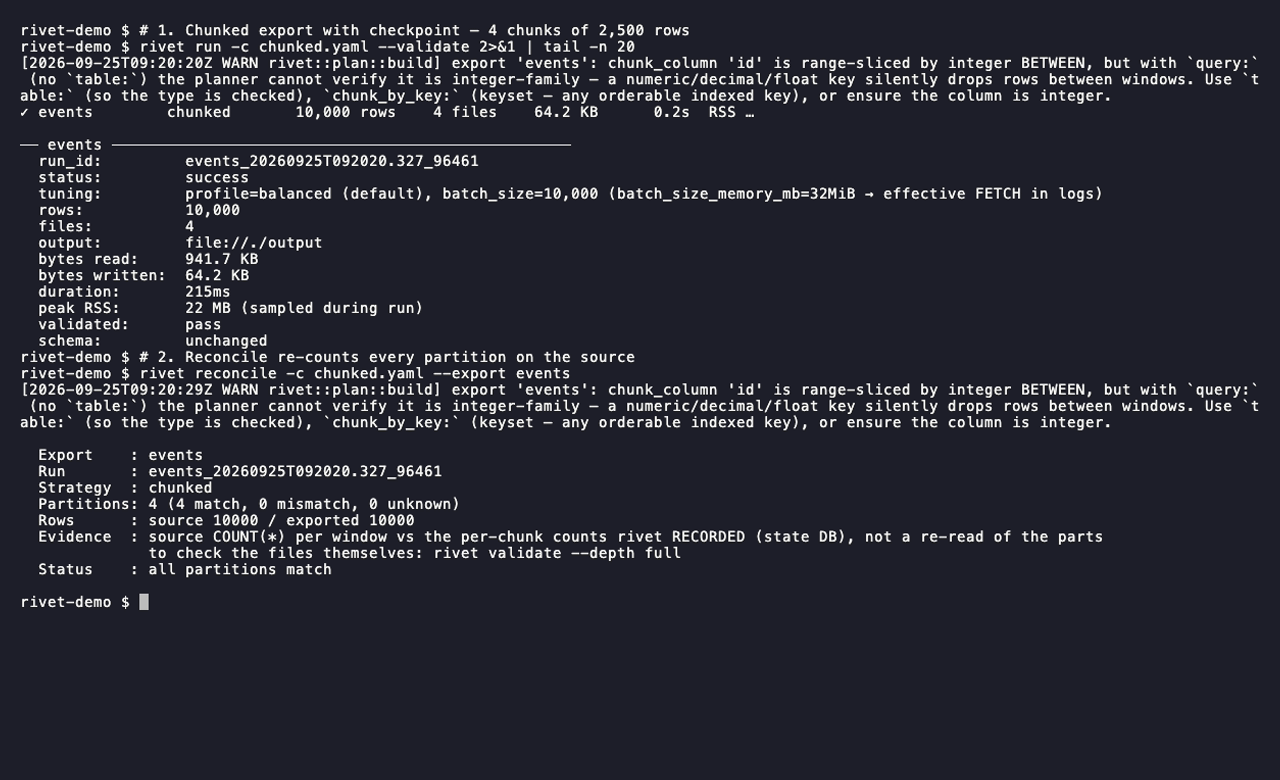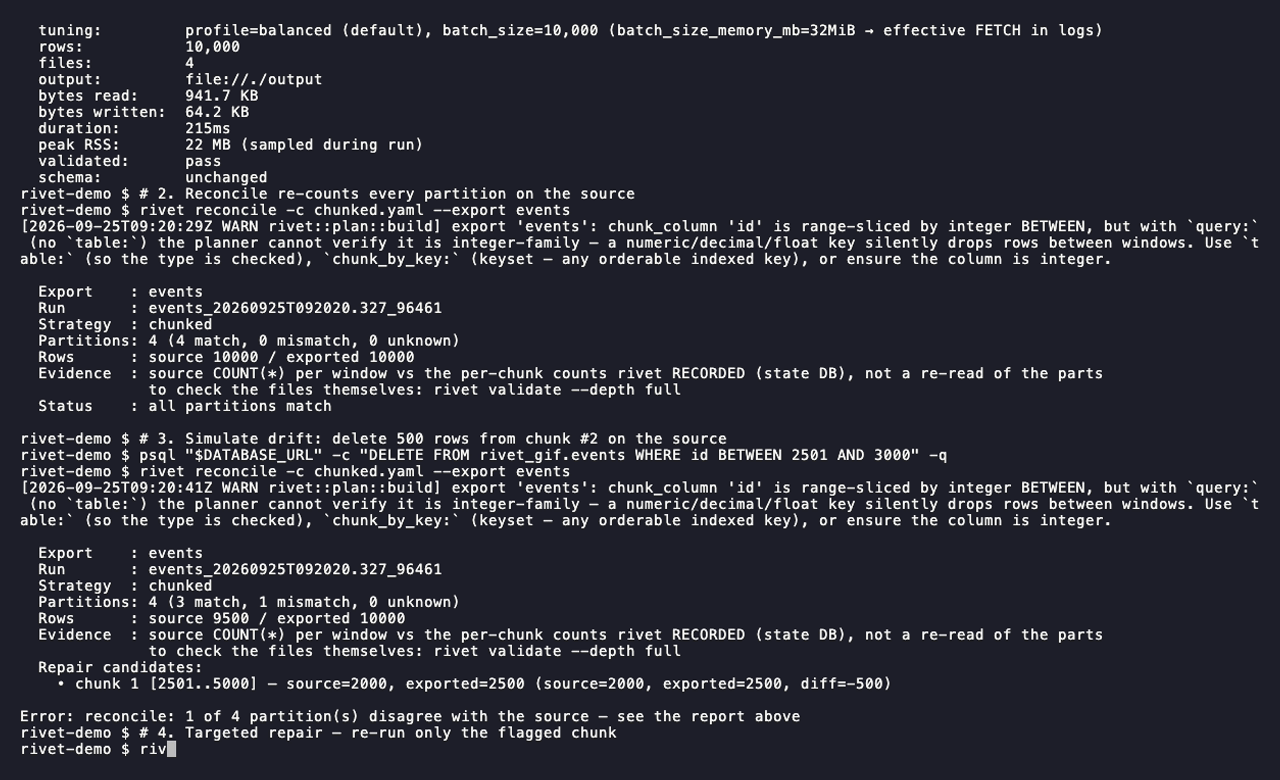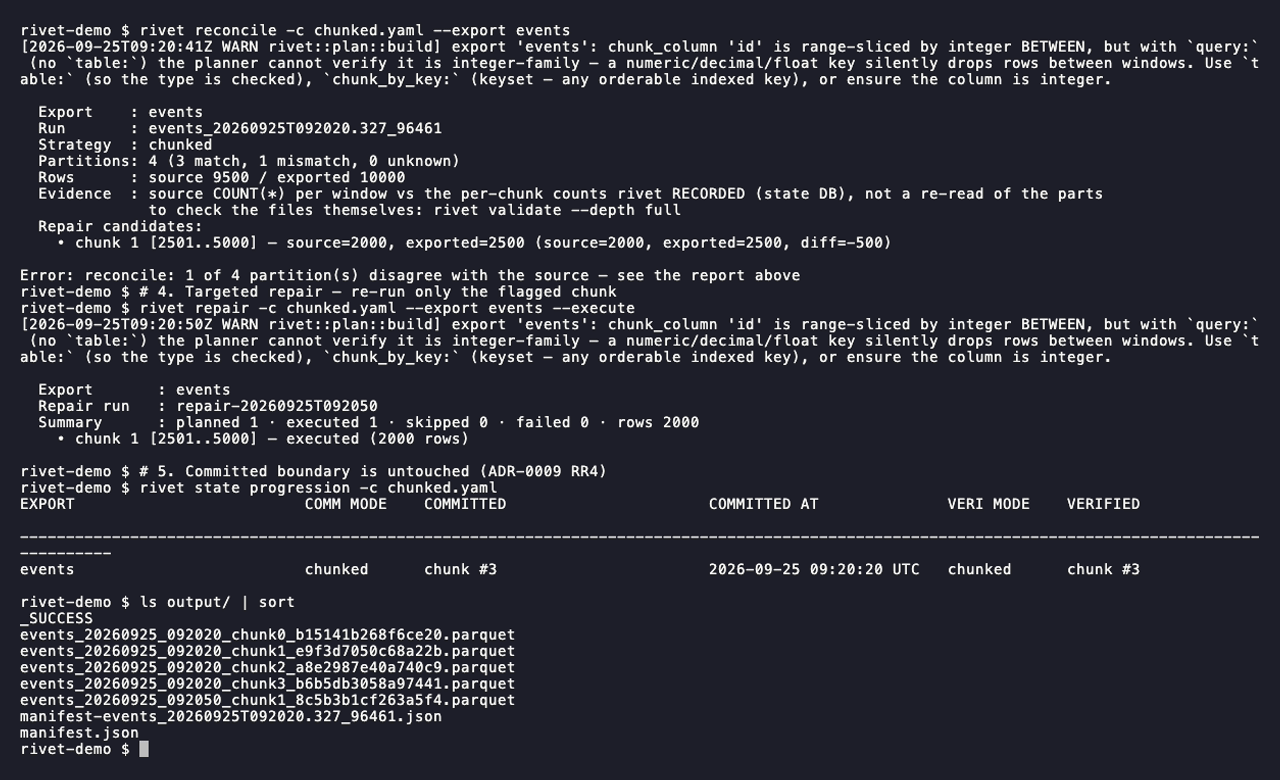
- gifs/reconcile-repair.gif — chunked + reconcile + targeted repair (≈35 s)
Export Modes
| Mode | When to Use | Guide |
|---|---|---|
| full | Snapshot the entire result set each run | modes/full.md |
| incremental | Only export rows newer than the last cursor | modes/incremental.md · composite cursor |
| chunked | Split large tables into parallel ranges by ID, or by date (chunk_by_days: 365 → one chunk per ~year, >= AND < semantics); checkpoint + --resume for crashed runs | modes/chunked.md |
| time_window | Export a rolling N-day window | modes/time-window.md |
| cdc | Stream INSERT/UPDATE/DELETE from the transaction log (MySQL binlog / PostgreSQL logical slot / SQL Server change tables / MongoDB change streams / Oracle LogMiner, preview) as typed Parquet/CSV — source-safe, at-least-once | reference/cdc.md |
Destinations
| Destination | Guide |
|---|---|
| Local filesystem | destinations/local.md |
| AWS S3 / MinIO | destinations/s3.md |
| Google Cloud Storage | destinations/gcs.md |
| Azure Blob Storage | destinations/azure.md |
| Stdout (pipe) | destinations/stdout.md |
Cloud auth & trust: cloud-auth.md — per-backend credential-flow matrix (AWS / GCS / Azure incl. SAS) · cloud-destinations.md — the cloud write trust contract (manifest, quarantine, support matrix).
Output layout
| Feature | What | Guide |
|---|---|---|
partition_by | Split rows into Hive-style col=value/ sub-folders by a date column (day/month/year); NULLs → __HIVE_DEFAULT_PARTITION__; orthogonal to mode | partitioning.md |
Reference
| Topic | Guide |
|---|---|
| Complete YAML config reference | reference/config.md |
| CLI commands and flags | reference/cli.md |
| Tuning profiles and parameters | reference/tuning.md |
rivet cdc — log-based change data capture: per-engine grants/prereqs, output shape, why it’s gentle on the source | reference/cdc.md |
MongoDB — the JSON-blob model, batch + CDC walkthroughs, source.mongo.* config, type fidelity + warehouse portability | reference/mongodb.md |
rivet init — scaffold YAML from the database | reference/init.md |
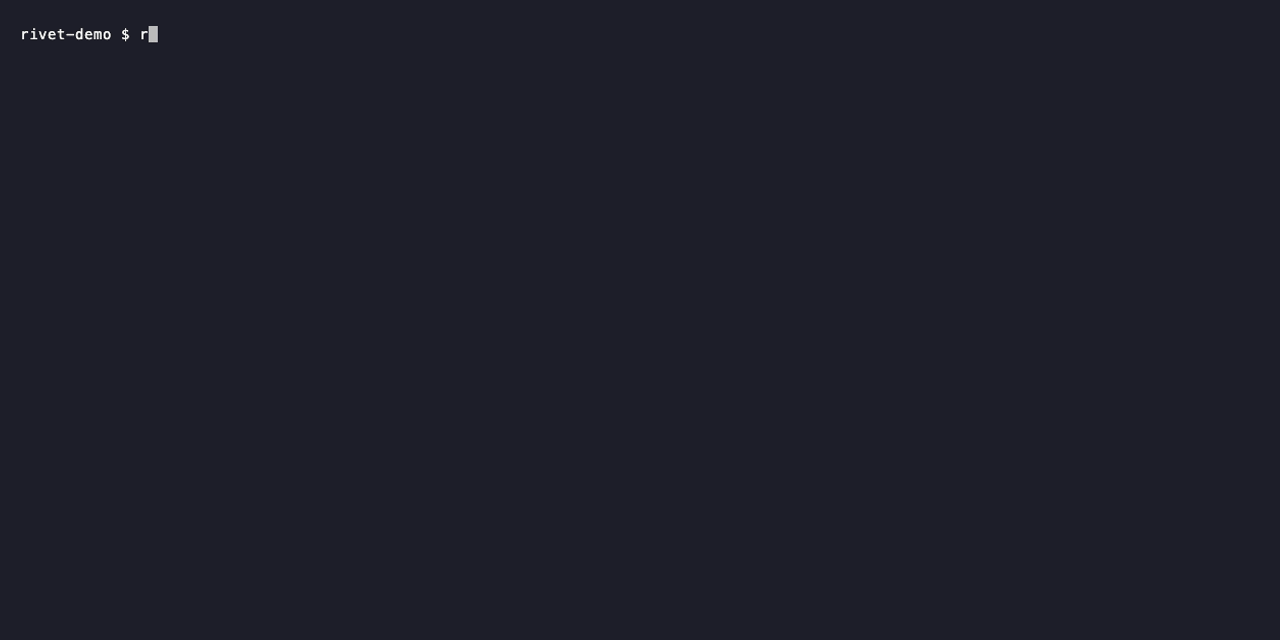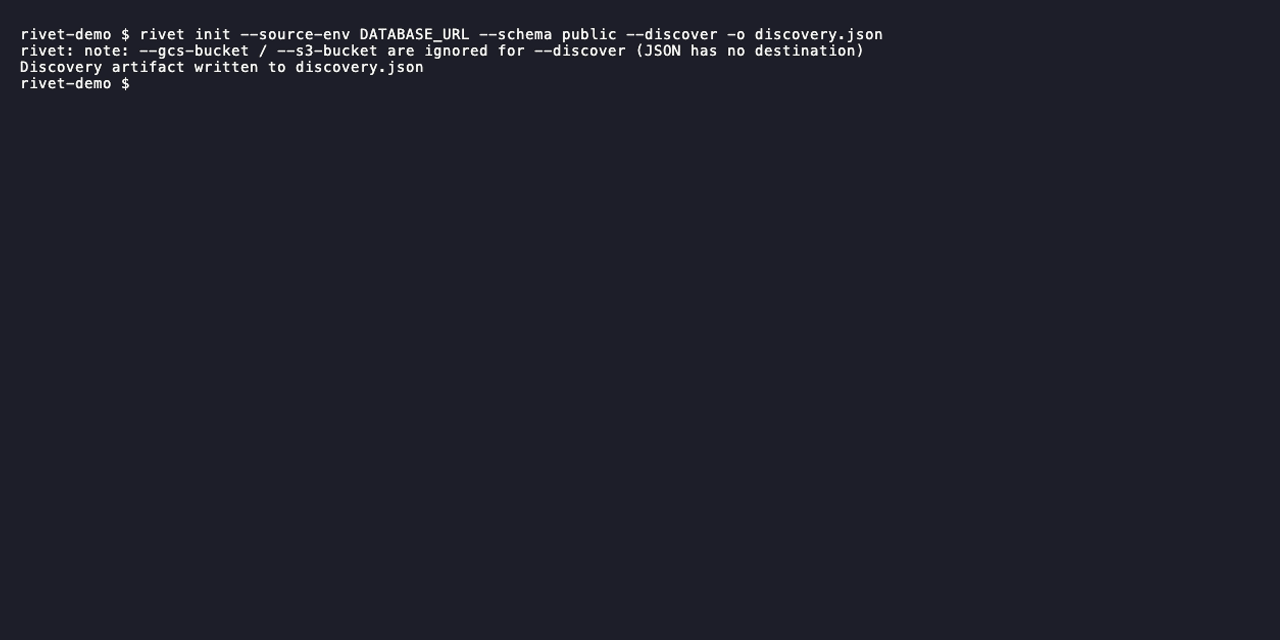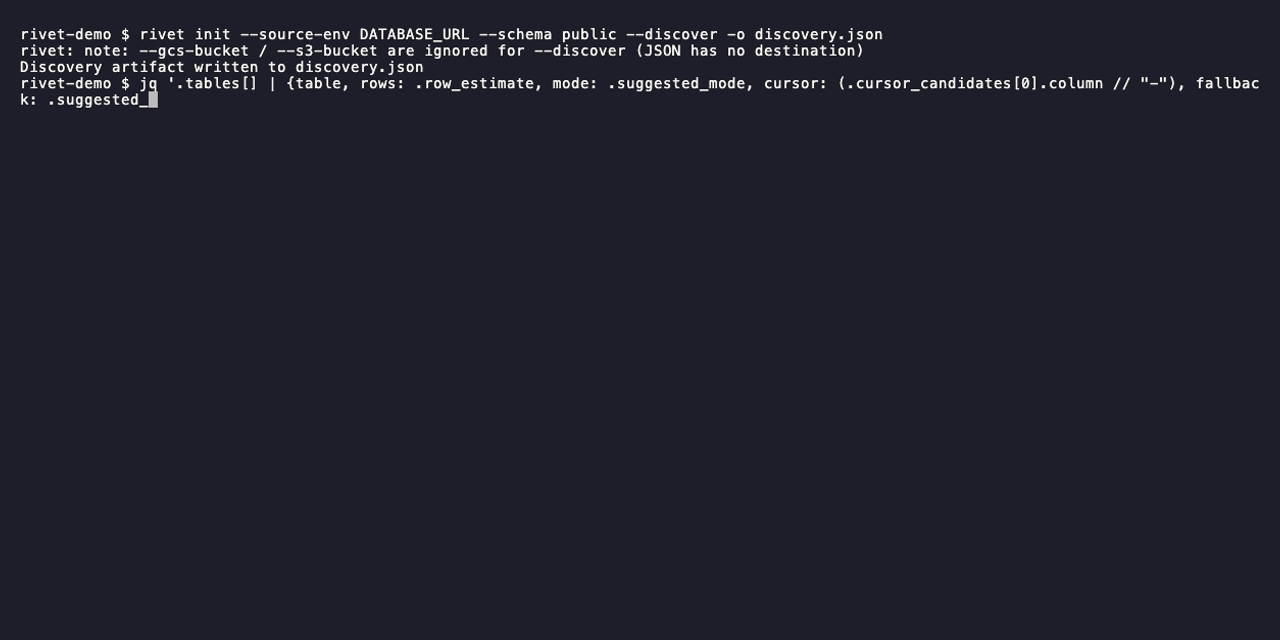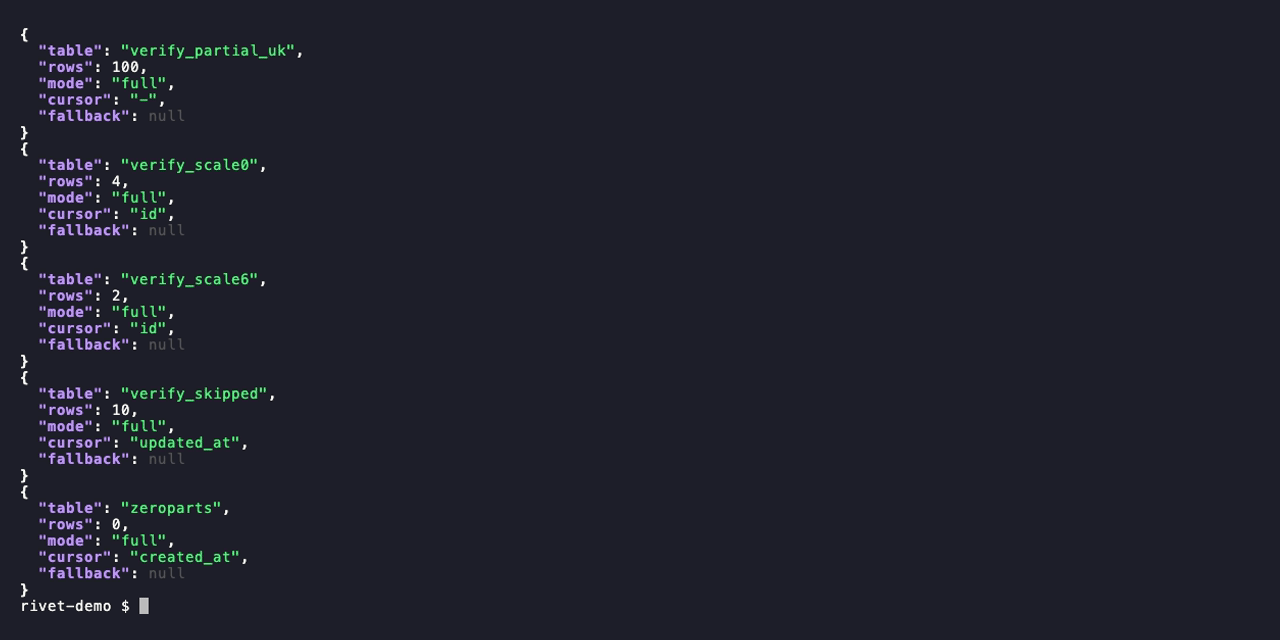
rivet init --discover — machine-readable JSON discovery artifact (ranked cursor / chunk candidates, row estimates, on-disk sizes) for automation and code review | reference/init.md#discovery-artifact—discover · gifs/discover-artifact.gif |
rivet check --type-report --target bigquery — per-column type fidelity report + warehouse compatibility (NUMERIC / BIGNUMERIC / TIMESTAMP overflow warnings); --strict exits non-zero on lossy mappings | reference/cli.md#rivet-check |
| Type mapping — per-engine source-type → Arrow/Parquet contract + warehouse-target fidelity (BigQuery / Snowflake / DuckDB / ClickHouse) | type-mapping.md |
| CDC failure modes & recovery — symptom → cause → fix per engine (slot / binlog / LSN / resume-token) | reference/cdc-failure-modes.md |
CDC change ordering — why (__pos, __seq) is the total change order (design rationale) | cdc-seq-ordering.md |
| Supported PostgreSQL / MySQL / SQL Server / MongoDB versions and test matrix | reference/compatibility.md |
| Offline + live test matrix, harness, fault-injection hook | reference/testing.md |
Trust contracts
The five surfaces a serious operator inspects before adopting Rivet. Same five rows, same order, are mirrored at the top of the project README.
| Topic | Guide |
|---|---|
| Execution semantics — retry, crash, resume, repair, reconcile, known non-guarantees | semantics.md |
| Reliability matrix — what runs in PR CI vs nightly vs manual; pgBouncer & ProxySQL coverage | reliability-matrix.md |
| Cloud smoke tests — last-verified real-cloud matrix per release (S3 / GCS / Azure) | cloud-smoke-tests.md |
| Release checklist — every gate every tag must clear before publish | release-checklist.md |
| Cloud permissions — least-privilege IAM / RBAC / SAS scopes for each backend | cloud-permissions.md |
| Security policy — what Rivet can access, sensitive artifacts, credential handling, reporting | ../SECURITY.md |
| Compatibility matrix — PG 12–16, MySQL 5.7 / 8.0, SQL Server 2022, MongoDB 4.4–8.0 actually exercised in CI | reference/compatibility.md |
| Cross-tool benchmark harness — reproducible PG/MySQL → Parquet vs sling, dlt, duckdb, clickhouse-local, odbc2parquet (defaults + steelman) | bench/README.md |
Best Practices
Practical guides explaining why settings matter and when to use them.
| Guide | What it covers |
|---|---|
| Resource-aware extraction | Memory budgets, warn/fail/auto_shrink policies, RSS formula |
| Parquet tuning | Row group strategies, target sizes, downstream read implications |
| Compression profiles | Profile-to-codec mapping, CPU/size trade-offs |
| Quality checks | Row count gates, null ratio, uniqueness cap (unique_max_entries) |
| Low-memory runners | Settings for 512 MB–4 GB hosts; auto_shrink guarantees and caveats |
| Recovery and resume | --resume semantics, crash recovery, state inspection |
| Benchmark methodology | How to run and interpret E2E and Criterion benchmarks; version comparison |
| Benchmark report v0.5.0 (historical) | Measured results — v0.5.0, pre-streaming; pending a 0.18 re-measure: compression profiles, row group targets, batch memory policies |
Architecture
| Topic | Guide |
|---|---|
| Data flow, pluggable traits, memory model, source layout | architecture.md |
| Source-aware extraction prioritization (advisory) | reference/prioritization.md |
Production
| Topic | Guide |
|---|---|
| Production checklist | pilot/production-checklist.md |
| UAT checklist (pilot sign-off) | pilot/uat-checklist.md |
| Plan/Apply for auditable extraction | reference/cli.md#rivet-plan · adr/0005-plan-apply-contracts.md |
| Reconcile / targeted repair | reference/cli.md#rivet-reconcile · adr/0009-reconcile-and-repair-contracts.md |
| Committed / verified progression | reference/cli.md#rivet-state-progression · adr/0008-export-progression.md |
Operator recipes
Action-first cookbooks for the most common production scenarios.
| Recipe | What it covers |
|---|---|
| recipes/recover-interrupted-run.md | Resume after kill / crash, drive validate / reconcile / repair, unstick a stalled state DB |
| recipes/idempotent-warehouse-load.md | Build an idempotent BigQuery / Snowflake loader on top of manifest.json + _SUCCESS |
| recipes/clickhouse-load.md | ClickHouse load (preview) — rivet run + rivet load per cycle, no compact step; what lands, known limits |
| reference/oracle.md | Oracle source (preview) — batch modes, bounded LogMiner CDC to files, types, known limits |
| recipes/airflow/ | Run Rivet on Airflow — a wave-aware DAG generated from rivet plan (heavy tables isolated, light ones parallelised, a barrier between waves), with per-table retries and a row-count reconcile gate |
Architecture Decision Records
| # | Title |
|---|---|
| 0001 | State update invariants (I1–I7) |
| 0002 | CLI product vs library |
| 0003 | Layer classification |
| 0004 | Destination write contracts |
| 0005 | Plan/Apply contracts (PA1–PA9) |
| 0006 | Source-aware extraction prioritization |
| 0007 | Cursor policy — single-column / coalesce (CC1–CC10) |
| 0008 | Committed / verified progression (PG1–PG8) |
| 0009 | Reconcile and targeted repair (RC1–RC6, RR1–RR8) |
| 0010 | Two parallel engines (in-process scoped threads vs subprocess fan-out) |
| 0011 | Source: Send (not Sync) — one connection per chunk worker |
| 0012 | Cloud manifest contract (M1–M9) |
| 0013 | Trust flag contract (--validate, --reconcile, --resume) |
| 0014 | Target type materialization (interchange vs native load; DuckDB/BQ/…) |
Example Configs
Ready-to-use YAML templates live in the examples/ directory. To scaffold YAML from a live database (rivet init), see reference/init.md and the root docker-compose.yaml.
Source-safe under load
The first question a serious operator asks about an extraction tool is what
does it do to my source database while it runs? A careless SELECT * holds a
long-running transaction, pins a read snapshot, inflates temp space, and spikes
p99 latency for every other query on the box. Rivet is built so that the honest
answer is “almost nothing you’ll notice.”
It holds no long-running query
A batch export streams the source in bounded pages — one chunk / one page at a time — and flushes each to a Parquet part before asking for the next. The longest query Rivet ever holds open on the source is a single page, not a full-table scan. In the cross-tool benchmark (PostgreSQL → Parquet, measured under a concurrent OLTP workload), the longest single server-side query each tool held was:
| Tool | Longest source query | Peak RSS |
|---|---|---|
| rivet | 0.00 s | 57 MB |
| rivet (chunked) | 0.00 s | 57 MB |
| duckdb | 7.7 s | 2 067 MB |
| odbc2parquet | 40.0 s | 3 579 MB |
| clickhouse-local | 50.3 s | 820 MB |
| sling | 94.6 s | 129 MB |
Rivet is the only tool in the field that never parks a long-running read on the
source. Everything else holds one server-side query open for the length of a
full scan — 8 to 95 seconds here, and proportionally longer on a real table.
That is the query your DBA sees in pg_stat_activity blocking autovacuum, or
the one a pooler’s statement timeout kills at the worst moment.
It stays gentle on concurrent traffic
Under the same concurrent OLTP workload, the p99 latency multiplier (how much the export slows other queries) is mid-field for Rivet — 5.1× single-stream, 3.3× chunked — comparable to the rest, but achieved at 57 MB of RAM and zero long queries instead of hundreds of megabytes to multiple gigabytes with a scan pinned open. Rivet trades a little client-side CPU for a source that never sees a heavy query.
If the source is fragile, production-shared, or behind a pooler (pgBouncer, ProxySQL, MaxScale), that trade is the whole point. See MSSQL gentle extraction and resource-aware extraction for the per-engine knobs.
CDC is a passive reader too
Change-data-capture reads the transaction log, not your tables. Running a looping CDC drain against a live writer, the writer’s throughput barely moves — except on SQL Server, and that cost is inherent to the engine, not to Rivet:
| Engine | Writer throughput under CDC | Why |
|---|---|---|
| PostgreSQL | 0.98× | logical decoding is light |
| MySQL | 1.07× | binlog dump is a passive reader |
| MongoDB | 1.01× | change stream reads the oplog |
| SQL Server | 0.78× | the capture Agent duplicates every change into change tables — a second write SQL Server itself performs |
The full per-engine numbers, harnesses, and contracts live in the performance & harm ledger. The one operational hazard that is per-engine — a CDC reader pinning source log retention — is covered on its own page: CDC cost, per engine.
Flat memory at any scale
Rivet’s memory is bounded by how much you buffer before a flush — not by how big the table is. It streams rows into Arrow batches, and every time a batch fills it is written to a Parquet part and dropped. A 10-thousand-row table and a 500-million-row table run at the same resident set size.
The number that matters
In the cross-tool benchmark, peak resident memory was:
| Tool | Peak RSS |
|---|---|
| rivet | 57 MB |
| sling | 129 MB |
| clickhouse-local | 820 MB |
| dlt | 1 735 MB |
| duckdb | 2 067 MB |
| odbc2parquet | 3 579 MB |
Rivet is 2× to 63× smaller than the field — and crucially, that 57 MB is flat. The tools that buffer the result set (or materialise it in an embedded engine) scale their memory with the data; Rivet does not.
Proven at production scale
The benchmark table is small enough to fit in RAM, which is exactly why the flat-memory property is invisible there for the buffering tools. It stops being invisible on a real table. A field run pulled a 454-million-row table to Parquet in about two hours with flat memory and no OOM — the same table on which Airbyte OOM’d. The mechanism the benchmark measures (bounded Arrow batches → Parquet parts) is the mechanism that survives at 454 M rows.
This is what lets Rivet run on a 512 MB–4 GB host, in a small Kubernetes Job, or alongside other work on a shared box. See low-memory runners for the exact settings and the RSS budget formula.
CDC memory is bounded by rollover, not the backlog
The same property holds for change-data-capture. A CDC drain’s peak RSS is
O(rollover) — the part-size at which it flushes and checkpoints — not
O(backlog). A soak test grows the drain interval 12× (10 → 120 minutes of
accumulated changes) and peak RSS stays flat: the run reads, flushes at
rollover, checkpoints, and acks in a loop, so a larger backlog just means more
loops, not more memory. The harness self-asserts both the flat RSS and that
every churned row was captured; details in the
performance ledger.
CDC cost, per engine
Change-data-capture reads a source’s transaction log, and the one operational hazard worth understanding before you turn it on is log retention: does the reader hold log data on the source, and can an abandoned reader fill the source disk? The answer is not the same across engines, and Rivet is explicit about it.
The one engine that can pin the disk: PostgreSQL
PostgreSQL’s logical replication slot is a consume-retention mechanism: the
server keeps WAL from the slot’s confirmed position forward until the consumer
acknowledges it. That is what makes resume lossless — Rivet’s CDC delivery is
at-least-once (a crash between flush and acknowledge re-reads the un-acked span;
dedupe downstream by PK + __op if you need exactly-once effects) — and it is also the one
place where a reader can hurt the source. While Rivet keeps up, retention is
bounded to roughly interval × write-rate (≈ 23.5 MB over a 6 s cycle at
~4 MB/s in the harness). But an abandoned or stuck slot is unbounded: during
this project’s own testing, a forgotten slot pinned 29 GB of WAL and crashed
the PostgreSQL instance by filling its disk.
Operational rule for PostgreSQL CDC: monitor slot lag / retained WAL, and drop slots you no longer consume. This is inherent to how PostgreSQL logical replication guarantees no-loss — every tool that uses a slot inherits it — but Rivet names it plainly rather than hiding it.
The engines that cannot: MySQL, SQL Server, MongoDB
On the other three engines, log retention is decided by the server on its own schedule, independent of any reader. A Rivet CDC run — or a crashed one — structurally cannot fill the source disk:
| Engine | Retention model | Disk-fill hazard |
|---|---|---|
| PostgreSQL | logical slot — reader-pinned until ack | Yes — monitor slot lag |
| MySQL | binlog purged by binlog_expire_logs_seconds regardless of reader | No |
| SQL Server | change tables trimmed by the CDC cleanup job regardless of reader | No |
| MongoDB | oplog is a fixed-size capped collection (rolls over by size) | No |
On these engines the trade-off flips: because the server can trim the log out from under a slow reader, the risk is not disk-fill but falling behind (missing changes if you resume after the log has rolled past your checkpoint). The mitigation is a short enough scheduler interval, not disk monitoring.
Why this shapes the default
Because retention on PostgreSQL is coupled to acknowledgement, an abandoned
continuous stream is the worst case — it holds a slot open forever. That is a
large reason the OSS model is the bounded drain: until_current now
defaults to true, so a scheduled run reads to the log
end, checkpoints, acks (advancing the slot), and exits. The next cycle resumes
from the checkpoint. Continuous streaming is an explicit opt-in
(until_current: false, or rivet cdc --stream) that logs a warning, so you
never start a never-terminating slot-holding stream by accident.
The full per-engine numbers, harnesses, and contracts are in the performance & harm ledger; the recovery playbook per symptom is in CDC failure modes.
Who is Rivet for?
A short, honest fit-check. Rivet is intentionally narrow — the goal is to do one thing well, not to be the only data tool you need. This page exists so you can decide in 60 seconds whether to keep reading, or whether something else is a better fit for your problem.
If you came here from a search for “Postgres / MySQL / SQL Server / MongoDB → Parquet” or “extract a big SQL table without an OOM”, you are probably in the right place.
Yes, Rivet is probably a good fit if…
- You need to dump rows from PostgreSQL, MySQL, or SQL Server (or documents from MongoDB) into Parquet or CSV files — locally, on S3, GCS, or Azure Blob Storage.
- The source database is fragile, production-shared, or behind a
pooler (pgBouncer, ProxySQL, MaxScale) and a careless
SELECT *is going to hurt someone. - You want resumable extraction — the job can crash, the network can blip, and the next run continues from a checkpoint instead of starting over.
- You want a manifest +
_SUCCESStrust contract so a downstream loader can decide exactly which files belong to a given run. - You are happy operating Rivet from cron, Airflow, GitHub Actions, Argo, a one-off shell script, or a Kubernetes Job — anything that can invoke a single CLI binary with a YAML config.
- You can write a SQL query. Rivet does not abstract SQL away; it runs the query you give it.
No, Rivet is probably not the right tool if…
| You actually need… | Use this instead |
|---|---|
| Always-on live streaming — every insert/update/delete pushed continuously into Kafka or Kinesis as it happens | Debezium, Estuary, Materialize, or your cloud’s native CDC (AWS DMS, GCP Datastream). (Rivet does capture CDC — inserts/updates/deletes — but to files: mode: cdc, resumable, per-invocation, not a live stream. See semantics.md.) |
| A SaaS connector marketplace — pre-built connectors for Salesforce, Stripe, NetSuite, Shopify, Hubspot, etc. | Airbyte, Fivetran, Stitch |
A managed warehouse loader — a continuously-managed service that loads every warehouse (Redshift, Databricks, …) as one product. (Rivet does load BigQuery / Snowflake — rivet load, a discrete command you schedule, not a managed service; recipe.) | Fivetran, Airbyte (cloud), dlt (self-hosted with destinations), Sling |
| In-warehouse transformation — modeling, joins, materializations, lineage | dbt, SQLMesh |
| A data orchestrator — DAGs, retries-with-callbacks, schedule UI, lineage graphs | Airflow, Dagster, Prefect |
| A Kubernetes operator / Helm chart for an extraction platform | Rivet runs as a single binary in a Job or CronJob; a heavier platform like Airbyte on Kubernetes is a different architecture |
| Exactly-once delivery to the destination — no chance of a duplicate file under any failure mode | Rivet provides at-least-once file delivery + manifest; consumers deduplicate on the warehouse side (recipe). If you need exactly-once at the file layer, use a transactional sink (warehouse MERGE, lake table commit). |
| A data catalog / governance / PII detection layer | Amundsen, DataHub, Collibra |
| A query engine that reads from Postgres/MySQL and joins with other sources at query time | DuckDB (postgres_scanner/mysql_scanner), Trino, ClickHouse |
If you find yourself trying to bend Rivet into one of the above shapes, stop and pick the tool above instead. We are not trying to become any of those, and shoehorning will be painful.
Edge cases — Rivet can do this, but read first
-
Very large single-table dumps (100M+ rows). Yes, but read
docs/modes/chunked.mdfirst — chunked mode with the right cursor column is the difference between an export that finishes in 20 minutes and one that holds a single SQL statement open for 2 hours. -
Sources with weak or missing primary keys / cursor columns. Rivet has
incremental_cursor_mode: coalescefor nullable primaries (see composite cursor walkthrough) and keyset (chunk_by_key) for chunking without an integer key — but these surface tradeoffs inrivet check(sparse range warnings). Look at the warnings, do not ignore them. -
Read replicas with replication lag. On PostgreSQL, a full-mode export runs inside a single snapshot transaction, so the exported rows are point-in-time consistent as of the replica’s “now”. Chunked/keyset exports issue independent short queries (parallel workers each on their own connection), and other engines (e.g. MySQL) run plain autocommit SELECTs — there consistency is per-query, not per-run. Either way, a lagging replica gives you the replica’s “now”, not the primary’s. Operator’s responsibility to choose the right endpoint.
-
Sources behind SSH bastions / jump hosts. No native SSH tunnel support yet (tracked in
rivet_roadmap.mdEpic 13). Usessh -Lorautosshto forward the port and point Rivet atlocalhost:<forwarded>. -
Stateless / ephemeral runners (Kubernetes pods, Lambda, ECS tasks). Set
RIVET_STATE_URLto a PostgreSQL state backend so cursors and checkpoints survive pod death. See the README § Stateless deployment.
Decision shortcut
Need always-on live streaming (into Kafka)?    → Debezium / Estuary
Need CDC captured to files (resumable)?        → Rivet  (mode: cdc)
Need a connector for a non-DB SaaS source?     → Airbyte / Fivetran
Need a managed extract+load product?           → Fivetran / Airbyte Cloud
Load extracted data into BigQuery / Snowflake? → Rivet  (rivet load)
Need a SQL-based transformation framework?     → dbt
Need an orchestrator?                          → Airflow / Dagster
Need to dump PG/MySQL to Parquet/CSV safely?   → Rivet
If you stayed on the last line, the
Getting Started guide is ~3 minutes and ends
with one Parquet file you can arrow read or duckdb 'SELECT * FROM read_parquet(…)' against.
Last updated: 2026-07-09.
Getting Started
Rivet exports tables from PostgreSQL, MySQL, and SQL Server (and collections from MongoDB) to Parquet (or CSV) files — locally, to S3, GCS, or Azure Blob Storage. Point it at a database, scaffold a config from your real tables, then run. (MongoDB has its own reference: reference/mongodb.md.)
brew install panchenkoai/rivet/rivet
export DATABASE_URL='postgresql://user:pass@localhost:5432/mydb'
# `orders` is a placeholder — use one of YOUR tables, or omit --table to scan the whole schema
rivet init --source-env DATABASE_URL --table orders -o rivet.yaml
rivet run -c rivet.yaml --validate
That’s the whole flow. The four steps below explain each command, expected output, and where to go from each. Read time: ~3 minutes.
Already running it locally? Jump to §3 Preflight & run. If you’re evaluating it for production, finish this page first, then continue with docs/pilot/.
1 · Install
# macOS / Linux — Homebrew (recommended)
brew install panchenkoai/rivet/rivet
rivet --version
# Docker — try without installing anything
docker run --rm ghcr.io/panchenkoai/rivet:latest --version
Pre-built binaries are published for Linux and macOS (x86-64 + arm64). On
Windows, install from source with cargo install rivet-cli (a native binary
is not currently published). Other install paths — cargo install rivet-cli,
build from source, plus the full Docker recipe with database-on-host pointers
(host.docker.internal vs --network host) — live in the project
README § Installation.
Shell completions: rivet completions bash|zsh|fish.
Try it in 60 seconds — no database of your own
Spin up a throwaway PostgreSQL, seed one table, and export it — nothing external to configure:
docker run -d --name rivet-demo -e POSTGRES_PASSWORD=demo -p 5432:5432 postgres:16
sleep 3
docker exec -i rivet-demo psql -U postgres <<'SQL'
CREATE TABLE orders (id serial PRIMARY KEY, name text, price numeric(10,2),
                     updated_at timestamptz DEFAULT now());
INSERT INTO orders (name, price)
  SELECT 'order-'||g, (random()*500)::numeric(10,2) FROM generate_series(1,500) g;
SQL

export DATABASE_URL='postgresql://postgres:demo@localhost:5432/postgres'
rivet init --source-env DATABASE_URL --table orders -o rivet.yaml
rivet run -c rivet.yaml --validate
# → 500 rows of typed Parquet in ./output/orders/.  Clean up: docker rm -f rivet-demo
That is the whole flow against a real (throwaway) database. Then jump to §4 Inspect & iterate, or read on to point Rivet at your own database.
2 · Connect & scaffold a config
Recommended pattern: put the connection URL in an environment variable and reference it from the config so credentials never enter the file or shell history.
export DATABASE_URL='postgresql://user:pass@localhost:5432/mydb'
# MySQL: same flag, just a mysql:// URL
# export DATABASE_URL='mysql://user:pass@localhost:3306/mydb'

rivet init --source-env DATABASE_URL --table orders -o rivet.yaml
# `orders` is a placeholder — use one of YOUR tables, or omit --table to scan the whole schema
rivet init connects once, reads the column list + a rough row estimate from the live database, and writes a YAML file with url_env: DATABASE_URL and a sensible default mode. For a large table with a single-column primary key it picks keyset (chunk_by_key) — seek paging that stays flat-memory and is immune to sparse/gappy keys; keyset is scaffolded sequential (add parallel: N yourself to fan it into row-percentile ranges). A large table with no single-column PK gets a range chunk_column with a row-scaled parallel: (1 / 2 / 4) out of the box — measured ~1.4× faster on a wide 2 M-row table and ~4× on a narrow one. You can also point it at a whole schema (--schema public) or emit a richer JSON discovery artifact instead (--discover -o discovery.json).
Full flag reference: reference/init.md. For a manually-authored YAML instead of rivet init, see reference/config.md.
State file. Rivet creates
.rivet_state.dbnext to the config (cursors, chunk checkpoints, run history). Add it to.gitignoreif the folder is version-controlled — see SECURITY.md § Sensitive local artifacts.
3 · Preflight & run
rivet doctor -c rivet.yaml   # verify source + destination auth
rivet check  -c rivet.yaml   # dry-run analysis per export
rivet run    -c rivet.yaml --validate --reconcile
The full basic workflow (init → doctor → check → run → state) recorded as a single terminal cast:
What each step does:
-
rivet doctor— connects to the source and writes a tiny probe object (.rivet_doctor_probe) to every destination prefix — removed afterwards on local destinations, while on S3 / GCS / Azure it stays at the prefix (the destination seam has no delete) and is filtered out of manifest and validate listings; fixes nothing, fails loudly on any auth / network issue. -
rivet check— runsEXPLAINagainst your queries, estimates row counts, detects whether your cursor / chunk columns are indexed, and emits a verdict + concrete suggestion. Verdicts areEFFICIENT·ACCEPTABLE·DEGRADED·UNSAFE; on the SQL engines the last two carry a mode-awareSuggestion:line (MongoDB is full-scan-only, so its verdicts omit the mode suggestion). -
rivet run --validate --reconcile— extracts.--validatereads each output file back and verifies its row count;--reconcilerunsSELECT COUNT(*)on the source query and compares with what was exported.
Example summary card after a successful run:
── orders ──
  run_id:      orders_20260519T120000.123
  status:      success
  tuning:      profile=balanced (default), batch_size=10,000 (batch_size_memory_mb=32MiB → effective FETCH in logs)
  rows:        5,432
  files:       1
  output:      file://./output
  bytes read:    1.2 MB
  bytes written: 847.0 KB
  duration:    1.2s
  peak RSS:    15 MB (sampled during run)
  validated:   pass
  schema:      unchanged
  reconcile:   MATCH (5,432/5,432)
4 · Inspect & iterate
rivet state show   -c rivet.yaml             # cursors (incremental exports)
rivet metrics      -c rivet.yaml --last 10   # per-run history
rivet state files  -c rivet.yaml             # files actually written
rivet journal      -c rivet.yaml --export orders   # per-run events / retries / quality issues
To make the second run only export rows that changed, switch the export to incremental mode with a cursor_column: (must be monotonically increasing — usually updated_at or a sequence id):
exports:
  - name: orders
    query: "SELECT id, name, updated_at FROM orders"
    mode: incremental
    cursor_column: updated_at
    format: parquet
    skip_empty: true            # a run with no new rows reports `skipped`
    destination:
      type: local
      path: ./output
Subsequent rivet run invocations will only fetch rows with updated_at > the stored cursor. For tables larger than ~5 M rows, switch to mode: chunked instead — see modes/chunked.md.
5 · Many tables: plan once, apply by waves
When a config has several exports, rivet plan assigns each one a wave — a priority band derived from its size, chunking strategy, and risk (ADR-0006). By default rivet plan is read-only: it prints the schedule for you to review but does not touch the config. Add --annotate-waves to write the wave: / parallel_safe: fields back into the config, where you can see and hand-edit them:
rivet plan -c rivet.yaml                   # review the schedule (read-only)
rivet plan -c rivet.yaml --annotate-waves  # write `wave: N` onto every export, in place
exports:
  - name: users
    wave: 1        # small / cheap → runs first
    # …
  - name: events
    wave: 3        # large → runs later
    # …
rivet apply then runs the whole config wave by wave, lowest first, with a barrier between waves — every export in wave 1 finishes before wave 2 starts. Exports with no wave: run last:
rivet apply rivet.yaml # a .yaml path → wave-ordered execution
(A .json path still means the sealed single-artifact replay — see reference/cli.md § rivet apply.) The plan suggests the waves; you stay in control — hand-edit wave: and apply respects your order.
Parallel within a wave — only where it’s safe
Add parallel_export_processes: true (or pass rivet apply --parallel-export-processes) and, within each wave, the cheap exports — the ones rivet plan marked parallel_safe: true (cost class Low, under ~100K rows) — run concurrently as separate processes. A heavier export already chunk-parallelizes its own ranges internally, so it runs alone in its wave: two big tables at once would multiply the load on the source. The wave stays bounded because only the cheap parallel_safe exports run concurrently, and each child honors its own batch/memory caps (the adaptive back-pressure governor is a separate opt-in: tuning.adaptive: true with parallel > 1).
parallel_export_processes: true # top-level: parallelize the cheap (parallel_safe) exports within each wave
Load into BigQuery or Snowflake (optional)
Rivet stops at typed Parquet by default. To load it into a warehouse, add a
top-level load: block to the same config and run rivet load — the target
table, column types, and source files are all derived from the export (nothing
hand-typed):
# rivet.yaml — the export above, plus a load target
load:
  target: bigquery          # or: snowflake (+ connection / warehouse / database / schema / storage_integration)
  project: my-gcp-project
  dataset: analytics
  cleanup_source: true      # wipe the staged Parquet once the load is row-count-verified
rivet run  -c rivet.yaml    # extract → GCS
rivet load -c rivet.yaml    # load → warehouse (native types; count-gated before any cleanup)
The load follows the export’s mode: — full overwrites the latest snapshot;
incremental / cdc append to <table>__changes and expose a current-state
dedup view keyed on the source primary key rivet run recorded (set pk: [id]
in the load: block for a query: export or to override it). Recipes:
snowflake-load.md ·
cdc-bigquery-load.md.
When something is wrong
Rivet tries to fail early and say exactly what to fix — most mistakes are caught at check / doctor time, before a single row is read.
A query that references a table (or column) that doesn’t exist is caught by rivet check — it exits non-zero with the offending name and SQLSTATE, instead of passing through to a half-finished run:
A typo in a config field is caught at parse time with a Did you mean …? suggestion that names the line:
An unreachable database — down, wrong host/port, or a tunnel that isn’t up — is reported by rivet doctor with a reachability hint before you waste a run:
More failure modes (retries, schema drift, crash/resume) and exactly what rivet does for each: semantics.md.
Next steps
| When you need to … | Go to |
|---|---|
| Pick the right export mode for each table | modes/ — full · incremental · chunked · time_window · cdc |
| Configure S3 / GCS / Azure / stdout destinations | destinations/ |
| Load exports into BigQuery / Snowflake | recipes/snowflake-load.md · cdc-bigquery-load.md |
| Look up a YAML field or a CLI flag | reference/config.md · reference/cli.md |
Understand run_id / cursor / chunk / manifest / journal | concepts.md |
| Tune for memory, throughput, source pressure | reference/tuning.md · best-practices/ |
| Take it to production (read replicas, poolers, monitoring) | pilot/production-checklist.md |
| Run a serious pilot (chunked + reconcile + repair on your data) | pilot/pilot-walkthrough.md |
| See exactly what happens under retry / crash / resume | semantics.md |
| Auditable plan/apply workflow for CI/CD | reference/cli.md § rivet plan · ADR-0005 |
Rivet Cheat Sheet
One page covering setup, extract, load and verification. Every command reads the
same YAML config (-c rivet.yaml). Full references: reference/cli.md ·
reference/config.md · reference/cdc.md.
init → doctor → check → run → validate / reconcile → load
Command builder. On the docs site, fill in the form below and every command
and config on this page is rewritten with your values, ready to copy. On GitHub
the form is not rendered: replace the {{…}} placeholders by hand.
0. Prerequisites: cloud and warehouse
Choose the destination and load target in the form, and the blocks below switch to the matching setup. Skip any step you have already done.
0.1 Destination bucket and credentials
{{CLOUD_SETUP}}
| Destination | Auth rivet supports | Minimum rights |
|---|---|---|
| GCS | ADC (gcloud auth application-default login), or a service-account key (GOOGLE_APPLICATION_CREDENTIALS / credentials_file:) | roles/storage.objectAdmin on the bucket (create, get, list, delete) |
| S3 | temporary keys from aws configure export-credentials (+ session_token_env), static IAM keys (access_key_env / secret_key_env), or a static-key aws_profile: | s3:PutObject, s3:GetObject, s3:DeleteObject, s3:ListBucket, s3:GetBucketLocation |
| Azure | storage account key (account_key_env) or SAS token (sas_token_env) | account key = full access; SAS needs rwdlc |
- rivet does not read
AWS_PROFILE, and SSO/login profiles do not work asaws_profile:. Export temporary credentials instead (thessooption above). - Temporary AWS keys expire, usually after about an hour. Re-run the
export-credentialsline before the next run. - BigQuery and Snowflake loads read GCS only (
destination: type: gcs). A ClickHouse load reads GCS, S3 or Azure. rivet doctor -c rivet.yamlconfirms the credentials can write to the prefix. On cloud storage it leaves a.rivet_doctor_probeobject behind.
More auth paths (MinIO, Azurite, SAS details): cloud-auth.md · cloud-permissions.md.
0.2 Warehouse for rivet load
{{LOAD_SETUP}}
{{LOAD_SQL}}
- BigQuery: the dataset must already exist, because rivet does not create datasets. Keep it in the same location as the bucket.
- Snowflake: database, schema and storage integration must already exist.
rivet creates the file format, stage, tables and views itself, which is why the
role needs the
CREATEgrants above. - ClickHouse (preview): the database must already exist. rivet creates the tables and views over HTTP. Known limits: recipes/clickhouse-load.md.
1. Setup
1.1 Batch (full / incremental / chunked)
brew install panchenkoai/rivet/rivet          # or: cargo install rivet-cli

# Credentials: the password is read without echo, never typed into the command line
printf 'DB password: '; read -rs DB_PASS; echo
export DATABASE_URL="{{URL}}"

# Scaffold a config from the live database
rivet init --source-env DATABASE_URL --table {{TABLE}} --tls {{TLS}}{{INIT_DEST}} -o rivet.yaml    # one table
rivet init --source-env DATABASE_URL --schema {{SCHEMA}} --tls {{TLS}}{{INIT_DEST}} -o rivet.yaml  # whole schema
rivet init --source-env DATABASE_URL --schema {{SCHEMA}} --include 'order*' --exclude '*_tmp' --tls {{TLS}} -o rivet.yaml
rivet init --source-env DATABASE_URL --tls {{TLS}} --discover -o discovery.json   # JSON: row estimates, cursor/chunk candidates

# Preflight
rivet doctor -c rivet.yaml                     # source + destination auth / connectivity
rivet check  -c rivet.yaml                     # EXPLAIN, index checks, verdict per export
rivet check  -c rivet.yaml --type-report --target {{LOAD_KIND}}   # bigquery | snowflake | duckdb | clickhouse
rivet check  -c rivet.yaml --strict            # non-zero exit on any unsafe type mapping
Minimal config:
source:
  type: {{SOURCE_TYPE}}           # postgres | mysql | mssql | mongo | oracle
  url_env: DATABASE_URL           # or url_file: / host+user+password_env+database
  tls: { mode: {{TLS}} }          # disable | require | verify-ca | verify-full (+ ca_file:)
exports:
  - name: {{NAME}}
    table: {{TABLE}}              # or query: / query_file:
    mode: full                    # full | incremental | chunked | time_window | cdc
    format: parquet               # parquet | csv
    compression_profile: balanced # none | fast | balanced | compact
    destination: {{DEST}}
All destination shapes:
destination: { type: local, path: ./output }
destination: { type: gcs,   bucket: my-bucket, prefix: exports/orders/ }
destination: { type: s3,    bucket: my-bucket, prefix: exports/orders/, region: us-east-1 }
destination: { type: azure, bucket: my-container, account_name: acct, account_key_env: RIVET_AZURE_KEY, prefix: exports/ }
.rivet_state.db(cursors, checkpoints, run history) is created next to the config. Add it to.gitignore.
Oracle (preview): the URL path is the service name (
oracle://user:pass@host:1521/ORCLPDB1), not a SID. Unquoted names are upper-case (table: ordersreadsORDERS). Types, modes and limits: reference/oracle.md.
1.2 CDC
Scaffold:
rivet init --source-env DATABASE_URL --mode cdc --table {{TABLE}} --tls {{TLS}} -o cdc.yaml
rivet init --source-env DATABASE_URL --mode cdc --tls {{TLS}} -o cdc.yaml   # whole DB: one `tables:` export (PG/MySQL),
                                                                             # one export per table (SQL Server)
rivet doctor -c cdc.yaml    # also probes slot WAL retention / binlog config / CDC Agent + retention
Source prerequisites:
| Engine | Server config |
|---|---|
| PostgreSQL | wal_level=logical (restart), max_replication_slots>=1, max_wal_senders>=1. For a DELETE to carry more than the primary key, ALTER TABLE <t> REPLICA IDENTITY FULL — the default (d) sends the key alone, which rivet warns about on every run |
| MySQL | log_bin=ON, binlog_format=ROW, binlog_row_image=FULL, binlog_row_metadata=FULL (recommended), binlog retention ≫ the run interval |
| SQL Server | SQL Server Agent running; Enterprise / Standard / Developer (not Express/Web) |
| MongoDB | Replica set required (?directConnection=true for a port-mapped single node) |
| Oracle (preview) | ARCHIVELOG mode, minimal supplemental logging, and ALL COLUMNS supplemental logging on each captured table (key-only logging is refused). The URL path is the pluggable database’s service name; rivet mines from CDB$ROOT. Archived-log retention is the DBA’s: nothing pins logs for rivet |
Grants for the selected engine:
{{CDC_GRANTS}}
Rules of thumb:
- MySQL: connect directly, not through ProxySQL/MaxScale. Give rivet a unique
server_id. - MySQL on RDS / Aurora: two settings that are not in
my.cnf. Binary logging follows automated backups — with retention at 0 the instance runslog_bin = 0and every binlog query answersERROR 1381, whatever the parameter group says. And retention is notbinlog_expire_logs_seconds: RDS purges a binlog as soon as the engine no longer needs it, so the next run’s resume dies withERROR 1236(measured: a checkpoint taken at 13:42 was already past retention at 13:59). Set it explicitly, well above the run interval:CALL mysql.rds_set_configuration('binlog retention hours', 72);A read replica also needslog_replica_updates = 1. - PostgreSQL: an abandoned slot pins WAL and fills the disk. Drop it with
SELECT pg_drop_replication_slot('{{SLOT}}');. Setmax_slot_wal_keep_sizeto cap it. - SQL Server: change-table retention defaults to about 3 days. A run that falls behind it fails loudly and needs a re-snapshot.
- Reading from a replica is verified on every engine: MySQL (
log_replica_updates=ON; rivet refuses a replica without it), PostgreSQL 16+ standbys in continuous mode only (until_current: false), SQL Server readable secondaries and MongoDB secondaries (readPreference=secondary).
CDC config:
source:
  type: {{SOURCE_TYPE}}
  url_env: DATABASE_URL
  tls: { mode: {{TLS}} }
exports:
  - name: {{NAME}}_cdc
    table: {{TABLE}}               # or tables: [a, b]  (one stream, PG/MySQL only)
    mode: cdc
    format: parquet
    cdc:
      initial: snapshot            # first run: anchor → full snapshot → drain stream
      checkpoint: {{CKPT_DIR}}/{{NAME}}.ckpt   # required for a baseline (initial:/backfill:) on every engine but PostgreSQL; MySQL/MongoDB/Oracle need it for any mode: cdc
      until_current: true          # default: drain to the log end as of open, then exit
      {{CDC_PARAM}}
      # rollover: 100000           # rows per part (≈ drain memory)
    destination: {{CDC_DEST}}
With several
mode: cdcexports, each one needs its ownslot,server_idandcheckpoint. The defaults collide, and config validation rejects them.
1.3 One config for the whole cycle: extract → load → compact
Add the warehouse flags to either scaffold above and rivet init writes one file
that drives everything — the exports, the top-level load: block, and the
base-and-buffer layout rivet compact needs. Nothing is hand-added afterwards.
rivet init --source-env DATABASE_URL --table {{TABLE}} --mode incremental --tls {{TLS}}{{INIT_LOAD}} -o rivet.yaml
rivet init --source-env DATABASE_URL --mode cdc --tls {{TLS}}{{INIT_LOAD}} -o rivet.yaml
                                               # whole DB: one `tables:` stream with backfill: auto

rivet doctor  -c rivet.yaml    # source + destination auth
rivet run     -c rivet.yaml    # Parquet → gs://{{BUCKET}}/exports/{{TABLE}}/
rivet load    -c rivet.yaml    # → the base on the first pass, the buffer on later ones
rivet compact -c rivet.yaml    # BigQuery: MERGE the buffer into the base, drop the buffer
- ClickHouse: the cycle is
run+loadonly. The change log is aReplacingMergeTree, the view reads it withFINAL, andrivet compactdoes nothing. The generated block carries nolayout:and nopartition:. - Snowflake:
rivet inithas no Snowflake flags. Scaffold with--gcs-bucketand add theload:block from §3.
Every value in the generated load: block is a guess from the catalog — review it
before the first load. It carries target: bigquery, pk: auto, cluster_by: auto,
cleanup_source: true; a per-table partition: on the creation stamp at
granularity: day (never a mutation stamp, which would move a row between partitions
on every update); and, for a mode that carries deltas (incremental, cdc),
layout: base_buffer so compact has a base to merge into. Field-by-field reference:
§3 below.
--gcs-bucketis required with the BigQuery flags: a BigQuery load reads GCS only, so aload:block over a local or S3 destination is a config its own next step refuses. The ClickHouse flags take--gcs-bucketor--s3-bucket. On a whole-database CDC scaffold the partition guesses land on the stream’sload.tables.<table>blocks — the place the load reads them — not on the per-table recipes, which the load never reads.
2. Extract
2.1 Batch
rivet run -c rivet.yaml                         # all exports
rivet run -c rivet.yaml -e {{NAME}}             # one export
rivet run -c rivet.yaml --validate --reconcile  # verify files + source COUNT(*) match
rivet run -c rivet.yaml --parallel-exports      # exports concurrently (threads)
rivet run -c rivet.yaml --parallel-export-processes   # one child process per export
rivet run -c rivet.yaml -p day=2026-09-14       # substitutes ${day} in queries
rivet run -c rivet.yaml --json --summary-output run.json
rivet run -c rivet.yaml --resume                # continue a crashed chunked run (chunk_checkpoint: true)

# Many tables: plan waves, then apply
rivet plan  -c rivet.yaml                       # read-only schedule
rivet plan  -c rivet.yaml --annotate-waves      # write wave:/parallel_safe: into the config
rivet apply rivet.yaml                          # wave by wave
rivet apply rivet.yaml --resume                 # skip exports with _SUCCESS, resume the rest.
                                                #   WITHOUT it a re-run appends fresh parts beside the old
                                                #   ones and rewrites manifest.json for this run only — a
                                                #   glob reader then double-counts. Clear the prefix first.
rivet apply rivet.yaml --pool 4 --split         # work-stealing pool; split one dominant table.
                                                #   A GENERATED config carries no `parallel_safe:`, so every
                                                #   export counts as heavy and `--pool` alone overlaps
                                                #   NOTHING — run `--annotate-waves` first. `--split` needs a
                                                #   dominant full/chunked/keyset export with a chunk key
                                                #   (never incremental/cdc). Measured on one 1.26M-row set:
                                                #   66s waves · 74s bare --pool · 57s annotated · 42s +split
rivet plan  -c rivet.yaml -e {{NAME}} --format json -o plan.json && rivet apply plan.json   # sealed replay
                                                # `-o` REQUIRES `--format json` (pretty mode ignores it)
Mode snippets:
# incremental: only rows past the stored cursor
mode: incremental
cursor_column: {{CURSOR}}
skip_empty: true
settle: { after: 1h }            # optional: export a row only once it is ≥1h old (s/m/h/d)
                                 # settle.column defaults to the cursor

# chunked, range key
mode: chunked
chunk_column: {{PK}}
chunk_size: 100000
parallel: 4
chunk_checkpoint: true           # enables --resume

# chunked, keyset (unique NOT NULL key, immune to sparse keys)
mode: chunked
chunk_by_key: {{PK}}
chunk_checkpoint: true           # crash recovery only
# keyset_incremental: true       # append-only tables: a clean re-run pulls only new keys

# time_window: rolling N days
mode: time_window
time_column: created_at
days_window: 30
Inspect state:
rivet state show         -c rivet.yaml               # incremental cursors
rivet state reset        -c rivet.yaml -e {{NAME}}   # re-export from scratch
rivet state chunks       -c rivet.yaml -e {{NAME}}   # chunk checkpoint status
rivet state reset-chunks -c rivet.yaml --stuck-checkpoints
rivet state progression  -c rivet.yaml               # committed / verified boundaries
rivet state runs         -c rivet.yaml --running     # run-status ledger
rivet state finish-run   -c rivet.yaml --run-id <id> # close a known-dead `running` row
rivet metrics            -c rivet.yaml --last 10
rivet journal            -c rivet.yaml -e {{NAME}}   # events, retries, quality issues
2.2 CDC
Config-driven (recommended: cloud destinations, TLS, recorded runs):
rivet run -c cdc.yaml                            # bounded: drain, write parts, checkpoint, exit
rivet run -c cdc.yaml --parallel-export-processes   # SQL Server per-table exports in parallel
rivet metrics -c cdc.yaml                        # CDC runs appear with mode=cdc
Schedule rivet run on an interval. Each run resumes from the checkpoint or slot.
cdc.until_current: false streams continuously, but only MySQL and MongoDB stay
up that way. PostgreSQL and SQL Server still exit on catch-up, and Oracle refuses it
at config load (bounded drain only).
Ad-hoc CLI (loopback hosts only, since it has no TLS):
rivet cdc --source-env DATABASE_URL --table {{TABLE}}{{CDC_FLAG}}          # NDJSON to stdout
rivet cdc --source-env DATABASE_URL --table {{TABLE}}{{CDC_FLAG}} \
          --output ./cdc-out --format parquet --checkpoint ./{{NAME}}.ckpt   # typed Parquet (local dir)
rivet cdc --source-env DATABASE_URL --table {{TABLE}}{{CDC_FLAG}} --max-events 10000   # soft cap, stops at a commit boundary
rivet cdc --source-env DATABASE_URL --table {{TABLE}}{{CDC_FLAG}} --stream             # continuous instead of bounded
Output shape: one row per change.
| column | meaning |
|---|---|
__op | insert / update / delete |
__pos | JSON commit position ({"file","pos"} MySQL, {"lsn"} PG/MSSQL, {"low_water","commit_scn"} Oracle). Shared by a whole transaction |
__seq | ordinal within the transaction. (__pos, __seq) is a total order |
| source columns | after-image for insert/update, key for delete |
Delivery is at-least-once, so dedupe downstream on PK + (__pos, __seq).
Parts are named cdc-<run_id>-NNNNNN.parquet and accumulate across runs.
manifest.json and _SUCCESS describe the latest run.
Recovery:
| Symptom | Action |
|---|---|
| Run failed | Re-run. The checkpoint did not advance, so the data is re-read, not lost |
| PG slot invalidated/dropped, MySQL binlog purged (ERROR 1236), MSSQL below retention | Re-baseline in ONE run (the run anchors first, then re-reads the baseline): delete the checkpoint (MySQL/MSSQL/Mongo) or let the slot be recreated (PG), AND clear the export’s cdc_snapshot row + snapshot/_SUCCESS, AND truncate <table>__changes before the next load. Deleting the checkpoint alone is refused (prior-run evidence exists) |
| MySQL checkpoint used against another server | Refused on purpose. Same order on the new host: fresh checkpoint first, then re-snapshot |
3. Load (BigQuery / Snowflake / ClickHouse)
Put a top-level load: block in the same config. The load reads column types
from the state DB and never connects to the source. An Oracle mode: cdc export
cannot feed a load: block yet (refused at config load). An Oracle batch export under
load: is accepted, but no live test loads one into a warehouse yet.
load:
  {{LOAD_TARGET}}
  pk: auto                      # auto (recorded source PK) | none | [col, ...]   — incremental/cdc dedup key
  cluster_by: auto              # auto | none | [col, ...]  (≤4 on BigQuery; a full-load table's ORDER BY on ClickHouse)
  partition:                    # none (default) | exactly one of column / range / ingestion. Not on ClickHouse
    column: {{CURSOR}}
    granularity: day            # hour | day | month | year
    # range: { column: n, start: 0, end: 1000000, interval: 1000 }
    # ingestion: day
    expiration_days: 90
    require_filter: false
  cleanup_source: true          # delete staged Parquet after the count gate passes
  gc_orphans: false             # also delete unmanifested crash leftovers
  allow_source_drift: false     # load even if the manifest's source count ≠ extracted
  layout: base_buffer           # log_view (default for incremental / capture-only CDC) | base_buffer
                                #   base_buffer: `<table>` is a PHYSICAL table, `<table>__changes` a
                                #   per-cycle buffer that `rivet compact` MERGEs in and drops. BigQuery only.
                                #   Absent: a CDC stream with `backfill:` gets base_buffer, the rest log_view.
  deleted_flag: true            # whether the base carries `__is_deleted`; absent: true for cdc, false otherwise
exports:
  - name: {{NAME}}
    # ...
    load: { pk: [{{PK}}], partition: none }   # per-export override: pk, cluster_by, partition, cleanup_source, gc_orphans, allow_source_drift, layout, deleted_flag
    # a multiplex `tables:` stream adds `tables: { <table>: { pk: [...], partition: none } }` — one block per captured table
Required target fields: BigQuery takes project and dataset. Snowflake takes
connection (a snow CLI connection), warehouse, database, schema and
storage_integration. ClickHouse takes url, database, user and password_env,
plus an optional named_collection (ClickHouse then reads the bucket itself). ClickHouse
refuses partition:, layout: base_buffer and a MongoDB CDC stream.
rivet run  -c rivet.yaml              # extract → bucket
rivet load -c rivet.yaml              # load → warehouse
rivet load -c rivet.yaml --run-id "nightly-$(date +%F)"   # tag jobs (BQ label / Snowflake QUERY_TAG)
rivet load -c rivet.yaml --rebuild-changelog               # allow a billed rebuild when partitioning changed
rivet compact -c rivet.yaml           # base_buffer only: MERGE `<table>__changes` into `<table>`, drop the buffer
rivet state loads -c rivet.yaml -t {{WAREHOUSE_TABLE}}
What the load does for each export mode::
| mode | warehouse result |
|---|---|
full | OVERWRITE the table with the latest snapshot. Re-running is idempotent |
incremental | log_view (default): append to <table>__changes, plus a current-state view deduped on pk. layout: base_buffer: the first pass lands <table> as a physical base, every later delta lands in the buffer <table>__changes, and rivet compact merges it in (latest per pk) and drops the buffer — the cycle is run → load → compact. DELETES ARE NOT CAPTURED: a cursor read only sees rows whose cursor advanced, and a deleted row has none, so the warehouse keeps it forever (deleted_flag is off for non-CDC, so there is no __is_deleted to set). Use mode: cdc if deletions must reach the warehouse |
cdc | append to <table>__changes, plus a view keeping the latest (__pos, __seq) per PK with __is_deleted (soft delete: live rows are WHERE NOT __is_deleted) |
cdc with tables: | one __changes table and one view per source table |
Guarantees:
- Manifest-driven. The load uses only the parts listed in
Successmanifests, never a prefix glob. - Count gate. The warehouse
COUNT(*)must equal the summed manifest rows before the load completes or cleans up. - Cost labels. BigQuery jobs are labelled
managed_by:rivet,rivet_op:{load,count,create,alter,view}andrivet_table:<t>.
4. Data verification
4.1 Built into the run
rivet run -c rivet.yaml --validate      # every manifest part present at its recorded size + _SUCCESS
rivet run -c rivet.yaml --reconcile     # + source COUNT(*) == exported rows (a mismatch fails the run)
exports:
  - name: {{NAME}}
    verify: content          # size (default) | content: require MD5 match per part (no download)
    on_schema_drift: fail    # warn (default) | continue | fail (exit 4)
    quality:
      row_count_min: 1000
      row_count_max: 10000000
      null_ratio_max: { {{PK}}: 0.0 }   # single runner only
      unique_columns: [{{PK}}]          # single runner only
      unique_max_entries: 1000000       # always cap memory
4.2 After the fact, without extracting
rivet validate -c rivet.yaml                       # full: manifest + parts + value-checksum re-read
rivet validate -c rivet.yaml --depth light         # manifest + _SUCCESS only (fast poll)
rivet validate -c rivet.yaml --depth sample        # + part reconcile + untracked surplus
rivet validate -c rivet.yaml -e {{NAME}} --date 2026-09-13   # a prior day's {date} prefix
rivet validate -c rivet.yaml -e {{NAME}} --prefix exports/{{NAME}}/2026-09-13/
rivet validate -c rivet.yaml --format json -o validate.json
For CDC, rivet validate descends into every table prefix and its snapshot/.
A missing _SUCCESS means the run did not finish cleanly.
4.3 Source vs export (chunked, chunk_checkpoint: true)
rivet reconcile -c rivet.yaml -e {{NAME}}                           # per-chunk recount; non-zero exit on mismatch
rivet reconcile -c rivet.yaml -e {{NAME}} --format json -o rec.json
rivet repair    -c rivet.yaml -e {{NAME}} --report rec.json         # print the repair plan
rivet repair    -c rivet.yaml -e {{NAME}} --report rec.json --execute   # re-export mismatched ranges only
4.4 Independent oracle (not rivet’s own bookkeeping)
DuckDB fingerprints the source query and the Parquet separately (rows, distinct key, non-null counts, sums, lengths). The script supports PostgreSQL and MySQL sources.
pip install duckdb
python dev/correctness/verify_export.py \
  --source-type {{VERIFY_TYPE}} \
  --dsn "{{DSN}}" \
  --query "SELECT * FROM {{TABLE}}" \
  --parquet "/path/to/{{NAME}}/*.parquet" \
  --key {{PK}}                 # exit 0 = PASS, 1 = FAIL
A prefix with orphaned pre-crash parts reads high. Verify only the parts named in
manifest.json.Run this BEFORE
rivet load, or setcleanup_source: false: the generatedload:block setscleanup_source: true, so a successful load deletes the staged Parquet and leaves this oracle nothing to read.
CDC replay check in DuckDB (latest image per key; the LSN parsing is PostgreSQL’s):
WITH ev AS (
  SELECT *, upper(lpad(split_part(__pos->>'lsn','/',1),8,'0')) ||
            upper(lpad(split_part(__pos->>'lsn','/',2),8,'0')) AS lsn_key
  FROM read_parquet('cdc-out/cdc-*.parquet')
)
SELECT * FROM (
  SELECT *, row_number() OVER (PARTITION BY {{PK}} ORDER BY lsn_key DESC, __seq DESC) rn FROM ev
) WHERE rn = 1 AND __op <> 'delete';
-- compare with: SELECT * FROM {{TABLE}};  on the source
4.5 Warehouse side
-- BigQuery: what each rivet step cost
SELECT (SELECT value FROM UNNEST(labels) WHERE key='rivet_op')    AS op,
       (SELECT value FROM UNNEST(labels) WHERE key='rivet_table') AS tbl,
       COUNT(*) jobs, SUM(total_bytes_billed) bytes_billed
FROM `region-us`.INFORMATION_SCHEMA.JOBS
WHERE EXISTS (SELECT 1 FROM UNNEST(labels) WHERE key='managed_by' AND value='rivet')
GROUP BY op, tbl ORDER BY bytes_billed DESC;

-- current state of a CDC load vs the source (cdc only: `__is_deleted` exists
-- when `deleted_flag` is on, which is the default for cdc and OFF otherwise —
-- on an `incremental` base this query fails with "Unrecognized name")
SELECT COUNT(*) FROM {{WAREHOUSE_SQL}} WHERE NOT __is_deleted;

-- an incremental / full base has no delete flag: count it plainly
SELECT COUNT(*) FROM {{WAREHOUSE_SQL}};
4.6 Inspection
rivet state files -c rivet.yaml -e {{NAME}} --json   # files actually written
rivet metrics     -c rivet.yaml -e {{NAME}} --json   # rows / files / bytes / status per run
                                                     #   NOTE: neither reaches `--split` sub-units — their
                                                     #   run ids are `<export>#0…#N` and `-e` only accepts a
                                                     #   config export name. Use `rivet state runs`, which
                                                     #   does list them.
rivet journal     -c rivet.yaml -e {{NAME}} --run-id <id>
Last updated: 2026-07-09.
Concepts
A one-page glossary of the terms Rivet uses everywhere — run_id, cursor, chunk, manifest, journal, progression. Read it once, then come back when a doc / CLI output references a term you’ve forgotten.
If you want the binding execution semantics (what’s at-least-once, what survives a crash, what doesn’t), see semantics.md. This page is the orientation; that one is the contract.
Two top-level objects
| Term | What it is | Where it lives | How to see it |
|---|---|---|---|
| Export | A named entry in rivet.yaml — a query + cursor / chunk strategy + destination triple. One config file can have many exports. | exports[]: array in the YAML. | rivet check lists them; rivet plan resolves them; rivet run extracts them. |
| Run | One invocation of rivet run. Produces zero or more files per export. Has a unique run_id. A single run can extract one or many exports. | The state DB (run_journal, export_metrics) + the per-run report artifacts .rivet/runs/<run_id>/summary.{json,md}. | rivet metrics --last N · rivet journal --export NAME. |
The same export can be extracted by many runs over time. Each run gets its own run_id; the export’s cumulative state (cursor, chunks done, files written) accretes across runs.
How the data is sliced
| Term | What it is | Used by |
|---|---|---|
| Mode | The extraction strategy: full (re-export everything), incremental (only rows newer than the last cursor), chunked (split a big table into N range chunks), time_window (rolling N-day window), cdc (change data capture — inserts/updates/deletes captured to Parquet/CSV files from the source’s replication log, resuming from the last committed log position each run). | One per export. See modes/. |
| Batch | One FETCH worth of rows materialised as an Arrow RecordBatch. Streamed and discarded — never accumulated in memory. Controlled by tuning.batch_size (rows) or tuning.batch_size_memory_mb (memory budget). | Every mode. The batch_size setting is what protects your source DB from a single huge fetch. |
| Chunk | A row-range slice of a chunked export (e.g. id BETWEEN 0 AND 50000). Each chunk runs as its own SQL SELECT and produces its own output file. Has a checkpoint row in the state DB so a crashed chunked run can --resume without re-exporting completed chunks. | Only mode: chunked. |
| Cursor | The last extracted value for incremental exports (a number, timestamp, or composite tuple). Next run starts from > cursor. | Only mode: incremental and the after-the-fact cursor recorded by mode: chunked runs. |
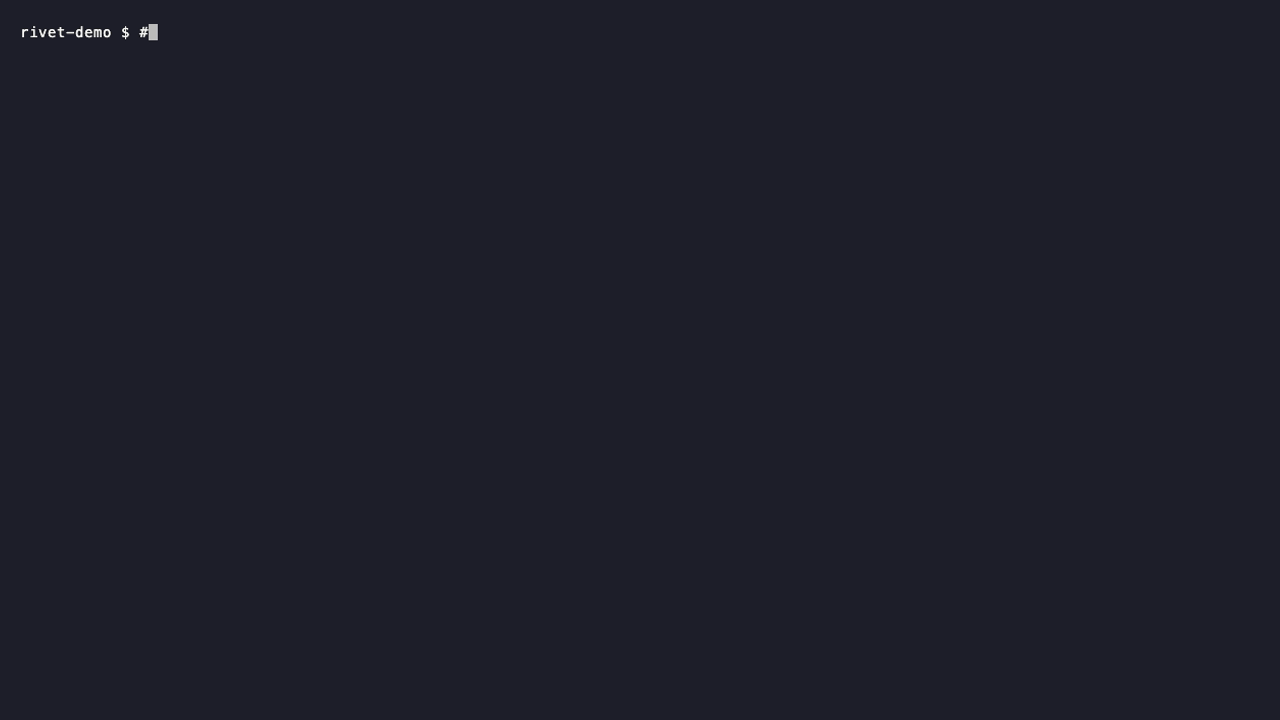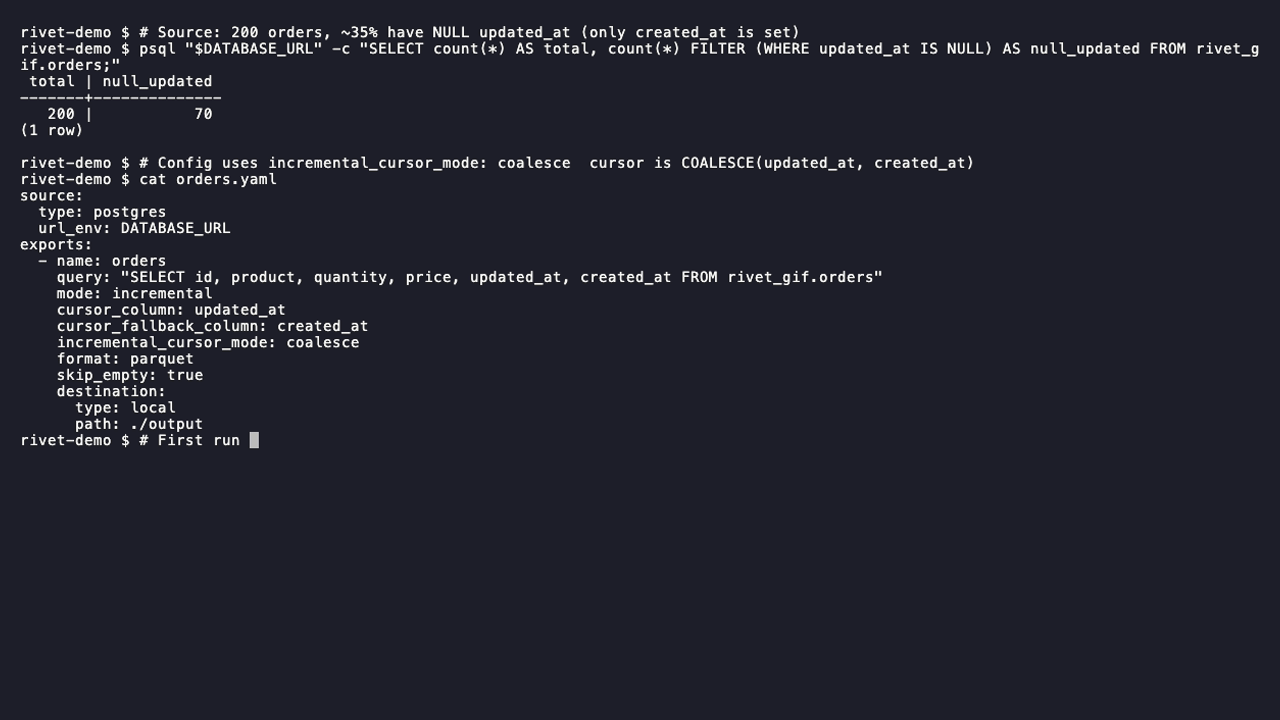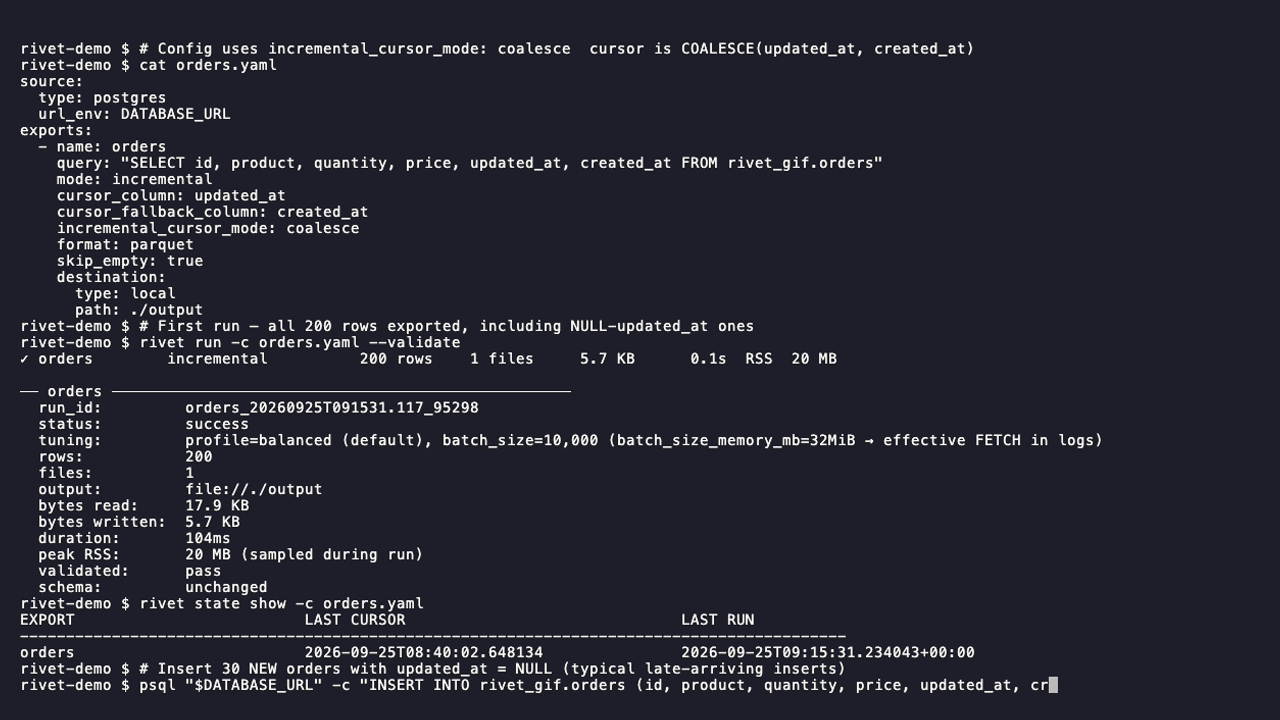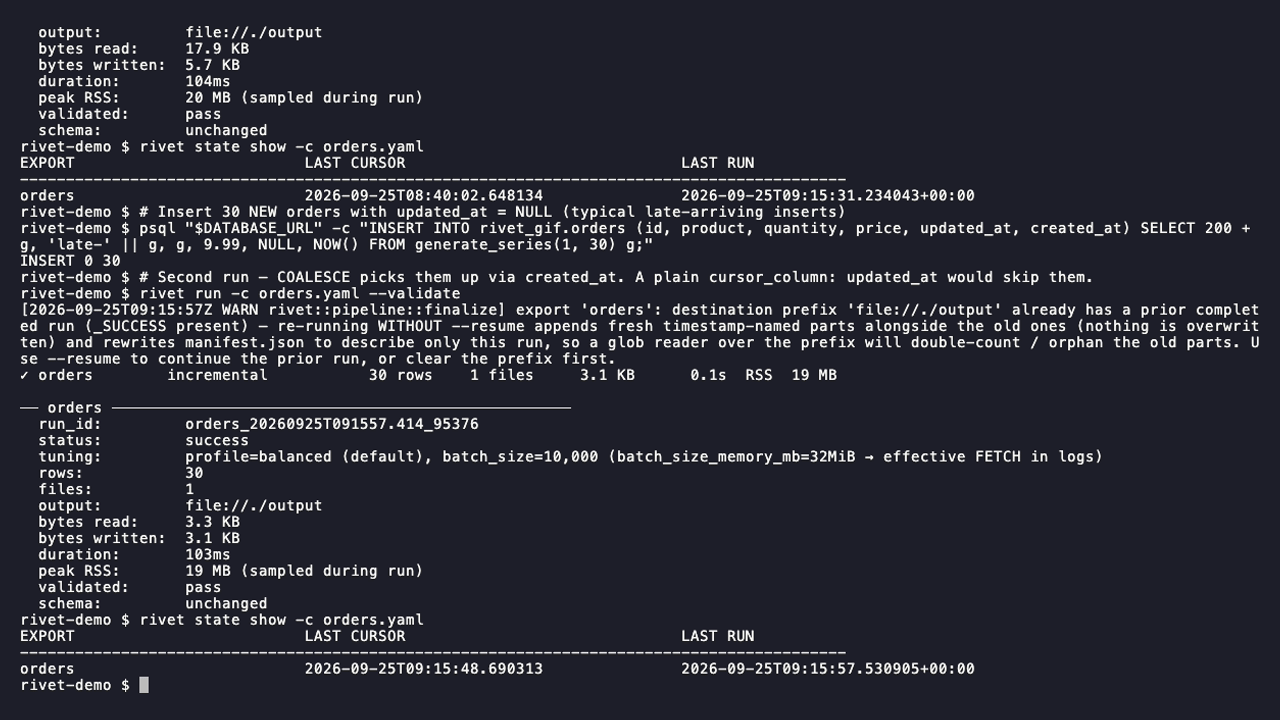
| Composite cursor | A COALESCE(primary, fallback) cursor — for tables where the primary column (e.g. updated_at) is nullable for some rows and a fallback (e.g. created_at) carries those rows forward. Stored as a single scalar; demoed in coalesce-cursor.gif; contract in ADR-0007. | Set incremental_cursor_mode: coalesce + cursor_fallback_column. See modes/incremental-coalesce.md. |
What’s recorded after each run
| Term | What it is | Table in .rivet_state.db | CLI |
|---|---|---|---|
| File log | The per-export ledger of files actually written — file name, row count, bytes, format, compression. Authoritative answer to “what files did this export produce?” Renamed from file_manifest in schema v8; the Manifest term now names the per-output-prefix manifest.json cloud-output contract that ships today (written alongside _SUCCESS in each destination prefix; carries per-part content_fingerprint for idempotent downstream loads). | file_log | rivet state files --export NAME |
| Metrics | One row per run per export — run_id, status, rows, bytes, duration, peak RSS, retries, validation / reconcile result. Authoritative answer to “how did this export perform over time?” | export_metrics | rivet metrics --export NAME --last N |
| Journal | Per-run event stream — every chunk start / complete / fail, every retry, every quality-gate decision, the first-line error text. Authoritative answer to “what happened during this specific run?” | run_journal table (one JSON document per run in the state DB) | rivet journal -c rivet.yaml --export NAME --run-id ID |
| Progression | The committed / verified boundary per export — for chunked, the highest contiguous chunk index that fully succeeded; for incremental, the high-water cursor value that has been reconciled. Advisory only (operator-readable; nothing in the pipeline depends on it). | export_progression | rivet state progression |
| Chunk checkpoint | Per-chunk row in the state DB tracking status (pending · running · completed · failed), attempt count, and first-line error. Only populated when chunk_checkpoint: true is set. | chunk_run + chunk_task | rivet state chunks --export NAME |
The decisive write order across these (which write happens before which) is the State Update Invariants in ADR-0001 — the I1-I7 sequence. The user-facing summary of “what happens if the process dies between I3 and I4” is in semantics.md § Crash semantics.
Two flags that are easy to confuse
| Flag | What it does | Cost |
|---|---|---|
--validate | Reads the output Parquet / CSV file back from disk after writing it. Asserts the row count in the file equals the row count Rivet thought it wrote. Catches silent writer bugs and partial writes. | One extra pass over the just-written file. Cheap. |
--reconcile | Runs SELECT COUNT(*) against the source query and compares with the total row count exported. Catches discrepancies between “what the cursor / chunk loop saw” and “what the source actually has”. | One extra COUNT(*) query per export. On a multi-million-row table this can take longer than the export itself. Worth it for first runs and weekly audits. |
Both are off by default; both add one line to the run summary. For chunked exports the dedicated per-partition reconcile + targeted repair workflow lives in rivet reconcile / rivet repair — see reference/cli.md § rivet reconcile and ADR-0009. The CLI flag --reconcile is the cheaper aggregate-only version.
Plan / apply (auditable execution)
| Term | What it is |
|---|---|
| Plan artifact | A sealed JSON document produced by rivet plan. Captures the resolved config, query fingerprints, preflight diagnostics, computed chunk boundaries, and cursor snapshots at planning time. Plaintext password: and scheme://user:pass@ userinfo are stripped at write time (ADR-0005 PA9); env / file references are preserved so the apply environment can re-resolve them. |
| Apply | rivet apply plan.json executes exactly the pre-computed plan. Refuses to run if the config has changed, if the cursor has advanced since plan time, or if the plan is older than 24 h (without --force). Designed for CI/CD review-then-execute workflows. |
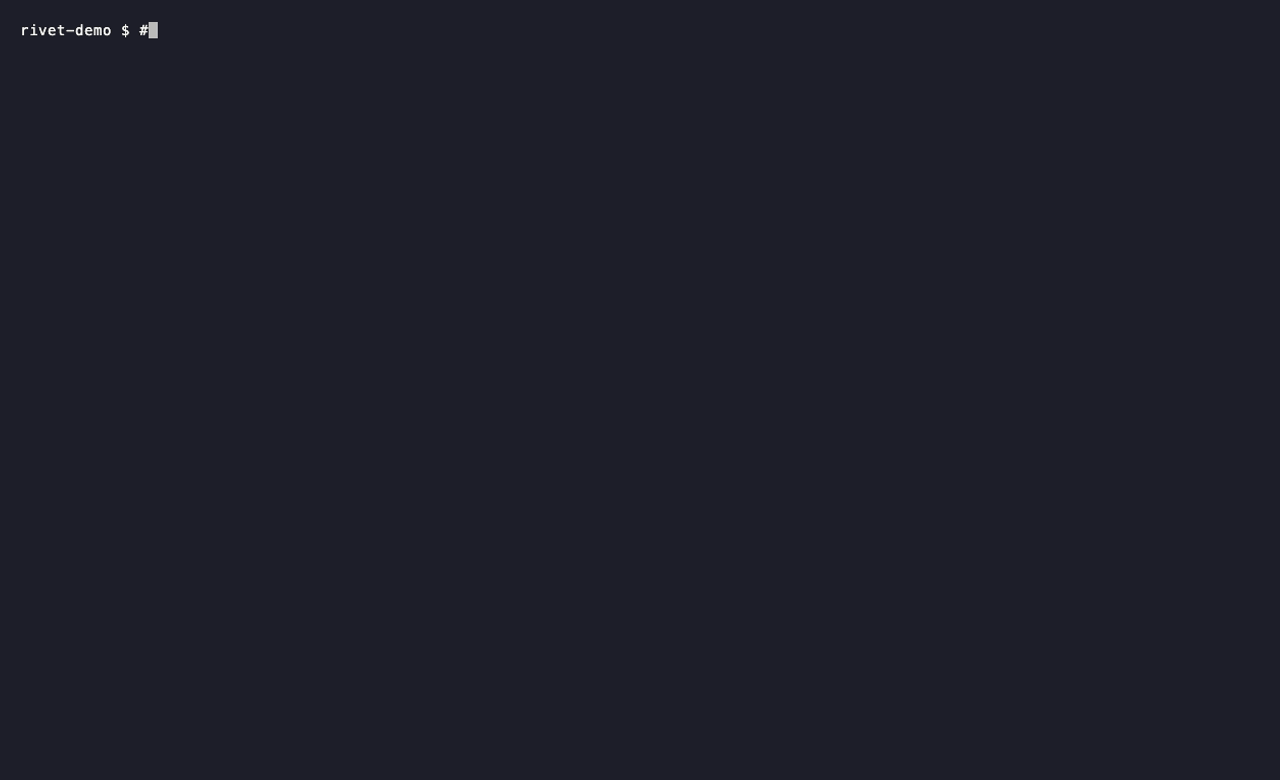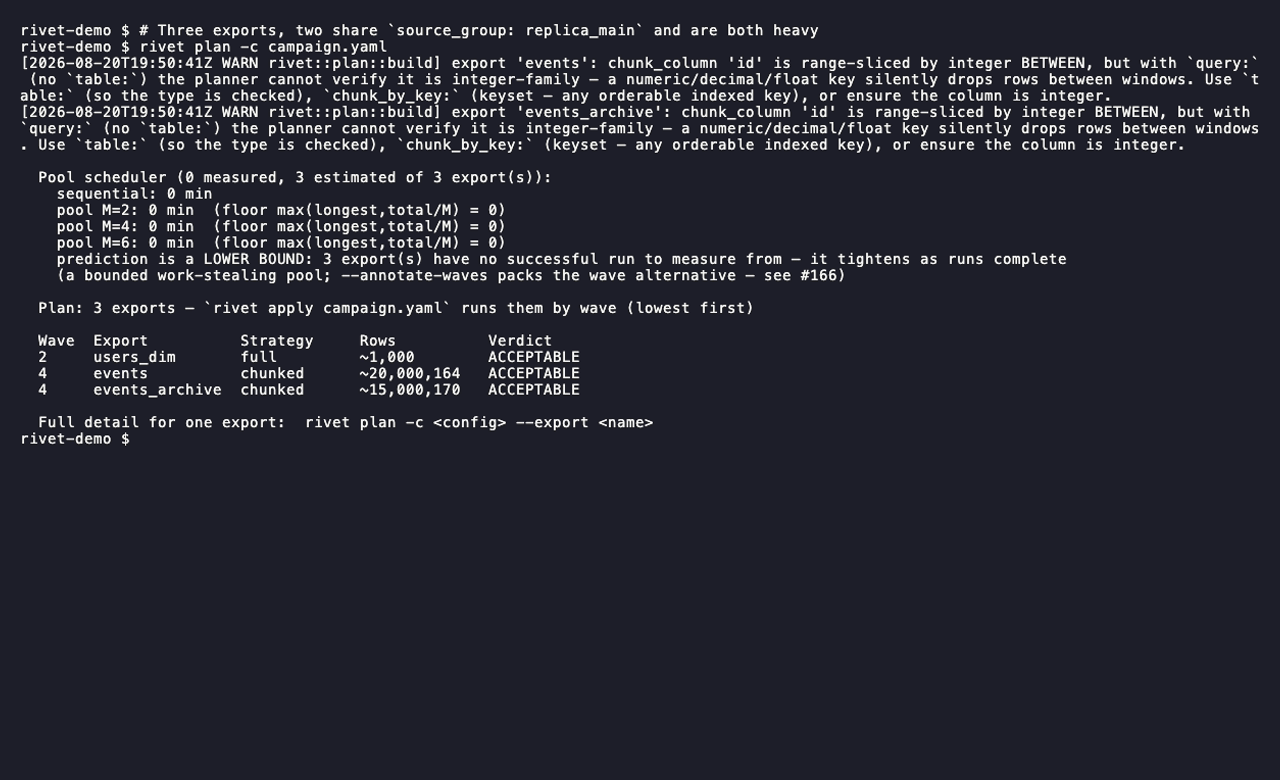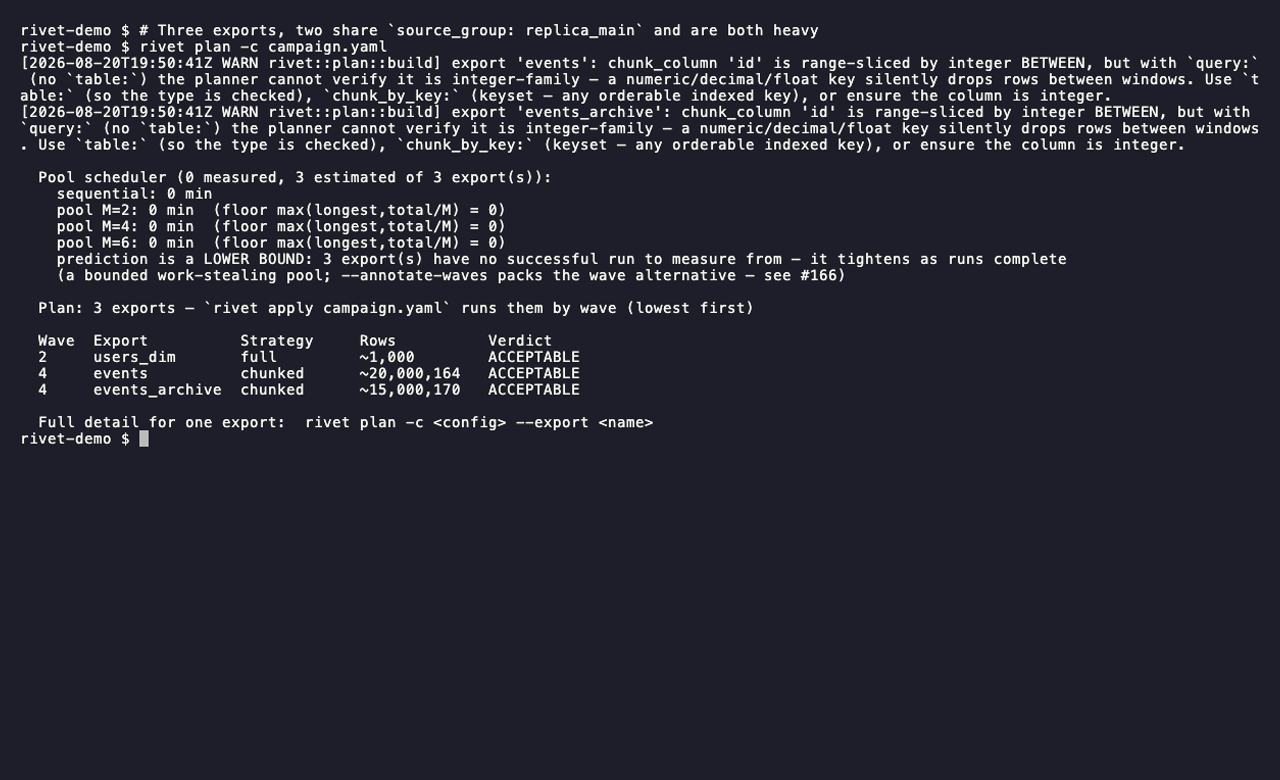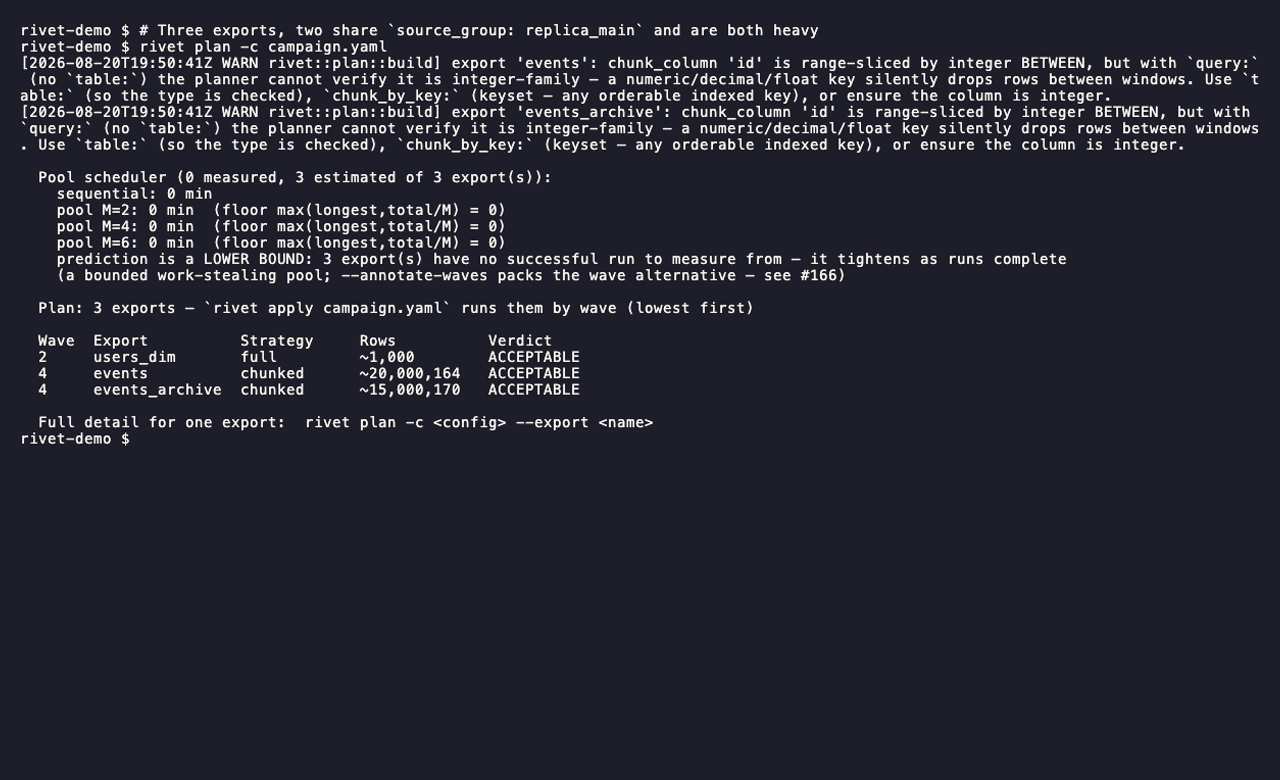
| Campaign / waves | When rivet plan is run on a multi-export config, the artifact embeds a CampaignRecommendation — exports sorted by an advisory priority score, grouped into execution waves, plus source_group warnings when several heavy exports share a replica (e.g. isolate_on_source: true). The priority score and grouping are advisory (ADR-0006), but Rivet can execute the waves itself: rivet apply <config>.yaml runs the exports wave-by-wave in ascending wave: order (optionally with --parallel-export-processes and --resume), or — with --pool N (optionally --split) — as a wave-less work-stealing pool (longest-first LPT scheduling) that replaces the wave barriers entirely and does not honor wave: tiers; an external scheduler (Airflow / cron / GH Actions) is optional. Demoed in plan-campaign.gif. |
You can stick with rivet run for everything; plan/apply is only there when you want a pre-execution review object that survives in a PR or a CI artifact.
Source-aware connections
| Term | What it is |
|---|---|
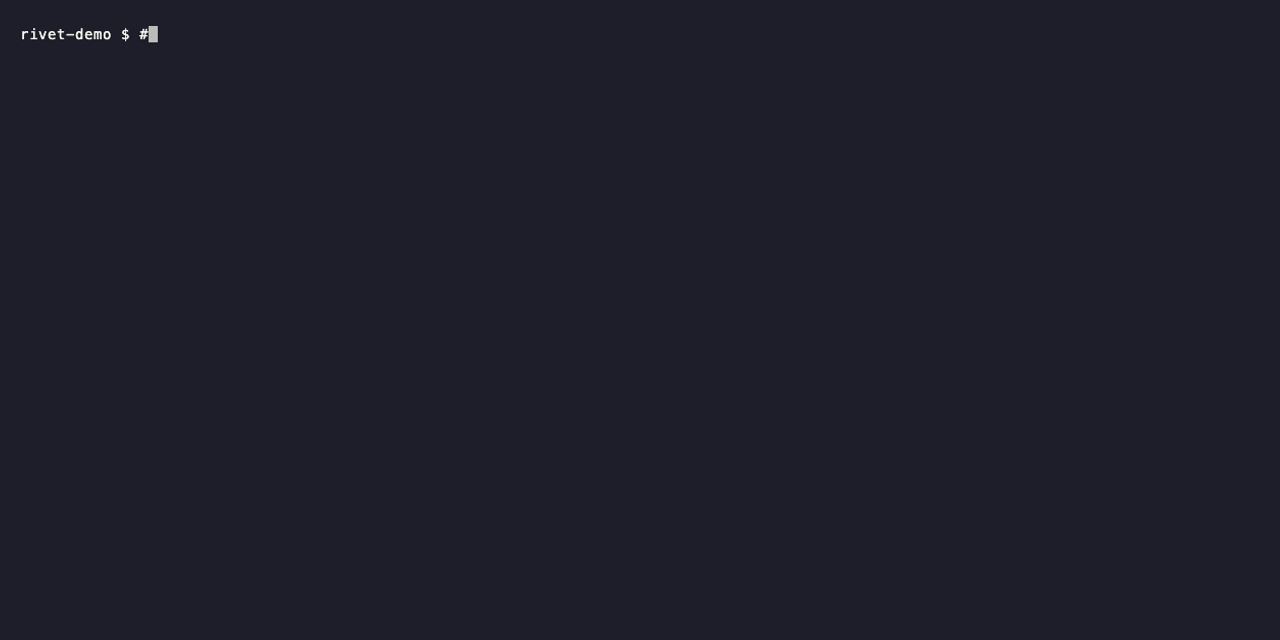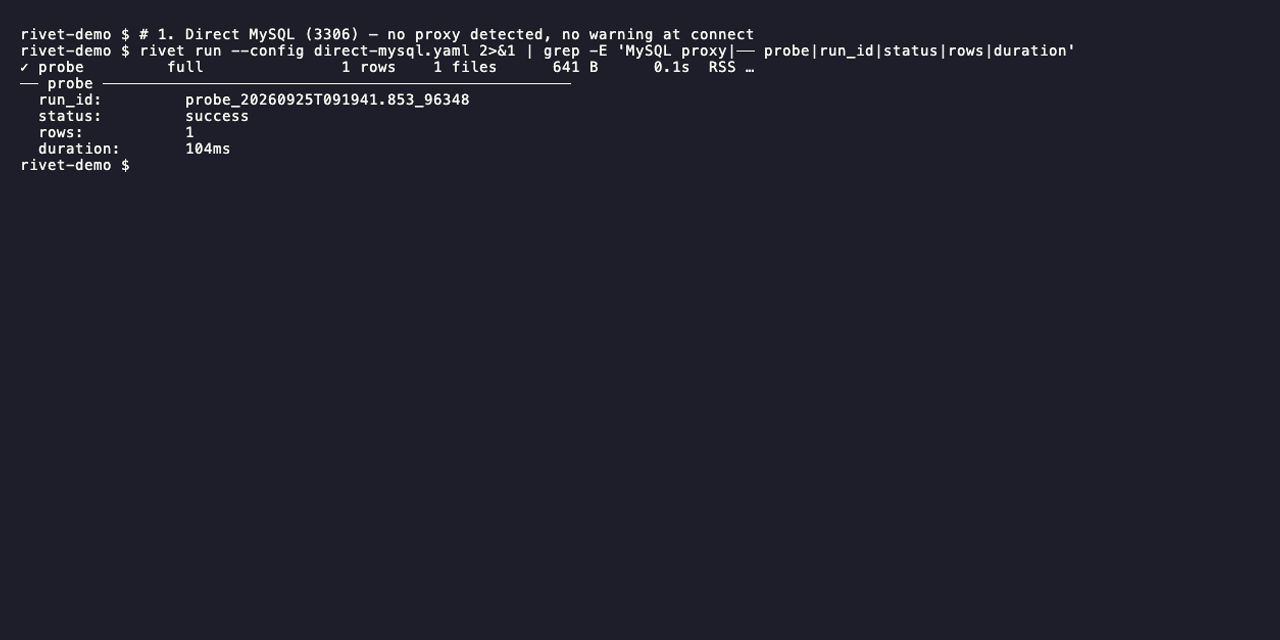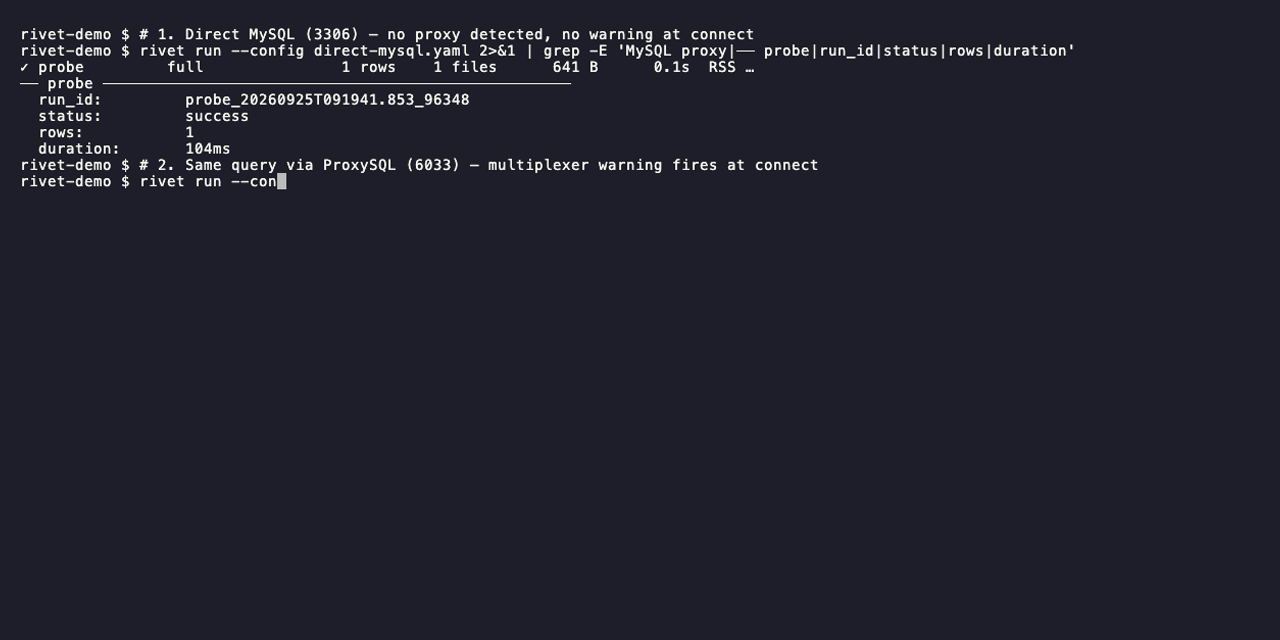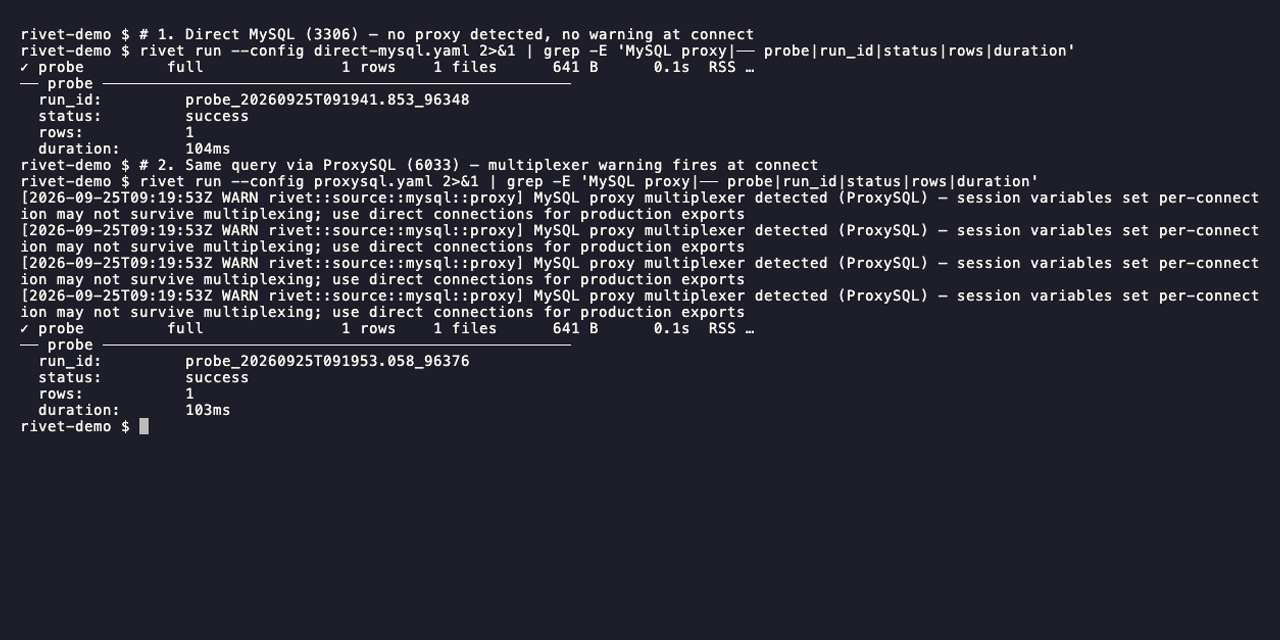
| Pool detector | At connect time Rivet probes for connection pooling and warns about subtle failure modes. PG: a PID-flip probe (pg_backend_pid() twice) flags pgBouncer / Odyssey in transaction mode — LISTEN/NOTIFY and advisory locks won’t survive. MySQL: a 4-signal classifier (PROXYSQL INTERNAL SESSION accepted · @@version_comment banner · @@proxy_version presence · CONNECTION_ID() drift) distinguishes Direct / ProxySql / MaxScale / Multiplexed. SQL Server: @@SPID drift across two consecutive queries on one connection flags a transaction-mode multiplexer (Multiplexed); SERVERPROPERTY('EngineEdition') of 5 / 8 (or an Azure @@VERSION banner) flags the AzureGateway fronting Azure SQL DB / Managed Instance. All Postgres tuning uses SET LOCAL inside an RAII-guarded BEGIN…COMMIT so session state is never leaked into the pool. Demo: pool-detect.gif. |
| MCP server | A separate binary, rivet-mcp, that speaks Model Context Protocol over stdin/stdout. Exposes read-only DB introspection tools (pg_stat_activity, checkpoint pressure, pg_stat_statements I/O, MySQL processlist, pgBouncer diagnostics) to MCP clients like Claude Desktop and Claude Code. Read-only — no DDL, no writes. Source: src/bin/rivet-mcp.rs + src/mcp.rs. |
Where each concept is exercised in the code
If you want to track a concept from this glossary back to the implementation:
Sourcetrait +ExportRequest—src/source/mod.rs- Cursor / incremental —
src/source/query.rs(predicate builder) +src/state/cursor.rs - Chunked / checkpoint —
src/pipeline/chunked/{mod, sequential_checkpoint, parallel_checkpoint}.rs+src/state/checkpoint.rs - File log + Metrics —
src/state/{file_log, metrics}.rs - Journal —
src/journal.rs(top-level) +src/state/journal_store.rs - Progression —
src/state/progression.rs(ADR-0008) - Validate / reconcile (CLI) —
src/pipeline/{validate, reconcile_cmd}.rs - Plan / apply —
src/pipeline/{plan_cmd, apply_cmd}.rs+src/plan/
Where to go next
- getting-started.md — the 5-minute install + first export, if you skipped it
- semantics.md — the binding execution contract (what’s at-least-once, what survives crashes)
- modes/ — when to pick
fullvsincrementalvschunkedvstime_windowvscdc - adr/ — every contract in this glossary has a numbered ADR with the rationale
Execution Semantics
How Rivet behaves under normal execution, retries, crashes, resume, repair, and reconcile. This is the contract a downstream pipeline can build on.
This page is a user-facing summary. The binding contracts live in the ADRs, which this document links into.
Scope
This document describes guarantees and known non-guarantees for:
- single-table exports (full, incremental, chunked, time-window, cdc),
- destination writes (local, S3, GCS, Azure Blob Storage, stdout),
- state and journal updates,
- automatic retries and
--resumeafter crashes, rivet reconcileandrivet repair,- in-process and subprocess parallelism.
It does not cover database / network / disk failures whose mode is external to Rivet (e.g. a corrupted Parquet file caused by a bad disk).
Core concepts
| Term | Meaning |
|---|---|
| Run | One invocation of rivet run. Has a unique run_id. Produces zero or more output files. |
| Export | A named entry in rivet.yaml — a query + cursor + destination triple. One run executes one or many exports. |
| Mode | full, incremental, chunked, time_window, cdc. See docs/modes/. |
| Batch | One FETCH worth of rows materialized as an Arrow RecordBatch. Streamed; never accumulated in memory. |
| Chunk | A row range (chunked mode) processed as one unit. Produces one output file. Has a checkpoint row in the state DB. |
| Cursor | The last extracted value for incremental exports. Stored in export_state.last_cursor_value. |
| File log | The per-export ledger of files written to the destination (file_log table, renamed from file_manifest in schema v8). |
| Journal | A per-run event log, persisted as a single JSON document in the state DB (run_journal table); inspect with rivet journal. Authoritative for “what happened when” during one run. |
| Progression | The committed / verified boundary per export (export_progression table). Advisory only. |
Normal execution
The pipeline is one straight line per export (see architecture.md § Data flow):
begin_query → FETCH batch → write batch to temp file
                          → next FETCH
                          → ...
            → finalize writer
            → destination.write(temp_file)
            → record manifest entry
            → advance cursor (incremental) / record chunk completion (chunked)
            → record metric (at end of run)
The exact state-write ordering is defined by ADR-0001 — State Update Invariants (I1–I7). The pipeline source code references these IDs at the call sites.
Retry semantics
Retries are classified by error type in src/pipeline/retry.rs:
The classifier (RetryClass) has two outcomes — Transient (retry) and Permanent (propagate):
| Class | Examples | Retried? |
|---|---|---|
Transient | connection reset, “server has gone away”, lock-wait timeout, deadlock / serialization failure, “too many connections”, cloud (temporary) writes (S3 / GCS) | Yes — exponential backoff up to tuning.max_retries. The variant carries needs_reconnect (reopen the source connection first — e.g. a network reset or 08xxx SQLSTATE) and extra_delay_ms (an added settling delay for capacity errors like “too many connections” / “database system is starting up”) |
Permanent | syntax error, auth failure, missing table / column, a statement-duration timeout (statement_timeout / max_execution_time) | No — propagates immediately. Uncategorized errors default to Permanent (they are not retried) |
A retried batch starts from the same cursor position as the failed attempt — see ADR-0001 I3 (Write Before Cursor). At-least-once delivery to the destination is therefore possible: on retry after a destination write succeeded but the cursor failed to advance, the same rows are written again, producing a duplicate file.
Retry-safety per destination is declared by capabilities().retry_safe — see ADR-0004 — Destination Write Contracts:
| Destination | retry_safe |
|---|---|
| S3, GCS, Azure | true (no partial visible objects; safe to retry) |
| Local filesystem | true (staged temp file + atomic rename; a failure leaves nothing at the final path) |
| stdout | false (no commit boundary; retry produces duplicate/corrupt output) |
When retries occur against a non-retry-safe destination, the pipeline logs a WARN so operators see the mismatch.
Crash semantics
If the process is killed (SIGKILL, OOM, host reboot), the next state depends on where the crash landed. The full failure-point map is in ADR-0001 § Failure Point Map. Summarised:
| Crash point | Files at destination | Manifest | Cursor | Next run does |
|---|---|---|---|---|
Mid-extraction (before dest.write) | none | no entry | not advanced | re-extract from last cursor |
After dest.write, before manifest | file present | no entry | not advanced | re-extract → duplicate file at destination |
| After manifest, before cursor | file present | entry | not advanced | re-extract → second duplicate + manifest entry |
| After cursor update | file present | entry | advanced | next run starts from new cursor; metric may be missing |
Clean error (Err return) | none | no entry | not advanced | normal retry |
Two strong invariants hold across every crash point:
- No row is silently skipped. The cursor only advances after the corresponding write succeeds (I3).
- No file at the destination is incomplete. Writers are finalized before destination upload (I1).
The trade-off is at-least-once at the destination: a crash between write and cursor advancement produces a duplicate file. Downstream consumers must tolerate this — see Known non-guarantees below.
Resume semantics
rivet run --resume consults the state DB to decide what work is outstanding. A
plain rivet run (no --resume) never skips the chunks of a run that
FINISHED — it does a fresh full pass. A checkpointed run holds its export’s run
lease (an flock beside a SQLite state DB, a session advisory lock on a Postgres
one) for as long as the process lives, and the OS releases it when the process
dies, kill -9 included. So when a plain run finds a chunk-checkpoint run still
in progress:
- its process is gone (the lease is free): the run resumes it, exactly as
--resumewould. Achunk_denseplan cannot be resumed, so it starts over. - its process is alive (the lease is held): the run is refused, and so is
--resume— wait for the live run to finish.
What --resume does:
- Incremental exports resume from
export_state.last_cursor_value. - Chunked exports consult the
chunk_tasktable: tasks incompletedare skipped; tasks inpendingorrunning(the latter reset topendingon resume) are re-issued; tasks infailedare retried whileattempts < max_chunk_attempts. - Full and time-window modes do not resume — they restart from the beginning. The previous run’s output files remain at the destination unless cleaned manually.
Chunk task transitions are strictly forward (pending → running → {completed | failed}). A completed chunk is never re-claimed, even after a crash — see ADR-0001 I5 (Chunk Task Acyclicity).
Repair semantics
rivet repair re-exports specific chunks identified as mismatch or unknown by a prior rivet reconcile. The full contract is ADR-0009 — Reconcile and Targeted Repair.
Key properties:
- Repair derives only from a reconcile report (RR1). There is no operator-typed chunk range.
- Dry-run by default (RR2).
--executeis required to perform writes. - Repair writes new files alongside originals (RR5). Rivet does not delete or overwrite prior destination files. Downstream dedup is the operator’s responsibility.
- Repair does not advance the committed boundary (RR4). Run
rivet reconcileagain afterwards to advancelast_verified_*.
Reconcile semantics
rivet reconcile compares per-chunk row counts between source and destination for the latest chunked run:
| Per-partition outcome | Meaning |
|---|---|
match | Counts equal |
mismatch | Both counts known and different |
unknown | Either count missing (e.g. chunk never completed) |
Scope and limits:
- Chunked mode only in v1.
time_windowandincrementalexports surface a clear “not supported” error. COUNT(*)based. No hash-based partition verification yet.- Verified boundary advances only on a fully clean report — zero mismatches and zero unknowns (ADR-0008 § PG5).
- Exit code gates on mismatch.
rivet reconcileexits non-zero when any partition is amismatch, sorivet reconcile && <next step>does not proceed on disagreeing data (mirrorsrivet validate).unknownpartitions (an incomplete chunk, or a non-integer keyset key with no source re-count) are surfaced as a warning but do not fail the command — “could not verify” is not “verified wrong”, and a keyset export is structurally all-unknown. The mismatch detail is always in the printed report regardless of exit code.
Reconcile reads from the same source and never writes files itself.
Parallel execution semantics
Rivet runs two distinct parallel engines — see ADR-0010 — Two Parallel Engines:
| Engine | Use case | Crash isolation |
|---|---|---|
| In-process scoped threads | Chunked export of a single table, split into N concurrent chunks | None — a panicking worker can fail the run |
Subprocess fan-out (--parallel-export-processes) | Many independent exports concurrently, one child per export | OS-level — a failing child exits non-zero; the parent aggregates and returns non-zero |
Both engines honour the same state invariants. Chunk checkpoints serialise the parallel threads’ state writes; subprocess children share one state DB — the parent migrates it once before spawning, and SQLite WAL (or the PostgreSQL state backend) handles the children’s concurrent writes.
Quality gates
When quality: is configured, the pipeline evaluates row-count, null-ratio, and uniqueness checks before advancing committed progression. A failing gate aborts the run with a non-zero exit code; the destination files remain (manual cleanup or replacement is the operator’s call). See docs/best-practices/quality-checks.md.
Destination commit boundaries
| Destination | Commit protocol | What “Ok” means |
|---|---|---|
| S3 / GCS / Azure | FinalizeOnClose | Object is committed only after writer close; a mid-upload failure leaves nothing visible |
| Local filesystem | Atomic | Ok means the full file is present; staged temp file + atomic rename, so a failure leaves nothing at the final path (retry_safe: true, partial_write_risk: false) |
| stdout | Streaming | No atomic commit boundary; partial output may be observable before write() returns |
Full per-backend table and rationale: ADR-0004 — Destination Write Contracts.
Known non-guarantees
Rivet does not currently guarantee:
- Exactly-once delivery to the destination. Crashes between destination write and cursor advancement can produce duplicate files. Plan downstream dedup or idempotent ingestion — the manifest’s per-part
content_fingerprintis the supported dedup key: identical rows produce byte-identical parts (and the same fingerprint) across rivet releases, so a duplicate is safely droppable by fingerprint. See recipes/idempotent-warehouse-load.md. - Continuous / near-real-time replication. Rivet does capture CDC to files (
mode: cdc— inserts/updates/deletes via a Postgres logical replication slot / MySQL binlog / SQL Server CDC change tables / MongoDB change streams, into typed Parquet/CSV — or the JSON-blob document image for MongoDB — resuming from the last committed log position each run), but it is not a continuously-running stream — changes are captured per invocation, not delivered live. For always-on near-real-time replication use Debezium or Estuary. - Completeness of incremental cursors that can tie. Incremental resume uses a strict
WHERE cursor > last_value. If two rows share the high-watermark value and the second becomes visible only after the run that advanced the watermark past it — e.g. a low-resolutionupdated_at(second granularity) or rows committed at the same timestamp after the read snapshot — the next run skips them and they are never exported. (Keyset pagination is unaffected: its key is planner-enforced unique + NOT NULL.) Use a strictly per-row-distinct, monotonic cursor (a sequence/identity id, or a timestamp with sub-value uniqueness); when the cursor can tie, re-snapshot the affected window withfull/chunkedmode. - Automatic cleanup of an interrupted write’s temp file. A crash mid-write on the local destination may leave a dot-prefixed temp file in the target directory — never a partial final file (the commit is an atomic
rename, so the final path is the complete file or absent). The stray temp file is harmless and can be removed manually. - Schema migration handling. If the source schema changes between runs, Rivet does not migrate the destination; it surfaces a schema-drift error (see tests/live/live_schema_drift.rs).
- Correctness of user-authored SQL. Rivet executes
query:verbatim. A query that omits aWHEREclause or selects from the wrong table will export the wrong data — there is no semantic validation. - Protection from poorly indexed source queries. Preflight (
rivet doctor,rivet check) warns about missing cursor indexes and unboundedORDER BY, but it does not refuse to run. The operator decides. - Stdout state safety. Using stdout with cursor or manifest state is technically allowed but not meaningful; plan validation rejects
stdout + chunkedandstdout + max_file_sizebefore execution (ADR-0004 Known Gap). - Atomicity across exports in one run. If a run has three exports and the second fails, the first export’s writes are already committed — the run does not roll back.
- Cross-run ordering when running in parallel from multiple machines against the same state DB. The default state DB is a local SQLite file; concurrent processes on one machine are handled via WAL, but multi-machine deployments should point
RIVET_STATE_URLat a shared PostgreSQL state backend — cross-run ordering across machines is still not guaranteed.
Test coverage
The invariants on this page are exercised by:
- tests/invariants.rs — ADR-0001 I1–I7 structural contracts.
- tests/journal_invariants.rs — RunJournal event ordering.
- tests/recovery.rs — chunk checkpoint resume semantics (I5, I6).
- tests/live/live_crash_recovery.rs — crash-and-resume against a live database.
- tests/live/live_chunked_recovery.rs — chunked resume after partial completion.
- tests/live/live_retry_and_faults.rs — retry classification under injected faults.
- tests/live/live_reconcile_repair.rs — reconcile / repair end-to-end.
Invariants and recovery suites run as named semantic gates in PR CI (.github/workflows/ci.yml). Branch protection blocks merges on regression. See reliability-matrix.md for the full coverage matrix.
Rivet type mapping contract
This document describes how Rivet maps source column types to logical
RivetType values and Arrow/Parquet/CSV
representations. It is aligned with the automated suite in
tests/type_roundtrip/ and
tests/live_type_golden.rs.
The short version
Wondering “will my decimals / UUIDs / JSON / timestamps silently break on the way out?” — the short answer is no:
- Decimals never become floats —
DECIMAL/NUMERICexport as exact ArrowDecimal128/Decimal256when precision and scale are known. - UUID and JSON keep native types — Parquet gets native
LogicalType::Uuid/LogicalType::Json, not opaque strings. - Timestamps preserve the instant — the point in time round-trips (Parquet
keeps the zone; CSV emits the instant normalised to UTC with a trailing
Z, while naive timestamps render bare). - Rivet fails loud, not silent — a lossy or unmapped type is named by
rivet checkand aborts the run, never quietly truncated.
The per-engine tables below are the precise contract; this is just the gist.
Guarantees (v0.18.0)
- DECIMAL / NUMERIC are never silently converted to float. They export as
Arrow
Decimal128/Decimal256in Parquet when precision and scale are known (column override, catalog hint, or PostgreSQL wire metadata). - Binary (
BYTEA,BLOB,BINARY/VARBINARYwith charset 63) stays ArrowBinaryin Parquet. - Float
NaN/±Infinityare preserved. Parquet stores them natively (IEEE-754); CSV emits the literalNaN/inf/-inf(and-0keeps its sign) rather than an empty cell — an empty cell would silently conflate a real special value withNULL. Note these are float values:decimal/NUMERIChas no NaN representation and a NaN/Infinity payload there is rejected at extract time, not coerced. Strict CSV loaders that expectInfinityoverinfshould configure their float parser accordingly; Parquet needs no such care. - JSON / JSONB is valid JSON text in the file, paired with the Arrow
arrow.jsoncanonical extension type so parquet-rs emits nativeLogicalType::Jsonin the Parquet footer. The Rivet field metadata (rivet.logical_type=json) stays for Rivet-aware consumers. - UUID exports as canonical 16-byte
FixedSizeBinary(16)paired with the Arrowarrow.uuidcanonical extension; parquet-rs emits nativeLogicalType::Uuid. Downstream Parquet readers (DuckDB, ClickHouse 25.x+, pyarrow, BigQuery autodetect) recover the UUID type without a cast. - Timestamps:
TIMESTAMPTZand MySQLTIMESTAMPuse UTC semantics (timezone: Some("UTC")); naiveTIMESTAMP/DATETIMEhave no timezone. - Nullability is preserved in Arrow schema and export.
What rivet init auto-detects (and what needs an override)
rivet init reads the source database’s catalog / wire-protocol metadata to
build the initial rivet.yaml. Whether a column lands as a native logical
type in the resulting Parquet depends on whether the source server
advertises the semantic — Rivet never guesses from column names or sample
values, by design (a wrong guess is silent corruption; an honest “I don’t
know” is a config knob).
| Semantic | PostgreSQL | MySQL | SQL Server | MongoDB |
|---|---|---|---|---|
JSON / JSONB | auto — Type::JSON (OID 114) and Type::JSONB (OID 3802) are native PG wire types. | auto — MYSQL_TYPE_JSON is native since MySQL 5.7. | manual override required — SQL Server stores JSON in nvarchar; the catalog reports only nvarchar. | always — the whole document exports as one document column (Utf8 + arrow.json), typed downstream by PARSE_JSON. |
UUID | auto — Type::UUID (OID 2950) is a native PG type. | manual override required. MySQL has no native UUID; they are stored in VARCHAR(36) or BINARY(16). The catalog reports only varchar/binary — semantic UUID information is gone before the driver ever sees the column. Operators add an explicit override (see below). | auto — uniqueidentifier is a native type; exports as FixedSizeBinary(16) + LogicalType::Uuid. | n/a — MongoDB does no per-field typing; _id is a stringified Utf8 key, values live inside the blob. |
DECIMAL(p,s) | auto when declared — PG’s catalog returns numeric_precision/numeric_scale for table-qualified queries; ad-hoc numeric expressions need an override. | auto — precision/scale derive from the wire column definition (display width + decimals), including ad-hoc queries; a columns: override is needed only in the rare case derivation fails (Rivet then reports the column Unsupported and names the override). | auto — precision/scale recovered from the data (tiberius drops the declared scale). | n/a — numbers stay inside the JSON document blob. |
Adding overrides looks like:
exports:
  - name: users
    query: "SELECT id, uid, amount FROM users"
    columns:
      uid: uuid              # MySQL VARCHAR(36) → UUID semantic
      amount: decimal(18,2)  # also valid for MySQL DECIMAL without catalog
      event_ts: timestamp_ns # keep SQL Server datetime2(7)'s 100 ns tick (see gap 4)
Supported override types: bool, int2/int4/int8, float4/float8,
decimal(p,s), date, timestamp, timestamp_ns, timestamp_tz,
timestamp_tz_ns, text, binary, json, uuid. The _ns timestamp
variants preserve sub-microsecond precision (range 1677–2262; see gap 4) — the
plain timestamp is microsecond with full date range.
The override path is safe: a uid: uuid declaration tries to parse each
cell — either 16 raw bytes (BINARY(16) layout) or a 36-char canonical text
form. Parse failures emit NULL, never silent garbage. Same convention
as decimal overrides whose values do not parse cleanly.
rivet init does not apply heuristics (“column is 36 chars wide and
named uid_* → probably UUID”) — guessing risks misclassifying a non-UUID
varchar and silently producing wrong-shape Parquet. Operators who want UUID
semantics on a MySQL column add the override explicitly.
Test commands
make test-types              # offline mapping contracts (PR-fast)
make test-types-live         # full matrix; requires docker compose
make test-types-validators   # PG/MySQL/SQL Server → Parquet → {DuckDB, ClickHouse} round-trip
test-types-validators re-runs the same canonical PG / MySQL / SQL Server type matrix used
by test-types-live, but writes the Parquet into the shared bind-mount under
tests/.live-tmp/ and feeds it through three independent readers: DuckDB,
ClickHouse (both from docker-compose.yaml), and pyarrow (installed alongside
duckdb in the same container). Each reader catches what the others cannot:
| Reader | What it pins |
|---|---|
| DuckDB | Autoload physical types (DECIMAL, TIMESTAMPTZ, INTEGER[], BLOB, …), decimal sums, JSON validity, UUID parseability, byte-exact BLOB, list lengths (including empty), null-bitmap propagation |
| ClickHouse | Independent confirmation of the above through a second decoder; native UInt64 round-trip for BIGINT UNSIGNED; tz-aware timestamps as DateTime64(6, 'UTC') |
| pyarrow | Arrow field metadata (rivet.* keys) reaches the Parquet footer; row-group statistics (min/max/null_count) are correct; Decimal256 (precision > 38) round-trips exactly where DuckDB downgrades to DOUBLE |
Local-reader type fidelity is now covered by the cross-tool harness’
type-loss matrix (dev/bench/smoke.py, rendered in
report.html): every source column vs each tool’s Parquet
type family. A BigQuery cloud-load type-diff (load each Rivet Parquet via
bq load --autodetect, assert decimal sums round-trip) is not currently in
the harness — it needs a GCP project + bq auth and is tracked for a future
cloud dimension (notably the earlier findings were:
LogicalType::Json does not autoload as native BQ JSON — it
falls back to BYTES/STRING; values are valid JSON but operators
need an explicit --schema='attrs:JSON,...' to query the structure).
In addition, two structural-only tests pin the Parquet layout itself —
parquet_schema.rs for
physical + logical types per column, and
parquet_metadata.rs for the
rivet.native_type / rivet.fidelity / rivet.logical_type field metadata.
Coverage extensions live in dedicated files:
compression_matrix.rs
re-runs the export under zstd / snappy / gzip / none and asserts
value parity across all four codecs;
csv_load.rs replays the matrix
through DuckDB read_csv_auto;
pg_edge_cases.rs covers
decimal precision boundaries (38, 39 / Decimal128↔Decimal256), tz timestamps
pre-epoch and far-future, JSON deep nesting + unicode keys + i64 edges,
arrays with NULL elements, large single-cell strings.
v0.7.8 breaking change: UUID export layout
UUID columns (PG native uuid type and MySQL columns explicitly overridden
as columns: { col: uuid }) now export as FixedSizeBinary(16) instead of
hyphenated Utf8. This is what lets parquet-rs emit native
LogicalType::Uuid so downstream readers (DuckDB, ClickHouse 25.x+,
pyarrow, BigQuery autodetect) recover the UUID type without a cast.
What this changes:
- Parquet schema:
BYTE_ARRAY + LogicalType::String→FIXED_LEN_BYTE_ARRAY + LogicalType::Uuid. - On-disk bytes: 36-char canonical ASCII (
a0eebc99-9c0b-…) → 16 raw bytes (the same UUID, compact encoding). - CSV: unchanged — the CSV writer still emits hyphenated lowercase text.
- DuckDB autoload:
VARCHAR→UUIDnative type. A view likeSELECT uid::VARCHAR FROM read_parquet(...)keeps working because DuckDB’sUUID::VARCHARcast yields the canonical form. - ClickHouse 24.8 autoload:
String→FixedString(16)(the bytes, not the text). To get back the canonical string, uselower(hex(uid))and reformat, or upgrade to ClickHouse 25.x which decodesLogicalType::Uuiddirectly.
Consumers reading the old Utf8-shaped Parquet files keep working — only files produced by Rivet ≥ v0.7.8 carry the new layout.
Findings & fixes from triangulating against external readers
Driving the matrix through DuckDB + ClickHouse + pyarrow exposed three real defects in the PG / MySQL drivers; all have been fixed in v0.7.8:
- PG arrays with NULL elements were silently lost. The driver decoded
ARRAY[1, NULL, 3]viatry_get::<Vec<i32>>, which errors on a NULL element; the error was swallowed and a whole-row NULL was written. Fixed by deserializing asVec<Option<T>>and pushing nulls throughListBuilder::append_null(src/source/postgres/arrow_convert.rs). - MySQL ENUM / SET were misclassified as
String. They arrive on the wire asMYSQL_TYPE_STRING/MYSQL_TYPE_VAR_STRINGwith theENUM_FLAG/SET_FLAGset, not asMYSQL_TYPE_ENUM. The mapper now checks the flag and emitsRivetType::Enumso therivet.logical_type=enumParquet metadata is preserved. - MySQL
native_typelost precision.tinyint unsigned,tinyint(1),bit(1),charvsvarchar,binaryvsvarbinaryall collapsed to a single label. The mapper now distinguishes them viacolumn_type()+flags()+character_set.
Known limitations (pinned by *currently_fails* tests)
- PG
numeric(p, -s)(negative scale) cannot be written to Parquet — the spec requires non-negative DECIMAL scale. Testpg_edge_decimal_negative_scale_currently_fails_at_parquet_writepins the failure with a friendly error message so any future workaround must update the test deliberately. - DuckDB’s
DECIMALis capped at precision 38 (HUGEINT-backed). For Parquet files withprecision > 38DuckDB silently returns DOUBLE. Our file still carriesLogicalType::Decimal(p, s)correctly — pyarrow decodes it asDecimal256. Verified inpg_edge_decimal_boundaries_round_trip.
PostgreSQL
| Source type | Rivet logical | Parquet (Arrow) | CSV | Notes | Tested |
|---|---|---|---|---|---|
smallint | int16 | Int16 | integer text | golden | |
integer | int32 | Int32 | integer text | golden | |
bigint | int64 | Int64 | integer text | golden | |
numeric(p,s) | decimal(p,s) | DECIMAL(p,s) | exact decimal text | override if unbounded in query | contract + live matrix |
real | float32 | Float32 | float text | golden | |
double precision | float64 | Float64 | float text | golden | |
date | date | Date32 | ISO date | golden | |
time | time(microsecond) | Time64(µs) | time text | partial | |
timestamp | timestamp(microsecond) | Timestamp(µs, None) | datetime text | naive wall clock | live matrix |
timestamptz | timestamp_tz(µs, UTC) | Timestamp(µs, UTC) | datetime text | live matrix | |
text / varchar | string | Utf8 | escaped UTF-8 | newlines/quotes escaped | live matrix |
bytea | binary | Binary | lowercase hex | live matrix | |
json / jsonb | json | Utf8 + Parquet LogicalType::Json (via arrow.json extension) | JSON string | live matrix | |
uuid | uuid | FixedSizeBinary(16) + Parquet LogicalType::Uuid (via arrow.uuid extension) | canonical UUID text | downstream readers autoload as native UUID type | golden |
boolean | bool | Boolean | true/false | type_roundtrip | |
numeric(10,2) | decimal(10,2) | DECIMAL(10,2) | exact decimal text | second precision tier | type_roundtrip |
char / bpchar | string | Utf8 | escaped UTF-8 | padded char | type_roundtrip |
interval | interval | Utf8 (ISO 8601) | duration text | not Parquet Interval type | type_roundtrip |
enum | enum | Utf8 + logical=enum | label text | custom PG enum | type_roundtrip |
text[] | list<string> | List<Utf8> | — | 1-D arrays | type_roundtrip |
integer[] | list<int32> | List<Int32> | — | 1-D arrays | type_roundtrip |
| nullable / all-null | — | null bitmap preserved | empty cells | note_nullable, note_all_null | type_roundtrip |
large text | string | Utf8 | escaped | 2k–5k chars | type_roundtrip |
MySQL
| Source type | Rivet logical | Parquet (Arrow) | CSV | Notes | Tested |
|---|---|---|---|---|---|
tinyint (not width 1) | int16 | Int16 | integer text | widened signed | golden |
tinyint(1) | bool | Boolean | 0/1 | MySQL boolean convention | golden |
smallint | int16 | Int16 | integer text | golden | |
int | int32 | Int32 | integer text | golden | |
bigint | int64 | Int64 | integer text | signed | golden |
bigint unsigned | u_int64 → UInt64 | UInt64 | integer text | values > i64::MAX | type_roundtrip |
decimal(p,s) | decimal(p,s) | DECIMAL(p,s) | exact decimal text | p/s auto-resolved from the wire column definition (override only as fallback) | live matrix |
float / double | float32 / float64 | Float32 / Float64 | float text | golden | |
date | date | Date32 | ISO date | golden | |
datetime | timestamp(µs, none) | Timestamp(µs, None) | datetime text | naive | live matrix |
timestamp | timestamp_tz(µs, UTC) | Timestamp(µs, UTC) | datetime text | SET time_zone = '+00:00' | live matrix |
time | time(µs) | Time64(µs) | time text | partial | |
varchar / text | string / text | Utf8 | escaped UTF-8 | live matrix | |
json | json | Utf8 + Parquet LogicalType::Json (via arrow.json extension) | JSON string | live matrix | |
binary / varbinary / blob | binary | Binary | hex in CSV | charset 63 / binary payload | type_roundtrip |
bit(1) | bool | Boolean | golden | ||
bit(n>1) | int64 | Int64 | avoids silent truncation | type_roundtrip | |
tinyint unsigned | int16 | Int16 | integer text | 0–255 | type_roundtrip |
smallint unsigned | int32 | Int32 | integer text | up to 65535 | type_roundtrip |
int unsigned | int64 | Int64 | integer text | up to 4294967295 | type_roundtrip |
decimal(10,2) | decimal(10,2) | DECIMAL(10,2) | exact decimal text | p/s auto-resolved from the wire column definition (override only as fallback) | type_roundtrip |
char | string | Utf8 | escaped | fixed CHAR(n) | type_roundtrip |
mediumtext / longtext | text | Utf8 | escaped | large payloads | type_roundtrip |
enum / set | enum | Utf8 + logical=enum | label text | SET comma-separated | type_roundtrip |
year | int16 | Int16 | integer text | calendar year | type_roundtrip |
boolean (native) | bool | Boolean | true/false | not only TINYINT(1) | type_roundtrip |
| nullable / all-null | — | preserved | empty cells | edge columns | type_roundtrip |
SQL Server (MSSQL)
| Source type | Rivet logical | Parquet (Arrow) | CSV | Notes | Tested |
|---|---|---|---|---|---|
tinyint (0–255) | int16 | Int16 | integer text | widened (unsigned source) | live matrix |
smallint | int16 | Int16 | integer text | live matrix | |
int | int32 | Int32 | integer text | live matrix | |
bigint | int64 | Int64 | integer text | live matrix | |
bit | bool | Boolean | 0/1 | live matrix | |
decimal(p,s) / numeric(p,s) | decimal(p,s) | DECIMAL(p,s) | exact decimal text | scale recovered from the data (tiberius drops declared scale) | live matrix |
money | decimal(19,4) | DECIMAL(19,4) | exact decimal text | fixed scale | live matrix |
smallmoney | decimal(10,4) | DECIMAL(10,4) | exact decimal text | fixed scale | type_roundtrip |
real | float32 | Float32 | float text | live matrix | |
float | float64 | Float64 | float text | live matrix | |
date | date | Date32 | ISO date | live matrix | |
time | time(µs) | Time64(µs) | time text | µs precision | live matrix |
datetime2 / datetime / smalldatetime | timestamp(µs, none) | Timestamp(µs, None) | datetime text | naive; µs default (full range), datetime2(7)’s 100 ns tick truncated — opt into timestamp_ns to keep it, see known gap 4 | live matrix |
datetimeoffset | timestamp_tz(µs, UTC) | Timestamp(µs, UTC) | datetime text | normalised to UTC | type_roundtrip |
nvarchar / varchar / nchar / char / text / ntext | string | Utf8 | escaped UTF-8 | live matrix | |
varbinary / binary / image | binary | Binary | hex in CSV | live matrix | |
uniqueidentifier | uuid | FixedSizeBinary(16) + Parquet LogicalType::Uuid | canonical UUID text | native UUID downstream | live matrix |
| nullable / all-null | — | preserved | empty cells | live matrix |
Unmapped SQL Server types resolve to Unsupported and fail loudly at schema
build unless a columns: override maps them.
MongoDB (JSON-blob model)
MongoDB has no fixed per-collection schema and no information_schema, so Rivet
does not map per-field SQL types the way the three SQL engines do. Every document
exports as exactly two columns:
| Source | Rivet logical | Parquet (Arrow) | CSV | Notes | Tested |
|---|---|---|---|---|---|
document key (_id) | string | Utf8 | stringified key | ObjectId → hex, int → decimal string, … | live |
| whole document | json | Utf8 + Parquet LogicalType::Json (via arrow.json extension) | JSON string | full BSON as extended JSON — relaxed by default, canonical opt-in (source.mongo.json) | live |
Per-field typing is deferred to the warehouse (PARSE_JSON → VARIANT on
Snowflake, native JSON on BigQuery / DuckDB). This is lossless and
schema-drift-proof: a new field in a document never breaks a load. Schema
inference / auto-discovery into typed columns is deliberately out of OSS scope.
CDC (change streams) emits the same two-column shape prefixed with the
__op / __pos / __seq meta columns. See
reference/mongodb.md for the full contract.
Known gaps (tracked)
-
Nested arrays, ranges, inet, PostGIS, geometry: not in the type matrix — they resolve to
Unsupportedand fail at schema build unless acolumns:override maps them. -
Nullability: every exported column is
OPTIONAL; a sourceNOT NULLconstraint is not propagated into the Parquet schema (ADR-0016, deferred to v0.8 Phase A). -
CSV complex types: arrays (
List),Decimal256(precision > 38), and non-UUID fixed binary have no CSV cell — the export fails loudly naming the column (see CSV serialization) rather than silently writing empty values. -
SQL Server
datetime2sub-microsecond precision — default is microsecond; nanosecond is opt-in. rivet mapsdatetime2toTimestamp(µs)by default, because Arrow nanosecond timestamps are i64 ns and span only 1677-09-21 .. 2262-04-11, whiledatetime2spans 0001–9999 — a blanket ns mapping would silently corrupt any value outside that window (a far worse bug than the precision gap). So the 7th fractional digit of adatetime2(7)(100 ns) is truncated to µs by default; lossless fordatetime2(6)and below.To preserve the 100 ns tick on a column whose data is inside the ns range, opt in per column with a
timestamp_nsoverride:columns: event_ts: timestamp_ns # naive; use timestamp_tz_ns for datetimeoffsetThe Parquet file then carries
Timestamp(ns)and the full precision survives (verified live 2026-06-07: DuckDB reads it natively asTIMESTAMP_NS,…12:00:00.1234567intact; the default µs path truncates to.123456). Caveats (all verified live 2026-06-07):- A value outside 1677–2262 exports as NULL (Arrow ns range).
- DuckDB — native
TIMESTAMP_NS, fully lossless. - Snowflake — autoloads as
NUMBER(38,0)(raw nanos);TO_TIMESTAMP_NTZ(col, 9)recovers a losslessTIMESTAMP_NTZ(it holds 9 digits — the 7th survives). - BigQuery — autoloads as
INT64(raw nanos, lossless as an integer); a nativeTIMESTAMP_MICROS(DIV(col,1000))is lossy (BigQueryTIMESTAMPis microsecond — the 7th digit drops). Keep the defaulttimestampfor BigQuery unless you carry the raw nanos.
Incremental mode: the default µs cursor on a
datetime2(7)lands one tick below the source max, re-exporting the boundary row every run — usetimestamp_ns(the cursor literal then carries all 9 digits), adatetime2(6)(or coarser) cursor, or an integer/identity cursor.
(MySQL DECIMAL now resolves its precision/scale from the wire column
definition — no override needed; see the MySQL section.)
Fidelity labels
| Label | Meaning |
|---|---|
exact | Value and type semantics preserved |
compatible | Value preserved; physical type differs (e.g. UUID as Utf8) |
logical_string | Valid text; native JSON tree semantics not enforced in Arrow |
lossy | Rejected in strict mode |
unsupported | Requires policy override |
CSV serialization
CSV shares the same Arrow RecordBatch as Parquet, so values are identical —
only the text rendering differs (src/format/csv.rs):
| RivetType | CSV rendering |
|---|---|
ints / float / bool / decimal | plain text (decimal exact, never via float) |
string / text / json / enum / interval | text, RFC-4180 quoted/escaped when needed |
uuid | canonical hyphenated lowercase (a0eebc99-…) |
binary (bytea / BLOB) | lowercase hex (deadbeef) |
date / time / timestamp | ISO 8601 (2026-01-01T12:00:00.000000) |
timestamp_tz | ISO 8601 normalised to UTC with a trailing Z (2026-01-01T12:00:00.000000Z) — distinguishable from a naive timestamp, which renders bare |
CSV has no cell representation for list (arrays), Decimal256
(precision > 38), or non-UUID fixed binary. Rather than silently write an empty
value, the export fails at writer creation naming the column — use
format: parquet or drop the column from the query.
Loading CSV into a warehouse: unlike Parquet (whose loader will not coerce a
declared type — see below), BigQuery’s CSV loader honors a declared --schema.
Bare --autodetect infers decimal text as FLOAT (precision-lossy) and every
semantic type (uuid / json / bytea) as STRING; declare NUMERIC / JSON
in the load schema, or recover post-load with PARSE_JSON / FROM_HEX as for
Parquet.
Downstream targets (autoload vs native)
Parquet/CSV preserve values and Arrow physical types. Warehouse engines infer types from
physical schema on autoload (e.g. JSON columns appear as STRING / VARCHAR). Native
target types (JSON, VARIANT, UUID, …) require a materialization step (cast SQL,
load schema, or typed view).
See ADR-0014: Target type materialization for
the full matrix (DuckDB, BigQuery, Snowflake, ClickHouse) and planned
rivet check --type-report --target <engine> extensions.
Verified physical autoload (DuckDB + ClickHouse, v0.18.0)
make test-types-validators re-reads every PG / MySQL matrix column through
two independent engines and pins the autoload type. The full matrix:
| RivetType (PG / MySQL source) | DuckDB DESCRIBE | ClickHouse DESCRIBE TABLE file() |
|---|---|---|
int16 / smallint | SMALLINT | Nullable(Int16) |
int32 / integer | INTEGER | Nullable(Int32) |
int64 / bigint | BIGINT | Nullable(Int64) |
u_int64 (MySQL BIGINT UNSIGNED) | UBIGINT | Nullable(UInt64) |
decimal(p,s) | DECIMAL(p,s) | Nullable(Decimal(p, s)) |
float32 / real | FLOAT | Nullable(Float32) |
float64 / double precision | DOUBLE | Nullable(Float64) |
date | DATE | Nullable(Date32) |
time(µs) | TIME | Nullable(DateTime64(6)) |
timestamp(µs) (naive) | TIMESTAMP | Nullable(DateTime64(6)) |
timestamp_tz(µs, UTC) | TIMESTAMP WITH TIME ZONE | Nullable(DateTime64(6, 'UTC')) |
string / text / enum / interval | VARCHAR | Nullable(String) |
json (PG JSON/JSONB, MySQL JSON) | JSON | Nullable(String) (ClickHouse 24.8) — DuckDB autoloads as native JSON |
uuid (PG native; MySQL via override) | UUID | Nullable(FixedString(16)) (ClickHouse 24.8) — DuckDB autoloads as native UUID |
binary (bytea / BLOB) | BLOB | Nullable(String) (raw bytes) |
bool | BOOLEAN | Nullable(Bool) |
list<inner> | inner[] | Array(Nullable(inner)) |
Round-trip values that the suite pins per row: sum(decimal * 10^scale)
matches the in-process Arrow check; json_valid / isValidJSON returns true
for every row; TRY_CAST(uid AS UUID) / toUUID(uid) parses every row; BLOB
columns compare byte-for-byte (hex(...)); the empty list survives; null
bitmaps propagate. The MySQL BIGINT UNSIGNED max value (2^64 − 1) is the
load-bearing assertion that exact-width unsigned ints are not silently
overflowed to i64.
BigQuery autoload & recovery (verified live)
BigQuery’s Parquet loader is weaker than DuckDB’s: it ignores several Parquet
logical types on autoload and — critically — will not coerce a column to a
different declared type on load. A bq load into a table that declares
JSON/DATETIME is rejected (Field x has changed type from JSON to BYTES),
so native types are recovered with a post-load transform, not a load schema.
| RivetType | BigQuery autoload | Native | Recovery (post-load) |
|---|---|---|---|
json | BYTES | JSON | PARSE_JSON(SAFE_CONVERT_BYTES_TO_STRING(col)) |
uuid | BYTES (16 raw) | BYTES (BigQuery has no UUID type; rivet load keeps the bytes) | none — render text in a view: TO_HEX(col) |
timestamp (naive) | TIMESTAMP (instant) | DATETIME | DATETIME(col) |
list<inner> | RECORD{item} | REPEATED inner | load staging with --parquet_enable_list_inference, then ARRAY(SELECT el.item FROM UNNEST(col) AS el) |
u_int64 | INT64 (overflows > 2^63−1) | NUMERIC | none post-load — fix at source: columns: { c: decimal(20,0) } |
timestamp_tz, decimal, string, binary, bool, ints | native | same | — |
Rivet writes the Parquet list element as item (arrow-rs default, not the
spec’s element), so even --parquet_enable_list_inference yields
REPEATED RECORD{item} rather than a clean REPEATED <scalar> — the UNNEST
flatten above is required.
rivet check --type-report --target bigquery prints the per-column autoload
type, the native type, and a ready-to-run recovery CREATE TABLE … AS SELECT
over the autoloaded <table>__staging. Set exports[].target: bigquery to get
it without the CLI flag. DuckDB needs none of this — it autoloads every logical
type natively.
Snowflake autoload & recovery (verified live)
Snowflake’s INFER_SCHEMA + COPY infers physical types only, so the same
semantic types degrade — and the INFER_SCHEMA column names come back
lowercase and case-sensitive, so the recovery SELECT must double-quote
every source reference ("col").
| RivetType | Snowflake autoload | Native | Recovery (post-load) |
|---|---|---|---|
json | TEXT | VARIANT | PARSE_JSON("col") |
uuid | BINARY (16 raw) | TEXT | REGEXP_REPLACE(LOWER(HEX_ENCODE("col")), …) → canonical UUID |
timestamp (naive) | NUMBER (µs) | TIMESTAMP_NTZ | TO_TIMESTAMP_NTZ("col", 6) |
time | NUMBER (µs of day) | TIME | TIME_FROM_PARTS(0,0,FLOOR("col"/1000000),MOD("col",1000000)*1000) |
binary | BINARY (needs BINARY_AS_TEXT=FALSE) | BINARY | — (set the file-format option) |
timestamp_tz | TIMESTAMP_TZ (pin session TIMEZONE='UTC') | TIMESTAMP_TZ | — (autoload uses session offset otherwise) |
u_int64 | NUMBER (overflows > 2^63−1) | NUMBER(20,0) | none post-load — fix at source: columns: { c: decimal(20,0) } |
list<inner> | VARIANT (the JSON array) | ARRAY | "col"::ARRAY |
decimal, string, bool, date, ints | native | same | — |
The load preamble the recovery depends on: CREATE FILE FORMAT … TYPE=PARQUET BINARY_AS_TEXT=FALSE, ALTER SESSION SET TIMEZONE='UTC', CREATE TABLE … USING TEMPLATE (… INFER_SCHEMA …), COPY … MATCH_BY_COLUMN_NAME=CASE_INSENSITIVE.
rivet check --type-report --target snowflake (--target sf) emits the
per-column autoload/native types and the post-load CREATE OR REPLACE TABLE …
recovery over <table>__staging. Set exports[].target: snowflake to skip the
flag.
Value-Based Output Partitioning (partition_by)
When to use
Set partition_by to split one export’s rows into one destination sub-folder
per value bucket of a column — the Hive-style col=value/ layout that
warehouses and query engines (Snowflake external tables, BigQuery external /
Hive-partitioned tables, Spark, DuckDB, Athena) discover automatically. Best for:
- Daily/monthly snapshots that land each day’s rows under its own prefix
- Backfilling history into a partitioned lake layout in one command
- Feeding a warehouse that prunes partitions by a date column
partition_by is orthogonal to mode: each partition runs the export’s own
mode, so mode: chunked chunks within a partition.
Required fields
partition_by— the column whose value buckets the rows (aDATE/TIMESTAMP/TIMESTAMPTZcolumn).- a
{partition}token indestination.pathordestination.prefix— Rivet refuses the run without it, because every partition would otherwise overwrite the same prefix.
Optional fields
partition_granularity—day(default),month, oryear.
Minimal config
source:
  type: postgres
  url: "postgresql://user:pass@host:5432/dbname"

exports:
  - name: events
    table: events
    partition_by: created_at
    partition_granularity: day
    format: parquet
    destination:
      type: s3
      bucket: my-bucket
      prefix: "events/{partition}/"      # → events/created_at=2023-01-01/
Run it
rivet run --config events.yaml --validate
What happens
- Rivet reads the
[min, max]span ofpartition_byfrom the source (SELECT min(col),SELECT max(col)over your query). - It generates one contiguous bucket per day/month/year across that span.
- Each bucket becomes its own export: the query is wrapped as
SELECT * FROM (<your query>) WHERE col >= '<lo>' AND col < '<hi>'(half-open:loinclusive,hiexclusive — no row counted twice), and{partition}resolves tocol=value. - Rows whose
partition_byvalue is NULL land incol=__HIVE_DEFAULT_PARTITION__/(the Hive default-partition convention) so no row is ever silently dropped.
Each partition is an independent, complete output prefix — its own
manifest.json and _SUCCESS — so it can be validated and consumed on its own.
Example output layout
events/
  created_at=2023-01-01/  manifest.json  _SUCCESS  events__2023-01-01_*.parquet
  created_at=2023-01-02/  manifest.json  _SUCCESS  events__2023-01-02_*.parquet
  ...
  created_at=__HIVE_DEFAULT_PARTITION__/  manifest.json  _SUCCESS  ...
DuckDB reads the whole tree as one partitioned dataset and recovers the partition column from the path:
SELECT created_at, count(*)
FROM read_parquet('events/**/*.parquet', hive_partitioning = true)
GROUP BY 1;
Granularity
partition_granularity | Path segment | Bucket bounds |
|---|---|---|
day (default) | col=2023-01-01 | [day, day+1) |
month | col=2023-01 | [month-start, next-month-start) |
year | col=2023 | [year-start, next-year-start) |
Notes and limits
- Cloud prefixes: put a
/after{partition}. Object stores have no directories — the part filename is appended to the resolved prefix verbatim.prefix: "events/{partition}/"yieldsevents/created_at=2023-01-01/part.parquet; omitting the trailing slash concatenates into…created_at=2023-01-01part.parquet. (Localpath:joins as directories, so the slash is optional there.) - Index the partition column. Expansion runs three probes over the base
query (
min,max, NULL-count). Without an index onpartition_bythose are up to three full scans before the first row is exported. - Time zones. Bucket bounds are emitted as
YYYY-MM-DDliterals on PostgreSQL and MySQL; SQL Server gets the unseparatedYYYYMMDDform, which T-SQL parses as ISO regardless of the session’sDATEFORMAT/language. For aTIMESTAMPTZcolumn the comparison happens at the session time zone — pin it (e.g. MySQLSET time_zone = '+00:00') when the exact day boundary matters. - Not compatible with
mode: time_window(time_window already filters by a rolling window). Usepartition_bywithfull,chunked, orincremental. - Not compatible with
mode: cdc(CDC reads the log, not a query), aload:block (per-export or top-level: the loader would load a single partition’s manifest), or a MongoDB source (the bucket probes are SQL). - Not compatible with
chunk_by_key(keyset). Each partition reads its bucket as a subquery around the table, and keyset seek pagination over that shape is not supported — Rivet rejects the combination up front. Atable:export keeps its table per partition, so a rangechunk_columnis type-checked and an unset one auto-resolves to the primary key as usual. --parallel-export-processesis disabled while partitioning is active (child processes re-load the config and can’t see the synthesised partitions); the run executes in-process.plan/checkdo not expand partitions yet. They report the parent export as one un-partitioned job (its{partition}token stays literal in the shown path, the row estimate is the whole span, strategy is the base mode). Treat their output as the per-partition shape, not the campaign.- Validating a single partition today: point
validateat the concrete prefix —rivet validate --config c.yaml --export events --prefix events/created_at=2023-01-01. Validating every partition of an export by its parent name in one command is not yet wired.
Choosing a chunking strategy per partition (large partitions)
partition_by is orthogonal to mode, so each partition runs the export’s mode
inside itself. The right choice depends on how big a single partition is and
whether the chunk key is dense within it. Consider a date that holds 100 M
rows:
| Setup | Source load | Use when |
|---|---|---|
mode: chunked, range chunk_column, key dense/correlated within the partition (e.g. the day ≈ the whole table) | One logical pass: ceil(key_span / chunk_size) indexed range scans, bounded memory. Good. | The common big-partition case. Keep chunk_size ≈ 100 k+. |
mode: chunked, range chunk_column, key sparse within the partition (rows interleaved with other days across the key range) | Chunk windows are computed over the partition’s [min,max] of the key, not its row count → many windows read key-range rows then discard out-of-partition ones. Query + I/O amplification. | Avoid — pick a key correlated with the partition, or a finer partition_granularity so each partition’s key range tightens. |
mode: full (no chunking) | One streaming SELECT. Postgres: server-side cursor, bounded memory, but a single long-running transaction (watch vacuum / replication lag). MySQL: one streaming SELECT over the wire (exec_iter); rivet accumulates only one adaptive batch at a time, so memory stays bounded — the cost is the query staying visible (Sending data) for the whole drain. SQL Server: streams one batch at a time server-side, bounded memory (like Postgres). MongoDB (full/cdc only): native cursor, keyset-paged on _id, bounded memory. | PG / SQL Server partitions that fit a long read. MySQL is memory-safe too, but the single query stays visible for the whole drain — prefer chunked there so each query is short. |
Row counts are always exact regardless of the choice — these trade-offs are about
source load and file fan-out, not correctness. There is no keyset/seek option
for a partition today (see the chunk_by_key limit above), so for a genuinely
huge partition with a sparse key the practical levers are a correlated range key
or a finer granularity.
Export modes — which one do I pick?
Every export declares a mode:. Start from the decision shortcut, then open the
guide for the mode you land on.
Decision shortcut
- Small-to-medium table, want a fresh snapshot every run →
full - Append-only or has an
updated_at, want only new/changed rows →incremental - Millions+ of rows, want speed and crash-resume →
chunked - Only the last N days matter (event/log table) →
time_window - Continuous low-latency replication from the WAL / binlog / oplog →
cdc
When in doubt, rivet init inspects the table and picks a sensible default for
you (small → full, large with an integer key → chunked).
At a glance
| Mode | Use when | Keeps state? | Parallel? | First run |
|---|---|---|---|---|
| full | complete snapshot each run | no (stateless) | no | exports everything |
| incremental | only rows past the saved cursor | yes (cursor) | no | exports everything, then deltas |
| chunked | tables too large for one full scan | yes (checkpoint, --resume) | yes | full, split into ranges |
| time_window | rolling N-day window | no (recomputed each run) | no | the window only |
| cdc | continuous log-based change capture | yes (resume checkpoint) | yes (multiplexed streams) | optional initial snapshot, then stream |
Notes worth knowing before you run:
incrementalfirst run = full export. With no cursor yet, every matching row is exported, so the first run behaves likefull— sizebatch_sizeaccordingly (incremental.md).chunkedclean re-runs are NOT idempotent. A crash +--resumeis at-least-once: a re-run chunk can be written twice (byte-identical), so de-duplicate downstream if you re-run (chunked.md).- Composite cursors are an
incrementalvariant, not a separate mode — see incremental-coalesce.md when one timestamp column isn’t enough. - Source engine matters. The SQL sources (PostgreSQL, MySQL, SQL Server)
support every mode. MongoDB, a document store, supports only
full(with keyset / parallel / resume paging on_id) andcdc— see ../reference/mongodb.md.
Full configuration reference: ../reference/.
Full Export Mode
When to use
Use mode: full when you want a complete snapshot of the query result set every time. Each run re-exports all rows from scratch. Best for:
- Small-to-medium tables (up to a few million rows)
- Reference/dimension tables that need a fresh copy each day
- One-time data migrations
MongoDB.
fullis MongoDB’s primary batch mode — the SQL-runner modes (incremental/chunked/time_window) do not apply to a document store. Withinfull, MongoDB adds keyset (seek) paging,parallel: N_id-range fan-out, and resume — all keyed on_id(source.mongo.page_size/parallel). See ../reference/mongodb.md.
Minimal config
source:
  type: postgres                                    # postgres, mysql, mssql, or mongo
  url: "postgresql://user:pass@host:5432/dbname"

exports:
  - name: users_daily                               # unique export name
    query: "SELECT id, name, email, created_at FROM users"
    mode: full                                      # re-export everything each run
    format: parquet                                 # parquet or csv
    destination:
      type: local
      path: ./output                                # directory for output files
Output file: ./output/users_daily_20260406_120000_123.parquet (the timestamp ends with a 3-digit millisecond field, e.g. _123, so rapid re-runs never collide)
Run it
# 1. Verify config and connectivity
rivet check --config users.yaml
rivet doctor --config users.yaml

# 2. Run with validation
rivet run --config users.yaml --validate --reconcile

# 3. Check results
rivet metrics --config users.yaml --last 5
What happens
- Rivet connects to the source database
- Executes
SELECT id, name, email, created_at FROM users - Fetches rows in batches controlled by
tuning.batch_size(default 10,000 withbalancedprofile) - Writes a timestamped output file
- Records metrics in the state database
No cursor is stored. Each run produces a new file with all rows.
batch_size directly controls memory usage and source load. For wide tables (many columns, TEXT/JSONB fields), reduce it to 1,000-5,000. See reference/tuning.md.
Common options
exports:
  - name: users_daily
    query: "SELECT * FROM users"
    mode: full
    format: parquet
    compression: zstd           # zstd (default), snappy, gzip, lz4, none
    skip_empty: true            # a 0-row run reports `skipped`, not `success`
    max_file_size: "512MB"      # split into multiple files if output exceeds this
    meta_columns:
      exported_at: true         # add _rivet_exported_at column
    destination:
      type: local
      path: ./output
    tuning:
      profile: safe             # safe/balanced/fast — controls batch size, timeouts
Troubleshooting
Export is slow on a large table – Switch to mode: chunked with parallel: 4 for tables over 1M rows. See chunked.md.
Output file is too large – Add max_file_size: "256MB" to split into parts.
A run that read 0 rows reports success – Add skip_empty: true to record it as skipped. No file is written for 0 rows either way, and a skipped run leaves the prefix describing the last run that delivered — so a later full rivet load keeps the previous data rather than emptying the table.
Incremental Export Mode
When to use
Use mode: incremental when you only want to export rows that are new or updated since the last run. Best for:
- Append-only tables (events, logs, audit trails)
- Tables with a reliable
updated_attimestamp - Tables with a monotonically increasing ID
- Daily/hourly syncs where re-exporting everything is wasteful
SQL sources only (PostgreSQL, MySQL, SQL Server).
incrementaldoes not apply to MongoDB, a document store — usefullorcdcthere (../reference/mongodb.md).
Required fields
cursor_column– the column used to track progress (must be monotonically increasing)
Minimal config
source:
  type: postgres
  url: "postgresql://user:pass@host:5432/dbname"

exports:
  - name: orders_incremental
    query: "SELECT id, user_id, product, price, status, updated_at FROM orders"
    mode: incremental
    cursor_column: updated_at       # tracks last exported value
    format: parquet
    destination:
      type: local
      path: ./output
Run it
# First run — exports all rows (no cursor yet)
rivet run --config orders.yaml --validate --reconcile

# Second run — only exports rows with updated_at > last cursor
rivet run --config orders.yaml --validate

# Check current cursor position
rivet state show --config orders.yaml

# Reset cursor to re-export everything
rivet state reset --config orders.yaml --export orders_incremental
What happens
- First run: no cursor exists, so all rows matching the query are exported
- Rivet records the maximum value of
cursor_columnas the cursor - Subsequent runs: Rivet wraps your query in a subquery, adds
WHERE updated_at > <last cursor>, and orders by the cursor column (the cursor is an inlined literal on Postgres/SQL Server — Postgres uses the escapedE'…'form — and a bind parameter on MySQL) - Only new/updated rows are exported; cursor advances after successful write
Run 1 (no cursor):  SELECT * FROM (SELECT ... FROM orders) AS _rivet ORDER BY "updated_at"
                     → 5000 rows, cursor saved: 2026-04-05 23:59:59
                     (the sort applies even to the full first run — an index
                      on the cursor column matters)

Run 2 (with cursor): SELECT * FROM (SELECT ... FROM orders) AS _rivet
                       WHERE "updated_at" > E'2026-04-05 23:59:59' ORDER BY "updated_at"
                      → 47 rows (only changes since last run)
Cursor column tips
| Column type | Example | Notes |
|---|---|---|
TIMESTAMP / DATETIME | updated_at | Most common; ensure it updates on every change |
BIGINT / SERIAL | id | Works for append-only tables |
TIMESTAMPTZ | created_at | Good for event streams |
The cursor column must be:
- Present in the SELECT clause
- Monotonically increasing (new rows always have a larger value)
- Not NULL for rows you want exported
Batch size and tuning
Even in incremental mode, Rivet fetches rows in batches (not all at once). The batch_size from tuning: controls how many rows are fetched per FETCH call:
source:
  type: postgres
  url_env: DATABASE_URL
  tuning:
    batch_size: 5000            # rows per fetch (default: 10,000 for balanced)

exports:
  - name: orders_incremental
    query: "SELECT id, user_id, product, price, updated_at FROM orders"
    mode: incremental
    cursor_column: updated_at
    format: parquet
    destination:
      type: local
      path: ./output
    tuning:
      batch_size: 2000          # per-export override (takes precedence)
On the first incremental run (no cursor yet), all rows are exported. If the table has millions of rows, this first run behaves like a full export — so batch_size directly impacts memory and source load. Use a smaller batch_size (1,000-5,000) for wide tables or production databases.
See reference/tuning.md for all tuning parameters.
Common options
exports:
  - name: orders_incremental
    query: "SELECT id, user_id, product, price, updated_at FROM orders"
    mode: incremental
    cursor_column: updated_at
    format: parquet
    skip_empty: true            # a run with no new rows reports `skipped`
    meta_columns:
      exported_at: true         # add _rivet_exported_at for dedup downstream
    destination:
      type: local
      path: ./output
Switching to incremental
The usual path is a full load first, then mode: incremental on the same export. What the first incremental run does depends on the export’s previous mode (ADR-0033, matrix):
| Previous mode | New cursor | First incremental run |
|---|---|---|
full, time_window, range chunked | any | full pass — no cursor was stored |
keyset (chunk_by_key), any variant | the same key | continues after the last exported key |
keyset or incremental | a different column, or a changed incremental_cursor_mode | refused until rivet state reset -c <config> --export <name> |
incremental | the same column with settle added | continues |
rivet load follows what each run holds. A run that re-read the whole table — a full load, or an incremental export’s first run — lands as a plain <table>. The first delta renames that table to <table>__changes, adds __op / __pos / __seq (NULL on the rows it already held) and makes <table> a view over it; the log keeps the table’s partitioning and clustering, and nothing is copied or dropped. A whole-table load onto a table rivet did not load, one whose partitioning or clustering differs from the config, or a view left by an earlier incremental load fails naming the difference and changes nothing — drop or rename the table, or align the config. The rename refuses the same way when the table’s columns differ from the export’s or a <table>__changes already exists beside it.
Settle window
Some rows keep changing for a while after they are inserted, and no column records when: a page view’s time-on-page arrives with the next hit, a session’s totals grow until it closes. A cursor exports such a row as soon as it appears, before its final values exist, and never sees the later write.
settle holds each row back until it is older than after by the source clock:
exports:
  - name: page_views
    table: page_views
    mode: incremental
    cursor_column: id              # a cheap primary-key range per run
    settle:
      column: server_time          # the row's insert time
      after: 1h                    # longer than the time the row keeps changing
aftertakess,m,hord. The warehouse copy lags the source by that much.- Without
column, the cursor itself is aged (cursor_column, or theCOALESCEin coalesce mode) — the right choice for anupdated_atcursor. - With a separate
column, the cursor also stops below the first row that is still settling, so a row committed out of id order is never skipped. - A row whose settle value is
NULLnever ages, so it is exported without waiting. - The column must be a date or timestamp; zone-less values are compared as UTC.
- Deletes stay invisible to a cursor. Use
mode: cdcwhen they must reach the warehouse.
Transactions that commit during a run
Each incremental read must see a transaction either whole or not at all. PostgreSQL and MySQL (InnoDB) read every statement from one snapshot, so they do. SQL Server does only when the database has a row-versioning option on:
| database option | how rivet reads the window |
|---|---|
READ_COMMITTED_SNAPSHOT ON | plain READ COMMITTED, which already reads one snapshot |
ALLOW_SNAPSHOT_ISOLATION ON | rivet switches the read to SNAPSHOT |
| neither (the SQL Server default) | locking READ COMMITTED, with a warning |
Under locking READ COMMITTED a scan can pass a row, wait on a row a writer holds, and read it once the writer commits, so the scan returns that transaction half-applied. The cursor then moves past the rows it had already passed, and no later run reads them. Enable ALLOW_SNAPSHOT_ISOLATION (ALTER DATABASE [<db>] SET ALLOW_SNAPSHOT_ISOLATION ON), or set a settle window longer than your longest write transaction.
A snapshot does not cover everything. A transaction that stamps its rows, commits late, and ends up with a cursor value below a row that committed earlier is skipped on every engine, since each read already moved past it. settle guards that race: set after longer than your longest write transaction.
Troubleshooting
the stored cursor ... was written for ... – The export’s cursor changed (a new cursor_column, or a keyset chunk_by_key export switched to incremental on another column). The old value means nothing for the new column; rivet state reset --config ... --export <name> starts the new cursor with a full pass.
A run with no new rows reports success – Add skip_empty: true to record it as skipped (no file is written for 0 rows either way).
Data appears duplicated across runs – Ensure cursor_column updates when rows are modified. If rows are updated without changing updated_at, they will be missed.
Need to re-export all data – rivet state reset --config ... --export <name> clears the cursor.
rivet apply fails with invalid configuration: password missing – A prior rivet plan silently stripped the plaintext password: from the artifact (ADR-0005 PA9). Migrate to password_env: DB_PASSWORD in the config and re-generate the plan. See the WARN line in the plan output.
Composite cursor (nullable primary)
If your primary column can be NULL for some rows (e.g. updated_at only set on updates), see incremental-coalesce.md — progression switches to COALESCE(primary, fallback) via incremental_cursor_mode: coalesce.
Incremental — Composite Cursor (coalesce mode)
See also: ADR-0007 — Cursor Policy Contracts.
When to use
Use incremental_cursor_mode: coalesce when a single column is not a reliable monotonic key, but combining two columns with COALESCE(primary, fallback) is.
Typical situations:
updated_atis nullable for some rows — progression must fall back tocreated_at.- A partial migration left some rows with only a
created_at, others with both. - You intentionally write
updated_atonly on changes and need a baseline for new rows.
If your primary column is reliably non-null and monotonic, stay with plain incremental — it is simpler, faster, and has fewer moving parts.
Required fields
| Field | Value |
|---|---|
mode | incremental |
cursor_column | primary progression column (e.g. updated_at) |
cursor_fallback_column | fallback column used when primary is NULL (e.g. created_at) |
incremental_cursor_mode | coalesce |
Config validation rejects:
coalescewithoutcursor_fallback_columncursor_fallback_columnset for any mode other thancoalesce
Minimal config
source:
  type: postgres
  url_env: DATABASE_URL

exports:
  - name: orders_coalesce
    query: "SELECT id, product, quantity, price, updated_at, created_at FROM orders"
    mode: incremental
    cursor_column: updated_at
    cursor_fallback_column: created_at
    incremental_cursor_mode: coalesce
    format: parquet
    destination:
      type: local
      path: ./output
What Rivet runs
A single-level wrapper with an outer ORDER BY on the coalesced expression (so the last Arrow batch carries the maximum progression value; ADR-0007 CC6):
SELECT _rivet.*,
       COALESCE(_rivet."updated_at", _rivet."created_at") AS "_rivet_coalesced_cursor"
FROM (<your query>) AS _rivet
WHERE COALESCE(_rivet."updated_at", _rivet."created_at") > '<last cursor>'
ORDER BY COALESCE(_rivet."updated_at", _rivet."created_at"),
         _rivet."updated_at",
         _rivet."created_at"
On the first run (no stored cursor) the WHERE is omitted.
State and output
- Stored cursor — a single scalar string, the max value of
COALESCE(primary, fallback)from the last exported batch (ADR-0007 CC5; sameStateStoreshape as regularincremental). - Output files — the synthetic
_rivet_coalesced_cursorcolumn is stripped before writing Parquet/CSV. Your output contains only your selected columns.
Apply semantics
Apply uses the cursor snapshot embedded in the plan artifact (ADR-0005 PA4). The comparison is string-wise and mode-agnostic — coalesce does not change the check, only the meaning of the opaque string.
Quoting and escaping
Rivet quotes cursor_column and cursor_fallback_column using the source dialect ("…" for Postgres, `…` for MySQL). On MySQL the cursor value is sent as a ? bind parameter (never inlined into the SQL). On Postgres it is emitted as an E'…' string literal with ' and \ backslash-escaped (O'Brien → E'O\'Brien'). No additional escaping is required on your side.
Caveats
COALESCEis not indexed — on very large tables the planner may not use the indexes onupdated_atorcreated_at. Preflight (rivet plan) will flag this in diagnostics.- Monotonicity is best-effort — if new rows can appear with a
created_atstrictly less than the latestCOALESCE(...)already seen, they will be skipped. Prefer settingupdated_aton insert when feasible. - One fallback only — two-level lexicographic cursors
(a, b)and more than one fallback are out of scope for v1 (ADR-0007).
Trying it locally
The dev seed (cargo run --bin seed) populates a fixture table orders_coalesce in both Postgres and MySQL with a configurable NULL ratio for updated_at:
# Uses dev/{postgres,mysql}/init.sql + seed defaults (~35% NULL updated_at).
cargo run --bin seed -- --target both --coalesce-rows 2000 --coalesce-null-ratio 0.35

# Then:
rivet plan --config dev/workbench/pg_incremental.yaml --export pg_orders_coalesce
rivet run  --config dev/workbench/pg_incremental.yaml --export pg_orders_coalesce
Troubleshooting
Stored cursor goes backwards — a row was inserted with created_at older than the last seen COALESCE value. Options: set updated_at at insert time, or reset cursor via rivet state reset.
Empty output on second run but new data exists — check that the predicate expression matches the data distribution. rivet plan shows the exact SQL form.
cursor_fallback_column rejected — you need incremental_cursor_mode: coalesce to enable the fallback. Without it, only the primary is used (see incremental.md).
Chunked Export Mode
When to use
Use mode: chunked when the table is too large for a single full export. Rivet splits the data into ranges by a numeric ID column and can process multiple chunks in parallel. Best for:
- Tables with millions or billions of rows
- Tables with a numeric primary key (
BIGINT,SERIAL) - When you need parallel extraction to save time
- Initial loads of large tables
Required fields
chunk_column– a numeric, date, or timestamp column to partition by (typically the primary key). Auto-resolved from the single-integer primary key if you use thetable: schema.nameshortcut (works on Postgres, MySQL, and SQL Server) — warn-level log line:export 'orders_chunked': chunk_column not set — auto-resolved to 'id' from the single-integer primary key on public.orders. Set `chunk_column:` explicitly to pin the choice and silence this warning.
Chunking strategies — pick one
Four ways to slice the table. They differ in how chunk boundaries are computed; everything below the strategy line (parallel, checkpoint, retry) is orthogonal and combines with any of them.
| Strategy | YAML | How boundaries are computed | When to use | Mutually exclusive with |
|---|---|---|---|---|
| Fixed size (default) | chunk_size: 100000 | SELECT MIN, MAX → [min..min+N), [min+N..min+2N), … — N rows of range per chunk | Dense numeric PK, predictable size budget per chunk | chunk_size_memory_mb |
| Fixed count | chunk_count: 16 | Range divided into exactly N equal slices; per-chunk size derived dynamically | You want exactly N workers / files (e.g. = CPU cores) | chunk_by_days |
| Date-native | chunk_by_days: 365 | chunk_column must be DATE / TIMESTAMP / TIMESTAMPTZ; windows of N days with >= AND < (open-end) semantics | Time-series, event logs, historical backfills by period | chunk_count |
| Memory-target | chunk_size_memory_mb: 256 | Auto-computes chunk_size from the engine’s row-size estimate (PG pg_class/reltuples, MySQL information_schema avg row length; SQL Server has no estimate and falls back to 512 B/row); clamped to [10_000, 5_000_000] rows. Requires table: shortcut. Works on Postgres, MySQL, and SQL Server | You want to budget by megabytes, not rows; wide tables where row-width is hard to guess | explicit chunk_size |
| Keyset (seek) | chunk_by_key: uid | Pages with WHERE key > last ORDER BY key LIMIT chunk_size on a unique index — sequential by default; parallel: N fans it into N disjoint key ranges — each page is one part file | MySQL tables with no single-integer PK (UUID / string / composite PK) — the only bounded shape without a server cursor. See Keyset pagination below | chunk_column, chunk_by_days, chunk_count |
Orthogonal options that combine with any strategy:
| Field | Effect |
|---|---|
parallel: N | Up to N chunks execute concurrently (separate DB connections). Default 1. rivet init scaffolds a row-scaled value (≤500 K → 1, <5 M → 2, ≥5 M → 4) |
chunk_checkpoint: true | Per-chunk row in state DB → after a crash, the next run (plain or --resume) skips completed chunks |
chunk_max_attempts: 3 | Requires chunk_checkpoint: true. Total attempt budget per chunk (first attempt + retries): 3 means each failed chunk is retried up to 2 times before the run bails. The budget is stored on the checkpoint run and enforced when a chunk task is claimed, so without chunk_checkpoint it has no effect — the non-checkpointed runners have no per-chunk retry and a failed chunk fails the run. Defaults to tuning.max_retries + 1 |
Picking
parallel. Extraction is I/O-bound, so the win comes from overlapping FETCH round-trips, not from CPU. Measured on a 10-core host, 2 M-row tables: a narrow table scales near-linearly (1→4≈ 4.2× faster), while a wide table (many large columns) saturates the wire early and plateaus atparallel: 2(2→4buys almost nothing for +60 % RSS). Each worker holds its own chunk buffer, so RSS grows roughly linearly withN— raise it for narrow tables, keep it at 2 for wide ones. Theinitheuristic is a good starting point; tune from there if memory or source connection count is constrained.
Each integer-range chunk runs: SELECT * FROM (<base_query>) AS _rivet WHERE <chunk_column> BETWEEN <lo> AND <hi> — inclusive bounds (hi = lo + chunk_size - 1) inlined as literals, not bind parameters. The subquery wrap applies to query: exports; a table: shortcut renders the unwrapped SELECT * FROM <table> WHERE <chunk_column> BETWEEN <lo> AND <hi>. The date variant (chunk_by_days) uses half-open WHERE col >= '<start>' AND col < '<end>'.
Minimal config
source:
  type: postgres
  url: "postgresql://user:pass@host:5432/dbname"

exports:
  - name: orders_chunked
    query: "SELECT id, user_id, product, price, status, ordered_at FROM orders"
    mode: chunked
    chunk_column: id                # numeric column to split ranges on
    chunk_size: 100000              # rows per chunk (default: 100,000)
    parallel: 4                     # concurrent chunk workers
    format: parquet
    destination:
      type: local
      path: ./output
Output files: one per chunk, named {export}_{YYYYMMDD_HHMMSS}_chunk{N}_{16-hex-nonce}.parquet, e.g. orders_chunked_20260406_120000_chunk0_a1b2c3d4e5f60718.parquet. The random nonce makes retried/re-run parts additive (never overwriting); match on *_chunk{N}_*.parquet, not on an exact stem.
Run it
# Preflight — shows chunk plan (how many chunks, range distribution)
rivet check --config large_table.yaml

# Run with validation and reconciliation
rivet run --config large_table.yaml --validate --reconcile
Progress bar (chunked exports)
In mode: chunked, Rivet shows a terminal progress bar while chunks run: export name, current/total chunks, running row count, elapsed time, and ETA. It appears when stderr is an interactive TTY (a normal terminal window). The bar does not depend on RUST_LOG (that variable only controls env_logger text lines). In CI, or when you pipe or redirect stderr, the bar is usually suppressed — then set RUST_LOG=info (or debug) to follow progress in the log instead.
The GIF above was recorded with RUST_LOG=info on a 50,000-row fixture (10 chunks of 5,000) so the per-chunk log line export 'events': chunk N/10 (...) and the final summary are both visible. On a real interactive terminal you would see the progress bar instead; the log lines appear when stderr is captured.
Use a small chunk_size relative to your table if you want many steps on the bar (each finished chunk advances it once). parallel: 1 still updates the bar after each sequential chunk.
Ready-made example in this repo: dev/scenarios/chunked_postgres_bench.yaml includes bench_content_p4_safe: PostgreSQL content_items with parallel: 4 and tuning.profile: safe (good for trying the bar on a wide table without hammering the source). Other exports in the same file cover serial / highly parallel / fatchunk / balanced profiles.
# From repo root; Postgres up + seeded (e.g. docker compose + cargo run --bin seed ...)
mkdir -p dev/output/bench
rivet check --config dev/scenarios/chunked_postgres_bench.yaml
rivet run --config dev/scenarios/chunked_postgres_bench.yaml --export bench_content_p4_safe
# Optional: RUST_LOG=info for more log detail; RUST_LOG=warn to reduce log noise (bar unchanged in a TTY)
What happens
- Rivet queries
SELECT MIN(id), MAX(id) FROM ordersto determine the range - Splits into chunks:
[min..min+chunk_size),[min+chunk_size..min+2*chunk_size), … - Each chunk runs independently:
SELECT ... WHERE id BETWEEN <lo> AND <hi>(inclusive, hi = lo + chunk_size - 1) - With
parallel: 4, up to 4 chunks execute concurrently - Each chunk writes a separate output file
Chunk checkpoint (resume after crash)
For very large exports, enable checkpointing so you can resume from where you left off:
exports:
  - name: orders_chunked
    query: "SELECT id, user_id, product, price, ordered_at FROM orders"
    mode: chunked
    chunk_column: id
    chunk_size: 100000
    parallel: 4
    chunk_checkpoint: true          # persist progress per chunk
    chunk_max_attempts: 3           # total attempt budget per chunk (3 attempts = 2 retries)
    format: parquet
    destination:
      type: local
      path: ./output
Resume after a crash:
# Resume only processes incomplete chunks
rivet run --config large_table.yaml --resume

# View checkpoint status
rivet state chunks --config large_table.yaml --export orders_chunked

# Clear checkpoint (to re-export from scratch)
rivet state reset-chunks --config large_table.yaml --export orders_chunked
Clean re-runs are NOT idempotent
Chunked mode is not “extract once, skip on the next clean run”. Two
plain rivet run invocations against the same table re-extract every
chunk both times — chunk_checkpoint: true only matters after a crashed
run, which the next run resumes. Each clean run produces a new file set with a
fresh run_id and timestamp suffix.
| Invocation | Behaviour |
|---|---|
rivet run (fresh) | extracts all chunks, writes files with run_id A |
rivet run (again, no crash) | extracts all chunks again, writes files with run_id B |
rivet run --resume (after a crash) | extracts only the chunks chunk_state says are incomplete |
If you want skip-on-no-change semantics, use mode: incremental
with a cursor_column instead — that mode persists the cursor between
runs, and skip_empty: true records a run that found nothing new as
skipped.
Chunk sizing guidance
| Table size | Suggested chunk_size | parallel |
|---|---|---|
| 1M rows | 100,000 | 2 |
| 10M rows | 100,000 | 4 |
| 100M+ rows | 200,000-500,000 | 4-8 |
Larger chunks = fewer queries but more memory per batch. Smaller chunks = more queries but lower peak RSS.
Date-based chunking
When your table’s natural partition boundary is time rather than a numeric ID, use chunk_by_days instead of relying on integer ranges.
exports:
  - name: orders_by_year
    query: "SELECT id, user_id, product, price, ordered_at FROM orders"
    mode: chunked
    chunk_column: ordered_at        # DATE or TIMESTAMP column
    chunk_by_days: 365              # one chunk per ~year
    format: parquet
    destination:
      type: local
      path: ./output
Rivet fetches MIN / MAX of the column as text, parses the dates, then generates non-overlapping windows:
-- each chunk window (open-end exclusive):
WHERE ordered_at >= '2023-01-01' AND ordered_at < '2024-01-01'
WHERE ordered_at >= '2024-01-01' AND ordered_at < '2025-01-01'
...
The open-end < end_date bound is intentional: it correctly captures all TIMESTAMP values within the day, including 23:59:59.999….
When to use date chunking over numeric chunking:
- The table has no dense numeric PK (UUIDs, composite keys)
- You want even partitions by time, not by row count
- The source DB has better statistics / indexes on the timestamp column
- You want to avoid unix-epoch arithmetic that JDBC tools often get wrong
chunk_by_days can be combined with parallel for concurrent date windows, and supports chunk_checkpoint / --resume like numeric chunked mode.
rivet check will report the strategy as date-chunked(ordered_at, 365d).
Sparse ID ranges
If IDs have large gaps (e.g. UUIDs cast to BIGINT, or deleted rows), many chunks may be empty. On a unique key use keyset (chunk_by_key, below) — it pages by rows, so gaps cost nothing. Otherwise chunk_count: N caps the number of windows.
rivet check will warn you about sparse ranges.
chunk_densewas removed. It paged byROW_NUMBER() OVER (ORDER BY chunk_column), recomputed per chunk, so concurrent inserts or deletes skipped or duplicated rows even on a unique key. A config that still setschunk_dense: trueis refused at load.
Keyset (seek) pagination — the safe shape without an integer PK
Range chunking needs a single integer PK to slice MIN..MAX. A MySQL table
whose PK is a UUID, string, or composite key has no such column, and — unlike
PostgreSQL — MySQL has no server-side cursor to bound a mode: full
snapshot. That left a real hole: such tables could only be exported as one
long-held SELECT * (the exact “don’t hold a long query on prod” risk Rivet
exists to avoid).
MongoDB has the same shape, but under
mode: full(a document store has nochunkedmode):source.mongo.page_sizeenables keyset (seek) paging on_id,parallel: Nfans out over disjoint_idranges, and both resume on_id. See ../reference/mongodb.md.
Keyset pagination closes it. Rivet pages the table by a unique, NOT NULL, index-backed key:
-- first page
SELECT * FROM (<base>) AS _rivet ORDER BY `uid` LIMIT 1000
-- subsequent pages (cursor = last page's max key)
SELECT * FROM (<base>) AS _rivet WHERE `uid` > ? ORDER BY `uid` LIMIT 1000
Each page is a bounded, index range scan (verified EXPLAIN: type: range
on the PK, no filesort, no full scan) and becomes one part file. This bounds
both peak RSS (≤ chunk_size rows in flight) and longest-query time.
exports:
  - name: events
    table: app.events            # `table:` shortcut required (index check)
    mode: chunked
    chunk_by_key: event_uuid     # single-column UNIQUE / PRIMARY, NOT NULL
    chunk_size: 1000             # rows per page
    format: parquet
    destination:
      type: local
      path: ./output
Output files: one per page, named {export}_{run_id}_keyset_{tag}.parquet where run_id is {export}_YYYYMMDDTHHMMSS.mmm (filename sanitization maps the . to _) and the tag is start for the first page, then a 16-hex hash of that page’s seek cursor — e.g. events_events_20260529T120000_123_keyset_start.parquet. The run_id/seek-based name makes a crash-resume overwrite its own page idempotently.
Auto-resolution (MySQL). With the table: shortcut and no chunk_by_key,
if the table has no single-integer PK but does have a usable single-column
unique key, Rivet auto-selects keyset on it and logs a warn naming the key
(set chunk_by_key: to pin the choice and silence the warning). On PostgreSQL,
auto-resolution stays off — its DECLARE CURSOR snapshot is already bounded, so
mode: full is the safe answer there; chunk_by_key: still works if you want
per-page files.
The key must be index-backed. This is the load-bearing safety property: an
ORDER BY on a non-indexed column degrades to a full-scan + filesort — worse
than the snapshot it replaces. Rivet refuses a chunk_by_key that is not a
single-column, NOT NULL, UNIQUE/PRIMARY key rather than emit such a query:
chunk_by_key 'payload' is not a usable keyset key on app.events — it must be a
single-column, NOT NULL, UNIQUE or PRIMARY key WHOSE TYPE the keyset cursor can
read (integer / float / string / timestamp / date / uuid). A `decimal`/`numeric`
key is excluded: the cursor cannot advance past it (it would fail mid-run after
a partial write). Without a usable key, `ORDER BY payload LIMIT n` would also
full-scan + filesort. Add a unique index of a supported type, pick another key,
use a range `chunk_column:` (integer), or `mode: full`.
Required privileges: read-only is sufficient — the introspection probe reads
information_schema index metadata, no elevated grants needed.
Resumability (chunk_checkpoint). rivet init defaults chunk_checkpoint: true
on keyset exports. It is crash-recovery: a run that dies mid-stream resumes from
its last committed key on the next run (its in-progress run_id is still open); a
run that finished CLEANLY clears that marker, so a plain re-run does a full pass and
never silently skips already-exported rows.
Append-only incremental (keyset_incremental). Off by default. When set, a
CLEAN re-run continues from the last exported key — pulling ONLY rows past the
high-water mark. Correct only for append-only tables: on a mutable table a row
whose key already passed is silently never re-read. For a mutable table use
mode: incremental on a timestamp cursor instead.
    chunk_by_key: event_uuid
    chunk_checkpoint: true       # crash-recovery (default on for keyset)
    keyset_incremental: true     # append-only ONLY: clean re-run pulls just new keys
Parallel keyset (parallel: N)
By default keyset pages sequentially — each page seeks past the previous page’s
last key. Set parallel: N and Rivet instead splits the key into N ROW-based
percentile ranges and seeks each range concurrently on its own connection:
    chunk_by_key: event_uuid
    chunk_size: 1000
    parallel: 4                  # 4 workers, each seeks a disjoint key range
The ranges are half-open ([lo, hi)) and adjacent, so together they partition
the key — every row is read exactly once (structural parity, proven on all
engines). Each worker still pages by seek within its range, so peak RSS stays
bounded (≤ N × chunk_size rows in flight) and no worker holds a long query.
Per-range crash-recovery is tracked in the state DB (chunk_checkpoint): a run
that dies resumes only the unfinished ranges.
Sweet spot. Extraction is I/O-bound, so the speedup plateaus early — ~3.1× at
parallel: 4on an indexed table, little beyond 4. It is tuned for indexed tables up to ~10 M rows. Past that, the range-boundary sampler (an indexOFFSETskip to find each percentile cut) grows costly at setup — for very large tables prefer a rangechunk_column(integer-PK), which slicesMIN..MAXarithmetically with no sampling pass.Canary first. Parallel keyset is new in 0.23.0. Run it on a canary table and diff row counts against a sequential (
parallel: 1) pass before rolling it out across a fleet — the sequential path is unchanged and remains the conservative default.
rivet init scaffolds a row-scaled parallel (≤500 K → 1, <5 M → 2, ≥5 M → 4)
on range chunk_column tables (no single-column PK). A keyset
(chunk_by_key) table is scaffolded sequential — add parallel: N yourself
to opt into parallel keyset. A preflight warns past ~5 M rows that peak RSS scales
with N.
Limitations (current):
- Single-column keys only — composite unique keys are not yet supported.
- Decimal (
numeric) keys andpartition_byare rejected for ALL keyset exports, sequential included: a decimal key is refused at plan time because the keyset cursor cannot read/advance past it, andpartition_byis incompatible withchunk_by_keyat config validation. (Parallel keyset adds no extra key-type restriction beyond these.)
Troubleshooting
Many empty chunks – Your ID column has gaps. Use chunk_by_key on a unique key, or chunk_count: N.
High memory usage with parallel > 1 – Reduce chunk_size or add tuning.profile: safe.
Export fails midway through 1000 chunks – Enable chunk_checkpoint: true; the next run resumes from the completed chunks, whether the last run crashed or failed.
Time-Window Export Mode
When to use
Use mode: time_window to export only rows within a rolling N-day window from the current timestamp. Best for:
- Event tables where you only need the last 7/30/90 days
- Periodic refresh of a “recent activity” dataset
- When
incrementalis not suitable because you need overlapping windows
Required fields
time_column– the timestamp column to filter ondays_window– how many days back from now to include
Minimal config
source:
  type: postgres
  url: "postgresql://user:pass@host:5432/dbname"

exports:
  - name: recent_events
    query: "SELECT id, user_id, event_type, payload, created_at FROM events"
    mode: time_window
    time_column: created_at         # timestamp column to filter
    days_window: 30                 # include rows from the last 30 days
    format: parquet
    destination:
      type: local
      path: ./output
Run it
rivet check --config events.yaml
rivet run --config events.yaml --validate
What happens
- Rivet calculates the cutoff:
NOW() - 30 days - Appends
WHERE created_at >= '2026-03-07 00:00:00'to your query - Exports all matching rows as a fresh file
- No cursor is stored – each run re-evaluates the window
Unlike incremental, this mode produces overlapping data across runs (the last 30 days always overlap with yesterday’s last 30 days).
Re-runs always emit a new file (intentional)
time_window does not persist “we already exported this window” anywhere.
Each rivet run re-evaluates the rolling window relative to NOW() and
writes a fresh file. Two back-to-back runs inside the same minute will
produce two near-identical files — same rows, different run_id /
timestamp suffix. That is the contract: this mode is built for rolling
recent activity (alerting, daily syncs), not for exactly-once
delivery. If you need the latter, switch to mode: incremental with a
cursor_column and skip_empty: true.
Downstream consumers that need deduplication should key off the
id / business key inside the rows themselves, not on file name or
run_id.
Time column types
By default, Rivet assumes a TIMESTAMP/DATETIME column. For Unix epoch integers, set time_column_type:
exports:
  - name: recent_events
    query: "SELECT id, user_id, event_type, created_at_epoch FROM events"
    mode: time_window
    time_column: created_at_epoch
    time_column_type: unix          # column stores Unix epoch (seconds)
    days_window: 7
    format: csv
    destination:
      type: local
      path: ./output
time_column_type | Column type | Filter generated |
|---|---|---|
timestamp (default) | TIMESTAMP / DATETIME | WHERE col >= '2026-03-07 00:00:00' |
unix | INT / BIGINT | WHERE col >= 1741305600 |
Common options
exports:
  - name: recent_events
    query: "SELECT id, user_id, event_type, created_at FROM events"
    mode: time_window
    time_column: created_at
    days_window: 30
    format: parquet
    compression: zstd
    skip_empty: true
    destination:
      type: local
      path: ./output
Troubleshooting
0 rows exported but the table has data – Check that days_window is large enough. Events older than the window are excluded. Also check timezones.
Duplicates across runs – This is by design. Each run exports the full window. Downstream consumers should deduplicate by primary key.
Need non-overlapping exports – Use mode: incremental with cursor_column instead.
CDC Reference
Rivet’s change-data-capture (CDC) reads a source’s transaction log — not the
tables — and emits each INSERT / UPDATE / DELETE as a row change. Because it
tails the log that the database already writes for replication and durability, it
adds almost no load to the OLTP path: no table scan, no locks, no read snapshot
(see Why CDC is gentle on the source).
Status. All three SQL engines support NDJSON streaming and typed Parquet/CSV
--output(realTimestamp/Date32/Decimal128columns). This page documents all three so the permissions are clear up front — they are the part operators most need to get right.MongoDB also has CDC — via change streams, with a different setup (a replica set, not per-table grants) and the JSON-blob document image rather than typed columns. It has its own reference: mongodb.md.
The command
# stream changes as NDJSON to stdout (no schema resolution, fewest privileges)
rivet cdc --source 'mysql://rivet_cdc:***@127.0.0.1:3306/app' --table orders

# write typed Parquet files (one row per change, after-image / upsert shape)
rivet cdc --source 'mysql://rivet_cdc:***@127.0.0.1:3306/app' \
          --table orders --output ./cdc-out --format parquet \
          --checkpoint ./orders.ckpt --rollover 100000
Prefer --source-env VAR or --source-file path over an inline URL outside local
dev — the URL is otherwise visible in ps / shell history.
The rivet cdc CLI is loopback-only: it carries no TLS configuration, so the
TLS gate refuses any remote (non-loopback) host before connecting. For a remote
source, use the config-driven rivet run path with a source.tls: block (see
From config).
| flag | meaning |
|---|---|
--server-id | replica id for the binlog connection (MySQL). Must be unique — distinct from the source and every real replica. Default 4271. |
--checkpoint PATH | persist/resume the log position. Omission semantics differ per engine: MySQL and MongoDB tail from the current position without checkpointing; PostgreSQL anchors server-side at the slot regardless (omission merely disarms the slot-loss hard error the checkpoint enables); SQL Server with no checkpoint re-reads the entire retained change table on every run. Keep it set. On the first checkpointed MySQL run the open position is persisted immediately (the client-side analogue of PostgreSQL’s slot pinning at creation), so an idle first run still anchors the resume position — without it, changes landing between two idle scheduler cycles would be skipped. |
--table NAME | only emit this table (repeatable for NDJSON; exactly one required for --output, whose schema is resolved from the source). |
--output DIR | write typed Parquet/CSV files instead of NDJSON. |
--max-events N | stop after N changes; without it the default bounded run drains to the log end as of open and exits (stream until interrupted only with --stream). The checkpoint is saved at transaction-commit boundaries (never mid-transaction), so an interrupted run resumes from the last fully committed transaction — re-reading, never skipping, a partially processed one. |
--rollover N | rows per output part file (default 100000); also rolls at a transaction boundary, never splitting one. This is the file-size ⇄ memory dial: larger ⇒ fewer, bigger files but more drain memory (the PostgreSQL peek reads a part’s worth per batch, so drain RSS is O(rollover) — ≈28 MB + 1.3 KB × rollover). Raise it to cut file count on a big host; lower it to cap memory on a small extractor. (Config: cdc.rollover.) |
--slot NAME | PostgreSQL logical slot (default rivet_slot; created if absent). |
--capture-instance NAME | SQL Server CDC capture instance (e.g. dbo_orders) — required for sqlserver://. |
--stream | Opt out of the default bounded run and stream continuously (a long-lived daemon). By default rivet cdc catches up to the source’s log end as of the moment the run opened, then exits instead of streaming — this is the scheduler-friendly model, so no flag is needed for it. Every engine pins that boundary at open (PostgreSQL: pg_current_wal_lsn(); MySQL: the binlog coordinates, plus BINLOG_DUMP_NON_BLOCK as the catch-up backstop; SQL Server: fn_cdc_get_max_lsn(); MongoDB: the cluster operationTime; Oracle: the current SCN), so a hot table whose writers outpace the drain cannot keep the run alive chasing a moving log end — the run’s work is O(backlog at open), and everything committed after the boundary is picked up by the next run from the checkpoint. With --max-events N, the bounded run stops at the smaller of “N events” or the boundary — so it never blocks waiting for the N-th event. Passing --stream removes the open-time boundary, but what that means is engine-specific: MySQL genuinely stays up (the binlog dump blocks on an idle source), and so does MongoDB (the change stream blocks awaiting events; it ends only if the stream is invalidated or closed); PostgreSQL and SQL Server are poll adapters that still exit on catch-up — one unbounded pass, not a daemon. Oracle refuses --stream (and cdc.until_current: false): LogMiner here is always a bounded drain to the SCN current at open. On PostgreSQL and SQL Server a continuous pipeline needs an external supervisor re-running the command (or just the default bounded model on a schedule). On a PostgreSQL standby (PG 16+ logical decoding) the ceiling query (pg_current_wal_lsn()) is unavailable during recovery, so the default bounded run fails loudly at open — pass --stream, or point the source at the primary. |
The engine is chosen from the URL scheme (mysql:// / postgresql:// /
sqlserver:// / mongodb://) by create_change_stream, the CDC sibling of the batch
create_source. With --output, each part goes through the same commit
path the batch export uses (ADR-0004) and a manifest.json + _SUCCESS is
written at clean end — but the CLI’s --output is a local directory only
(it is wired to the local destination; a gs://…/s3://… string would be
taken as a literal local path). For a cloud destination, use the config path
(mode: cdc with a destination: block) below. Typed columns
(real Timestamp / Date32 / Decimal128, not strings) flow through RivetValue
structural typing — for all three engines (MySQL binlog values, PostgreSQL
test_decoding parse, SQL Server change-table ColumnData).
From config (rivet run)
CDC also runs as an export in a config, so a scheduled rivet run captures
changes alongside batch exports and records the run the same way:
source:
  type: mysql
  url_env: DATABASE_URL          # credentials out of the file
  tls: { mode: verify-full }     # required for a remote host (see below)
exports:
  - name: orders_cdc
    table: orders
    mode: cdc
    format: parquet
    cdc:
      checkpoint: /var/lib/rivet/orders.ckpt
      until_current: true        # drain to now and exit — for a scheduler
      # per-engine, all optional:
      server_id: 4271            # MySQL replica id
      slot: rivet_orders         # PostgreSQL logical slot
      capture_instance: dbo_orders  # SQL Server (required for sqlserver://)
    destination: { type: gcs, bucket: my-bucket, prefix: cdc/orders }
rivet run --config cdc.yaml      # captures, writes typed Parquet, records the run
rivet metrics -c cdc.yaml        # the CDC run appears with mode=cdc, like a batch
A mode: cdc export reuses the export’s table, destination, and format; the
cdc: block carries only the CDC-specific knobs.
initial: snapshot — the safe switch, enforced by construction. On the
first run (no anchor yet) rivet performs, in order: ① create the resume anchor
(PostgreSQL slot / MySQL binlog checkpoint / SQL Server max-LSN checkpoint),
② run a full batch snapshot of each table into
<destination>[/<table>]/snapshot/ (its own parts + manifest.json +
_SUCCESS), ③ drain the change stream. Because the anchor predates the
snapshot read, a change landing mid-snapshot appears in both the snapshot
and the stream — an overlap the PK + __op dedupe absorbs, never a gap.
Subsequent runs skip the snapshot because the state DB records it as done (cdc_snapshot — the authoritative signal; the snapshot/_SUCCESS marker remains a legacy co-signal, so re-snapshotting requires clearing BOTH) and go straight to draining;
a run that crashes mid-snapshot re-snapshots on retry (the anchor stays put, so
nothing is lost). Once any snapshot completed, a MISSING server-side anchor
(a dropped PostgreSQL slot) is a loud error, never a silent re-anchor — see
“A vanished slot” below. Load order downstream: the snapshot prefix as the base table,
then MERGE the CDC parts. MySQL / SQL Server require cdc.checkpoint: with
initial: snapshot (it is the anchor); PostgreSQL anchors in the slot.
  - name: orders_cdc
    table: orders
    mode: cdc
    format: parquet
    cdc: { initial: snapshot, checkpoint: /var/lib/rivet/orders.ckpt, until_current: true }
    destination: { type: gcs, bucket: my-bucket, prefix: cdc/orders }
cdc.backfill: — the baseline by reference, for tables that disagree.
initial: snapshot synthesizes one single-connection mode: full scan per
captured table. That is right for a small table and wrong for a large
one — a 313M-row table read end to end on one statement runs into
tuning.statement_timeout_s (300s under the balanced profile) long before it
finishes, while the same table as a batch export, keyset-paged with parallel: 4,
takes ~22 minutes. And a multiplex stream’s tables do not agree on how they are
read: one has a unique id and keysets, another has only a non-unique index and
must range-chunk.
So the baseline is declared by REFERENCE — each captured table names the ordinary batch export that already describes how to read it:
exports:
  - name: orders                 # an ordinary export; `rivet init` already writes it
    table: orders
    mode: chunked
    chunk_by_key: id             # keyset
    parallel: 4
    chunk_checkpoint: true       # the baseline is resumable
    format: parquet
    destination: { type: gcs, bucket: my-bucket, prefix: exports/orders/ }
    columns: { price: decimal(10,2) }

  - name: app_cdc
    tables: [orders]
    mode: cdc
    format: parquet
    cdc:
      checkpoint: /var/lib/rivet/app.ckpt
      backfill: auto             # or: [orders, …]
    destination: { type: gcs, bucket: my-bucket, prefix: cdc/ }
auto pairs each entry of tables: with the export whose table: names it;
a list names them explicitly. One rivet run then does anchor → baseline → drain,
and the ordering is what makes it safe: the anchor is taken before the first row
is read, so a row changed mid-baseline also arrives on the stream and the
current-state view keeps the higher (__pos, __seq).
What the leg borrows and what stays its own is the whole design. Borrowed:
mode, chunk_by_key / chunk_column, page size, parallel, chunk_checkpoint,
tuning and the column types. Its own: the name, the <destination>/<table>/snapshot/
prefix, the format and the meta columns — so the referenced export contributes a
recipe, never a second load target, and every load invariant that holds for a
synthesized leg holds unchanged here. Types MERGE (the recipe’s, with a qualified
"table.column" key on the CDC export still winning); a column both sides declare
differently is refused, because the two legs write into one <table>__changes
and one column cannot have two types.
The run loop skips an export that is named as a backfill recipe, so a full
rivet run reads each table once — rivet run -e orders still exports it on its
own. An interrupted baseline resumes on the next plain rivet run from its chunk
checkpoints (range-chunked and keyset legs alike, both live-proven against a crash
after the first page — no --resume, no synthesized name; a leg whose recipe
changed after the crash names rivet state reset-chunks -e <leg>) and
leaves the anchor alone; once a table’s baseline is recorded (per table, in the
state DB), later runs go straight to the drain. cdc.initial: and cdc.backfill:
both describe the first run’s baseline, so config load refuses the pair.
Multiple CDC exports: each owns its stream resources. A PostgreSQL slot has
ONE consumer (a shared slot is advanced past changes the other export never
read), a MySQL server_id has ONE connection (the server kills the older one),
and a checkpoint file has ONE writer. Config validation rejects two mode: cdc
exports that resolve to the same slot / server_id / checkpoint — including
the defaults (rivet_slot, 4271): a multi-table CDC config must set them
explicitly per export:
exports:
  - name: orders_cdc
    table: orders
    mode: cdc
    cdc: { slot: rivet_orders, checkpoint: /var/lib/rivet/orders.ckpt }
    ...
  - name: users_cdc
    table: users
    mode: cdc
    cdc: { slot: rivet_users, checkpoint: /var/lib/rivet/users.ckpt }
    ...
Or multiplex: several tables through ONE stream (tables:). N single-table
exports cost N slots — and PostgreSQL decodes the WAL once per slot (MySQL:
N binlog connections). One export with tables: rides a single slot/connection
and a single checkpoint, and routes each table’s changes to its own sub-prefix
(<destination>/<table>/, each with its own parts + manifest.json +
_SUCCESS — exactly like N exports, minus the N−1 slots):
exports:
  - name: app_cdc
    tables: [orders, users, payments]
    mode: cdc
    format: parquet
    cdc: { slot: rivet_app, checkpoint: /var/lib/rivet/app.ckpt, until_current: true }
    destination: { type: local, path: /data/cdc }   # → /data/cdc/orders/, /data/cdc/users/, …
The resume position is a property of the stream, so the at-least-once sequence generalises: every table’s buffered part is flushed before the one checkpoint/ack advances — a crash mid-roll re-reads for all tables rather than losing any one of them.
columns: overrides on a multi-table export support two key shapes: a bare
column name applies to every captured table that has it, and a qualified
"table.column" key targets one table and wins over the bare key there —
so same-named columns needing different treatments never collide:
    columns:
      amount: "decimal(20,4)"          # every table's `amount`
      "legacy_orders.amount": text     # …except this one
A qualified key naming a table the export does not capture is a config error (a typo must fail at load, never silently miss its target).
Whole-database CDC across engines — and why the config shape differs.
tables: multiplexing is PostgreSQL/MySQL only, and that is a property of the
engine, not a rivet or driver limit. MySQL exposes one server-wide binlog and
PostgreSQL one logical slot — a single stream carrying every table’s changes, so
rivet reads it once and routes by table (and two exports sharing the
slot/server_id would collide — exactly the scarce resource the one-stream form
conserves). SQL Server has no such stream: CDC is enabled per table
(sys.sp_cdc_enable_table) and read through a per-capture-instance function
(cdc.fn_cdc_get_all_changes_<instance>) — there is no server-wide “all changes”
surface to tap, so capture is inherently per-table. Use one export per table
there, each with its own capture_instance; sharing a capture_instance between
exports is safe (the change-table poll is read-only and resume state lives in the
per-export checkpoint), and per-table exports never collide (no slot / server_id
— the change tables are populated by one shared capture Agent regardless of how
many readers).
The operator flow is identical across the three SQL engines, only the config
shape differs (MongoDB’s whole-database change stream uses the same mode: cdc
config shape — see mongodb.md):
rivet init --mode cdc(no--table) scaffolds the whole database on every engine — onetables:export on MySQL (and on PostgreSQL when every table is in thepublicschema; mixed schemas fall back to per-table exports), one export per table (distinctcapture_instance) on SQL Server — so you never hand-list tables. Over two or more tables on MySQL/PostgreSQL the stream getsbackfill: autoand one batch recipe per table (the baseline read), and itsload:may carrytables: { <table>: { pk, partition, cluster_by, … } }so each captured table has its own warehouse shape.rivet run -c <config>drains the whole set; add--parallel-export-processesto run SQL Server’s per-table exports concurrently.rivet validate -c <config>descends into every table’s prefix and itsinitial: snapshotsub-dataset on every engine, so one command certifies the whole stream.
The per-table vs one-stream split is connection/resource topology, not
throughput or memory: drain RSS is O(part rollover) per stream on all three
engines, independent of table count. Each run produces the standard
per-export summary block and an export_metrics row (rows / files / bytes /
duration / status), so CDC shows up in rivet metrics and the run aggregate
exactly like a batch export. TLS: unlike the CLI (which is loopback-only),
the config path passes source.tls to the change stream — so a remote source over
TLS requires the tls: block, and a remote host without it is refused before any
connection (the same gate the batch path uses).
The four models
Rivet normalises four different source mechanisms behind one ChangeStream:
| engine | mechanism | model |
|---|---|---|
| MySQL | binlog (ROW) streamed as a replica | push — the client reads the log directly |
| PostgreSQL | logical replication slot (test_decoding) | poll the slot via pg_logical_slot_peek_changes() |
| SQL Server | cdc.* change tables the capture Agent extracts | poll the change function by LSN window |
| MongoDB | whole-database change stream (db.watch() over the oplog) | tailable stream; the resume token checkpoints the position (JSON-blob image — see mongodb.md) |
| Oracle (preview) | LogMiner over the redo logs, mined from CDB$ROOT | poll: each run mines [checkpoint, SCN at open] with COMMITTED_DATA_ONLY (ADR-0037) |
MySQL and PostgreSQL expose the log to the client; SQL Server does not — there a server-side Agent extracts the log into change tables that rivet polls.
Permissions & prerequisites
MySQL — the binlog grants
Rivet registers as a replica and streams the binlog. Least privilege:
CREATE USER 'rivet_cdc'@'%' IDENTIFIED BY '***';

-- read the binlog stream (register as replica, COM_BINLOG_DUMP).
-- Server-wide: REPLICATION SLAVE cannot be scoped to a database/table.
GRANT REPLICATION SLAVE  ON *.* TO 'rivet_cdc'@'%';

-- read the current binlog coordinate (SHOW MASTER STATUS) when starting
-- without a checkpoint.
GRANT REPLICATION CLIENT ON *.* TO 'rivet_cdc'@'%';

-- ONLY for `--output`: rivet resolves the table's column types with
-- `SELECT * FROM <table> LIMIT 0` (metadata only, no rows). Not needed for NDJSON.
GRANT SELECT ON `app`.`orders` TO 'rivet_cdc'@'%';

FLUSH PRIVILEGES;
Server configuration (my.cnf [mysqld], or SET GLOBAL + restart where
allowed):
log_bin           = ON       # binary logging on (often already on for replication/PITR)
binlog_format     = ROW      # rivet needs row images, not statements — MIXED/STATEMENT will not work
binlog_row_image  = FULL     # full before/after image — REQUIRED for the after-image / MERGE shape;
                             # MINIMAL drops unchanged columns and breaks "overwrite all columns"
server_id         = 1        # any unique id for the source; rivet uses a DIFFERENT --server-id
Notes:
-
REPLICATION SLAVEis server-wide by design. You cannot grant binlog access for one database only — the binlog is a single server-wide stream. Scope data exposure with--table(rivet filters client-side) and theSELECTgrant. -
A stale
server_idcollision silently kills the stream. Give rivet a--server-idno other replica uses. -
Connect CDC directly to MySQL — not through ProxySQL / MaxScale. The binlog stream is
COM_BINLOG_DUMP, a replication protocol query proxies don’t carry; the batch path can go through a pooler, CDC cannot. Rivet probes the connection and fails fast with this exact reason if it sees a proxy, so point the source at the MySQL host (the replication endpoint), not the proxy port. -
binlog_row_image = FULLis MySQL’s default; the risk is a source that has set it toMINIMALto shrink the binlog — that path needs the column-mask MERGE, not the simple overwrite (see Output shape). -
Amazon RDS / Aurora MySQL: two managed-only settings, and neither is in
my.cnf. Both were diagnosed the hard way on a customer replica, a day apart.-
Binary logging follows automated backups. With backup retention at 0 the instance runs
log_bin = 0no matter what the parameter group says, andSHOW BINARY LOGSanswersERROR 1381 (HY000): You are not using binary logging. Set backup retention above zero (this restarts the instance), thenbinlog_format = ROW,binlog_row_image = FULLandbinlog_row_metadata = FULLin the parameter group. A read replica also needslog_replica_updates = 1to re-log what it applies. -
binlog_expire_logs_secondsdoes not govern retention here. RDS purges a binlog as soon as the engine itself no longer needs it — typically within minutes — so a checkpoint written by one run is unreadable by the next and the resume fails with ERROR 1236. Measured: a checkpoint taken at 13:42 was already past retention at 13:59. Set the managed knob instead, sized well above the CDC cadence:CALL mysql.rds_set_configuration('binlog retention hours', 72); CALL mysql.rds_show_configuration; -- confirm
The filenames are the tell:
mysql-bin-changelog.NNNNNNis RDS’s naming, so anERROR 1236naming one of those is this, notPURGE BINARY LOGS. -
PostgreSQL — the logical slot
Rivet’s PostgreSQL reader consumes a logical slot through the normal SQL
connection (pg_logical_slot_peek_changes()), not the streaming-replication
protocol. That changes what you must grant:
-- REPLICATION attribute: required to create and read a logical slot, even via
-- the SQL functions (pg_create_logical_replication_slot / _get_changes).
ALTER ROLE rivet_cdc WITH LOGIN REPLICATION PASSWORD '***';

-- ONLY for `--output`: schema resolution (SELECT ... LIMIT 0).
GRANT SELECT ON app.orders TO rivet_cdc;
Server configuration (postgresql.conf, needs a restart):
wal_level            = logical   # log enough to decode row changes (default is 'replica')
max_replication_slots = 10       # >= 1 (defaults are usually fine)
max_wal_senders       = 10       # >= 1
Notes:
- No
pg_hba.confreplicationline is required. That entry is for the streaming walsender protocol; rivet’s poll model uses an ordinary connection, so the normalhost app rivet_cdc ...rule suffices. (This is the main way the poll model is operationally lighter than streaming CDC tools.) - A logical slot pins WAL until it is consumed/advanced. An abandoned slot
prevents WAL recycling and fills the disk — the number-one PostgreSQL CDC
foot-gun. Drop unused slots with
SELECT pg_drop_replication_slot('rivet_slot');. wal2json/pgoutputare alternatives totest_decoding;test_decodingis always built in and needs no extension.
SQL Server — CDC change tables
SQL Server has no client-streamable log. A server-side Agent job extracts the
log into cdc.* change tables, which rivet polls. Two distinct privilege levels:
-- ONE-TIME ENABLE (requires sysadmin or db_owner):
EXEC sys.sp_cdc_enable_db;                         -- creates the cdc schema + capture job
EXEC sys.sp_cdc_enable_table
     @source_schema = N'dbo', @source_name = N'orders',
     @role_name = N'cdc_reader',                   -- gating role for readers (or NULL = no gate)
     @capture_instance = N'dbo_orders',
     @supports_net_changes = 0;

-- RUNTIME READER (what rivet connects as — least privilege):
CREATE USER rivet_cdc FOR LOGIN rivet_cdc;
GRANT SELECT ON SCHEMA::cdc TO rivet_cdc;          -- read the change tables + functions
ALTER ROLE cdc_reader ADD MEMBER rivet_cdc;        -- if a gating role was set above
Notes:
- SQL Server Agent must be running. The capture job (default ~5 s scan cycle)
is what populates the change tables. If the Agent stops, the change tables
silently freeze and the transaction log can’t truncate — disk pressure. A
production reader should watch for a non-advancing
sys.fn_cdc_get_max_lsn(), not read “no rows” as “no changes”. - Edition gate: CDC is on Enterprise / Standard / Developer — not Express or Web. On Express, use Change Tracking instead (different, lighter, but only tells you which rows changed, not the data).
- Enabling CDC needs
sysadmin/db_owner; the runtime reader needs only theSELECTgrant above. - Retention: the cleanup job keeps ~3 days by default. If rivet is offline
longer than retention, the saved LSN falls below
sys.fn_cdc_get_min_lsn()and the read errors — fall back to a full re-snapshot.
Oracle — LogMiner (preview)
Oracle CDC reads the redo logs through LogMiner, which ships with every edition
(Free included) and needs no GoldenGate licence. rivet never sets
ENABLE_GOLDENGATE_REPLICATION (that one does need the licence).
-- ONCE, as SYSDBA in CDB$ROOT:
SHUTDOWN IMMEDIATE; STARTUP MOUNT; ALTER DATABASE ARCHIVELOG; ALTER DATABASE OPEN;
ALTER DATABASE ADD SUPPLEMENTAL LOG DATA;              -- minimal logging
CREATE USER c##rivetcdc IDENTIFIED BY … CONTAINER = ALL;
GRANT CREATE SESSION, SET CONTAINER, LOGMINING TO c##rivetcdc CONTAINER = ALL;
GRANT EXECUTE_CATALOG_ROLE TO c##rivetcdc CONTAINER = ALL;
GRANT SELECT ON v_$database TO c##rivetcdc CONTAINER = ALL;   -- and the same for
--   v_$archived_log, v_$log, v_$logfile, v_$logmnr_contents, v_$logmnr_logs, v_$transaction

-- PER CAPTURED TABLE (its owner or a DBA), in the pluggable database:
ALTER TABLE app.orders ADD SUPPLEMENTAL LOG DATA (ALL) COLUMNS;
GRANT SELECT ON app.orders TO c##rivetcdc;
Notes:
- The URL names the pluggable database (
oracle://c%23%23rivetcdc:…@host:1521/ORCLPDB1—#percent-encoded). rivet switches the session toCDB$ROOTto mine and keeps only that PDB’s changes. A non-CDB works without the switch. - ALL COLUMNS logging, not PRIMARY KEY. With key logging an UPDATE’s redo carries only the changed columns, so the change cannot represent the row; rivet refuses such a table and prints the statement above.
- Tables the preview refuses by name: a column of type LOB, LONG, XMLTYPE, JSON, INTERVAL, BOOLEAN, VECTOR, ROWID or an object type; a name over 30 bytes; and, before 23ai, an identity column (LogMiner ignores those tables entirely).
- Retention is the DBA’s, as with the binlog: nothing pins archived logs for rivet. If the checkpoint needs a log that was deleted, the run fails with a data-loss error (see Failure modes).
- Loading an Oracle stream with
rivet loadis not supported in the preview: amode: cdcOracle export under aload:block is refused when the config is read.
Reading from a replica (no primary access)
A common real-world constraint: you’re handed a database but only a read
replica, never the master. Rivet reads the log of whatever host you point
source.url at — it never needs the primary specifically. Whether a replica
can serve that log is an engine + replica-config question, not a rivet limitation:
| engine | from a replica? | what the replica needs | verified |
|---|---|---|---|
| MySQL | ✅ yes | log_bin = ON and log_replica_updates = ON (log_slave_updates pre-8.0.26) so the replica re-logs replicated changes into its own binlog — this is off by default: a replica applies changes but does not re-log them without it. Plus the REPLICATION SLAVE / REPLICATION CLIENT grant and a server_id distinct from both the primary and the replica. rivet refuses a replica with log_replica_updates = OFF at start, because its binlog holds none of the replicated changes. | live test + release gate: capture from a re-logging replica, refusal on one that does not |
| PostgreSQL | ✅ 16+, continuous mode only | Logical decoding on a standby is a PostgreSQL 16 feature. Run with cdc.until_current: false: the default bounded run refuses on a standby, because the position it bounds by (pg_current_wal_lsn()) does not exist during recovery. The first run creates the slot on the standby and waits until the primary logs a running-transactions snapshot (routine on a busy primary; SELECT pg_log_standby_snapshot() on the primary forces one). Set hot_standby_feedback = on on the standby so the primary keeps the rows the slot still needs. Below 16 a standby cannot host a logical slot — point rivet at the primary. | live test + release gate: continuous capture from a 16 standby, refusal of the bounded mode |
| SQL Server | ✅ yes (readable secondary) | CDC is enabled and captured on the primary (the capture job runs there); the cdc.* change tables replicate to an Always On secondary with SECONDARY_ROLE (ALLOW_CONNECTIONS = ALL), and rivet reads them there with plain SELECTs. | live test + release gate: a read-scale availability group (CLUSTER_TYPE = NONE), capture read from the secondary |
| MongoDB | ✅ yes (secondary) | Point source.url at a secondary with readPreference=secondary (and directConnection=true for one member); the change stream reads that member’s oplog. | live test + release gate: a two-member replica set, capture from the secondary |
MySQL caveat — the checkpoint is replica-local. Rivet resumes by binlog
{file, pos} (not GTID), and a replica’s binlog coordinates are its own, not the
primary’s. A checkpoint taken against one replica does not transfer to another
host, and rivet refuses one written by a different server (it records server_uuid).
If you fail over (to a different replica, or to the primary), delete the checkpoint so
CDC anchors on the new host first, then re-snapshot the table (mode: full).
SQL Server — the checkpoint follows a failover, and nothing else. An availability
group’s replicas share one log, so a checkpoint written on the primary resumes on a
secondary (verified live). The checkpoint records the database’s family_guid and
recovery_fork_guid, and rivet refuses to resume against a database whose
family_guid differs (another server’s database: its LSNs address a different log) or
whose recovery_fork_guid changed (a RESTORE rewound the log). Recover by deleting the
checkpoint so CDC re-anchors first, then re-snapshot the table with mode: full —
in the other order, the changes between the snapshot and the new anchor land in neither.
A checkpoint written before rivet recorded the identity resumes with a warning.
So the answer to “can I read the log from a slave?” is yes on all four engines, each
verified live: MySQL (with log_replica_updates = ON), PostgreSQL 16+ in continuous mode,
a SQL Server readable secondary, and a MongoDB secondary. Point source.url at the replica;
everything else (grants, mode: cdc, output) is identical to running against a primary.
Output shape
--output writes one row per change in the typed after-image (upsert) shape:
__op     __pos                              __seq  id   name    amount
insert   {"file":"binlog.000046","pos":681} 0      1    alice   100
update   {"file":"binlog.000046","pos":682} 0      1    alice   150
delete   {"file":"binlog.000046","pos":683} 0      2    bob     200
__op—insert/update/delete.__pos— the transaction’s commit position (the same value rivet checkpoints). Every change of one transaction shares it — it is not a total order over changes.__seq— the change’s ordinal within its transaction (0-based, log order), so(__pos, __seq)is a total order. It is the tiebreak when one transaction touches a key more than once and, being a column, survives the load into an (unordered) warehouse table (Parquet row order does not). See CDC change ordering. (MongoDB gives every event a distinct__pos, so its__seqis always0.)- the source columns, typed (resolved from the source schema), carrying the after-image for insert/update and the key (before-image) for delete.
Downstream applies it by primary key:
MERGE target t USING staged s ON t.id = s.id
WHEN MATCHED AND s.__op = 'delete' THEN DELETE
WHEN MATCHED                       THEN UPDATE SET t.* = s.*   -- overwrite all columns
WHEN NOT MATCHED AND s.__op <> 'delete' THEN INSERT (...);
With a full row image, which columns changed is irrelevant — the latest image
per key already contains every prior change, so dedup-by-key + overwrite is
correct. “Latest” is the highest (__pos, __seq) — the commit position, then the
intra-transaction ordinal (a transaction that updates one key twice shares
__pos, so __seq breaks the tie). This is why binlog_row_image = FULL matters.
Deduplicating by position, per engine
__pos granularity differs by engine, and the dedup recipe follows from it:
| engine | __pos | unique per event? |
|---|---|---|
| MySQL | {file, pos} — the transaction’s commit position | per statement under autocommit; all events of one multi-statement transaction share it |
| PostgreSQL | {lsn} — the transaction’s COMMIT LSN | all events of one transaction share it |
| SQL Server | {lsn} — __$start_lsn | per transaction (rows within share it) |
Two distinct problems:
- At-least-once re-delivery (a crashed run’s part re-read on resume): the
re-delivered event is byte-identical — same
__op,__pos, and image — soSELECT DISTINCTover the staged rows (or dedup on(pk, __pos, __op)) removes it exactly. - Latest-image-per-key (the MERGE): order by
(__pos, __seq)— the commit position, then the intra-transaction ordinal.__seqbreaks the tie when a transaction touches one key more than once (those changes share__pos); it is a column, so — unlike Parquet row order — it survives the load. See CDC change ordering.
-- DuckDB replay: newest surviving image per key.
WITH ev AS (
  SELECT *,
         upper(lpad(split_part(__pos->>'lsn', '/', 1), 8, '0')) ||
         upper(lpad(split_part(__pos->>'lsn', '/', 2), 8, '0')) AS lsn_key   -- PostgreSQL X/Y → sortable
  FROM read_parquet('…/sessions/cdc-*.parquet')
), latest AS (
  SELECT * FROM (
    SELECT *, row_number() OVER (
      PARTITION BY id
      ORDER BY lsn_key DESC, __seq DESC) AS rn        -- (__pos, __seq) = total order
    FROM ev)
  WHERE rn = 1
)
SELECT * FROM latest WHERE __op <> 'delete';
(MySQL: order by (file, pos) parsed from __pos, then __seq; SQL Server: the
fixed-width hex lsn string is already lexically ordered, then __seq.) In a
warehouse MERGE, apply the same window to the staged batch first, then merge the
winners by PK + __op.
Downstream loading
CDC output is the same typed Parquet the batch export writes (same
build_arrow_field pipeline), so the warehouse-loading recipes apply unchanged —
the engine-specific MERGE and the JSON-as-BYTES / naive-timestamp autoload
recovery are in
recipes/idempotent-warehouse-load.md
(BigQuery) and recipes/snowflake-load.md, keyed on
the PK + __op above.
Verified cross-engine on a CDC part: DuckDB reads json natively, ClickHouse
as String (JSONExtract* parses it), BigQuery as BYTES (PARSE_JSON after
SAFE_CONVERT_BYTES_TO_STRING); integers keep their width (INT32/INT64) and
timestamps their microseconds. The JSON text round-trips losslessly in all three — the
type that auto-detects differs, the data does not.
Part naming. Parts are run-stamped — cdc-<run_id>-000000.parquet — so a
scheduler re-running into the same prefix appends each cycle’s parts alongside
the previous cycle’s (nothing is overwritten). manifest.json / _SUCCESS
describe the latest run only; a glob reader over the prefix sees the union of
all cycles, which is the intended at-least-once stream — dedupe by PK + __op +
__pos downstream, and archive parts you have already loaded if you want the
prefix to stay small.
Without --output, rivet emits the same information as NDJSON (one JSON object
per change) to stdout.
Why CDC is gentle on the source
batch (SELECT) | CDC (log) | |
|---|---|---|
| touches | the table | the log only |
| locks / read snapshot | yes | no |
| buffer-pool eviction | yes (scans cold pages) | no |
| cost scales with | table size (re-scan) | change rate (deltas) |
| when it costs | actively, every run | latently (log retention / disk) |
The log is written anyway (WAL for durability, binlog for replication/PITR), so on MySQL/PostgreSQL CDC mostly reads what already exists — near-zero incremental OLTP cost. The one real CDC cost is disk via log retention if the consumer lags (PG slots pin WAL; MySQL keeps binlog until read). SQL Server is the exception: its Agent writes changes into change tables (extra write volume + storage), so CDC there trades read-contention for an ongoing write/storage overhead.
Failure modes & recovery
Every CDC run is bounded and resumable, and the durable sequence is
flush → checkpoint → ack: the resume position only advances after the part is
durably written. So on any failure — a dropped connection, a query error, a full
source disk — the run fails loudly (non-zero exit, with the per-engine setup
hint), the checkpoint/slot is not advanced, and the next run re-reads from
the last good position. Rivet never silently loses a change; the trade-off is
at-least-once, so a failed run’s already-uploaded parts can reappear — dedupe
downstream by primary key + __op (the output is the upsert / after-image shape).
A failed run leaves its durable parts in the destination but no manifest.json /
_SUCCESS — that pair marks a clean end, so a missing _SUCCESS is how you (and
rivet validate) tell a partial run from a complete one.
PostgreSQL — the slot fills / the source disk fills
A logical slot pins WAL until rivet advances it (confirmed_flush_lsn). The
behaviour depends on whether rivet is running:
- Running + advancing — each successful run reads the changes, writes them durably, then advances the slot, so PostgreSQL releases the WAL up to that point. The slot only ever holds the WAL since the last advance — it does not grow unbounded while rivet keeps the slot moving.
- Stopped (abandoned slot) — rivet does nothing (it isn’t running); the slot
keeps pinning WAL and the source disk fills. This is the number-one
PostgreSQL CDC foot-gun, and it is operator responsibility:
SELECT pg_drop_replication_slot('rivet_slot');when you stop capturing for good. - Source disk already full — run rivet (it reads WAL to advance the slot, which releases WAL and relieves the pressure) or drop the slot. If PostgreSQL is too degraded to answer, rivet’s query fails → the run fails → re-read next run.
Memory is O(largest transaction). The adapters buffer a whole
transaction until its COMMIT (parts never split a transaction — the resume
invariant; SQL Server buffers per poll batch). Measured on MySQL: ~1.4 KB of RSS
per buffered row (~14× a 100-byte payload): a 100k-row transaction drains at
~170 MB RSS, 300k at ~440 MB — linear. A transaction past the hard caps (5M
buffered rows or 2 GiB estimated bytes by default; RIVET_CDC_MAX_TX_ROWS /
RIVET_CDC_MAX_TX_BYTES override them) fails the run LOUDLY before it can OOM.
Opt-in RIVET_CDC_SPILL_DIR spills the adapter’s copy past the cap to disk
(PostgreSQL, MySQL, SQL Server; Oracle always refuses at the cap), but the sink
still holds the whole transaction, so it saves only ~11% of peak RSS — see
CDC failure modes. Run bulk backfills in batched
transactions, or through mode: full/initial: snapshot (the batch path streams).
DDL inside a capture window: safe where the engine names its columns, a
LOUD ERROR where it does not. PostgreSQL (wire text) and SQL Server (change
tables) always name every image column, so rivet maps values by NAME: a
DROP COLUMN or RENAME landing between runs captures correctly, and an
equal-arity DROP a + ADD c leaves c NULL for the older images rather than
filling it with a neighbour’s value (unless the dropped column sat at c’s
position, which looks exactly like a rename and is read as one). A column ADDED while a run is open is not in
that run’s schema, so its values for that run’s window are dropped — re-snapshot
the table after an ADD COLUMN if those values matter. MySQL’s binlog carries
names only when the server runs with binlog_row_metadata=FULL (8.0.1+ —
strongly recommended; the compose test stack sets it):
# my.cnf — makes mid-stream DDL safe for rivet CDC
binlog_row_metadata = FULL
Under the default MINIMAL the binlog is nameless and positional — expect
runs to FAIL with an explicit error (“an event … carries N column(s) but the
resolved schema has M”) whenever a DDL lands inside a capture window. That is
deliberate: mapping by position would put values into the wrong columns
silently, and a loud stop is the only safe behavior. Recover by
re-snapshotting the table (or resetting the checkpoint past the DDL), and set
binlog_row_metadata=FULL to retire this error class. DDL between runs is
always fine — each run resolves the schema fresh. A mid-window RENAME is safe
in both modes (same arity ⇒ positional fallback keeps the value). Same-arity
TYPE changes remain undetectable without schema history (roadmap) — run type
migrations and their backfills through a re-snapshot.
The value checksum runs on CDC too. The same always-on two-ended check the
batch export performs — an independent fold of the decoded cells vs a fold of
the built Arrow column — runs per column before every CDC part is written; a
mismatch fails the run naming the column, never writes the corrupted part.
Failure behaviour is also parity: a value unrepresentable in the declared
column (PostgreSQL 'NaN'::numeric in a Parquet decimal) fails loudly on both
paths, never a silent NULL.
For the full operational failure playbook — every symptom, what rivet does, how to recover, how to prevent — see cdc-failure-modes.md.
A vanished slot is a loud error, not a silent restart. When a resume checkpoint exists but the slot is gone (dropped by an operator, or invalidated and removed), rivet refuses to re-create it — a fresh slot would anchor at the current position and silently skip everything since the drop. The run fails with the re-snapshot hint; delete the checkpoint file only when you explicitly accept a fresh anchor.
Bound the blast radius: set max_slot_wal_keep_size (PG 13+). PostgreSQL then
invalidates the slot rather than fill the disk; rivet’s next run fails with a
slot-invalidated error and you re-snapshot. Monitor pg_replication_slots
(active, and restart_lsn vs the current LSN = how much WAL the slot is holding).
rivet doctorautomates this monitoring. For a config withmode: cdcexports, doctor probes the engine: PostgreSQL — the export’s slot (retained WAL, fails above 1 GiB) and any other inactive slot pinning WAL (the abandoned-slot foot-gun); MySQL —log_bin/binlog_format=ROW/binlog_row_image=FULL, and whether the checkpoint’s binlog file is still retained (a purged file is reported before the run fails with ERROR 1236); SQL Server — CDC enabled, the capture instance exists, the checkpoint is within retention, and the Agent service is running.
MySQL — the binlog was purged
If rivet is offline long enough that the saved binlog position is purged
(binlog_expire_logs_seconds / PURGE BINARY LOGS), the resume read fails with
MySQL ERROR 1236 (the requested binlog file is gone). The position is
unrecoverable — delete the checkpoint so CDC re-anchors first, then
re-snapshot (mode: full). Size binlog retention comfortably above your CDC cadence.
SQL Server — the checkpoint fell below retention
If the saved LSN falls below sys.fn_cdc_get_min_lsn() (the cleanup job — ~3
days by default — removed the changes after it), rivet fails loudly — “the
resume position is older than the change-table retention … re-snapshot” — rather
than resume from the new min and silently skip the gap. Delete the checkpoint so
CDC re-anchors first, then re-snapshot. Also watch for a non-advancing sys.fn_cdc_get_max_lsn():
that means the Agent capture job stopped, so the change tables are frozen — read
“no rows” as “the job is down”, not “no changes”.
Oracle — the archived logs were deleted
If the checkpoint needs redo older than the oldest archived log still listed (RMAN
DELETE INPUT, a retention policy), or a log sequence is missing in between, the run
fails with “… LOST to this stream” instead of mining from whatever remains. Delete
the checkpoint so the next run anchors first, then re-snapshot the table.
A checkpoint written against another database (a different DBID, a RESETLOGS
since, or another pluggable database) is refused the same way: an SCN means nothing
outside the database that issued it.
Recovery, in one line
Re-run to resume from the last checkpoint (the common case). If the run reports the
position is unrecoverable (PostgreSQL slot invalidated, MySQL binlog purged, SQL
Server retention exceeded), restart CDC from a new checkpoint first, then
re-snapshot the table with mode: full — the only safe recovery once the source log
no longer covers the gap. The order matters: the new anchor must exist before the
snapshot reads, so the stream overlaps the snapshot (duplicates, which the load
deduplicates) instead of leaving the changes in between in neither.
Limitations (current)
Typed output (real Timestamp/Date32/Decimal128), commit-boundary
checkpointing, cloud destinations + manifest.json/_SUCCESS, and the
config-driven rivet run path with a recorded run are all in place for all three
engines. What remains:
- Continuous capture is bounded-poll-and-exit by default on every engine (they
drain their backlog and stop). The supported continuous model is a scheduler
running the default bounded
rivet cdc(orrivet runwithcdc.until_current: true, now the default) on an interval, each run resuming from the checkpoint. For an unbounded run, pass--stream(config:cdc.until_current: false; the config-drivenrivet runpath logs an engine-specific warning), because only MySQL (the binlog dump blocks) and MongoDB (the change stream blocks awaiting events, ending only if the stream is invalidated or closed) genuinely stay up as daemons; PostgreSQL and SQL Server still exit on catch-up (one unbounded pass — run it under a supervisor that restarts it). The bounded run remains the intended model. - Schema drift: the sink schema is frozen at the first flush — a column added mid-run is not picked up until the next run re-resolves the table, and its values captured in the meantime are dropped (the events are still acked) — re-snapshot the table to recover them.
- No lag metric: the run records rows / files / bytes / duration / status, but not replication lag (“how far behind the source is”) — the next observability step.
- Pre-image completeness depends on the source config: full UPDATE/DELETE
before-images need
binlog_row_image=FULL(MySQL) /REPLICA IDENTITY FULL(PostgreSQL); otherwise only key columns are carried. - Type parity with the batch export is total: every Rivet-mapped type —
including PostgreSQL arrays (real
Listcolumns, inner NULLs preserved) andNUMERIC/DECIMALabove precision 38 (Decimal256) — is byte-identical to the batch export, enforced per engine by the live*_full_type_matrix_matches_batchtests (ArrayData equality).
CDC failure modes & recovery
What rivet does when a CDC run hits an operational failure, what you do to recover, and how to prevent it. Two guarantees frame every row:
- Loud stop, never a silent gap. When the source can no longer supply the changes since the checkpoint (a dropped/invalidated slot, purged binlog, aged-out change table), rivet fails the run with a specific error and a recovery hint — it never silently re-anchors at “now” and skips the gap. The cost is a re-snapshot; the benefit is you always know the numbers are right.
- At-least-once, so a crash or outage is a delay, not a loss. rivet reads,
durably writes, then acks (
peek → flush → ack). A crash between the write and the checkpoint re-reads the un-acked changes on the next run. Duplicates are the downstream MERGE’s job; loss does not happen.
rivet doctor -c rivet.yaml is the preventive layer. For mode: cdc exports
it probes the engine and turns most of the rows below from an incident into a
warning before the run — run it in your scheduler’s pre-flight step.
The table
| Symptom | What rivet does | Operator recovery | Prevention |
|---|---|---|---|
| PostgreSQL slot dropped or invalidated (with a resume checkpoint present) | Fails loud — refuses to re-create the slot (a fresh slot would anchor at current and skip everything since the drop). Error names the re-snapshot path. | Re-snapshot the table (initial: snapshot → delete the checkpoint, clear the export’s cdc_snapshot row in the state DB, AND delete the destination’s snapshot/_SUCCESS marker — the two done-signals are OR-ed, so leaving either one in place skips the snapshot). If a warehouse load consumes this stream, also truncate its <table>__changes table before the next load — a re-snapshot row carries NULL __pos and loses the dedup to every already-loaded change row, so without the truncate the current-state view silently serves pre-gap values for exactly the rows the re-snapshot fixed. Then resume. The WAL since the drop is gone — no tool can recover it. | rivet doctor flags a slot holding > 1 GiB retained WAL; set max_slot_wal_keep_size (PG 13+) so PG invalidates the slot instead of filling the disk. |
| PostgreSQL slot filling the source disk (consumer stopped / cadence too slow) | The slot pins WAL until consumed — this is PostgreSQL behavior; rivet does not fill it, but an abandoned slot will. | Resume draining (the slot advances on ack), or drop the slot + re-snapshot if it is beyond retention. | rivet doctor fails the slot check above 1 GiB retained WAL; monitor pg_replication_slots.restart_lsn vs current LSN; cap with max_slot_wal_keep_size. |
| An abandoned other slot pinning WAL (left by a previous tool) | Not rivet’s slot, but it fills the same disk — the #1 CDC foot-gun. | SELECT pg_drop_replication_slot('slot_name') for the dead slot. | rivet doctor reports every inactive slot pinning WAL, not just the export’s own. |
| MySQL binlog purged (retention shorter than the drain cadence) | The next run fails with ERROR 1236 (requested position no longer in the binlog). Loud, not silent. | Delete the checkpoint so CDC re-anchors first, then re-snapshot (mode: full). | Size binlog_expire_logs_seconds above your CDC cadence; rivet doctor predicts it — flags a checkpoint already below retention before the run fails. |
SQL Server change table aged out (checkpoint LSN below fn_cdc_get_min_lsn) | Loud stop — the saved LSN is below the capture instance’s minimum retained LSN. | Delete the checkpoint so CDC re-anchors first, then re-snapshot. | Size the CDC retention (sys.sp_cdc_change_job @retention) above your cadence; rivet doctor checks the checkpoint stays above fn_cdc_get_min_lsn. |
| SQL Server Agent stopped | Capture freezes — no new change-table rows are produced; a run drains what exists and then sees nothing new. | Start SQL Server Agent; capture resumes and the next run catches up. | rivet doctor reports the Agent service state; a stopped Agent is flagged. |
| Corrupt or unreadable checkpoint file | Fails loud on garbage / truncated / empty checkpoints (invalid JSON — a serde error surfaces; never a silent re-anchor). A wrong-engine checkpoint that is still valid JSON passes the shared loader (the position is stored as an opaque JSON blob) and only fails when the engine interprets it — don’t rely on that as a guard. | Restore the checkpoint from backup, or delete it (the next run anchors fresh) and then re-snapshot. | Keep the checkpoint on durable, non-ephemeral storage; back it up alongside the destination. |
| Missing checkpoint parent directory (first run) | The checkpoint save creates parent directories — the scaffolded ./cdc/TABLE.ckpt no longer fails a fresh quickstart (fixed in 0.16.5). | None — handled. | — |
| DDL inside a capture window | PostgreSQL & SQL Server map images by column name — a DROP COLUMN or rename between runs captures correctly, and an equal-arity DROP+ADD leaves the new column NULL for older images (unless the dropped column sat at the new one’s position, which is read as a rename). A column added while a run is open is not in that run’s schema: its values for that run are dropped and acked (re-snapshot to recover them). MySQL under binlog_row_metadata=FULL behaves the same; under the default MINIMAL the binlog is nameless and rivet fails loud rather than misalign values. | Under MySQL MINIMAL: re-snapshot past the DDL, or reset the checkpoint. Same-arity type changes (undetectable without schema history) — re-snapshot through the migration. | Set binlog_row_metadata=FULL (MySQL 8.0.1+); run type-changing migrations + their backfills through a re-snapshot. |
| A single transaction larger than memory | The MySQL adapter buffers a whole transaction until its COMMIT (never splits it — the resume invariant); memory is O(largest transaction), ~1.4 KB RSS per buffered row (100k rows ≈ 170 MB). Hard per-transaction caps bail loudly before OOM: 5M buffered rows and 2 GiB estimated bytes by default (RIVET_CDC_MAX_TX_ROWS / RIVET_CDC_MAX_TX_BYTES override them — raise only when a transaction this large is genuinely expected). | Split bulk backfills into batched transactions, or run them through mode: full / initial: snapshot (the batch path streams). | Do bulk operations in batches. Opt-in spilling exists: set RIVET_CDC_SPILL_DIR (a directory — relative forms resolve against the config’s directory — or 1 to place it beside the checkpoint, falling back to <config dir>/.rivet/spill when the export has none) and a transaction past the cap spills its tail to disk instead of failing — the transaction is still delivered whole. (PostgreSQL, MySQL and SQL Server; Oracle ignores the variable and always refuses at the cap.) Note the measured limit: this moves the adapter’s copy only (~11% of peak RSS on a 100k-row transaction); the sink still buffers a whole transaction, so the caps stay the honest guard and spilling off stays the default. |
| Destination outage mid-drain (S3/GCS/Azure unreachable) | No loss — peek → flush → ack: an un-flushed part is not acked, so the next run re-reads those changes. The run fails loud on the write error. | Restore the destination and re-run; the un-acked changes replay. | Alert on run failure; the at-least-once contract makes this a delay, not a loss. |
Process crash mid-drain (kill -9, OOM, node reboot) | No loss — the checkpoint advances only after parts are durably committed and acked; a crash re-reads the un-acked tail. Verified: kill mid-5k-drain → resume captures all 5,000. | Re-run; resume continues from the last committed position. | — |
| Destination disk full (ENOSPC) | Fails loud naming the full disk; the checkpoint does not move. | Free space or point the export at a roomy destination; the full backlog is captured after healing (verified). | Monitor destination capacity; a full disk is a delay, not a loss. |
REPLICATION grant revoked mid-stream | Fails loud pointing at the grants; the checkpoint does not move. | Restore the grant; the next run resumes with zero loss. | Alert on run failure; the checkpoint freeze makes this recoverable. |
| A batch and a CDC export share one destination prefix | Fails loud before the first part lands — refuses to overwrite the other shape’s manifest.json (which would orphan its parts from rivet validate). | Give each export its own prefix; the CDC scaffold uses exports/TABLE/cdc/. | Keep one shape per prefix (the scaffold does this by default). |
MySQL 8.4 (SHOW MASTER STATUS removed) | Handled transparently — rivet uses SHOW BINARY LOG STATUS (8.2+) with a legacy fallback. | None. | — |
The shape of every recovery
Two recovery paths cover the table:
- Re-snapshot — when the source no longer has the changes since the
checkpoint (slot invalidated, binlog purged, change table aged out, a
same-arity type change). Take a fresh consistent baseline
(
initial: snapshotormode: full), then resume CDC from the new anchor. The gap is not recoverable from the log — the honest fix is a new baseline. - Re-run — when the changes are still in the source but a write or process failed (destination outage, crash, ENOSPC, revoked grant). The at-least-once contract replays the un-acked tail; no baseline needed.
The rule of thumb: source-side loss ⇒ re-snapshot; sink-side or process failure ⇒ re-run. rivet always fails loud enough to tell you which.
CDC change ordering: __pos is not a total order — add __seq
Shipped in 0.17.0 — this page is the design rationale, not a proposal.
__seqis a live CDC output column; the current reference is reference/cdc.md § Output shape. This page records why(__pos, __seq)is the total change order. The per-engine population below covers the three SQL engines; MongoDB (added later) gives every change-stream event a distinct__pos, so its__seqis always0.
Problem (verified live on all three engines)
The CDC output columns are __op, __pos, and the after-image. __pos is the
commit position of the change’s transaction:
| engine | __pos | source |
|---|---|---|
| MySQL | {"file":"binlog.000047","pos":11721549} | transaction commit pos |
| Postgres | {"lsn":"3D/485795A0"} | peek_changes commit LSN |
| SQLServer | {"lsn":"0000002d000000d80194"} | __$start_lsn (txn LSN) |
Commit position is exactly right for resume/checkpoint (all engines resume
at a commit boundary). But it is not a total order over changes: every
change in one transaction shares it. Proven — 8000 UPDATEs of one PK in a
single transaction produced COUNT(DISTINCT __pos) = 1 on all three engines.
Downstream, the current-state dedup view
ROW_NUMBER() OVER (PARTITION BY <pk> ORDER BY <parsed __pos> DESC) = 1
has 8000 tied rows, so ROW_NUMBER picks an arbitrary one. Live result: the
view returned counter = 1 for a row whose committed value was 8000 —
silently wrong current state. This bites any transaction that touches the
same PK more than once (triggers, ORMs, read-modify-write loops, batch
upserts). The row order inside the Parquet part is the change order, but that
order is lost the moment the log is loaded into an (unordered) warehouse table.
Design: emit a per-change __seq (intra-transaction ordinal)
Add a __seq column to the CDC output: the change’s ordinal within its
commit group. Keep __pos unchanged (still the commit position, still what
resume uses). The pair (__pos, __seq) is then a total order that:
- matches log order (commit order across transactions, emission order within),
- is deterministic and log-derived, so a re-emitted change (at-least-once,
crash-before-ack) carries the same
(__pos, __seq)— the dedup tiebreak is a true tie between identical rows, so either wins and the value is right, - survives the load (it is a column, not row order).
Dedup view becomes:
ROW_NUMBER() OVER (PARTITION BY <pk> ORDER BY <parsed __pos> DESC, __seq DESC) = 1
Per-engine population
__seq is a 0-based counter over the changes of one commit, in log order:
- SQL Server — use the native
__$seqvalfrom the change table (it already orders operations within__$start_lsn).__seq = dense_rank of __$seqval within __$start_lsn(or__$seqvalrendered as a comparable fixed-width value). No invention — the engine hands us the order. - PostgreSQL — logical decoding yields the transaction’s changes in order;
assign
0,1,2,…, resetting when__pos(commit LSN) advances. - MySQL — binlog row events arrive in order within the transaction; assign
0,1,2,…, resetting at each commit__pos.
Because the reset key is __pos (the commit position), the ordinal is
reproducible from the log alone on every run — the at-least-once property above
holds without any persisted counter.
Why not alternatives
- A single global run counter (0,1,2,… over the whole run) breaks across
runs: run 2 resets to 0, so a newer change gets a smaller counter than an
older one from run 1.
(__pos, __seq)avoids this by resetting per commit, keeping the ordinal log-derived. - Folding
__seqinto__pos(making__posdistinct per change) would break resume, which must stop on a commit boundary, not mid-transaction. - Relying on Parquet row order — lost on load into a warehouse table.
Blast radius
- CDC sink schema gains one column (
__seq INT64), all engines. - One capture-agnostic path populates it — the shared
TxnSeqper-commit ordinal, stamped as the stream is consumed on every engine (SQL Server’s__$seqvalonly orders the change-table read; MySQL/Postgres from a per-commit ordinal). validate.rscan additionally assert(__pos, __seq)is strictly increasing in part→row order (today it only checks__posnon-decreasing).- The
rivet-prodedup view template orders by(__pos, __seq). - Regression test per engine: N changes to one PK in one transaction → the dedup view returns the last change’s value, not an arbitrary one.
Loading rivet CDC into BigQuery — free ingest, cheap dedup
rivet load on a mode: cdc config does this end to end — it appends the change
log for free and builds a current-state dedup view. This note explains the model
it implements (verified against BigQuery docs + live behavior): why CDC ingest
and dedup to current state can be free, the way the batch loader is free. The
one command is at the bottom.
What rivet CDC produces
Per-change typed Parquet: the after-image columns plus __op
(insert/update/delete) and __pos (monotonic log position), append-only,
at-least-once (a re-run can re-emit a change).
The one hard fact
- Loading raw changes is FREE — it is an ordinary
LOAD DATA(native schema, partitioned, clustered), identical to the batch path. - Deduplication to current state is inherently cross-row (latest row per
primary key + drop deletes). Any materialization of that state is a query
(
MERGE/CREATE TABLE AS SELECT) and is billed. There is no free lunch for collapsing a change log into current state.
So “free CDC + dedup” is really: keep the pipeline free, and defer/limit the dedup cost.
Three options
| Option | Ingest | Dedup / current state | Cost | Fit |
|---|---|---|---|---|
Native CDC (_CHANGE_TYPE=UPSERT/DELETE, Storage Write API + NOT ENFORCED PK) | streaming | automatic, by ingest order (or _CHANGE_SEQUENCE_NUMBER) | billed (streaming ingest ~$0.025–0.05/GB); the table forbids MERGE/DML | real-time; not a batch-file model |
| Batch MERGE | free LOAD DATA → staging | MERGE staging → target (upsert by PK, delete on __op) | billed per merge (scans staging + touched partitions) | standard; materializes state each run |
| Append + view ✅ | free LOAD DATA → <table>__changes | a view dedups at read time | free to ingest + define; billed only when current state is read | best fit for rivet’s free batched loader |
Recommended: append the log (free) + a dedup view (free)
-
Ingest (free).
LOAD DATA INTO <table>__changes (…native schema… , __op STRING, __pos STRING)— the same free, native-schema, daily-batched load the batch path uses (__posis the JSON log-coordinate string, see the view below). Partition__changesby change date, cluster by the primary key so the view below prunes efficiently. -
Current state (free to define). A view collapses the log. Note
__posis a JSON string of the log coordinate (verified live), NOT an integer — MySQL renders{"file":"binlog.000047","pos":10840633}, PostgreSQL/SQL Server a{"lsn":…}. So the ordering must parse it; sorting the raw string is wrong ("9">"10"lexically). The parse is therefore per-engine:-- MySQL (binlog file + position): CREATE OR REPLACE VIEW `<table>` AS SELECT * EXCEPT (__op, __pos, __seq, __rn), (__op = 'delete') AS __is_deleted FROM ( SELECT *, ROW_NUMBER() OVER ( PARTITION BY <pk> ORDER BY JSON_VALUE(__pos,'$.file') DESC, CAST(JSON_VALUE(__pos,'$.pos') AS INT64) DESC, __seq DESC ) AS __rn FROM `<table>__changes` ) WHERE __rn = 1; -- PostgreSQL / SQL Server: ORDER BY JSON_VALUE(__pos,'$.lsn') … -- Snowflake: PARSE_JSON(__pos):file … and SELECT * EXCLUDE (…)One expression does the dedup work: at-least-once dedup (a re-emitted change has the same
(__pos,__seq)and loses the tiebreak) and latest-per-PK collapse. Soft delete: the latest change is kept unconditionally, and its__opis projected into a boolean__is_deletedcolumn — a deleted row survives as a tombstone (last-known values +__is_deleted = true) instead of silently vanishing; live state isWHERE NOT __is_deleted. Verified live: three changes (insert/update/delete) loaded twice (10 rows) collapse to 3 distinct-PK rows — the deleted PK present with__is_deleted = true, the other twofalse(2 live rows).
Ingest + view are both free. Reading <table> scans __changes (billed),
but clustering on <pk> keeps it cheap; if current state is read hot, add an
optional daily compaction (CREATE OR REPLACE TABLE <table>__snapshot AS SELECT * FROM <table>) — one billed scan per day, not per read. This is the
classic log + periodic compaction.
The base-and-buffer layout (backfill: streams) and rivet compact
A stream whose baseline comes from cdc.backfill: does NOT use the view above.
Its baseline legs overwrite a physical base table <table> — the source
columns plus one service column, __is_deleted BOOL (written as false inside
the baseline Parquet, so no NULL ever appears) — and the stream’s runs append
into <table>__changes, a per-cycle buffer without a partition. The cycle is
rivet run     -c cfg.yaml   # anchor once, baseline once, then only the changes
rivet load    -c cfg.yaml   # baseline → <table> (batched, staging + CLONE); changes → <table>__changes
rivet compact -c cfg.yaml   # MERGE <table>__changes into <table>; DROP the buffer
compact is one scripted job per table: the latest change per key (the
same __pos order the view uses) is upserted; a delete flags the base row
(__is_deleted = TRUE, last values kept — the warehouse deletes nothing) and a
later insert un-flags it. For a day-partitioned base (init’s default) the script
collects the buffer’s distinct days into a variable and every MERGE filters
both sides with DATE(col) IN UNNEST(days) — measured: 172 bytes read against
48 KB for a MIN..MAX range on the same buffer, i.e. exactly the touched
partitions; more than 4,000 days merge in chunks of 4,000 inside the same
script. Then the script drops the buffer and the next load creates it again
from its run’s spec. Other partition keys (hour, month, year, integer ranges)
keep a constant MIN..MAX range per window in separate jobs — the truncation
forms did not prune when measured. An empty buffer is just dropped.
What a cycle bills: BigQuery charges every statement that reads a table at
least 10 MB per table, so a compaction with changes bills a 30 MB floor (the
probe, and the MERGE over two tables); one without changes bills nothing. The
load side is free (CREATE, LOAD DATA). The script’s child statements
appear in INFORMATION_SCHEMA.JOBS under parent_job_id with the same labels.
Consumers read <table> directly, WHERE NOT __is_deleted for live rows. The
buffer holds no history — __is_deleted in the base is the record that a row
was deleted. BigQuery only in this release; Snowflake keeps the view layout.
Every billed step carries its own label
The whole point of the loader’s job labels (managed_by:rivet /
rivet_op:<op> / rivet_table:<table> / rivet_run:<load run id>) is that
you can price each table’s update, per operation. There are two operations:
rivet_op:load— everythingrivet loadruns for a table: the freeLOAD DATAjobs (one per batch of at most 4,000 partitions), theCOUNT(*)gate, the table DDL, the stagingCLONEof a batched whole-table load, the view;rivet_op:merge— everythingrivet compactruns for a table (the billedMERGEand its partition-range probe).
rivet_table is the base table’s short name for both the table and its
__changes, so GROUP BY op, tbl answers “what does keeping this table current
cost” in one row per table per operation:
SELECT
  (SELECT value FROM UNNEST(labels) WHERE key='rivet_op')    AS op,      -- load | merge
  (SELECT value FROM UNNEST(labels) WHERE key='rivet_table') AS tbl,
  COUNT(*) AS jobs, SUM(total_bytes_billed) AS bytes_billed
FROM `region-us`.INFORMATION_SCHEMA.JOBS
WHERE EXISTS (SELECT 1 FROM UNNEST(labels) WHERE key='managed_by' AND value='rivet')
GROUP BY op, tbl ORDER BY bytes_billed DESC;
Every rivet-driven job passes through one labelled seam (run_sql(sql, op, table)), so nothing rivet runs is unlabelled — only jobs you run yourself need
labels of your own.
The one command: rivet load
rivet load -c cfg.yaml — where the export is mode: cdc and the config carries
a top-level load: block with target: bigquery — does both steps
automatically. The view’s key is the source primary key rivet run recorded
(pk: auto, the default); pk: [..] overrides it and is required only when
none was recorded (a query: export, a table without a primary key):
- free
LOAD DATAof the CDC Parquet into<table>__changes(the same native-schema batched loader, with__op/__pos/__seqin the schema); CREATE OR REPLACE VIEW <table>— the exact dedup view above.
exports:
  - name: orders
    table: orders
    mode: cdc
    cdc: { until_current: true, checkpoint: /var/lib/rivet/orders.ckpt }
    destination: { type: gcs, bucket: my-bucket, prefix: cdc/orders/ }
load:
  target: bigquery      # or: snowflake (+ connection/warehouse/database/schema/storage_integration)
  project: my-proj
  dataset: analytics
  # pk: [id]            # the view's PARTITION BY; default: the source primary key
  cleanup_source: true
Both steps are free. The count gate (summed manifest rows == warehouse
COUNT(*)) and source cleanup work exactly as in the batch path. There is no
--cdc flag — the mode comes from the export’s mode: cdc; one config drives
both rivet run (extract) and rivet load.
Live-verified end to end: this flow builds the dedup view shown above, with two
refinements over the sketch — on MySQL the binlog file is parsed numerically
(CAST(REGEXP_EXTRACT(JSON_VALUE(__pos,'$.file'), r'[0-9]+$') AS INT64) then
CAST(JSON_VALUE(__pos,'$.pos') AS INT64)), and the delete flag is
COALESCE(__op = 'delete', FALSE) AS __is_deleted so snapshot-backfill rows
(NULL __op) stay live — and a deleted PK survives as __is_deleted = true
rather than vanishing. See the matrix cells cdc_backfill_snapshot_{mysql,pg,mongo}
and the Snowflake parity mongo_cdc_delete_flag_snowflake.
A whole schema: one stream, one warehouse table per source table
rivet init --mode cdc over a whole schema emits ONE multiplex export — every
table through one change stream (one PostgreSQL slot / one MySQL binlog
connection), rather than one export and one slot per table:
exports:
  - name: cdc
    tables: [orders, customers, line_items]
    mode: cdc
    cdc: { initial: snapshot, until_current: true, checkpoint: /var/lib/rivet/cdc.ckpt }
    destination: { type: gcs, bucket: my-bucket, prefix: cdc/ }
load:
  target: bigquery
  project: my-proj
  dataset: analytics
Loads are batched by partition span. BigQuery writes at most 4,000
partitions per job. Before any job, rivet load reads the partition column’s
range from every Parquet footer and packs the files, in order of their lowest
value, into jobs whose combined span fits — so a keyset export over an
autoincrement key (whose files are date-local because id grows with time)
loads eleven years of daily partitions in three or four jobs, never coarsened
to month. A whole-table (OVERWRITE) load that needs several jobs fills a
<table>__staging table and swaps it in with one zero-copy CLONE. The one
shape nothing splits is a single file wider than 4,000 partitions (dates
uncorrelated with the read key): that is refused before any job, naming the
file and the granularity that fits.
The capture fans each table out under <prefix>/<table>/ (its own
manifest.json + _SUCCESS, with initial: snapshot nested a level below as
<prefix>/<table>/snapshot/), and rivet load follows that layout: one
<table>__changes + one dedup view per SOURCE table, each loaded from its own
sub-prefix only. Each table is keyed on its own recorded primary key; the rest of
the load: block is shared by every table of the stream unless the export’s
load: carries tables: { orders: { partition: { column: created_at, granularity: day } }, customers: { partition: none } } — one block per captured
table, layered over the export’s and the top-level load:. With
cdc: { backfill: auto, … } in place of initial: snapshot, each table’s
baseline is read by the batch export that names it (keyset, chunked, with its
columns:) into the same <prefix>/<table>/snapshot/, so the load is unchanged
(rivet init --mode cdc scaffolds that shape on MySQL and PostgreSQL); rivet check --target bigquery prints one resolver document
per table (Export: cdc/orders), so you see each table’s native schema before
loading it. Live-verified against BigQuery over a 3-table PostgreSQL stream
(#252).
Bottom line: yes — rivet can ingest CDC into BigQuery and expose a deduplicated current state entirely for free (append + view). The only unavoidable cost is materializing current state, which we defer to read time (a view) or amortize (daily compaction) — never on the ingest path.
The full CDC cycle, step by step — every engine
The operator’s sequence for a mode: cdc export from nothing to a warehouse
table that follows the source: preflight → anchor + baseline → load → changes →
load → an interruption on the CDC leg → load → an idle cycle. Each step names
what to run and what must be true afterwards, checked by two readers that share
nothing with rivet: the source itself (COUNT(*)) and the warehouse (bq).
The same sequence runs unattended as
full_cdc_cycle_{mysql,postgres,mssql,mongo} in
tests/live/live_cdc_full_cycle.rs — one body, four engines, through the Rig.
0. Prerequisites per engine
| engine | what the log needs | anchor model | cdc.checkpoint: |
|---|---|---|---|
| MySQL | binlog_format=ROW, binlog_row_image=FULL, a user with REPLICATION SLAVE, REPLICATION CLIENT; on RDS/Aurora: automated backups ON (retention > 0, else log_bin=0, ERROR 1381) and CALL mysql.rds_set_configuration('binlog retention hours', N) (ERROR 1236 otherwise) | client-side file — {file, pos, server_uuid, gtid_executed} | required for any mode: cdc |
| PostgreSQL | wal_level=logical, max_replication_slots ≥ 1, a role with REPLICATION | server-side slot | not needed (the slot is the anchor) |
| SQL Server | SQL Server Agent running, sys.sp_cdc_enable_db, sys.sp_cdc_enable_table per table (one cdc: export per table — tables: is refused) | from-LSN floored at fn_cdc_get_min_lsn | required for a baseline |
| MongoDB | a replica set (change streams), directConnection if port-mapped | resume token | required for any mode: cdc |
rivet doctor --config cfg.yaml checks the log-side state it can read (PostgreSQL: the slot;
MySQL: binlog mode and whether the checkpoint is still retained; SQL Server: the Agent and
retention; MongoDB: the replica set) and prints the fix per line. Grants, wal_level,
max_replication_slots and RDS retention are not probed — check them by hand.
1. The config: one CDC export, one recipe, one load:
source: { type: mysql, url_env: SOURCE_URL }
exports:
  - name: orders                       # the RECIPE: how to read the table
    table: orders
    mode: chunked
    chunk_by_key: id
    chunk_size: 250000
    chunk_checkpoint: true
    parallel: 4
    destination: { type: gcs, bucket: my-bucket, prefix: "exports/orders/" }

  - name: stream                       # the CDC export
    tables: [orders]
    mode: cdc
    cdc:
      checkpoint: ./cdc/stream.ckpt
      backfill: auto                   # baseline through the recipe, after the anchor
      until_current: true
    destination: { type: gcs, bucket: my-bucket, prefix: "exports/stream/" }

load: { target: bigquery, project: my-proj, dataset: my_ds, pk: auto }
rivet init --source-env SOURCE_URL --mode cdcover two or more tables (MySQL, PostgreSQLpublic) scaffolds exactly this shape: one recipe per table — keyset where the table has a single-column keysettable key, range orfullotherwise — and onetables:stream withbackfill: auto. A single table, SQL Server, MongoDB or a non-publicschema get a per-table capture-only stream instead (addinitial: snapshotor a recipe +backfill:yourself). Add theload:block and run.- A stream over several tables rarely shares one partition column or one key.
Put the per-table layer on the stream’s own
load:block:load: { partition: { column: created_at, granularity: day }, tables: { customers: { partition: none }, line_items: { pk: [id, line_no] } } }— each table’s block overrides the export’s, which overrides the top-levelload:. ordersis a read recipe: a whole-configrivet run(andrivet apply) skips it — atwarn— and the CDC export runs it after the anchor into its ownexports/stream/orders/snapshot/.rivet run -e ordersstill exports it alone. It is never a load target.- Only a
fullorchunkedrecipe is admitted; anincrementalone reads a slice and is refused at config load, before any anchor exists. - A column typed on the recipe (
columns:) reaches the baseline, the stream and the recorded load spec alike — one type per column in one__changes.
2. Preflight
rivet check  --config cfg.yaml     # grades the CDC export as a log reader, not a scan
rivet doctor --config cfg.yaml     # binlog/slot/Agent/replica-set readiness, per line
rivet plan   --config cfg.yaml     # plans the batch exports; skips the stream and the recipe, saying so
Expect: no DEGRADED/UNSAFE on the CDC export; every doctor line green. plan
skips the stream and the recipe, saying so — on the §1 config that leaves nothing
to plan and it exits non-zero with “nothing to plan” (expected — not a fault in
the config); with a plain batch export alongside it plans that one and exits 0.
3. Run 1 — anchor, then baseline — then load 1
rivet run  --config cfg.yaml
rivet load --config cfg.yaml
Order inside the run: anchor first (checkpoint pinned / slot created), then the baseline read through the recipe, then the drain of whatever changed during the baseline. A change landing mid-baseline is therefore in both — a duplicate, which the dedup view absorbs — never in neither.
Check:
-- source
SELECT COUNT(*) FROM orders;
-- warehouse (bq query --use_legacy_sql=false)
SELECT COUNT(*) FROM `my-proj.my_ds.orders`;
Both equal. The warehouse object is a plain table after run 1.
If the baseline is interrupted (a kill, a statement timeout on one chunk), just
run again: a chunk_checkpoint: true recipe resumes its own leg on the next
plain rivet run — no --export <leg> --resume, no synthesized names.
4. Changes → run 2 → load 2
Insert, update and delete a few rows at the source, then:
rivet run  --config cfg.yaml
rivet load --config cfg.yaml
Check:
-
With a
backfill:recipe the layout is base + buffer (load.layout: base_buffer, the default for this shape):ordersis a physical table holding the baseline, and this cycle’s changes landed in the bufferorders__changes— exactly the number of changed rows (an update is one row, a delete is one row with__op = 'delete'). The base does not move until you compact:rivet compact --config cfg.yamlCOMPACT OKmerges the latest change per key intoorders, flags a deleted key with__is_deleted = TRUE(its last values kept — the disappearance is data too) and drops the buffer. Live state isWHERE NOT __is_deleted:SELECT COUNT(*), COUNT(DISTINCT id) FROM `my-proj.my_ds.orders` WHERE NOT __is_deleted;Both equal the source’s
COUNT(*);orders__changesis gone until the next load. -
Under
load.layout: log_view(a capture-only stream, or written explicitly) there is no compaction:ordersis a view overorders__changes, which keeps every change, and the sameWHERE NOT __is_deletedreads live state. -
A second
rivet loadwith no new run appends nothing (the load ledger); a secondrivet compactfinds no buffer and says so. -
On ClickHouse (preview) there is no compaction either: the change log is a
ReplacingMergeTreethat collapses versions per key by itself, and the view reads it withFINAL. The cycle isrivet run+rivet load; see the ClickHouse recipe.
A load never merges: the baseline OVERWRITEs the base, changes LOAD DATA INTO
the buffer (or the changelog); only rivet compact rewrites base rows.
5. An interruption ON THE CDC LEG → run 3 → load 3
Make more changes, start rivet run, and kill it while it is draining (kill -9; the automated scenario injects RIVET_TEST_PANIC_AT=cdc_after_flush_before_ack
and cdc_after_ack). Then simply:
rivet run     --config cfg.yaml
rivet load    --config cfg.yaml
rivet compact --config cfg.yaml   # base + buffer; a `log_view` stream skips this
Check: live state (WHERE NOT __is_deleted) equals the source, one row per key.
orders__changes may hold a change twice if the kill landed after the part was
flushed but before the checkpoint advanced — that is at-least-once, and compact
(or the view, under log_view) collapses it. What must never happen is a change
in neither.
6. Idle cycle
rivet run  --config cfg.yaml   # nothing changed
rivet load --config cfg.yaml   # "up to date"
Check: no orders__changes buffer was created (under log_view, the changelog
did not grow); live state still equals the source.
Recovery orders that matter
- Log gone (slot invalidated, binlog purged — ERROR 1236, MSSQL below
retention): re-baseline in ONE run, in the product’s own order — the run pins
the anchor first, then re-reads the baseline. To make it do that: delete the
checkpoint (MySQL / SQL Server / MongoDB) or let the slot be recreated
(PostgreSQL), AND clear the export’s
cdc_snapshotrow and the table’ssnapshot/_SUCCESS, AND truncate<table>__changesbefore the next load (a re-read baseline has no__pos, so the log cannot be deduplicated across it; the load refuses without the truncate). Deleting the checkpoint alone is refused: prior-run evidence exists and the run would re-anchor over a gap. - MySQL checkpoint used against another server: refused on purpose; same order on the new host.
rivet validate --config cfg.yamlcertifies both legs — the baseline undersnapshot/and the change parts — and never reports the baseline as stray.
Running the automated scenario
docker compose --profile cdc up -d
export BIGQUERY_TEST_PROJECT=<gcp-project> RIVET_TEST_GCS_BUCKET=<bucket>   # RIVET_TEST_BQ_DATASET optional
cargo test --test live_suite full_cdc_cycle -- --ignored --test-threads=1
Without the warehouse env the four tests skip, by name.
Database version support
Rivet supports five source engines — PostgreSQL, MySQL, SQL Server,
MongoDB and, in preview, Oracle Database — every supported version of which
is listed in the table below.
PostgreSQL and MySQL run the full end-to-end suite on each release —
doctor, check, every export mode (full / incremental / chunked / time_window),
every output format (CSV / Parquet) with every compression codec, reconcile,
recovery scenarios, state management, date-chunking, and rivet init. The
release gate runs that suite against a representative set — PostgreSQL 14,
16 and 18, MySQL 8.0 and 8.4 — chosen as oldest-supported, primary target and
newest; the remaining supported versions share the same code paths and are
spot-checked rather than gated on every release. No version-specific code paths
exist to skip: the same Rust driver builds and the same YAML configs drive every
target. SQL Server and
MongoDB carry their own scope and CI coverage, detailed below.
MongoDB (the OSS JSON-blob source — batch + CDC) rides its own dedicated CI matrix across 4.4 → 8.0, live-tested through the canonical test rig, rather than the SQL e2e suite above (a document store has no chunked / incremental / time_window modes). See mongodb.md.
Supported versions
| Engine | Versions | Status |
|---|---|---|
| PostgreSQL | 12 | Supported |
| PostgreSQL | 13 | Supported |
| PostgreSQL | 14 | Supported (release gate) |
| PostgreSQL | 15 | Supported |
| PostgreSQL | 16 | Supported (primary target, release gate) |
| PostgreSQL | 17 | Supported |
| PostgreSQL | 18 | Supported (release gate) |
| MySQL | 5.7 | Supported (EOL upstream Oct 2023) |
| MySQL | 8.0 | Supported (primary target, release gate) |
| MySQL | 8.4 | Supported (release gate) |
| SQL Server | 2022 | GA (source engine; see scope below) |
| MongoDB | 4.4 | Supported |
| MongoDB | 5.0 | Supported |
| MongoDB | 6.0 | Supported |
| MongoDB | 7.0 | Supported (primary target) |
| MongoDB | 8.0 | Supported |
| Oracle | 26ai Free (23.26) | Preview — batch, plus bounded CDC to files (no continuous CDC; a CDC export cannot feed load:); see oracle.md |
“Primary target” means the version that runs the e2e suite by default in the
local docker-compose.yaml top-level postgres / mysql / mssql / mongo services.
“Legacy” versions are opt-in under the legacy compose profile (see below).
SQL Server (MSSQL) — current scope
Status: GA. The engine is live-validated and feature-complete for the shapes below. The two gaps that formerly held it in Beta are now closed: the transitive rustls-webpki advisory (resolved — see below) and
datetimeoffsetroundtrip verification, so it is promoted to the same GA bar as PG/MySQL.Transitive advisory — RESOLVED.
tiberius0.12 formerly linkedrustls0.21 →rustls-webpki0.101, carrying CA name-constraint advisories (RUSTSEC-2026-0098/0099) and a CRL-parse panic (RUSTSEC-2026-0104). Rather than wait for an upstreamtiberiusbump, the driver now uses itsvendored-opensslTLS backend (OpenSSL, statically linked on every platform), so those advisories are out of the dependency tree entirely — not suppressed. On Linux this also unifies the TLS stack with the PG/MySQL drivers (all three link OpenSSL). On macOS the stacks differ: PG/MySQL usenative-tls, which resolves to the system SecureTransport framework, while the MSSQL driver statically links OpenSSL (SecureTransport cannot complete SQL Server’s TDS-wrapped TLS handshake). Strict validation (tls.mode: verify-ca | verify-full) is enforced by OpenSSL and rejects a certificate that does not chain to the trusted CA — verified live on macOS and Linux against a private-CA-configured SQL Server (correct CA connects; wrong CA is refused withcertificate verify failed).cargo auditis clean for the MSSQL engine. (native-tlsis deliberately not used: on macOS it resolves to SecureTransport, which cannot complete SQL Server’s TDS-wrapped TLS handshake.)Type fidelity.
datetimeoffset, the one type formerly “mapped but not roundtrip-verified”, is now validated through the DuckDB/ClickHouse Parquet oracles (UTC instant + tz-awareness, positive/negative offsets + NULL).
SQL Server is a source engine (source.type: mssql, scheme sqlserver://,
default port 1433), driven by the async tiberius client. Supported today:
- Modes:
full/ snapshot,incremental,chunked(range + dense), keyset (seek) via explicitchunk_by_key— the ideal shape for a non-integer PK (UUID / string) — and CDC (mode: cdc/rivet cdc, reading SQL Server change tables via the Agent capture job; see cdc.md). The page builder emits the T-SQLOFFSET 0 ROWS FETCH NEXT n ROWS ONLYclause (T-SQL has noLIMIT). - Types (live-validated through the DuckDB + ClickHouse Parquet oracles):
int/bigint/smallint/tinyint,bit,decimal/numeric,real/float,money,date,time,datetime2,nvarchar/varchar/char,varbinary,uniqueidentifier(→ native ParquetLogicalType::Uuid), anddatetimeoffset(→Timestamp(µs, UTC): the offset is applied and the UTC instant re-read correctly by the DuckDB/ClickHouse oracles — positive and negative offsets and NULL all covered in the type matrix). - TLS: required on the login handshake (SQL Server always encrypts it).
Set
tls.ca_file:for a private CA, ortls.accept_invalid_certs: truefor a self-signed dev cert.
Why these versions
- PostgreSQL 12 — oldest mainstream release still in community support (final minor release; community support ended Nov 2024, but many managed platforms — RDS, Cloud SQL, Azure Database — continue to ship it).
- PostgreSQL 13–15 — actively supported by upstream.
- PostgreSQL 16 — current stable at the time of writing; Rivet’s default.
- MySQL 5.7 — EOL upstream in October 2023 but widely deployed in legacy systems; keeping it in the matrix prevents silent breakage for those users.
- MySQL 8.0 — current stable; Rivet’s default.
Older releases (PostgreSQL ≤11, MySQL ≤5.6) aren’t tested. They may well work — Rivet’s SQL surface is deliberately narrow — but regressions on them aren’t caught by CI.
Running the compatibility matrix locally
Bring up every server the matrix covers:
# Primary versions (PG 16, MySQL 8.0) — plus MinIO and fake-gcs for destinations
docker compose up -d postgres mysql minio fake-gcs

# Legacy versions — opt in via the `legacy` profile
docker compose --profile legacy up -d \
    postgres-12 postgres-13 postgres-14 postgres-15 mysql-57

cargo build --release --bin rivet --bin seed --features dev-seed
Ports assigned (none conflict with the primary services):
| Service | Port |
|---|---|
postgres | 5432 |
postgres-12 | 5412 |
postgres-13 | 5413 |
postgres-14 | 5414 |
postgres-15 | 5415 |
mysql | 3306 |
mysql-57 | 3357 |
Then pick one of:
# Full e2e suite on every version — seeds each DB, then runs
# python3 -m dev.pytools.e2e against it with URLs retargeted via env.
python3 -m dev.pytools.legacy_stand full-matrix

# Just one target
TARGETS="pg-12"     python3 -m dev.pytools.legacy_stand full-matrix
TARGETS="mysql-57"  python3 -m dev.pytools.legacy_stand full-matrix

# Lighter compat smoke (seed + mode sampler + init) — same config, fewer
# assertions; useful when iterating on compat-sensitive code paths.
python3 -m dev.pytools.legacy_stand legacy
How the matrix targets an arbitrary server
python3 -m dev.pytools.e2e no longer hardcodes localhost:5432 / localhost:3306.
It reads RIVET_PG_URL and RIVET_MYSQL_URL from the environment (falling
back to the primary ports if unset), and every e2e YAML uses
url_env: RIVET_PG_URL (or RIVET_MYSQL_URL). So the same script + configs
drive any target:
RIVET_PG_URL=postgresql://rivet:rivet@localhost:5412/rivet \
    python3 -m dev.pytools.e2e
python3 -m dev.pytools.legacy_stand full-matrix does nothing more exotic than:
seed → export those env vars → invoke python3 -m dev.pytools.e2e.
Engine-specific notes
MySQL 5.7 — window functions
The view orders_sparse_for_export used by the chunked-sparse demo queries
uses ROW_NUMBER() OVER (...), which is only available from MySQL 8.0. The
dev/mysql/init.sql seeding script creates this view; when 5.7 runs the same
script it fails at container bootstrap with
ERROR 1064 (42000) at line 104: You have an error in your SQL syntax …
near '(ORDER BY id) AS chunk_rownum FROM orders_sparse' at line 5
Rivet ships a dedicated dev/mysql/init_57.sql (identical schema minus the
view) and docker-compose.yaml mounts it for the mysql-57 service. The
seed binary detects the server version via SELECT VERSION() and
short-circuits the CREATE OR REPLACE VIEW when the server reports 5.x:
note: MySQL 5.7.44 has no window functions — skipping `orders_sparse_for_export` view
All other schema (tables, indexes, JSON columns) works unchanged on 5.7.8+.
No production YAML depends on orders_sparse_for_export; it’s only used by
the chunked-sparse demo.
MySQL 5.7 — arm64 hosts (Apple Silicon)
There is no official arm64 image for mysql:5.7 on Docker Hub. The
docker-compose.yaml entry for mysql-57 pins platform: linux/amd64 so
Docker Desktop falls back to its amd64 emulator on M-series Macs. Boot is
~2 seconds slower than a native image but otherwise transparent.
MySQL 5.7 — auth plugin and local clients
MySQL 5.7 defaults to mysql_native_password. MySQL 8.0 defaults to
caching_sha2_password, and the Homebrew mysql-client@9 package on macOS
has dropped the plugin library for native_password entirely:
ERROR 2059 (HY000): Authentication plugin 'mysql_native_password'
    cannot be loaded: dlopen(...) (no such file)
The rust mysql crate (version 28, which Rivet depends on) has native_password
built in, so Rivet itself connects fine. Only local CLI tools (mysql,
mysqladmin) may refuse to. When scripts need a reachability probe, they use
a bash /dev/tcp test rather than mysqladmin:
if (exec 3<>/dev/tcp/127.0.0.1/"$port") 2>/dev/null; then
    echo "reachable"
fi
PostgreSQL — no TLS by default
Rivet’s dev/e2e/*.yaml configs connect without TLS (matches the primary
e2e harness). For production, enable transport security explicitly:
source:
  type: postgres
  url_env: DATABASE_URL
  tls:
    mode: verify-full           # disable | require | verify-ca | verify-full
    ca_file: /etc/ssl/certs/rds-ca-2019-root.pem
See config.md for the full TLS block. This works against every supported PostgreSQL version (12+).
PostgreSQL — rivet’s sessions run in UTC
Every PostgreSQL connection rivet opens sets TimeZone = 'UTC', DateStyle = 'ISO, MDY',
IntervalStyle = 'postgres' and bytea_output = 'hex', whatever the server, database or role
defaults are. Stored values are unaffected: a timestamptz is an instant, and a timestamp
has no zone. What changes is calendar arithmetic inside your own query:. For example,
current_date and ts::date on a timestamptz column count days in UTC. For the server’s
local day, say so explicitly: (ts AT TIME ZONE 'Europe/Kyiv')::date. Behind a
transaction-mode pooler (pgBouncer, Odyssey), a session SET would leak to other clients.
There rivet sets the zone only inside the export’s own transaction.
What “passes” means per target
Each target in dev/pytools/legacy_stand.py runs 83 assertions against its assigned
server. Status reported by the suite:
  pg-12: PASS (83 passed, 0 skipped)
  pg-13: PASS (83 passed, 0 skipped)
  pg-14: PASS (83 passed, 0 skipped)
  pg-15: PASS (83 passed, 0 skipped)
  pg-16: PASS (83 passed, 0 skipped)
  mysql-57: PASS (83 passed, 0 skipped)
  mysql-80: PASS (83 passed, 0 skipped)
581 assertions total, and a broken compat path surfaces which target(s)
failed and which specific assertion inside. Per-target logs are written to
/tmp/rivet_full_matrix/<target>.log.
Policy
- Adding a new supported version: add a service to
docker-compose.yamlunder thelegacyprofile, add the port mapping todev/pytools/legacy_stand.py, run the matrix, land the PR with the new version listed in this page’s table. - Dropping a version: remove the service from the compose file, remove
the target from
dev/pytools/legacy_stand.py, remove its row from this page, and note the change inCHANGELOG.md. Dropping a version is a minor-version bump (no SemVer guarantees apply to unsupported servers).
MongoDB Reference
Rivet reads a MongoDB collection as a JSON-blob table: every document becomes exactly two columns —
| column | type | contents |
|---|---|---|
_id | Utf8 | the document key, stringified (ObjectId → hex, int → decimal string, …) |
document | Utf8 + arrow.json extension | the whole BSON document as extended JSON |
Rivet does not flatten fields into typed columns. Documents in one collection
rarely share a schema, so rivet keeps each document intact as one JSON value and
lets the warehouse type it on the way in (PARSE_JSON → VARIANT on Snowflake,
JSON on BigQuery). This is lossless and schema-drift-proof: a new field in a
document never breaks a load.
Two run modes:
- Batch — a full snapshot of a collection to Parquet/CSV. Works against a
standalone
mongodor a replica set. - CDC — change capture via a change stream.
Requires a replica set (a single-node replica set is fine); a standalone
mongodcannot open a change stream.
Prerequisites
- A connection URL:
mongodb://[user:pass@]host:port/database. - For a port-mapped single-node replica set (common in local/dev docker),
append
?directConnection=true— otherwise the driver tries to re-resolve the replica-set members by their in-container hostnames and fails withReplicaSetNoPrimary. - For CDC, the login needs a role that can run
changeStream(e.g.readon the database). For delete/update pre-images (MongoDB 6.0+), the collection needschangeStreamPreAndPostImagesenabled.
Scenario A — Batch export (full snapshot)
Goal: copy a whole collection to Parquet, verify nothing was lost, and learn how it will land in the warehouse.
1. Scaffold a config
rivet init --source "mongodb://127.0.0.1:27017/shop" -o mongo.yaml
Or write it by hand — the minimal batch config:
# batch.yaml
source:
  type: mongo
  url: "mongodb://127.0.0.1:27017/shop"
  mongo:
    page_size: 5000          # keyset (seek) paging on _id — bounded query time
exports:
  - name: products
    table: products          # the collection name
    mode: full
    format: parquet
    parallel: 4              # _id-range fan-out (optional)
    destination:
      type: local
      path: "./out/products"
2. Preflight — rivet check
$ rivet check -c batch.yaml

Export: products
  Strategy:     full-parallel(4)
  Mode:         full
  Row estimate: ~20K
  Verdict:      ACCEPTABLE
check is advisory — it never blocks the run. (A couple of lines in the report —
max_connections, “only chunked mode benefits from parallelism” — are worded for
SQL sources and don’t apply to Mongo; ignore them.)
3. Warehouse portability — rivet check --target snowflake
$ rivet check -c batch.yaml --target snowflake

  document  json → VARIANT   warn ~
     autoload: TEXT
     note: JSON autoloads as TEXT; recover native VARIANT with PARSE_JSON after load
     recover: PARSE_JSON("document")
This tells you the exact recovery: load document as TEXT/VARCHAR, then
PARSE_JSON it into a VARIANT. Swap --target bigquery for the BigQuery form.
4. Run + validate — rivet run --validate
$ rivet run -c batch.yaml --validate

✓ products      keyset        20,000 rows    6 files   347.5 KB   0.8s
── products ──────────────────────────
  run_id:     products_20260708T120725.974
  rows:       20,000
  files:      6
  validated:  pass
--validate re-reads the output and checks the row counts. Add --reconcile to
compare the destination against a fresh countDocuments on the source.
4b. Or: plan → apply (freeze, review, execute)
rivet run decides the strategy and executes in one shot. To separate the
decision from the execution — review it, check it into a PR, run it later or on
another host — split it into plan + apply:
$ rivet plan -c batch.yaml --format json -o plan.json
Plan written to: plan.json
plan.json is the frozen, self-describing strategy — reviewable and tamper-evident:
{
  "export_name": "products",
  "expires_at": "2026-07-09T12:13:22Z",       // stale plans (>24h) are rejected
  "integrity": "xxh3:0f4e1be244bc0845",       // apply verifies this checksum
  "resolved_plan": {
    "strategy": { "Keyset": { "key_column": "_id", "chunk_size": 5000, "parallel": 4 } },
    "format": "parquet",
    "compression": "zstd"
  }
}
$ rivet apply plan.json

── products ──────────────────────────
  run_id:  products_20260708T121322.293
  rows:    20,000
  files:   6
  verify:  not run — add `--reconcile` or `rivet validate`
apply executes exactly the frozen plan (it re-checks the integrity
checksum and the expiry first). Same result as run; the difference is that the
strategy was pinned and reviewable in between. (One cosmetic note: the plan’s
base_query renders as SELECT * FROM products — a logical placeholder; Mongo
does not run SQL.)
5. What landed
$ duckdb -c "SELECT COUNT(*), COUNT(DISTINCT _id) FROM read_parquet('out/products/*.parquet')"
20000, 20000                              # no loss, no duplicates across pages

$ duckdb -c "SELECT document FROM read_parquet('out/products/*.parquet') LIMIT 1"
{"_id":{"$oid":"6a4e…"},"sku":"P000001","name":"Item 1",
 "price":{"$numberDecimal":"1.99"},"qty":1,"tags":[],"meta":{…}}
Every document is verbatim relaxed extended JSON — note $oid and
$numberDecimal type tags, which a warehouse PARSE_JSON reconstructs.
Scenario B — CDC (change capture)
Goal: capture inserts/updates/deletes from a collection, resumably, into Parquet. Needs a replica set.
1. Config
# cdc.yaml
source:
  type: mongo
  # directConnection=true is REQUIRED for a port-mapped single-node replica set
  url: "mongodb://127.0.0.1:27018/shop?directConnection=true"
exports:
  - name: orders_cdc
    table: orders
    mode: cdc
    format: parquet
    cdc:
      checkpoint: "./orders.ckpt"   # resume anchor (persisted resume token)
      initial: snapshot             # copy pre-existing docs first, then stream
      until_current: true           # bounded: drain the backlog, then exit
    destination:
      type: local
      path: "./cdc_out/orders"
2. Preflight — rivet doctor
$ rivet doctor -c cdc.yaml

[OK]  CDC replica set — replica set (server 7.0.37)
[OK]  CDC capture tier — full-image-capable (6.0+) — delete/update pre-images
      ride when changeStreamPreAndPostImages is enabled on the collection
doctor proves the source is a replica set and reports the capability tier
(see Capability tiers).
3. First run — snapshot + drain
$ rivet run -c cdc.yaml

✓ orders_cdc__snapshot_orders  full   3 rows   1 files       # the snapshot leg
── orders_cdc ──────────────────────────
  rows:   0                                                   # no changes yet
The snapshot leg copies the 3 pre-existing documents (they predate the change
stream, so the stream alone would miss them). The CDC leg then drains to
“now” — 0 changes — and, because until_current: true, exits. The checkpoint now
holds the resume token.
4. Some changes happen
db.orders.insertOne({_id:4, total:75, status:"new"})
db.orders.updateOne({_id:1}, {$set:{status:"shipped"}})
db.orders.deleteOne({_id:3})
5. Resume — captures only what changed
$ rivet run -c cdc.yaml

── orders_cdc ──────────────────────────
  rows:   3                                                   # only the 3 new changes
$ duckdb -c "SELECT __op, _id, document FROM read_parquet('cdc_out/orders/*.parquet')
             WHERE __op IS NOT NULL ORDER BY __pos"
insert  4  {"_id":4,"total":75,"status":"new"}
update  1  {"_id":1,"total":100,"status":"shipped"}           # post-image
delete  3  (null)                                             # _id only, no pre-image
Each change row carries three metadata columns:
| column | meaning |
|---|---|
__op | insert | update | delete |
__pos | the resume token — a distinct, order-preserving position per event |
__seq | always 0 for Mongo (see Dedup ordering) |
Scheduling
Run the same command on an interval (cron, systemd timer, Airflow). Each run
resumes from the checkpoint and drains to current. Because part files are named
from the millisecond run_id, consecutive runs into the same destination prefix
never overwrite each other.
Scenario C — many collections: source impact & parallel tuning
A config can export many collections at once (one - name: block each). rivet plan then writes one plan file per collection (plan.<name>.json), and — a
difference from SQL sources — every collection gets the same strategy shape:
keyset on _id. Mongo’s _id is always present and always indexed, so there
is no per-table strategy diversity to discover (no “table without a primary key”,
no chunk-vs-cursor choice). Files scale with size: files = ceil(rows / page_size).
What a full export does to the source
Measured over a 13-collection export (~800K documents, parallel: 1):
| source metric | value | meaning |
|---|---|---|
| query plan | LIMIT → FETCH → IXSCAN(_id) | every page rides the _id index — never a collection scan |
| docs examined ÷ returned | 1.000 | each document is read exactly once — zero wasted scan |
| queries issued | ~43 | 13 collections paged (find({_id:{$gt:…}}).limit(page_size)) |
| peak connections | 8 | modest |
| per-page latency | ~17 ms | for a 25K page |
Why this is gentle on a production Mongo:
- Index-bound. The seek
find({_id:{$gt: last}}).sort({_id:1}).limit(N)uses the_id_index —examined == returned, no over-scan, on any collection. - No long-lived cursor. Keyset issues a fresh bounded query per page, not one
cursor held open for the whole scan. Nothing is pinned in server memory for
minutes, and there is no cursor-timeout risk (this is why
no_cursor_timeoutis irrelevant to keyset). A naivefind()export would hold one cursor for the entire scan;skip/limitpaging would be O(n²) (re-scanning each page’s prefix). Keyset is O(n) with a page-lived cursor.
parallel: N — the trade
parallel: N splits a collection into N disjoint _id ranges (quantile
boundaries found with $sample, not a full-scan $bucketAuto) and scans them
concurrently. Same 8 heavy/medium collections, varying N:
parallel | wall-time | speed-up | peak connections | docs examined ÷ returned |
|---|---|---|---|---|
| 1 | 35.7 s | 1.0× | 8 | 1.000 |
| 4 | 12.4 s | 2.9× | 20 | 1.042 |
| 6 | 8.3 s | 4.3× | 26 | 1.042 |
| 8 | 7.1 s | 5.0× | 32 | 1.042 |
Reading the curve:
- The scan cost is flat. From
parallel: 4up,examined ÷ returnedsits at 1.042 and does not move — the only overhead is the one-time$sampleboundary probe (~+4%, fixed per collection, independent of N). More workers do not scan the source harder; the range scans stay index-bound and disjoint. - Connections grow linearly (~3 per unit of
N): 8 → 20 → 26 → 32. - Speed-up has a knee at ~6. 1→4 is 2.9×, 4→6 adds 1.5×, but 6→8 adds only 1.17× (+23% wall improvement for +23% connections — parity). Below the knee, connections buy speed cheaply; above it, they don’t.
So the choice is purely Mongo’s connection budget vs. desired wall-time — the scan footprint barely changes:
| setting | when |
|---|---|
parallel: 1 | a production Mongo under load — smallest footprint (8 conns, examined ÷ returned = 1.000) |
parallel: 6 | the sweet spot — 4.3× at 26 connections |
parallel: 8 | only when Mongo has connection headroom — 5× at 32 connections |
The bigger the collection, the more parallel pays off — the fixed ~+4% $sample
cost amortises better over 300K rows than over 30K.
Connection pool
There is no external pooler (no pgBouncer/ProxySQL analog) — the MongoDB driver
pools connections itself, one pool per Client, and rivet passes the pool
knobs straight through from the connection URL (it sets none of its own):
| URL param | driver default | effect |
|---|---|---|
maxPoolSize | 10 | hard cap on connections per client |
minPoolSize | 0 | keep-warm minimum |
maxIdleTimeMS | ∞ | idle connection TTL |
maxConnecting | 2 | concurrent handshakes |
The one thing to know: parallel: N opens N independent clients — N pools.
So the connection ceiling is N × maxPoolSize. In practice each worker runs a
sequential keyset scan and holds only ~1–2 connections (the measured peak was
20 at parallel: 4, not 4 × 10 = 40 — workers don’t saturate their pools), but
N × maxPoolSize is the ceiling to size against the server’s budget:
source:
  type: mongo
  # cap each worker's pool; with parallel: 4 the ceiling is 4 × 5 = 20
  url: "mongodb://host/db?maxPoolSize=5"
directConnection=true (needed for a port-mapped replica set) does not
disable the pool — it still holds up to maxPoolSize connections to the single
server, just without topology discovery.
Config reference — source.mongo.*
| key | values | default | effect |
|---|---|---|---|
json | relaxed | canonical | relaxed | how document renders (see Type fidelity) |
page_size | N | — | keyset (seek) paging on _id; bounds query time on big collections |
resume | bool | false | resume batch keyset paging across runs (reuses the export checkpoint) |
read_concern | server | snapshot | server | snapshot gives a point-in-time read (5.0+ replica set) |
no_cursor_timeout | bool | true | keep a slow scan’s cursor alive |
Everything else is the shared surface: parallel (an _id-range fan-out for
Mongo), mode: cdc, cdc.{checkpoint, initial, until_current, max_events}, and
--target / --format / --validate / --reconcile on the CLI.
Type fidelity
Rivet stores document verbatim — there is no corruption at rest. Fidelity
downstream depends on the JSON mode and the reader:
relaxed(default) renders numbers as bare JSON ("qty": 1), with type tags only where JSON can’t express the type ($oid,$numberDecimal,$date). Compact and directly queryable.canonicaltype-tags every value ({"$numberInt":"1"},{"$numberLong":"…"}). Verbose but unambiguous.
The one trap — large 64-bit integers. A relaxed Int64 larger than 2⁵³
(9,007,199,254,740,992) is a bare JSON number. A reader that parses JSON numbers
as IEEE-754 doubles (most JavaScript-based tools) will round it. Two safe
paths:
- Target Snowflake or BigQuery — their
PARSE_JSONparses JSON integers as exactNUMBER(up to 38 digits), not doubles. Verified round-trip:9007199254740993survives relaxed → Parquet →PARSE_JSON→INTEGER. - Or set
json: canonical—$numberLongis a string, lossless for any reader.
| value | relaxed + f64 JS reader | relaxed + Snowflake/BigQuery | canonical |
|---|---|---|---|
Int64 ≤ 2⁵³ | exact | exact | exact |
Int64 > 2⁵³ | rounded ⚠ | exact | exact |
Decimal128 | exact ($numberDecimal string) | exact | exact |
Guidance: for a Snowflake/BigQuery target, relaxed is safe and the better
default. Choose canonical if a downstream f64 JSON parser will touch large
integers.
Consuming in the warehouse
The two-column blob (_id + document) loads into any warehouse, but two things
are worth knowing before you write the MERGE.
document is JSON — but BigQuery loads it as BYTES
Rivet tags the document column with the Arrow arrow.json extension. Snowflake
and a direct PARSE_JSON pick this up, but BigQuery’s Parquet loader does not
recognise the extension — the column lands as BYTES, not JSON. Convert on
read (verified against a live BigQuery load):
PARSE_JSON(SAFE_CONVERT_BYTES_TO_STRING(document)) -- BigQuery
Snowflake autoloads document as TEXT, so PARSE_JSON(document) is direct —
see rivet check --target snowflake.
Merging on _id
For the common case — a collection with a single _id type (the MongoDB
convention: ObjectId by default, or a consistent int/string) — the flat _id
column is a perfect merge key:
MERGE INTO target T USING source S ON T._id = S._id ... -- uniform _id
Merging a heterogeneous-_id collection
If one collection mixes _id types (int 1001 and string "1001", or an
ObjectId and its hex stored as a string), the flat _id column stringifies
them to the same text. A MERGE ON _id then matches one source row against
both target rows and silently overwrites one with the other — a real data loss,
confirmed on a live BigQuery merge. Rivet exports both rows correctly (the export
never loses data) and warns when a full scan or CDC run sees a heterogeneous
_id; the fix is in the merge key, downstream.
The typed value is always in document._id. On BigQuery, JSON_QUERY preserves
the type (1001 and "1001" render as different JSON text — 1001 vs
"1001"), so a type-exact key is:
-- distinguishes int 1001 from string "1001"; correct on ANY collection
TO_JSON_STRING(JSON_QUERY(PARSE_JSON(SAFE_CONVERT_BYTES_TO_STRING(document)), '$._id'))
A CDC merge keyed on it, deduped by the order-preserving __pos (latest wins):
MERGE INTO `dataset.target` T
USING (
  SELECT
    PARSE_JSON(SAFE_CONVERT_BYTES_TO_STRING(document)) AS document,
    TO_JSON_STRING(JSON_QUERY(
      PARSE_JSON(SAFE_CONVERT_BYTES_TO_STRING(document)), '$._id')) AS id_key,
    __op
  FROM `dataset.cdc_stream`
  QUALIFY ROW_NUMBER() OVER (PARTITION BY id_key ORDER BY __pos DESC) = 1
) S
ON TO_JSON_STRING(JSON_QUERY(T.document, '$._id')) = S.id_key
WHEN MATCHED AND S.__op = 'delete' THEN DELETE
WHEN MATCHED THEN UPDATE SET document = S.document
WHEN NOT MATCHED AND S.__op != 'delete' THEN INSERT (document) VALUES (S.document);
Heterogeneous _id in one collection is rare and discouraged — it usually
signals an app bug or a botched migration. Keyset paging and parallel reject it
outright (see the caveat below), so it only ever reaches a full scan or CDC. The
document._id key above is also correct on uniform collections, so it is a
safe default if you would rather not special-case.
Capability tiers
The change-stream feature set depends on the server version — doctor reports it:
| tier | versions | update/delete images |
|---|---|---|
| current-state | 4.4, 5.0 | update carries the current full document (UpdateLookup); delete carries _id only |
| full-image-capable | 6.0+ | pre-images available on delete/update when changeStreamPreAndPostImages is enabled |
Operational parity
The batch read path carries the same reliability surface as the SQL engines
(each row is a live test in live_mongo*.rs):
| concern | Mongo behavior |
|---|---|
| retry | transient errors are classified and retried on a fresh connection — network drops, ServerSelection, pool-cleared, and the retryable-read command codes (a replica-set failover / stepdown mid-scan). See classify_mongo_error. |
| crash-recovery | a crash mid-export (any commit window) + a clean re-run loses nothing — every _id is present — at at-least-once: a keyset full export keeps no mid-run checkpoint, so the re-run rescans and the orphaned crash page’s rows survive as duplicates, deduped downstream by _id. |
| reconcile | rivet run --reconcile — source count_documents vs destination rows, reports MATCH. |
| resume | source.mongo.resume: true — the export persists the keyset cursor; the next run reads only _id greater than last time (incremental append-by-_id, no rescan). |
| harm metrics | source-impact counters come from serverStatus (needs the clusterMonitor role / serverStatus action). A read-only login without it degrades gracefully — the counters are simply absent, the export is unaffected. |
Deliberately N/A (not gaps):
rivet reconcile/rivet repair(partition-level) — keyset has no natural partitions, so the CLI routes you torivet run --reconcilerather than guessing a partition scheme. (Chunked SQL exports have numeric-range partitions; a document store does not.)- schema drift — the blob schema is fixed at two columns (
_id,document); a new field in a document lands inside thedocumentJSON, so the Parquet schema never changes and there is nothing to drift. (Contrast the SQL engines, where anALTER TABLE ADD COLUMNshifts the column set.) - connection pooler /
proxy.rs— the MongoDB driver pools connections itself (andmongosis transparent), so there is no pgBouncer/ProxySQL analog to test.
Caveats
UpdateLookupis current-state, not point-in-time. An update’s captured document is the document as it exists when the stream reads the event, not at the moment of the update. If a document is updated then deleted before the next capture, the update’sdocumentcomes backNULL(the doc is gone) — this is at-least-once-correct (the delete is captured), not a loss. Frequent captures keep the post-image fresh.- A delete without a pre-image has
document = NULL. EnablechangeStreamPreAndPostImages(6.0+) if you need the deleted document body. - Dedup ordering. To reconstruct current state from
the change log, order by
__posalone and keep the last row per_id(deletes remove). Unlike SQL engines, Mongo gives every event a distinct__poseven inside one transaction, so__seqis always0. - Keyset needs a single
_idtype. Keyset paging (andparallel) seeks with$gt, which MongoDB type-brackets — it cannot cross from one BSON_idtype to another (a numeric cursor never matches a string_id, even though strings sort after numbers). rivet detects a heterogeneous-_idcollection up front (int + string, …) and refusespage_size/parallelwith a clear error rather than silently dropping every type but one; omitpage_sizeto use a full scan — its single cursor does cross types. The four numeric types (Int32/Int64/Double/Decimal128) share one bracket, so a mixed-numeric_idkeysets fine, andparalleltiles any single ordered type (ObjectId, int, string). A full scan (or CDC) over such a collection reads everything, but the flat_iddisplay column can collide across types — rivet warns, and Consuming in the warehouse shows the type-exact merge key.
Oracle Database (source)
Status: Preview. Live-tested against Oracle AI Database 26ai Free (release 23.26.3,
gvenzl/oracle-free:23-slim-faststart, the stand’soraclecompose service).mode: cdcreads the redo logs through LogMiner (preview; see the Oracle section of cdc.md for the prerequisites). The driver is Oracle’s pure-Rust thin driveroracledb 26.0.0-beta.4; no Oracle client install is needed.
Connecting
source:
  type: oracle
  url_env: ORACLE_URL   # oracle://user:password@host:1521/SERVICE
- The URL path is the service name (Oracle Free’s pluggable database is
FREEPDB1), not a SID. Port defaults to 1521. Percent-encode@,:and/in the password. rivet init --source-env ORACLE_URLscaffolds a config from the catalog of the connecting user’s schema (--schema OWNERfor another one).- Unquoted names are upper-case in Oracle.
table: ordersreadsORDERS; a quoted mixed-case table ("MixedCase") needs aquery:—rivet initwrites one. Strategy columns (chunk_column,chunk_by_key,cursor_column) match the catalog name exactly;rivet checknames the real spelling when they do not.
TLS
tls.mode other than disable connects with tcps://. The driver verifies the
server certificate against the public CA bundle compiled into it, not the
system trust store, for every enforced mode. tls.ca_file is refused: a server
certificate issued by a private CA cannot be verified yet.
Privileges
| Grant | Needed for |
|---|---|
CREATE SESSION + SELECT on the exported tables | every export |
SELECT_CATALOG_ROLE (or SELECT on V_$SYSSTAT, V_$SYSTEM_EVENT) | source-harm metrics and governor pressure; without it they are absent and rivet doctor says so |
Row estimates come from ALL_TABLES.NUM_ROWS and need no extra grant.
Session state
rivet pins its own session so values never depend on database or client
defaults: TIME_ZONE = '+00:00', NLS_CALENDAR = GREGORIAN,
NLS_NUMERIC_CHARACTERS = '.,', ISO NLS_DATE_FORMAT / NLS_TIMESTAMP_FORMAT /
NLS_TIMESTAMP_TZ_FORMAT, and NLS_SORT = NLS_COMP = BINARY (so a keyset or
cursor seek compares keys the way ORDER BY sorts them, even under a logon
trigger that makes the session linguistic).
Modes
| Mode | Oracle notes |
|---|---|
full | any table, view or query: |
incremental | cursor bound as text through the pinned masks |
chunked range | chunk_column must be an integer NUMBER(p ≤ 18, 0) |
chunked keyset (chunk_by_key) | single-column unique NOT NULL key: integer NUMBER of any precision, bare NUMBER, VARCHAR2/CHAR, DATE, TIMESTAMP(0..6); also parallel > 1 |
time_window, partition_by | ANSI TIMESTAMP '…' / DATE '…' bounds |
TIMESTAMP(7..9) is not a keyset key (rivet reads it at microseconds, so a page
could not advance), and it is refused as an incremental cursor
(RIVET_SOURCE_CURSOR_FINER_THAN_MICROSECOND): the saved cursor would fall below
its own row and every run would export that row again. Read it as
CAST(col AS TIMESTAMP(6)) in a query:, or pick a cursor with at most 6
fractional digits. rivet init never scaffolds one as a cursor or a keyset key,
nor a BINARY_FLOAT/BINARY_DOUBLE or zoned TIMESTAMP keyset key.
columns: override keys match the result’s column names exactly; a key that
matches one only when case is ignored (created_at for CREATED_AT) is refused
(RIVET_CONFIG_COLUMN_OVERRIDE_CASE) rather than silently skipped.
tuning.statement_timeout_s is enforced on the server: the driver’s call timeout
stops the query at the budget.
Types
| Oracle | Arrow / Parquet |
|---|---|
NUMBER(1..9, 0) / NUMBER(10..18, 0) | Int32 / Int64 |
NUMBER(p, s) otherwise | Decimal128(p, s); s > p widens to (s, s), negative s to (p − s, 0) |
bare NUMBER, FLOAT | exact decimal text (Utf8) with a warning — declare columns: to load it as a number |
BINARY_FLOAT / BINARY_DOUBLE | Float32 / Float64 (NaN, ±Inf kept) |
BOOLEAN (23ai and later) | Boolean |
DATE, TIMESTAMP(0..6) | Timestamp(µs) |
TIMESTAMP(7..9) | Timestamp(µs), sub-microsecond digits truncated (reported Lossy) |
TIMESTAMP WITH [LOCAL] TIME ZONE | Timestamp(µs, UTC) — converted on the server (SYS_EXTRACT_UTC) |
INTERVAL YEAR TO MONTH / DAY TO SECOND | ISO 8601 duration text |
VARCHAR2, NVARCHAR2, CHAR, NCHAR, CLOB, NCLOB, LONG | Utf8 (a zero-length LOB stays '', not NULL) |
RAW, LONG RAW, BLOB | Binary |
JSON, XMLTYPE, VECTOR, ROWID | text, serialized on the server |
Refused with the column named (live-tested on a VARRAY): user-defined object
types, collections and ANYDATA — select their attributes in a query:. An
unaliased ROWID in a query: is refused too — alias it.
BC dates keep their calendar fields (Oracle -0001-06-15 is 0001-06-15 BC in
Parquet); dates before 1582-10-15 are not converted from Oracle’s Julian calendar.
Known limits
- The driver is a beta:
oracledb =26.0.0-beta.4, pinned exactly, behind theoraclecargo feature, which is on by default. - TLS verifies the server against the public CA bundle compiled into the driver
(
webpki-roots) only: no system trust store, notls.ca_file(refused), no Oracle wallet. TIMESTAMP(7..9)values are truncated to microseconds (reported Lossy, with a warning); such a column is refused as an incremental cursor.- CDC (LogMiner) is a preview and runs only as a bounded drain to files, to the SCN
current at open; continuous CDC (
until_current: false,rivet cdc --stream) is refused at config load (RIVET_CONFIG_CDC_CONTINUOUS_UNSUPPORTED), and an Oracle CDC export cannot feed aload:block. ATRUNCATE(table, partition or subpartition) of a captured table is refused after the changes before it are delivered and checkpointed, and every re-run stops there until you re-anchor and re-snapshot. It captures NUMBER, FLOAT, BINARY_FLOAT/DOUBLE, DATE, TIMESTAMP (every zone form), VARCHAR2/NVARCHAR2/CHAR/NCHAR and RAW columns and refuses a table with any other type by name. - Graded only against Oracle AI Database 23ai/26ai Free. 19c and 21c are untested.
NVARCHAR2/NCHARon a database whose character set is not Unicode is untested.- A table of exactly 1000 columns that has LOBs: the server-side empty-value flags would exceed Oracle’s 1000-column select list, so zero-length LOBs read as NULL, with a warning.
- Each chunk or page reads its own statement-level snapshot; there is no cross-chunk consistency.
Source-Aware Extraction Prioritization
See also: ADR-0006 — Source-Aware Extraction Prioritization.
Rivet helps decide what to extract first, what to delay, and what to isolate on shared source hosts. This is an advisory planning feature — it does not schedule runs, change execution, or throttle workers.
What you get
For each export, rivet plan computes and embeds:
priority_score(0..100) — deterministic rule-based rank.priority_class—low/medium/high.cost_class—low/medium/high/very_high.risk_class—low/medium/high.recommended_wave— integer 1..4 grouping exports by urgency + cost.reasons[]— structured, explainable reasons (small_table,weak_cursor,sparse_range_risk,reconcile_required, …).isolate_on_source— set when a sharedsource_grouphas several heavy exports.
For a multi-export rivet plan invocation the same artifact also contains a campaign view:
ordered_exports— sorted bypriority_score(descending), tie-broken by name.waves[]— exports grouped byrecommended_wave.source_group_warnings[]— human-readable warnings about shared-source collisions.
Inputs (how the score is built)
| Signal | Source |
|---|---|
| Row estimate | Preflight EXPLAIN |
| Chunk count | Computed at plan time for chunked exports |
| Strategy | Resolved ExtractionStrategy |
| Cursor quality | Preflight index use + min/max range; see ADR-0007 |
| Sparse-range risk | Preflight warnings |
| Reconcile required | reconcile CLI flag or reconcile_required: true in config |
| Source freshness | Heuristic for short time_window exports |
| Source group | source_group: in exports[] config |
| History (Epic I) | Last ~20 rows of export_metrics — retry rate, recent failure, avg duration |
Missing signals (e.g. preflight failed) lower confidence explicitly — the recommendation is never silently “strong” on weak data.
Historical refinement (Epic I)
When prior runs exist, rivet plan folds them into the score with bounded contribution (fixed per-reason penalties: −8 recent failure, −5 high retry rate, −4 slow history — at most 17 points when all three fire) so history cannot override preflight:
| Condition | Penalty | Reason |
|---|---|---|
| Most recent run failed | −8 | recent_failure_history |
| Retry rate > 0.3 over ≥3 runs | −5 | high_retry_rate_history |
| Average duration ≥ 5 min over ≥3 runs | −4 | slow_history |
History is ignored when sample size is too small or when state.get_metrics is unavailable — the advisory never becomes louder than the data allows.
Enabling shared-source awareness
Mark exports that share a single replica/host with source_group:
exports:
  - name: orders
    source_group: replica_a
    mode: incremental
    cursor_column: updated_at
    ...

  - name: events
    source_group: replica_a
    mode: chunked
    chunk_column: id
    ...

  - name: users_dim
    mode: full          # no source_group — won't participate in group warnings
    ...
If two or more members of the same group land in the heavy cost classes, Rivet flags the group and marks each heavy member as isolate_on_source: true in the artifact.
Viewing the output
Pretty (default) — rivet plan --config ... prints a Priority block per export and a Campaign block when multiple exports are planned:
  Priority   : score 72 — High (wave 2)
  Prioritize :
    • [large_table] Medium/large estimated row count (~8000000).
    • [chunking_heavy] Chunked extraction (12 chunk windows) — higher source load and runtime.
    • [shared_source_heavy_conflict] Shared source group 'replica_a' has multiple heavy exports — run this export alone on that source.
  Campaign   :
    • Source group 'replica_a': 2 heavy-cost exports (orders, events) — avoid running them concurrently; stagger or isolate.
JSON artifact — rivet plan --format json --output plan.json ... embeds the full prioritization object (per-export recommendation plus the campaign view).
Design principles
- Advisory, not authoritative. Recommendations guide operators and external orchestrators; they do not change what Rivet executes.
- Explainability first. Every recommendation carries a list of structured reasons; nothing is score-only.
- Metadata is signal, not truth. When preflight fails or metadata is missing, the
low_confidence_metadatareason is attached and scores move toward neutral. - Graceful degradation. Weaker inputs → weaker (never stronger) recommendations.
Out of scope
- Runtime scheduling / queueing / throttling — Rivet recommends; operators schedule.
- Automatic execution reordering based on the campaign view — the artifact surfaces the order; no runtime component consumes it.
- Business-criticality overrides — not inferred from the database; express via
source_groupandreconcile_required.
Historical refinement (Epic I) is in scope and implemented — see the section above.
For future planning work, see rivet_roadmap.md at the repo root.
Local Filesystem Destination
Config block
destination:
  type: local
  path: ./output                    # directory for output files
path can be absolute (/data/exports) or relative to the working directory.
Rivet creates the directory if it does not exist.
Output filenames
Files are named automatically:
{export_name}_{YYYYMMDD}_{HHMMSS}_{mmm}.{format}
The trailing _mmm is milliseconds, added so two runs in the same second never overwrite each other.
Examples:
users_daily_20260406_120000_123.parquetorders_incremental_20260406_120000_123.csv(CSV is always uncompressed — a compression codec on CSV is rejected at config validation, see Compression below)
For chunked exports, each part appends _chunk{N} plus a 16-hex random nonce (the nonce guarantees re-runs/repairs never overwrite an existing part):
orders_chunked_20260406_120000_chunk0_9f3a1c2b4d5e6f70.parquet
File splitting
For large exports, split output into multiple files:
exports:
  - name: big_table
    query: "SELECT * FROM big_table"
    mode: full
    format: parquet
    max_file_size: "256MB"          # split when file exceeds this size
    destination:
      type: local
      path: ./output
Parts are named: big_table_20260406_120000_123_part0.parquet, ..._part1.parquet, etc. (unpadded part index; the timestamp includes a millisecond field).
Accepted size suffixes: KB, MB, GB (case-insensitive).
Compression
Compression is applied before writing to disk:
exports:
  - name: users
    query: "SELECT * FROM users"
    mode: full
    format: parquet
    compression: zstd               # default for Parquet
    compression_level: 3            # optional: 1 (fast) to 22 (smallest)
    destination:
      type: local
      path: ./output
| Format | Default compression | Options |
|---|---|---|
| Parquet | zstd | zstd, snappy, gzip, lz4, none |
| CSV | none | none only |
CSV does not support compression — parquet is the compressed format. A
compression: other than none on a CSV export is rejected at config
validation. Compress CSV output downstream (e.g. gzip) if you need it.
Verify
rivet doctor --config my_export.yaml
Output:
[OK] Destination Local(./output)
List exported files
rivet state files --config my_export.yaml
rivet state files --config my_export.yaml --export users_daily --last 5
S3 Destination (AWS S3 / MinIO)
Config block
destination:
  type: s3
  bucket: my-data-bucket            # S3 bucket name (must already exist)
  prefix: exports/daily/            # optional key prefix (folder-like path)
  region: us-east-1                 # AWS region (required for AWS S3)
Credentials
Rivet uses OpenDAL for S3 access. Credentials are resolved in this order:
Option 1: AWS default credential chain (recommended)
If you’re running on EC2, ECS, Lambda, or have ~/.aws/credentials configured, just set region:
destination:
  type: s3
  bucket: my-data-bucket
  region: us-east-1
Option 2: Environment variables
Set AWS_ACCESS_KEY_ID and AWS_SECRET_ACCESS_KEY before running:
export AWS_ACCESS_KEY_ID=AKIA...
export AWS_SECRET_ACCESS_KEY=wJa...
rivet run --config export.yaml
Or reference them in the config:
destination:
  type: s3
  bucket: my-data-bucket
  region: us-east-1
  access_key_env: AWS_ACCESS_KEY_ID
  secret_key_env: AWS_SECRET_ACCESS_KEY
Option 3: AWS profile
destination:
  type: s3
  bucket: my-data-bucket
  region: us-east-1
  aws_profile: my-profile           # uses [my-profile] from ~/.aws/credentials
S3-compatible endpoints (MinIO / local emulators)
For a local S3-compatible emulator, add endpoint. A loopback endpoint
(localhost / 127.x / ::1 — the MinIO case) is accepted as-is:
# MinIO (loopback — no extra flag needed)
destination:
  type: s3
  bucket: rivet-exports
  endpoint: "http://localhost:9000"
  region: us-east-1                 # required but can be any value
  access_key_env: MINIO_ACCESS_KEY
  secret_key_env: MINIO_SECRET_KEY
Non-loopback S3-compatible services (R2, Wasabi, B2) — not supported
Rivet rejects any non-loopback custom endpoint at config load, by design:
a committed custom endpoint silently redirects every upload (a
data-exfiltration / cleartext-credential risk), so only loopback emulators are
accepted with credentials. Cloudflare R2, Wasabi, Backblaze B2 and similar
services all require a non-loopback endpoint and are therefore not a
validated Rivet destination — Rivet has never been tested against them.
(allow_anonymous: true technically waives the endpoint guard and static keys
are still used to sign, but that flag is meant for anonymous emulators; the
combination is untested against real S3-compatible services and may break
without notice. If you depend on it anyway, verify the full upload path —
parts, manifest.json, _SUCCESS, and a re-read — yourself.)
Output keys
Files are uploaded as:
s3://{bucket}/{prefix}{export_name}_{YYYYMMDD}_{HHMMSS}_{mmm}.{format}
This is the single (non-chunked, non-keyset) runner’s naming: the timestamp includes a millisecond field, and its size-split parts append _part{N} before the extension. Chunked runs name parts {export}_{timestamp}_chunk{N}_{nonce}.{format} and keyset runs key part names off the run id — see the per-runner naming table in docs/cloud-destinations.md.
Example: s3://my-data-bucket/exports/daily/orders_20260406_120000_123.parquet
Streaming upload
Rivet streams data directly to S3 without buffering the entire file in memory. Peak RSS stays proportional to batch_size, not to the total export size.
Verify
rivet doctor --config export.yaml
Output:
[OK] Destination S3(my-data-bucket)
Doctor labels the destination as S3(<bucket>); a passing check prints no detail suffix.
Troubleshooting
NoSuchBucket – The bucket must already exist. Create it first: aws s3 mb s3://my-data-bucket.
AccessDenied – Check IAM policy. Rivet needs s3:PutObject and s3:GetBucketLocation.
SignatureDoesNotMatch with MinIO – Ensure region is set (even for MinIO, e.g. us-east-1).
Google Cloud Storage Destination
Config block
destination:
  type: gcs
  bucket: my-gcs-bucket             # GCS bucket name (must already exist)
  prefix: exports/                   # optional object prefix
Credentials
Rivet uses OpenDAL for GCS access. Credentials are resolved in this order:
Option 1: Application Default Credentials (recommended)
If you’re running on GCE, Cloud Run, or have gcloud configured, no extra config is needed:
# On a local machine, set up ADC:
gcloud auth application-default login

# Then just use:
rivet run --config export.yaml
destination:
  type: gcs
  bucket: my-gcs-bucket
Option 2: Service account JSON key
destination:
  type: gcs
  bucket: my-gcs-bucket
  credentials_file: /path/to/service-account.json
Option 3: GOOGLE_APPLICATION_CREDENTIALS env var
export GOOGLE_APPLICATION_CREDENTIALS=/path/to/service-account.json
rivet run --config export.yaml
Required IAM permissions
The service account or authenticated user needs:
storage.objects.createstorage.objects.delete(if overwriting)storage.buckets.get(forrivet doctorverification)
The simplest predefined role: Storage Object Admin (roles/storage.objectAdmin) on the bucket.
Output keys
Files are uploaded as:
gs://{bucket}/{prefix}{export_name}_{YYYYMMDD}_{HHMMSS}_{mmm}.{format}
This is the single (non-chunked, non-keyset) runner’s naming: the timestamp carries millisecond precision, and its size-split parts append _part{N}. Chunked and keyset runs use their own run-unique part names — see the per-runner naming table in docs/cloud-destinations.md.
Example: gs://my-gcs-bucket/exports/orders_20260406_120000_123.parquet
Streaming upload
Rivet streams data directly to GCS without buffering the entire file in memory. This keeps peak RSS proportional to batch_size, not total export size.
Using fake-gcs-server for development
For local development/testing, use fake-gcs-server:
# docker-compose.yaml
services:
  fake-gcs:
    image: fsouza/fake-gcs-server
    ports:
      - "4443:4443"
    command: ["-scheme", "http", "-port", "4443"]
# rivet config
destination:
  type: gcs
  bucket: test-bucket
  endpoint: "http://localhost:4443"
Create the bucket first:
curl -X POST "http://localhost:4443/storage/v1/b?project=test" \
  -H "Content-Type: application/json" \
  -d '{"name": "test-bucket"}'
Verify
rivet doctor --config export.yaml
The GIF above shows the end-to-end flow with Application Default Credentials (no credentials_file: in the config, no GOOGLE_APPLICATION_CREDENTIALS env var — Rivet reads ~/.config/gcloud/application_default_credentials.json directly):
cat gcs.yaml— production-shaped YAML (justtype: gcs,bucket:,prefix:).rivet doctorwrites a small.rivet_doctor_probeobject to verify write access, then reports[OK] Destination GCS(<bucket>)followed by a finalAll checks passed.line.rivet run --validateexports 100 rows and uploads the Parquet file.gcloud storage lsconfirms the probe file and the export both landed in the bucket.
Source: docs/gifs/doctor-gcs.tape.
Plain-text equivalent output:
[OK] Destination GCS(my-gcs-bucket)
Doctor labels the destination as GCS(<bucket>); passing checks print no
detail suffix.
Troubleshooting
403 Forbidden – Check IAM permissions. The service account needs storage.objects.create.
404 Not Found – The bucket must already exist. Create it: gsutil mb gs://my-gcs-bucket.
ADC not found – Run gcloud auth application-default login or set GOOGLE_APPLICATION_CREDENTIALS.
Azure Blob Storage Destination
Added in 0.7.1. Third cloud destination after S3 and GCS, on the same opendal-backed write/read surface and the same M1–M9 manifest trust contract. Verified live against a real Azure storage account on 2026-05-21.
Config block
destination:
  type: azure
  bucket: my-container             # Azure container name (Rivet reuses `bucket:` across S3 / GCS / Azure)
  account_name: mystorageacct       # the `<acct>` in `<acct>.blob.core.windows.net`
  account_key_env: RIVET_AZURE_KEY  # env var holding the account key
  prefix: exports/                  # optional object prefix
account_name is a plain string — it’s the public DNS-visible name of
the storage account, not a secret (same status as AWS region). The
account key lives in an env var and is wrapped in Zeroizing<String>
inside Rivet so it’s wiped from heap on drop.
Rivet auto-derives the endpoint from account_name as
https://<account_name>.blob.core.windows.net. Set endpoint:
explicitly only for a loopback emulator (Azurite, e.g.
http://127.0.0.1:10000/devstoreaccount1) or, with
allow_anonymous: true, an anonymous emulator. Rivet rejects any
non-loopback custom endpoint at config load as an exfiltration guard
unless allow_anonymous: true is set (the anonymous-emulator escape),
and allow_anonymous cannot be combined with credentials — so
authenticated sovereign-cloud (US-Gov, China-Mooncake) or custom-DNS
endpoints are not currently supported.
Credentials
Option 1: Storage account name + account key (the 0.7.1 path)
The primary auth flow for 0.7.1. Account key comes from the Azure portal (Storage account → Access keys → key1 or key2). Rotate via the portal; Rivet has no opinion about rotation cadence.
Shell:
export RIVET_AZURE_KEY="long-base64-key-from-portal=="
Config:
destination:
  type: azure
  bucket: my-container
  account_name: mystorageacct
  account_key_env: RIVET_AZURE_KEY
To fetch the key from the Azure CLI:
az storage account keys list \
  --account-name <account> --resource-group <rg> \
  --query "[0].value" -o tsv
Option 2: Azurite emulator (and public read-only containers)
For local development against Azurite:
destination:
  type: azure
  bucket: rivet-e2e
  endpoint: http://127.0.0.1:10000/devstoreaccount1
  allow_anonymous: true
allow_anonymous: true skips both account_name and account_key_env.
Rivet refuses to combine allow_anonymous: true with explicit
credentials.
Run Azurite via Docker:
docker run -d --name rivet-azurite -p 10000:10000 \
  mcr.microsoft.com/azure-storage/azurite \
  azurite-blob --blobHost 0.0.0.0
Option 3: SAS token (added in 0.7.2)
A Shared Access Signature token scopes access to a specific container and time window — useful when you cannot or should not share the full account key.
Shell:
export AZURE_STORAGE_SAS_TOKEN="sv=2021-08-06&ss=b&srt=o&sp=rwdlacupitfx&se=2026-06-01T00:00:00Z&st=2026-05-21T00:00:00Z&spr=https&sig=..."
Config:
destination:
  type: azure
  bucket: my-container
  account_name: mystorageacct
  sas_token_env: AZURE_STORAGE_SAS_TOKEN
account_key_env and sas_token_env are mutually exclusive — Rivet
rejects configs that specify both. The leading ? is stripped
automatically if you paste the token directly from the Azure portal.
Generate a SAS token via the Azure CLI:
az storage container generate-sas \
  --account-name <account> --name <container> \
  --permissions rwdl --expiry 2026-06-01 \
  --account-key "$RIVET_AZURE_KEY" -o tsv
SAS expiry preflight (added in 0.7.4)
Rivet parses the se= (signed-expiry) field from the token at construction
time — before any network call is made:
-
Already expired — Rivet fails fast with:
Azure SAS token already expired (se=2026-05-21T00:00:00+00:00). Generate a new SAS and re-export.rivet doctorsurfaces this as a named category (sas expired) with theaz storage container generate-sashint, so the operator knows exactly what to do. -
Within 60 minutes of expiry — Rivet logs a
WARNand continues. Useful when a long export was started close to the expiry boundary. -
No
se=field — the token likely uses a stored-access-policy whose expiry is server-side. Rivet accepts it without a warning.
URL-encoded characters in the expiry value (%3A for :, %2B for +)
are decoded automatically, so tokens pasted directly from the Azure portal
or from az storage container generate-sas -o tsv work without manual
editing.
Still planned (future releases)
These auth modes are not yet implemented:
- Service principal (
tenant_id,client_id,client_secret_env) — unattended automation. - Managed identity — Rivet running inside Azure VM / AKS / Functions.
- Connection string (
connection_string_env) — the all-in-oneDefaultEndpointsProtocol=https;AccountName=…;AccountKey=…blob.
Required RBAC
The account holding the key needs to be able to write to the container. Predefined roles that work:
- Storage Blob Data Contributor — read/write objects (recommended).
- Storage Blob Data Owner — adds ACL management on top.
The Azure storage account key path bypasses RBAC entirely and grants
full access to every container in the account — that’s the trade-off
for simplicity. Use SAS token (sas_token_env) for least-privilege
access scoped to one container and time window.
Output keys
Files are uploaded as:
az://{container}/{prefix}{export_name}_{YYYYMMDD}_{HHMMSS}_{mmm}.{format}
This is the single (non-chunked, non-keyset) runner’s naming: the
timestamp carries millisecond precision, and its size-split parts append
_part{N}. Chunked and keyset runs use their own run-unique part names
— see the per-runner naming table in
docs/cloud-destinations.md.
Example: az://my-container/exports/orders_20260521_181423_042.parquet.
The az:// scheme is the HDFS / azcopy convention. Rivet writes the
same string into the manifest’s destination.uri field so downstream
consumers can canonicalise object identities across runs.
Streaming upload
Like S3 and GCS, Rivet streams data directly to Azure Blob without
buffering the entire file in memory. Peak RSS is proportional to
batch_size, not total export size.
Trust contract
Identical to S3 and GCS:
- Manifest written to
<prefix>manifest.json(M1). _SUCCESSmarker written last (M2).--validateand--reconcileconsult the manifest (M5/M6).--resumereconciles cumulative committed rows vs the manifest (M8).- Mid-resume orphans are quarantined via server-side copy + delete
(M9 — opendal 0.55 returns Unsupported on
renamefor Azure Blob, same as S3/GCS).
Verify
rivet doctor --config export.yaml
rivet run --config export.yaml
rivet validate --config export.yaml
Plain-text expected output:
[OK]  Source auth (Postgres)
[OK]  Destination Azure(my-container)

All checks passed.
Troubleshooting
AuthenticationFailed: Server failed to authenticate the request —
account_key_env points to a stale or rotated key, or account_name
doesn’t match the key. Refresh from the Azure portal and re-export.
ConfigInvalid: endpoint is empty — account_name not set and no
explicit endpoint: either. Rivet auto-derives the endpoint from
account_name when endpoint: is unset; supplying neither yields this
error.
connection refused to 127.0.0.1:10000 — Azurite emulator not
running. Start with the Docker command above.
The specified container does not exist — Azure requires the
container to be pre-created (Rivet does NOT auto-create containers, the
same way S3 buckets must exist beforehand):
az storage container create \
  --account-name <account> --name <container> \
  --account-key "$RIVET_AZURE_KEY"
See also
- docs/cloud-auth.md — full cross-cloud auth-flow matrix (S3 / GCS / Azure) with troubleshooting and use-case recommendations.
- docs/destinations/s3.md, docs/destinations/gcs.md — sibling backends, same trust-contract surface.
Stdout Destination
Config block
destination:
  type: stdout
No additional fields required. Data is written directly to standard output.
When to use
- Piping data to other tools (
jq,duckdb,wc -l) - Quick previews without creating files
- Integration with other CLI pipelines
Example: preview as CSV
# preview.yaml
source:
  type: postgres
  url_env: DATABASE_URL

exports:
  - name: preview
    query: "SELECT id, name, email FROM users LIMIT 100"
    mode: full
    format: csv
    compression: none               # no compression for stdout readability
    destination:
      type: stdout
rivet run --config preview.yaml | head -20
Example: pipe to DuckDB
rivet run --config export.yaml | duckdb -c "SELECT count(*) FROM read_csv('/dev/stdin')"
Example: pipe to jq (CSV → JSON lines)
rivet run --config export.yaml | csvjson | jq '.[] | select(.status == "active")'
Notes
- Only one export can use
type: stdoutper config file (multiple exports would intermix output) - CSV output supports only
compression: none—zstd/gzipon a CSV export is rejected at config load. For compressed (binary) stdout output useformat: parquet; keepformat: csvfor human-readable output - Rivet streams to stdout without buffering the full result
- Progress bars and log messages go to stderr, so they don’t interfere with piped data
--validateand--reconcileflags work normally — results are printed to stderr
Verify
rivet doctor --config preview.yaml
Output:
[OK] Destination Stdout (streaming; no preflight needed)
(stdout is a streaming sink — doctor records the check but performs no write probe)
Cloud Destinations
Single-page tour of every destination Rivet ships with: what they have in common, where they differ, and what guarantees you can build downstream infrastructure on top of.
For the per-backend deep dive, read the dedicated pages:
| Backend | Page |
|---|---|
| Local filesystem | docs/destinations/local.md |
| Amazon S3 | docs/destinations/s3.md |
| Google Cloud Storage | docs/destinations/gcs.md |
| Azure Blob Storage | docs/destinations/azure.md |
| Stdout | docs/destinations/stdout.md |
For the credential matrix (env vars, profile files, identity providers), see docs/cloud-auth.md.
The supported destination set is exactly: AWS S3, Google Cloud Storage, Azure Blob Storage, the local filesystem, stdout — plus their loopback dev emulators (MinIO for S3, fake-gcs-server for GCS, Azurite for Azure), which CI exercises. Other S3-compatible services (Cloudflare R2, Wasabi, Backblaze B2), sovereign clouds, and custom-DNS endpoints are untested and not supported; the config-load endpoint guard rejects them by design.
Common output contract
Every non-streaming destination (Local, S3, GCS, Azure) produces the same three artefacts at the resolved prefix on a clean run:
| File | Purpose |
|---|---|
<export>_<timestamp>[_partN].<fmt> | Data parts, run-unique, named per runner: single runs use <export>_<ms-timestamp>[_partN].<fmt> (millisecond stamp); chunked runs use <export>_<timestamp>_chunk<N>_<16-hex-nonce>.<fmt> (second-granularity stamp; uniqueness comes from the random nonce); single-worker keyset runs use <export>_<run_id>_keyset_<seek-tag>.<fmt> (named by the seek cursor, so a crash re-read from the same seek overwrites its part idempotently; the run_id embeds a millisecond stamp); parallel keyset runs (parallel > 1) use <export>_<run_id>_pk_w<worker>_<page>.<fmt> (same run_id stamp); parallel Mongo runs use <export>_<ms-timestamp>_w<worker>_keyset<page>.<fmt> (run-unique via the shared millisecond stamp). <fmt> is parquet or csv. |
manifest.json | ADR-0012 trust contract: every committed part is listed with size_bytes and content_fingerprint. Schema fingerprint and run identity travel here. |
_SUCCESS | Single line xxh3:<16-hex> over the exact bytes of manifest.json. Presence implies M5 (every listed part exists at recorded size). |
The contract is atomic at write boundaries, not at the prefix:
manifest.json is written before _SUCCESS, so an Airflow / CI sensor
that polls for _SUCCESS never sees a half-built manifest. A
HEAD _SUCCESS is cheap enough that downstream consumers should prefer
it over GET manifest.json for the “data ready?” signal.
Schema and resume semantics:
schema.jsonis reserved for a future release (per-run schema snapshot — see the roadmap). Today the schema fingerprint lives insidemanifest.jsonunderschema_fingerprint._quarantine/<run_id>/lands on resume when M9 finds an untracked or corrupt part. The original byte location is preserved under that subtree for forensics.
Authentication modes
Local
No credentials. Permissions come from the OS. Use path: (with
optional {date}/{table}/{export}/{run_id} placeholders) to point
at the output directory.
Amazon S3
| Mode | Fields | Notes |
|---|---|---|
| Static keys | access_key_env + secret_key_env | Plain IAM access key pair. |
| Static keys + session token | access_key_env + secret_key_env + session_token_env | STS / SSO / IAM Identity Center / AssumeRole / MFA. |
| Profile | aws_profile | Reads ~/.aws/credentials / ~/.aws/config like the AWS CLI. |
| Default chain | (none of the above set) | Env, profile, container, EC2/EKS — same precedence as the AWS SDK. |
region: is optional when the SDK can derive one from the profile or env
vars; required otherwise. endpoint: overrides the resolved S3 endpoint.
Only a loopback endpoint (MinIO) is a supported custom-endpoint path; any
non-loopback endpoint (AWS GovCloud, Cloudflare R2, Wasabi, custom domains)
is rejected at config load as an exfiltration guard. The one waiver is
allow_anonymous: true — the anonymous-emulator escape, which sends no
credentials at all; it is not an auth path for those services, which remain
untested / not supported as Rivet destinations
(see cloud-auth.md, “S3-compatible storage”).
Google Cloud Storage
| Mode | Fields | Notes |
|---|---|---|
| Service-account file | credentials_file: /path/to/sa.json | Long-lived service-account JSON. |
| Service-account env | (none set; GOOGLE_APPLICATION_CREDENTIALS exported) | Path to the SA JSON in env. |
| Application Default Credentials | (none set; gcloud auth application-default login) | Local-dev / workstation auth. |
bucket: is required. endpoint: overrides the default storage.googleapis.com.
Azure Blob Storage
| Mode | Fields | Notes |
|---|---|---|
| Account key | account_name + account_key_env | Long-lived storage-account key. |
| SAS token | account_name + sas_token_env | Short-lived, scope-limited credential issued out-of-band. |
| Anonymous | allow_anonymous: true | Azurite emulator and public read-only containers only. |
account_key_env and sas_token_env are mutually exclusive — picking
both is refused at config-load time with a message that names both
fields. account_name is the prefix in
<account>.blob.core.windows.net; an explicit endpoint: takes
precedence over the derived URL, but only a loopback emulator
endpoint (Azurite) is accepted alongside credentials — a non-loopback
endpoint is rejected at config load unless allow_anonymous: true, which
itself cannot be combined with credentials, so sovereign clouds are not
reachable.
The Azure SAS-token body may be pasted with or without the leading ?
— Rivet trims it transparently so sv=…&sig=… and ?sv=…&sig=… are
both accepted.
Future Azure modes (Managed Identity, Service Principal, workload identity federation) are on the roadmap but not yet supported.
Manifest + _SUCCESS
The trust contract is the same on every cloud backend. See ADR-0012 for the formal invariants:
- M1: parts before manifest.
- M2:
_SUCCESScarries the fingerprint of the exactmanifest.jsonbytes — fingerprint drift means something else wrote that prefix. - M5: with
_SUCCESSpresent, every listed part exists at recorded size and content fingerprint. - M6: legacy prefixes (no
manifest.json) are surfaced aslegacy_run: true;rivet validatereturns success without certifying. - M8: resume against a
_SUCCESS-marked prefix is refused without--force; the verifier wants the operator to opt in to re-exporting over a completed dataset. - M9: untracked or corrupt parts encountered on resume are moved
under
_quarantine/<run_id>/rather than deleted.
Resume behavior
rivet run --resume walks the destination prefix, cross-checks against
the state DB and the prior manifest, and decides per-chunk:
- skip — chunk already committed.
- rewrite — chunk was in-progress (or its part is missing); re-export the same key range.
- quarantine — untracked or corrupt object at the chunk’s part path;
move to
_quarantine/<run_id>/and re-export.
Resume preserves both manifest.json and _SUCCESS only after the run
finishes cleanly. An interrupted resume leaves the prior _SUCCESS in
place so an external sensor polling _SUCCESS still sees the most
recent verified dataset.
Validate behavior
rivet validate is the standalone counterpart to rivet run --validate
(see docs/destinations/ for the per-backend nuance). It
never queries the source: only HEAD / GET _SUCCESS /
GET manifest.json against the resolved destination.
Validate flags:
--date YYYY-MM-DD— resolve{date}against the given day instead of today. The flag a “did yesterday’s run land cleanly?” Airflow sensor needs.--run-id <RID>— substitute{run_id}in the destination template (composes with--date).--prefix <STRING>— bypass placeholder resolution and verify exactly that prefix. Refused with multiple exports — see the inline error.
The resolved physical prefix is surfaced in both --format pretty and
--format json output (resolved_prefix) so it’s obvious which bytes
were checked.
Reconcile and repair
| Command | Reads source? | Writes source? | Writes destination? |
|---|---|---|---|
rivet reconcile | yes — one COUNT(*) per partition | no | no |
rivet repair --execute | yes — re-exports flagged ranges | no | yes — under _quarantine/ first if a stale object exists |
Both honor the same placeholder resolver as run and validate.
Quarantine behavior
Path layout under the destination prefix:
<prefix>/
  part-000001.parquet
  part-000002.parquet
  manifest.json
  _SUCCESS
  _quarantine/
    <run_id>/
      part-XXXXXX.parquet   ← evicted object kept verbatim
Quarantine is best-effort: a successful copy followed by a failed
delete leaves the object reachable at both paths. M9 re-trips on the
next resume and the orphan eventually gets moved.
Support matrix
| Destination | Auth | Manifest | _SUCCESS | Resume | Validate | Quarantine |
|---|---|---|---|---|---|---|
| Local | path | ✅ | ✅ | ✅ | ✅ | ✅ |
| S3 | env / profile / session-token | ✅ | ✅ | ✅ | ✅ | ✅ |
| GCS | service-account / env / ADC | ✅ | ✅ | ✅ | ✅ | ✅ |
| Azure | account-key / SAS / anonymous | ✅ | ✅ | ✅ | ✅ | ✅ |
| Stdout | — | — | — | — | — | — |
Known limitations
- Object lifecycle policies — Rivet does not configure retention, lifecycle transitions, encryption-at-rest, or replication rules on the destination. Manage those out-of-band (Terraform, console).
- Incomplete multipart uploads are not aborted on failure — when a
streamed (large-part) upload fails mid-transfer, the multipart upload is
left open: its already-uploaded parts are billed but invisible to
listings, and Rivet currently has no abort call on that error path (a
crash could never run one anyway). Configure an
abort-incomplete-multipart-upload lifecycle rule on every destination
bucket (S3:
AbortIncompleteMultipartUpload, e.g. 7 days; GCS/Azure: the equivalent incomplete-upload cleanup) — this is load-bearing hygiene, not an optimization. - Azure SAS expiry — SAS tokens are short-lived by design. Rivet reads the env var once at process start; a long-running export whose token expires mid-flight will fail at the next write. Pair short SAS validity with appropriately small exports, or use account-key auth.
- Eventual consistency on first list — S3 / GCS / Azure are
read-after-write consistent for new objects but list operations can
lag on some backends. This affects
--resumeonly, which useslist_prefix; the validate path uses targetedHEADrequests and is consistent. - Network egress costs — Rivet does not enforce a destination /
source region affinity. Exporting a 100 GB table from
us-east-1Postgres to aneu-west-1bucket goes the long way around at full egress price. Pin source and destination to the same region for any non-trivial workload.
Reporting trust-contract issues
A trust-contract violation is treated as a security-grade bug. See SECURITY.md for the disclosure channel. Examples:
_SUCCESSpresent, but a part listed inmanifest.jsonis missing._SUCCESSfingerprint disagrees with the bytes ofmanifest.json.manifest.jsonreferences the wrongschema_fingerprintfor the parts at the prefix.- A credential ever appearing in any artefact (
manifest.json,summary.json, journal events, log lines).
Cloud destination authentication
Rivet talks to S3 / GCS / Azure Blob Storage via opendal. Three supported AWS auth flows, three GCS flows, and three Azure flows are documented below, each with the exact rivet config + shell setup, plus a “what NOT to use” note for the common confused-by-AWS-CLI-v2 case.
If your auth path isn’t listed, the rivet error you’ll see most often is one of:
loading credential to sign http request, source: error sending request
for url (http://169.254.169.254/latest/api/token)
That’s the EC2 instance-metadata-service fallback — opendal didn’t find creds in the configured chain and is now trying IMDS, which is unreachable on a developer laptop or non-EC2 host. The fix is always “give opendal the right credentials before it falls through to IMDS”.
AWS S3
Path A — static IAM access key (long-lived)
The classical case: an IAM user has a long-lived (access_key_id, secret_access_key) pair (looks like AKIA...). No session token, no
rotation worries. Best for CI, automation, dedicated rivet IAM users.
Shell:
export RIVET_AWS_ACCESS_KEY=AKIAxxxxxxxxxxxxxxxx
export RIVET_AWS_SECRET_KEY=xxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxx
Rivet config:
destination:
  type: s3
  bucket: my-bucket
  region: eu-north-1
  access_key_env: RIVET_AWS_ACCESS_KEY
  secret_key_env: RIVET_AWS_SECRET_KEY
Path B — temporary credentials with session token (STS / SSO / IAM Identity Center / AssumeRole / MFA / IRSA)
If your access key starts with ASIA... rather than AKIA..., it’s a
short-lived STS token and you MUST also pass the session token,
otherwise S3 rejects every request.
This covers a lot of modern AWS setups:
- AWS IAM Identity Center / AWS Login (
aws configurein AWS CLI v2 → “AWS Login”): credentials live in~/.aws/login/cache/, not in~/.aws/credentials. aws sts assume-rolefor cross-account access.- MFA-protected sessions (
aws sts get-session-token). - EKS IRSA (IAM Roles for Service Accounts) / Pod identities.
- GitHub Actions OIDC / GitLab JWT-based AWS access.
Shell — bridge from any of the above to env vars rivet understands:
# AWS CLI v2 helper that prints export commands:
eval "$(aws configure export-credentials --profile default --format env)"

# Now in this shell session:
#   AWS_ACCESS_KEY_ID=ASIAxxxxxxxxxxxxxxxx
#   AWS_SECRET_ACCESS_KEY=...
#   AWS_SESSION_TOKEN=...
#   AWS_CREDENTIAL_EXPIRATION=2026-05-21T16:33:43+00:00
Rivet config — point all three env-name fields at the env vars the helper just exported:
destination:
  type: s3
  bucket: my-bucket
  region: eu-north-1
  access_key_env: AWS_ACCESS_KEY_ID
  secret_key_env: AWS_SECRET_ACCESS_KEY
  session_token_env: AWS_SESSION_TOKEN
Caveats:
- The token has a short lifetime (often 1 hour). When it expires
re-run
aws configure export-credentials …to refresh. - For long-running pipelines that exceed the token lifetime, prefer Path A (static keys) or run a refresh loop in your scheduler.
- Rivet does NOT ship a daemon-mode that re-reads creds during a run — the token captured at startup is used throughout.
Path C — aws_profile (only for static-key profiles)
Rivet has a aws_profile: <name> config option that uses reqsign’s
AwsDefaultLoader to read credentials from ~/.aws/config +
~/.aws/credentials.
This works only when the named profile carries plain static
aws_access_key_id + aws_secret_access_key lines (the format AWS
CLI v1 wrote, and AWS CLI v2’s “IAM user” mode still writes).
It does not work for AWS Login / SSO profiles that store
short-lived sessions in ~/.aws/login/cache/ — reqsign 0.16’s loader
doesn’t read that format and falls through to IMDS, hanging or failing
with the error quoted above.
If you have an AWS Login profile, use Path B instead.
destination:
  type: s3
  bucket: my-bucket
  region: eu-north-1
  aws_profile: rivet-prod
What NOT to use
- Mixing
aws_profilewithaccess_key_env/session_token_env: the explicit env-var fields take precedence at the opendal level, but this leaves the reqsign default-chain still wired up and can trigger surprise IMDS lookups. Pick one path. AWS_PROFILEenv var alone: rivet doesn’t read it. Either setaws_profile:in the config or use the env-var path.
Google Cloud Storage
Path A — Application Default Credentials (developer laptop)
If you ran gcloud auth application-default login, ADC writes a token
to ~/.config/gcloud/application_default_credentials.json. Rivet
auto-detects this and uses it transparently:
destination:
  type: gcs
  bucket: my-bucket
  prefix: exports/
No credentials_file: needed. See gcs_auth::try_authorized_user_loader
in src/destination/gcs_auth.rs for the detection.
Path B — Service account JSON
For CI / production, point at a service-account key file:
destination:
  type: gcs
  bucket: my-bucket
  prefix: exports/
  credentials_file: /etc/rivet/sa.json
Or via env (GOOGLE_APPLICATION_CREDENTIALS):
export GOOGLE_APPLICATION_CREDENTIALS=/etc/rivet/sa.json
Rivet reads that key file itself and mints the access token in process —
the RFC 7523 jwt-bearer grant (a claim set signed RS256 with the file’s own
private_key, exchanged at https://oauth2.googleapis.com/token). The same
credential is used for the GCS write and for a rivet load --target bigquery
that follows, so both legs run as the SAME identity: the service account, not
whatever human gcloud happens to be logged in as. Rivet logs which one it
resolved at info level (GCS: using ADC service_account credentials as …@….iam.gserviceaccount.com), and BigQuery records it as user_email in
INFORMATION_SCHEMA.JOBS_BY_PROJECT — check there, not in rivet’s output, if
you need to prove it.
No Google Cloud SDK is needed on PATH for either leg. The one credential shape
that still requires gcloud is external_account (workload identity), which
needs an STS token exchange rivet does not implement.
destination:
  type: gcs
  bucket: my-bucket
  prefix: exports/
Path C — Anonymous / emulator
For fake-gcs-server / GCS emulator setups:
destination:
  type: gcs
  bucket: rivet-e2e
  endpoint: http://localhost:4443
  allow_anonymous: true
Rivet disables both VM metadata probing and the standard config-load
chain when allow_anonymous: true so the emulator path works on a
host that has unrelated GCS profiles configured.
Azure Blob Storage
type: azure uses Azure’s “container” terminology — the existing bucket:
field carries the container name (rivet keeps a single field for the
“top-level namespace inside the cloud account” across S3 / GCS / Azure).
Path A — Storage account name + account key
The primary, simplest auth flow. Account key is a long-lived
secret string from the Azure portal (Storage account → Access keys → key1
or key2). Rotate it via the portal; rivet wipes the in-memory copy on
drop via Zeroizing.
Shell:
export RIVET_AZURE_KEY="long-base64-key-from-portal=="
Rivet config:
destination:
  type: azure
  bucket: my-container            # Azure container name
  account_name: mystorageacct      # the `<acct>` in `<acct>.blob.core.windows.net`
  account_key_env: RIVET_AZURE_KEY
account_name is a plain string in YAML — it’s not a secret, it’s the
public DNS-visible name of the storage account (same status as AWS region
or GCS bucket name).
Rivet auto-derives the endpoint from account_name as
https://<account_name>.blob.core.windows.net — operators only need to
set endpoint: for a loopback emulator (Azurite). Both loopback shapes
are accepted: with credentials (account_name: devstoreaccount1 +
account_key_env holding the well-known dev key — the shape the live
Azurite test in CI uses), or with allow_anonymous: true and no
credentials at all (Path B below).
Sovereign clouds (US-Gov, China-Mooncake) and custom DNS fronts are not
currently reachable: a non-loopback Azure endpoint with credentials is
rejected at config load, and allow_anonymous: true cannot be combined
with credentials.
Path B — Azurite emulator / public-read containers
For local development against Azurite:
destination:
  type: azure
  bucket: rivet-e2e
  endpoint: http://127.0.0.1:10000/devstoreaccount1
  allow_anonymous: true
allow_anonymous: true skips both account_name and account_key_env.
Use it only for emulators or genuinely public read-only containers; rivet
will refuse to combine allow_anonymous: true with explicit credentials.
Path C — SAS token
A Shared Access Signature (SAS) token scopes access to a specific
container and time window — useful when you can’t or shouldn’t hand out
the full account key. account_key_env and sas_token_env are
mutually exclusive; rivet refuses a config that sets both.
Shell:
export AZURE_STORAGE_SAS_TOKEN="sv=2021-08-06&ss=b&srt=o&sp=rwdlacupitfx&se=2026-06-01T00:00:00Z&spr=https&sig=..."
Rivet config:
destination:
  type: azure
  bucket: my-container
  account_name: mystorageacct
  sas_token_env: AZURE_STORAGE_SAS_TOKEN
The leading ? is stripped automatically if you paste the token straight
from the Azure portal. Rivet parses the se= (signed-expiry) field at
startup and fails fast on an already-expired token (and warns within 60
minutes of expiry) — see
destinations/azure.md
for the full preflight behaviour.
Not yet supported
These AAD-based flows are on the roadmap but not yet shipped; use Path A or Path C today:
- Service principal (
tenant_id,client_id,client_secret_env) — for unattended automation. - Managed identity — for rivet running inside Azure VMs / AKS / Functions.
- Connection string (
connection_string_env) — the all-in-oneDefaultEndpointsProtocol=https;AccountName=…;AccountKey=…blob.
To bridge a connection string today, extract the AccountKey value into
an env var and use Path A.
S3-compatible storage (MinIO)
Same as AWS Path A above + an explicit endpoint: URL. Static keys
only — STS / temporary credentials are an AWS-specific concept.
destination:
  type: s3
  bucket: rivet-test
  endpoint: http://localhost:9000
  region: us-east-1
  access_key_env: MINIO_ACCESS_KEY
  secret_key_env: MINIO_SECRET_KEY
Cloudflare R2, Wasabi, Backblaze B2 etc. are not supported: they require
a non-loopback endpoint:, which Rivet rejects at config load (a committed
custom endpoint redirects every upload — an exfiltration guard). Only the
loopback MinIO shape above is a validated custom-endpoint path. Rivet has
never been tested against R2 / Wasabi / B2; allow_anonymous: true
technically waives the endpoint guard (static keys still sign), but the flag
targets anonymous emulators and the combination is unvalidated — use it at
your own risk, and verify the upload end-to-end if you do.
Troubleshooting
| Symptom | Likely cause |
|---|---|
loading credential to sign http request, source: error sending request for url (http://169.254.169.254/...) then timeout | IMDS fallback — credentials never resolved. See above sections. |
InvalidAccessKeyId / SignatureDoesNotMatch | Static key + session-token mismatch. If your access_key_id starts with ASIA…, you MUST pass session_token_env too. |
403 Forbidden on PutObject | Region mismatch (key for one region used against another) or insufficient IAM permission (need s3:PutObject, s3:GetObject, s3:DeleteObject, s3:ListBucket for the bucket / prefix). |
connection refused to localhost:9000 | MinIO not running. docker compose up -d minio from the repo root. |
GCS auth works in gcloud but rivet hangs | Likely ADC has expired. Re-run gcloud auth application-default login. |
Azure: AuthenticationFailed: Server failed to authenticate the request | account_key_env points to a stale/rotated key, or account_name doesn’t match the key. Refresh from the Azure portal. |
Azure: connection refused to 127.0.0.1:10000 | Azurite emulator not running. azurite --location /tmp/azurite & or docker run -p 10000:10000 mcr.microsoft.com/azure-storage/azurite. |
Recommended setups by use case
- Local dev → MinIO: Path A static keys,
endpoint: http://localhost:9000. - Local dev → real AWS S3: Path B (export creds via
aws configure export-credentials …). - CI / GitHub Actions → real AWS S3: Path B with OIDC-issued temporary creds (set the env vars from the GitHub
aws-actions/configure-aws-credentialsstep output). - Production / Airflow / Dagster → S3: Path A with a dedicated IAM user, key rotation handled by your secret store.
- Local dev → real GCS: Path A with
gcloud auth application-default login. - Production → GCS: Path B with a service account JSON.
- Local dev → Azurite: Azure Path B (
allow_anonymous: true,endpoint: http://127.0.0.1:10000/devstoreaccount1). - Production → Azure Blob Storage: Azure Path A with
account_key_envsourced from your secret store (Key Vault, doppler, sops, etc.), or Path C with a scoped SAS token. Service Principal / Managed Identity are not yet supported.
Azure auth modes
| Mode | Fields | Notes |
|---|---|---|
| Account key | account_name + account_key_env | Long-lived storage-account key. |
| SAS token | account_name + sas_token_env | Short-lived, scope-limited credential issued out-of-band. |
| Anonymous | allow_anonymous: true | Azurite emulator and public read-only containers only. |
account_key_env and sas_token_env are mutually exclusive — picking
both is refused at config-load time with a message that names both
fields. account_name is the prefix in
<account>.blob.core.windows.net; an explicit endpoint: takes
precedence over the derived URL, but only a loopback emulator
endpoint (Azurite) is accepted alongside credentials — a non-loopback
endpoint is rejected at config load unless allow_anonymous: true, which
itself cannot be combined with credentials, so sovereign clouds are not
reachable.
The Azure SAS-token body may be pasted with or without the leading ?
— Rivet trims it transparently so sv=…&sig=… and ?sv=…&sig=… are
both accepted.
Cloud Permissions
Minimum credentials Rivet needs at each cloud destination — and the
extra capabilities validate, reconcile, and --resume request on
top of write.
For credential wiring (env vars, profiles, identity providers) see
docs/cloud-auth.md. For the trust contract those
credentials produce (manifest, _SUCCESS, quarantine), see
docs/cloud-destinations.md.
Why this is split out
Rivet treats writes and reads asymmetrically:
| Operation | What it touches | Why the permission split matters |
|---|---|---|
rivet run | PUT parts, manifest.json, _SUCCESS. May LIST/HEAD on resume to detect orphan or quarantined parts. | A write-only role is safe for a happy-path job runner that never resumes; add list+head if you ever expect resume. |
rivet validate | HEAD _SUCCESS, GET manifest.json, HEAD each listed part. | Pure read role. Run from a separate principal in CI / monitoring. |
rivet reconcile | Same as validate plus source read for COUNT(*). | Destination read remains pure-read. Source needs the SELECT grants from your normal extraction role. |
rivet repair --execute | Same as run, plus COPY + DELETE if quarantining stale objects (M9). | Adds delete; required for the quarantine path. |
The recommendation: the first principal you create gets full
read+write+list+head+delete on the destination prefix; that single role
covers every Rivet command without mode-switching. Once the workflow
is stable you can split it into a write-bound principal (just run)
and a read-bound principal (validate from a separate Airflow sensor
or monitoring job).
Amazon S3
Required for rivet run
s3:PutObjecton the destination prefixs3:GetBucketLocation(resolved by SDK at startup)
Required for rivet run --resume, rivet validate, rivet reconcile
s3:GetObjecton the destination prefixs3:ListBucketon the bucket scoped to the prefix
Required for rivet repair --execute (with quarantine path)
s3:DeleteObjecton the destination prefix- All of the above
Example IAM policy (least-privilege role for full Rivet surface)
{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "RivetWrite",
      "Effect": "Allow",
      "Action": ["s3:PutObject", "s3:GetObject", "s3:DeleteObject"],
      "Resource": "arn:aws:s3:::my-data-bucket/exports/*"
    },
    {
      "Sid": "RivetList",
      "Effect": "Allow",
      "Action": ["s3:ListBucket", "s3:GetBucketLocation"],
      "Resource": "arn:aws:s3:::my-data-bucket",
      "Condition": {"StringLike": {"s3:prefix": ["exports/*"]}}
    }
  ]
}
Restrict s3:prefix if a single bucket holds multiple unrelated
datasets. Server-side encryption (SSE-KMS) requires
kms:Encrypt/kms:GenerateDataKey on the configured key — not part of
Rivet’s contract; the operator manages it.
Google Cloud Storage
Required for rivet run
storage.objects.createon the destination prefix
Required for rivet run --resume, rivet validate, rivet reconcile
storage.objects.geton the destination prefixstorage.objects.liston the bucket
Required for rivet repair --execute (with quarantine path)
storage.objects.deleteon the destination prefix- All of the above
Predefined roles
The closest fit for the full surface is Storage Object Admin
(roles/storage.objectAdmin). For pure-write workloads, Storage
Object Creator (roles/storage.objectCreator) is sufficient but
breaks --resume and every read-side command.
For least-privilege, prefer a custom role with the four explicit
permissions above scoped to the bucket via IAM conditions on
resource.name.
Azure Blob Storage
Azure has two permission models depending on credential mode:
Account key (account_key_env)
Bypasses RBAC. The key holder has full access to every container in the storage account — read, write, list, delete, set ACLs. Convenient but blunt; use SAS for least-privilege.
SAS token (sas_token_env)
Token-scoped permissions. Generate with the minimum set:
| Permission flag | Why Rivet needs it |
|---|---|
r (read) | validate, reconcile, --resume |
w (write) | run |
d (delete) | repair --execute quarantine path |
l (list) | --resume and validate |
c (create) | run (some Azure flows require both c and w) |
az storage container generate-sas --permissions rwdlc … covers the
full Rivet surface for one container and one time window.
Azure RBAC (when using AAD-based credentials — future)
Once Service Principal / Managed Identity support lands (see destinations/azure.md § Still planned), the predefined roles will be:
- Storage Blob Data Contributor — read/write/delete blobs (recommended for the full Rivet surface).
- Storage Blob Data Reader — read-only (
validate,reconcilefrom a separate principal).
Local filesystem
Rivet runs as the OS user that invoked it. The operator is responsible for:
- Read+write on the destination directory.
- Enough disk space for the largest individual part and the staged
state file (
.rivet_state.db). Streaming uploads to cloud avoid buffering the full export but still write per-part files locally during chunked runs.
Quick reference table
| Capability | S3 action | GCS action | Azure SAS flag |
|---|---|---|---|
Write parts + manifest + _SUCCESS | s3:PutObject | storage.objects.create | c+w |
Read manifest + parts (validate, reconcile) | s3:GetObject | storage.objects.get | r |
List for --resume and quarantine detection | s3:ListBucket | storage.objects.list | l |
Delete (quarantine via repair --execute) | s3:DeleteObject | storage.objects.delete | d |
| Discover endpoint at startup | s3:GetBucketLocation | n/a (handled by SDK) | n/a |
Verifying the role works
rivet doctor --config rivet.yaml performs a probe write under the
resolved destination prefix (.rivet_doctor_probe). On cloud backends
(S3 / GCS / Azure) the probe object is not deleted — the destination
interface is write-only — so a leftover .rivet_doctor_probe is expected;
remove it manually if you want a spotless prefix. A clean doctor run tells
you the credential resolves and has at least write on the prefix. It does
not prove
list/head capabilities; the first rivet run --resume against an
existing prefix is what surfaces missing list permissions.
For a stricter dry-run, follow the manual cloud smoke flow in docs/cloud-smoke-tests.md.
See also
- docs/cloud-auth.md — credential wiring matrix.
- docs/cloud-destinations.md — the trust contract every backend implements.
- docs/destinations/ — per-backend deep dives.
- SECURITY.md — credential handling and redaction guarantees.
Cloud Smoke Tests
This document records the manual real-cloud verification performed before each Rivet release. It is the operator-discipline counterpart to the automated PR CI matrix described in reliability-matrix.md.
Per-PR CI uses MinIO (S3-compatible) and fake-gcs containers. Real S3 / GCS / Azure endpoints are exercised manually here — too expensive and too credential-sensitive to run on every push.
Last manually verified
| Backend | Auth mode | Date verified | Verified by |
|---|---|---|---|
| Local FS | path | continuous (CI) | PR CI |
| S3 | env access key | 2026-05-22 | maintainer |
| S3 | session token (STS) | 2026-05-22 | maintainer |
| S3 | AWS profile | 2026-05-22 | maintainer |
| GCS | ADC / service account | 2026-08-19 | maintainer + assistant (0.24.5 pre-tag) |
| Azure Blob | account key env | 2026-05-21 | maintainer |
| Azure Blob | SAS token env | 2026-05-22 | maintainer |
Update this table as part of the release checklist.
Tested scenarios
For each backend, the smoke run covers:
- Fresh export to an empty prefix —
rivet runproduces parts +manifest.json+_SUCCESS. - Manifest fingerprint round-trip —
_SUCCESSbody matches the xxh3 ofmanifest.jsonbytes. -
rivet validateon the just-finished run — exits 0. -
rivet validate --date YYYY-MM-DDagainst a previous-day prefix — exits 0 (historical anchor). -
rivet validate --prefix <abs-prefix>— bypasses placeholder resolution, exits 0 against the same physical prefix. -
rivet validate --run-id <RID>— re-checks a specific run. - Failed source auth → no URL password in stderr /
summary.json/summary.md/manifest.json/ journal events / log lines. - Failed destination auth → no credential in the same artifact set.
- Cleanup: probe object
.rivet_doctor_proberemoved; no orphaned parts under the test prefix.
Per-backend results
S3 — 2026-05-22
| Scenario | Result | Notes |
|---|---|---|
| Fresh export | ✅ | MinIO + real AWS S3 (us-east-1) |
validate | ✅ | — |
validate --date (historical) | ✅ | Anchor lifts the implicit “today” assumption (v0.7.2) |
validate --prefix | ✅ | — |
| Manifest fingerprint match | ✅ | M2 |
| Auth-failure secret-leak audit | ✅ | URL password redacted; access keys not echoed |
GCS — 2026-08-19 (0.24.5 pre-tag)
Scope decision, recorded rather than implied: this release’s real-cloud smoke
was deliberately LIMITED to GCS. S3 and Azure keep their 2026-05-22/21 dates —
their sessions were expired at smoke time and the release rides the emulator
(MinIO / Azurite) coverage plus the shared CloudDestination path, which this
GCS run exercises for real.
| Scenario | Result | Notes |
|---|---|---|
| Fresh export | ✅ | real GCS bucket rivet-matrix-smoke-…, ADC; release binary |
validate | ✅ | — |
validate --date (historical) | ✅ | — |
validate --prefix | ✅ | prefix taken from validate’s own JSON report |
validate --run-id | ✅ | re-check of the smoke run |
| Auth-failure secret-leak audit | ✅ | probe password absent from stderr + every run artifact |
GCS — 2026-05-22
| Scenario | Result | Notes |
|---|---|---|
| Fresh export | ✅ | fake-gcs + real GCS bucket |
validate | ✅ | — |
validate --date (historical) | ✅ | — |
validate --prefix | ✅ | — |
| Manifest fingerprint match | ✅ | M2 |
ADC vs explicit credentials_file | ✅ | Both paths exercised |
| Auth-failure secret-leak audit | ✅ | Service-account JSON path is logged but contents are not |
Azure Blob — 2026-05-21 (account key) / 2026-05-22 (SAS)
| Scenario | Result | Notes |
|---|---|---|
| Fresh export (account key) | ✅ | RIVET_AZURE_KEY env var |
| Fresh export (SAS token) | ✅ | AZURE_STORAGE_SAS_TOKEN env var; v0.7.2 path |
validate | ✅ | — |
validate --date (historical) | ✅ | — |
validate --prefix | ✅ | — |
Endpoint auto-derive from account_name | ✅ | Regression caught 2026-05-21; covered by azure_destination_auto_derives_endpoint_from_account_name unit test |
| SAS-expiry preflight | ✅ | v0.7.4 — doctor warns when se= is < 60 min; fails when expired |
| Auth-failure secret-leak audit | ✅ | Account key + SAS token redacted |
What is not covered
Manual smoke tests intentionally skip:
- Long-running SAS-expiry mid-export. The preflight catches near-expiry tokens before extraction starts; we do not run a many-hour export against a deliberately short SAS.
- Cross-region network instability. Toxiproxy chaos coverage exists
in PR CI (
live_chaos) but only against MinIO and fake-gcs. - Provider outage or throttling. Documented as a known limitation in cloud-destinations.md § Known limitations.
- Multipart upload interruption beyond what
live_chunked_recoveryexercises against MinIO. - Full IAM permission matrix. Minimum-required permissions are documented in cloud-permissions.md; a systematic least-privilege matrix is roadmap.
- Bucket / container lifecycle policies, encryption-at-rest, replication. Out of scope for Rivet (the operator manages these out-of-band).
How to reproduce
The smoke runner expects environment variables matching each backend’s auth mode (see the per-backend pages under docs/destinations/). At minimum:
# S3 (real AWS bucket, region us-east-1)
export AWS_ACCESS_KEY_ID=AKIA...
export AWS_SECRET_ACCESS_KEY=wJa...
export RIVET_SMOKE_S3_BUCKET=rivet-smoke-${USER}
# Copy an example config to a scratch path and point it at the smoke bucket
cp examples/pg_chunked_s3.yaml /tmp/smoke-s3.yaml
# edit /tmp/smoke-s3.yaml: set `bucket:` to $RIVET_SMOKE_S3_BUCKET
rivet doctor --config /tmp/smoke-s3.yaml
rivet run    --config /tmp/smoke-s3.yaml
rivet validate --config /tmp/smoke-s3.yaml
rivet validate --config /tmp/smoke-s3.yaml --date "$(date -u +%Y-%m-%d)"
# The resolved prefix comes from validate's own JSON report — the run
# summary (.rivet/runs/<id>/summary.json) does not record it.
rivet validate --config /tmp/smoke-s3.yaml --prefix "$(rivet validate --config /tmp/smoke-s3.yaml --format json | jq -r '.exports[0].resolved_prefix')"
Equivalent recipes for GCS and Azure live under
examples/ (pg_full_azure_sas.yaml,
mysql_full_azure_sas.yaml, etc.).
Reporting smoke-run failures
If a smoke run regresses on a clean checkout, file an issue tagged
smoke-regression and include:
- The exact backend / auth mode that failed.
- The release tag or commit SHA.
- The
rivet doctorandrivet runoutput (with credentials redacted — Rivet’s own output should already be clean). - The resolved prefix from the run summary.
Trust-contract violations (manifest fingerprint drift, missing parts under
_SUCCESS, credentials in artifacts) follow the
security disclosure path, not
the public issue tracker.
Best Practices
Practical guidance for using Rivet’s resource-aware extraction capabilities. These guides go beyond the reference documentation to explain why settings matter and when to use them.
The tuning and compression settings shown here apply to every Rivet source
(PostgreSQL, MySQL, SQL Server, MongoDB) and every mode (full, incremental,
chunked, time_window, cdc) — the quick-start examples below use PostgreSQL +
incremental only for concreteness. Quality checks are the exception: on the
multi-part runners (chunked, keyset, parallel-Mongo) only row_count bounds are
enforced; null_ratio_max and unique_columns are single-runner only (each part
processes independently). See quality-checks.md.
| Guide | What it covers |
|---|---|
| Resource-aware extraction | Memory budgets, batch cap policies (warn/fail/auto_shrink), RSS formula |
| Parquet tuning | Row group strategies, target sizes, downstream read implications |
| Compression profiles | Profile-to-codec mapping, CPU/size trade-offs, when to use each |
| Quality checks | Row count gates, null ratio, uniqueness tracking, unique_max_entries cap |
| Low-memory runners | Settings for 512 MB–4 GB hosts; auto_shrink guarantees and caveats |
| Gentle SQL Server extraction | Easy on the source DB and the worker; why chunk_size (not chunk_size_memory_mb) on MSSQL — config: rivet_mssql_gentle.yaml |
| Recovery and resume | --resume semantics, crash recovery, state inspection |
| Benchmark methodology | How to run E2E and Criterion benchmarks, interpret results, compare versions |
Quick-start recipes
Safe production export
source:
  type: postgres
  url_env: DATABASE_URL
  tuning:
    profile: balanced

exports:
  - name: orders
    query: "SELECT * FROM orders"
    mode: incremental
    cursor_column: updated_at
    format: parquet
    compression_profile: balanced
    destination:
      type: local
      path: ./out
    parquet:
      row_group_strategy: auto
      target_row_group_mb: 128
    quality:
      row_count_min: 1
      unique_columns: [id]
      unique_max_entries: 1000000
    tuning:
      max_batch_memory_mb: 256
      on_batch_memory_exceeded: warn
Low-memory runner (≤ 512 MB RAM)
tuning:
  profile: safe
  max_batch_memory_mb: 64
  on_batch_memory_exceeded: auto_shrink
parquet:
  row_group_strategy: auto
  target_row_group_mb: 32
  max_row_group_mb: 64
compression_profile: fast
CI strict mode
tuning:
  max_batch_memory_mb: 128
  on_batch_memory_exceeded: fail
quality:
  row_count_min: 100
  unique_columns: [id]
  unique_max_entries: 500000
Resource-Aware Extraction
Rivet gives you explicit controls over how much memory a single export is allowed to use. This guide explains the mental model, the available knobs, and the recommended defaults for common scenarios.
The two memory budgets
Rivet operates with two independent memory boundaries:
| Boundary | Config key | What it measures | When it fires |
|---|---|---|---|
| Process RSS guard | tuning.memory_threshold_mb | OS-reported resident set size | Chunked exports only: before starting each chunk, if RSS exceeds (strictly >) the threshold → pause. The parallel chunked runner (non-checkpointed) re-polls every 2 s until RSS drops; sequential and checkpointed chunked paths pause once for a fixed 2–5 s and proceed. Other modes (full, incremental, keyset, mongo-parallel) do not pause on this setting; they only record peak RSS — use max_batch_memory_mb for a per-batch bound in any mode |
| Batch footprint cap | tuning.max_batch_memory_mb | Arrow in-memory buffer size | Before writing, if batch bytes > cap → apply policy |
They are complementary, not redundant:
- RSS guard (
memory_threshold_mb) is a late, coarse signal — the OS has already committed the memory. - Batch cap (
max_batch_memory_mb) is an early, precise signal — it measures the Arrow buffer before I/O.
For predictable memory use, set both.
Batch memory cap policies
When a batch exceeds max_batch_memory_mb, the on_batch_memory_exceeded
policy determines what happens:
| Policy | Effect | When to use |
|---|---|---|
warn (default) | Log the overage with a suggested batch_size, continue. | Development, observability without blocking. |
fail | Exit non-zero immediately. | CI pipelines where oversized batches indicate a config error. |
auto_shrink | Recursively split the batch in half until each sub-batch fits, then write sub-batches. Row count and output are identical. | Low-memory runners where you cannot predict row width in advance. |
auto_shrink is the safest choice for wide or skewed tables. It adds CPU
overhead from the extra Arrow slicing, but total output is always correct.
Recommended configurations
Production default — shared database
tuning:
  profile: balanced
  max_batch_memory_mb: 256
  on_batch_memory_exceeded: warn
Strict CI pipeline
tuning:
  max_batch_memory_mb: 128
  on_batch_memory_exceeded: fail
Any batch that would exceed 128 MB is a sign that batch_size is too large for
the table width. The pipeline fails fast rather than silently consuming memory.
Low-memory runner (≤ 512 MB RAM)
tuning:
  profile: safe
  max_batch_memory_mb: 64
  on_batch_memory_exceeded: auto_shrink
auto_shrink automatically adapts to unexpected wide rows without operator
intervention.
High-throughput read replica
tuning:
  profile: fast
  batch_size: 100000
  max_batch_memory_mb: 512
  on_batch_memory_exceeded: warn
Understanding batch_size vs max_batch_memory_mb
batch_size is a row count. max_batch_memory_mb is a byte budget. They
interact:
actual_batch_bytes ≈ batch_size × avg_row_bytes
For a narrow numeric table (avg row ~100 B), batch_size: 50000 is
~5 MB — well within any reasonable cap.
For a wide text table (avg row ~10 KB), the same batch_size: 50000 is
~500 MB — a common source of OOM surprises.
Rule of thumb: set max_batch_memory_mb to your desired per-batch budget,
and let auto_shrink handle any table that exceeds it. You only need to tune
batch_size manually when you want to optimise throughput.
auto_shrink guarantees
When auto_shrink splits a batch:
- Row count is preserved. Total rows exported equals source rows queried.
- No duplicate rows. Each row appears in exactly one sub-batch.
- Cursor correctness. For incremental exports, the cursor advances to the last row of the original batch, not the last sub-batch. This ensures the second run does not re-export rows.
- File splitting is unaffected.
max_file_sizeboundaries are computed per sub-batch write, so file splits still occur at roughly the configured size. - Quality checks run on sub-batches. Row count, null ratio, and uniqueness checks accumulate correctly across all sub-batches.
Peak RSS formula
peak_rss ≈ max_batch_memory_mb + parquet_writer_buffer + rivet_overhead
parquet_writer_buffer is typically 1–2× the batch footprint during encoding.
rivet_overhead is ~50–150 MB (runtime, connection pool, temp file page cache).
Practical rule: provision at least 3 × max_batch_memory_mb + 256 MB of
available RAM.
See also
- Tuning reference — full parameter list
- Parquet tuning — row group size and its memory implications
- Compression profiles — CPU/size trade-offs
Low-Memory Runners
How to run Rivet reliably on hosts with 1–4 GB of RAM — containers, small VMs, and CI workers.
Numbers in this guide are measured, not estimated. The benchmark below was run against a
content_itemstable: 200,000 rows, 12 columns (TEXT, JSONB, VARCHAR), average row size ~3 KB. All three scenarios exported the same 200,000 rows and produced identical row counts in the output.
The problem with defaults
Rivet’s balanced profile sizes each batch from a 32 MB memory target using the schema’s estimated row width (clamped 1,000–150,000 rows; the static 10,000 applies only when no schema is available). Narrow tables (IDs, timestamps, small text) fetch large batches, wide ones (TEXT/JSONB columns, average row ~3 KB) small — but a larger batch size can still push total RSS above 800 MB:
| Config | batch_size | Peak RSS | Wall time | Output size |
|---|---|---|---|---|
No cap (batch_size: 25000) | 25,000 | 878 MB | 17.2 s | 71 MB (zstd-3) |
Safe baseline (max_batch_memory_mb: 64) | 2,000 (safe profile) | 154 MB | 16.6 s | 71 MB (zstd-3) |
Tight (batch_size: 500, cap 32 MB) | 500 | 111 MB | 16.3 s | 188 MB (snappy) |
The safe baseline cuts RSS by 5.7× with no wall-time regression. The default profile does adapt to table shape, but its 32 MB target and 150k-row ceiling may still exceed a tight host budget — low-memory environments need explicit caps (max_batch_memory_mb, or a fixed batch_size).
The safe baseline
Start here for any host with less than 2 GB available:
source:
  type: postgres
  url_env: DATABASE_URL
  tuning:
    profile: safe
    max_batch_memory_mb: 64
    on_batch_memory_exceeded: auto_shrink
    memory_threshold_mb: 512

exports:
  - name: my_table
    query: "SELECT * FROM my_table"
    format: parquet
    destination: { type: local, path: ./out }
    parquet:                       # per-export setting — lives inside the export entry
      row_group_strategy: auto
      target_row_group_mb: 32
      max_row_group_mb: 64
What each setting does:
| Setting | Effect |
|---|---|
profile: safe | batch_size: 2000, throttle_ms: 500, memory_threshold_mb: 2048 |
max_batch_memory_mb: 64 | Caps each Arrow batch at 64 MB; overrides the profile default |
on_batch_memory_exceeded: auto_shrink | Splits oversized batches instead of failing |
memory_threshold_mb: 512 | On chunked exports, pauses before the next chunk when process RSS exceeds 512 MB — the parallel chunked runner waits until RSS drops; sequential/checkpointed paths pause a fixed 2–5 s once and proceed (other modes only record peak RSS) |
target_row_group_mb: 32 | Writes smaller Parquet row groups — reduces Parquet writer peak RSS |
On a wide-text table (200K rows, avg 3 KB/row, 12 columns), this combination measured 154 MB peak RSS — compared to 878 MB without the cap. Actual RSS on your table will depend on row width and column count; use rivet metrics to validate after the first run.
512 MB host (container / CI)
source:
  tuning:
    profile: safe
    batch_size: 500
    max_batch_memory_mb: 32
    on_batch_memory_exceeded: auto_shrink
    memory_threshold_mb: 256
    throttle_ms: 1000

exports:
  - name: my_table
    query: "SELECT * FROM my_table"
    format: parquet
    destination: { type: local, path: ./out }
    compression_profile: fast    # per-export; snappy: lower CPU overhead than zstd
    parquet:                     # per-export setting — lives inside the export entry
      row_group_strategy: auto
      target_row_group_mb: 16
      max_row_group_mb: 32
On the wide-text benchmark table (200K rows, ~3 KB/row), this config measured 111 MB peak RSS — well within a 512 MB host. Wall time was identical to the uncapped run.
Trade-off: fast (snappy) compresses less aggressively than balanced (zstd-3). On the same table, snappy produced a 188 MB output file vs. 71 MB for zstd-3. If storage cost matters, use compression_profile: balanced even on a constrained host — the CPU cost difference is small (snappy is only ~5–10% faster on text-heavy data).
Wide-table export (TEXT / JSONB heavy)
Wide tables need a smaller batch size and tighter row group targets. Use batch_size_memory_mb to let Rivet calculate batch size from a memory budget rather than a row count:
exports:
  - name: events
    query: "SELECT id, payload, metadata FROM events"
    format: parquet
    destination: { type: local, path: ./out }
    tuning:
      batch_size_memory_mb: 32      # target ~32 MB per batch
      max_batch_memory_mb: 64       # hard cap; auto_shrink if exceeded
      on_batch_memory_exceeded: auto_shrink
    parquet:
      row_group_strategy: auto
      target_row_group_mb: 32
batch_size_memory_mb samples the first batch to estimate row width, then adjusts subsequent batches automatically. This is more reliable than guessing a row count for wide tables.
Parallel exports on memory-constrained hosts
When running multiple exports in parallel (--parallel-export-processes), each worker spawns its own OS process with an independent heap. Budget memory per-worker:
available_ram = total_ram × 0.7     # leave 30% for OS / filesystem cache
ram_per_worker = available_ram / workers
max_batch_memory_mb = ram_per_worker × 0.5   # batch is ~half of worker RSS
Example for 2 GB host, 2 workers:
available = 2048 × 0.7 = ~1400 MB
per worker = 1400 / 2 = ~700 MB
max_batch_memory_mb = 700 × 0.5 = ~350 MB
source:
  tuning:
    max_batch_memory_mb: 256    # conservative, with headroom
    on_batch_memory_exceeded: auto_shrink
    memory_threshold_mb: 512
auto_shrink guarantees and caveats
auto_shrink is the most reliable policy for low-memory environments because it adapts at runtime instead of failing.
Guarantees:
- Total row count is identical to a no-cap run — no rows are lost or duplicated.
- Cursor state and manifest are correct — each sub-batch writes atomically.
- Parquet schema is stable across sub-batches.
Caveats:
- Adds CPU overhead proportional to the split depth. A batch that splits 8 levels (256× fragmentation) adds measurable latency.
- If a single row is wider than
max_batch_memory_mb, the split terminates at a 1-row batch and writes it as-is. This is correct but may produce many small files. - For extremely wide rows (average row >
max_batch_memory_mb), lowerbatch_sizeto 1–100 instead of relying on auto_shrink alone.
For tables where individual rows can be > 64 MB (BLOB-heavy schemas), set max_batch_memory_mb to match the expected maximum row size and accept single-row batches as the floor:
tuning:
  batch_size: 10
  max_batch_memory_mb: 256
  on_batch_memory_exceeded: auto_shrink
Monitoring RSS in production
Rivet always reports peak RSS in the run summary printed to the terminal:
✓ events full 142,380 rows 1 files 71.2 MB 16.6s RSS 154 MB
The RSS value is sampled by a background thread during the run, so it reflects the high-water mark rather than end-of-process RSS.
The same value is stored in the state DB and accessible via:
rivet metrics --config rivet.yaml --export events
Use these to validate that RSS stays within your host budget across different table sizes. The first run on a new table is the most reliable baseline — query planner cache, filesystem buffer, and jemalloc slab warmth all affect subsequent runs.
Quick-reference: settings by host RAM
Measured on a wide-text table (200K rows, ~3 KB avg row, 12 columns incl. TEXT and JSONB). Measured RSS is what you can expect on similarly shaped tables; narrow numeric tables will use less.
| Host RAM | batch_size | max_batch_memory_mb | target_row_group_mb | memory_threshold_mb | Measured RSS |
|---|---|---|---|---|---|
| 512 MB | 250–500 | 16–32 | 16 | 200 | ~111 MB ✓ |
| 1 GB | 500–1000 | 32–64 | 32 | 400 | ~154 MB ✓ |
| 2 GB | 1000–2000 | 64–128 | 32–64 | 768 | ~200 MB est. |
| 4 GB | 2000–5000 | 128–256 | 64–128 | 1536 | ~350 MB est. |
Rows marked ✓ are directly measured. Rows marked “est.” are extrapolated from the measured data points. Actual RSS will be higher on tables with larger average row width (e.g. JSONB blobs, long TEXT fields).
See also
- Resource-aware extraction — memory budgets, policies, RSS formula
- Parquet tuning — row group strategies and downstream implications
- Tuning reference — all tuning parameters and profiles
Gentle SQL Server extraction — easy on the database and the worker
Extracting from SQL Server has two things to be gentle to, and they pull on different knobs:
- The source database — don’t hold long transactions, don’t block writers, don’t add write pressure.
- The rivet worker — don’t let rivet’s own RAM blow up on a wide/large table.
rivet is gentle to the source almost for free, but the worker side needs one
deliberate setting on SQL Server. This page is the why; the copy-paste config
is rivet_mssql_gentle.yaml.
TL;DR
exports:
  - name: big_table
    table: big_table
    mode: chunked
    chunk_column: id          # range-chunk on the PK (or chunk_by_key for UUID/string PKs)
    chunk_size: 50000         # ROW COUNT — bounds rivet's RAM. NOT chunk_size_memory_mb.
    parallel: 1               # sequential = gentlest to the source
    chunk_checkpoint: true    # resumable
source:
  environment: production     # Balanced profile: gentler batch/throttle/retry defaults
The one rule that matters: on SQL Server, set chunk_size (rows) explicitly;
do not use chunk_size_memory_mb. Everything else is the usual chunked export.
Gentle to the source — what rivet does, and the lever you have
Measured against live SQL Server 2022 (the cross-tool harness —
dev/bench/smoke.py --engine mssql, results in
report.html), a properly chunked
rivet export is a quiet tenant:
| Signal | rivet (chunked) | Why |
|---|---|---|
| Longest open transaction | 0 ms | each chunk is an autocommit SELECT, no BEGIN TRAN |
| Log Flush Waits delta | 0 | rivet only reads — zero write pressure |
log_reuse_wait_desc | NOTHING | rivet pins nothing back from log truncation |
| Peak lock count | 3–4 | shared locks released as each chunk scans (READ COMMITTED) |
The lever: environment: production (or replica). It selects the
Balanced tuning profile — gentler batch/throttle/retry defaults.
environment: local (the default for dev) does not throttle.
The OPT-2 back-pressure governor is a separate, explicit opt-in: it arms only
when you set tuning.adaptive: true and parallel > 1 (with parallel: 1
there is no worker to shed). When armed, on SQL Server it samples
Log Flush Waits/sec — the _Total row of sys.dm_os_performance_counters —
and sheds a concurrent worker when that counter rises, so a source someone
else is hammering slows rivet down instead of the other way round.
Read the table above together with this: Log Flush Waits delta = 0 for a
rivet export is exactly why it is the governor’s signal. It measures redo-
write pressure, which a read-only export cannot inflate — so the governor
can only ever be moved by foreign write traffic, and rivet’s own reads can
never talk it into shedding its own workers. An earlier version sampled the
tempdb-spill counters Workfiles Created/sec + Worktables Created/sec
instead; because a large chunked read spills to tempdb by design, the
governor read its own exhaust and walked parallelism 4→3→2→1 without ever
recovering (a field pool run lost 1h48m to it). That implementation is gone.
The practical consequence: the governor does not react to rivet’s own tempdb
spills. If your export is the thing straining tempdb, the levers are
tuning.batch_size and tuning.max_batch_memory_mb (and a smaller
chunk_size), not adaptive.
Caveat — isolation. rivet reads under SQL Server’s default READ COMMITTED. It does not downgrade to
NOLOCK/ snapshot isolation, so on a table under heavy concurrent OLTP writes the per-chunk shared locks can briefly contend. If that matters more than read-consistency, enable RCSI on the database. Lock-light read options inside rivet are roadmap.
Gentle to the worker — batch_size bounds RSS, not chunk_size
The SQL Server engine streams the result set: it consumes rows from the
server incrementally and emits an Arrow batch every tuning.batch_size rows,
never holding more than one batch in memory (the SQL Server analogue of the
PostgreSQL cursor’s FETCH N). So:
peak RSS ≈
batch_size× avg_row_bytes — independent ofchunk_size.
That splits the two knobs cleanly:
batch_sizeis the memory lever.chunk_sizeis now only the file-count lever (one part file per chunk). A largechunk_size— ormode: full— gives few large files and still runs at low RSS.
Measured live against SQL Server 2022, exporting content_items
(2 000 000 rows × ~5 KB heavy text):
| config | wall | peak RSS | files |
|---|---|---|---|
mode: full (streamed, one file) | 8m03s | 171 MB | 1 |
chunk_size: 5000 | 8m15s | 101 MB | 400 |
One file and ~170 MB at 2 M heavy rows. Before streaming, mode: full
buffered the whole table (~10 GB → OOM) and the only way to bound memory was a
tiny chunk_size → hundreds of tiny files. Now you pick chunk_size purely for
the downstream file layout; memory stays put.
Sizing the two knobs
-
batch_size(RAM): peak RSS ≈batch_size× avg_row_bytes. Lower it for wide rows.Row shape avg row batch_sizefor ~100 MB/workernarrow (ints/dates) ~0.1 KB leave the profile default typical (mixed cols) ~1 KB ~50 000 wide / heavy text ~5 KB ~10 000 -
chunk_size(files): ≈ rows ÷ desired file count. Bigger = fewer, larger files; memory is unaffected.mode: full= one file.
Skip
chunk_size_memory_mbon SQL Server: introspection returns noavg_row_bytes, so it can’t size by bytes (it falls back to ~500 k-row chunks). With streaming that no longer blows up memory, butchunk_size(files) +batch_size(RAM) are the honest levers.
Verify it
- Worker: run under
/usr/bin/time -v(orgtime -v) and watch Maximum resident set size — it should trackbatch_size × row_bytes, flat acrosschunk_sizeand table size. - Source: run the harness (
smoke.py --engine mssql) — its harm matrix reports longest open txn, lock count, and worker-time delta during a live export.
Roadmap
- ✅ Streaming export — the engine now consumes the result set incrementally
and emits one
batch_sizebatch at a time, so RSS is bounded bybatch_size, notchunk_size. (Was:into_first_resultmaterialised the whole chunk.) - ◻
avg_row_bytesfrom MSSQL introspection sochunk_size_memory_mbcan size by bytes (add a row-size probe tointrospect_mssql_table_for_chunking). Lower priority now that streaming bounds memory regardless. - ◻ Lock-light reads (RCSI / snapshot opt-in) for sources under heavy concurrent OLTP writes.
Parquet Tuning
Rivet writes Parquet using Apache Arrow’s ArrowWriter. How rows are grouped
within the file — and how large each group is — affects peak memory during
write, compression ratio, and downstream read performance.
What is a row group?
A Parquet file is divided into row groups: horizontal slices of the table. Each row group is compressed and encoded independently.
┌─────────────────────────────────────┐
│  Parquet file                       │
│  ┌───────────────────────────────┐  │
│  │  Row group 1 (e.g. 100K rows) │  │
│  └───────────────────────────────┘  │
│  ┌───────────────────────────────┐  │
│  │  Row group 2 (e.g. 100K rows) │  │
│  └───────────────────────────────┘  │
│  ...                                │
└─────────────────────────────────────┘
Row group size is the most important Parquet tuning parameter for Rivet because it determines how much Arrow data is buffered in memory before each flush.
Why the library default can be dangerous
Without explicit row group configuration, ArrowWriter uses a default limit of
1 048 576 rows per row group. For narrow tables this is fine (~100 MB). For
wide tables (large TEXT, JSONB, BYTEA columns) the same 1M-row group can
consume 10–50 GB of writer memory before it is flushed.
Rivet’s parquet.row_group_strategy: auto uses the Arrow schema to estimate
row width and choose a row count that targets a configurable memory budget.
Strategies
parquet:
  row_group_strategy: auto          # schema-based estimate (recommended)
  row_group_strategy: fixed_rows    # exact row count per group
  row_group_strategy: fixed_memory  # same math as auto — alias for clarity
auto (recommended)
Rivet estimates avg_row_bytes from the Arrow schema field types and computes:
rows_per_group = target_row_group_mb × 1024² / avg_row_bytes
A minimum of 1 000 rows per group is always applied (protects against
pathologically wide schemas). The result is computed once from the schema in
on_schema and held constant for the export.
Accuracy note: schema-based estimation assumes average-width values. For
columns with high variance (TEXT, JSONB) the actual group size may be larger
or smaller than the target. This is an advisory target, not a hard guarantee.
fixed_rows
Use when you need exact control over row group count or size, typically for downstream tooling that benefits from fixed chunk sizes.
parquet:
  row_group_strategy: fixed_rows
  row_group_rows: 100000
fixed_memory
Identical math to auto (target_row_group_mb drives the calculation). Useful
as a self-documenting alias when intent is memory-driven.
Choosing a target
| Target | Best for | Trade-offs |
|---|---|---|
| 32 MB | Wide tables, low-memory runners | More row groups, lower peak write RSS, possibly weaker compression |
| 64 MB | Wide text/JSON tables, production default for skewed data | Balanced RSS and compression |
| 128 MB | Narrow-to-medium tables, default balanced setting | Good compression, moderate RSS |
| 256 MB | Narrow tables on high-RAM hosts, archive/cold storage | Best compression ratio, highest write RSS |
Configuration examples
Balanced default (most tables)
parquet:
  row_group_strategy: auto
  target_row_group_mb: 128
Wide JSON or text tables
parquet:
  row_group_strategy: auto
  target_row_group_mb: 64
  max_row_group_mb: 128
max_row_group_mb caps the computed group size even if the schema estimate
underestimates actual row width.
Low-memory environment (≤ 512 MB RAM)
parquet:
  row_group_strategy: auto
  target_row_group_mb: 32
  max_row_group_mb: 64
Archive / cold storage (maximise compression)
parquet:
  row_group_strategy: auto
  target_row_group_mb: 256
compression_profile: compact
Exact control for downstream tooling
parquet:
  row_group_strategy: fixed_rows
  row_group_rows: 50000
How row groups interact with auto_shrink
When on_batch_memory_exceeded: auto_shrink is set alongside Parquet row group
tuning, each sub-batch written by auto_shrink is treated as a separate batch
for row group accounting. The row group row count target still applies per
sub-batch.
In practice: if auto_shrink splits a 10 000-row batch into two 5 000-row
sub-batches, each sub-batch gets its own row group (or shares a partial group
with adjacent sub-batches, depending on when the writer flushes).
Downstream read implications
Larger row groups generally improve Parquet scan throughput because fewer group headers need to be read. However, predicate pushdown (column filters) works at row group granularity — smaller groups allow more skipping when only a subset of rows matches the filter.
For warehouse loads (DuckDB, Trino, BigQuery), target_row_group_mb: 128 is a
reasonable default. For ad-hoc analytical queries with selective filters,
smaller groups (32–64 MB) improve selective read latency.
See also
Compression Profiles
Rivet’s compression_profile is a high-level, intent-based way to choose a
compression codec without knowing the specific codec name or level.
Profile-to-codec mapping
| Profile | Codec | Level | Best for |
|---|---|---|---|
none | Uncompressed | — | Debug / scratch, temporary files, downstream re-compression |
fast | Snappy | — | Fast backfills, high-throughput pipelines, read replicas |
balanced | Zstd | 3 | Production default — good compression, predictable CPU |
compact | Zstd | 9 | Storage-sensitive archives, cold storage, network-constrained uploads |
Choosing a profile
none — uncompressed
Use when:
- You are debugging output format or schema issues and want to open the file quickly.
- Downstream tooling re-compresses the file (e.g. S3 server-side compression).
- The file is temporary and will be deleted immediately after processing.
Avoid in production: uncompressed Parquet files are 3–10× larger than Zstd-3 on typical tabular data, increasing storage cost and upload time.
fast — Snappy
Use when:
- Throughput matters more than output size (large backfills, bulk loads).
- The extraction runs on a shared database or low-CPU runner where Zstd overhead is unwanted.
- Downstream query engines read the file frequently and benefit from fast decompression (Snappy is ~2–3× faster to decompress than Zstd).
Snappy produces files ~20–30% larger than Zstd-3 on typical tabular data.
balanced — Zstd level 3 (recommended default)
Use when:
- You want a sensible production default without thinking about the trade-off.
- Extraction runs on dedicated infrastructure (not shared OLTP database).
- Files are stored in S3/GCS and you want reasonable storage costs.
Zstd level 3 delivers ~60–70% compression ratio on typical tabular data with ~2–3× the CPU cost of Snappy. This is the right default for most pipelines.
compact — Zstd level 9
Use when:
- Storage cost or network transfer cost is a primary constraint.
- The pipeline runs infrequently (nightly, weekly) and has CPU to spare.
- Files are cold-stored and rarely read.
Zstd level 9 can deliver 5–15% better compression than level 3, at 3–5× the CPU cost. It is rarely worth using in real-time or latency-sensitive pipelines.
Precedence
compression_profile takes priority over the lower-level compression and
compression_level fields. If you set compression_profile, any explicit
compression or compression_level values on the same export are ignored.
# compression_profile wins — compression: snappy is ignored
compression_profile: compact
compression: snappy # ignored
This ensures profiles are self-contained: once you pick a profile, you do not need to audit individual codec settings.
To use a codec not covered by the four profiles (e.g. Gzip, LZ4), omit
compression_profile and set compression directly:
compression: gzip
compression_level: 6
CSV output
Compression profiles apply only to Parquet format. On a CSV export any
compression_profile other than none is rejected at config-validation
time (rivet check / doctor / run error out with “CSV output does not
support compression_profile: …”). CSV files are always written uncompressed —
omit the field (or set none) and compress after export with gzip, zstd,
etc. if needed.
Configuration examples
Production default
format: parquet
compression_profile: balanced
Fast backfill from read replica
format: parquet
compression_profile: fast
tuning:
profile: fast
batch_size: 50000
Cold storage archive
format: parquet
compression_profile: compact
parquet:
row_group_strategy: auto
target_row_group_mb: 256
Benchmark expectations
Based on typical tabular data (mixed integer, text, timestamp columns):
| Profile | Relative wall time | Relative output size |
|---|---|---|
none | 1.0× (baseline) | 1.0× (largest) |
fast (Snappy) | 1.1–1.3× | 0.3–0.5× |
balanced (Zstd-3) | 1.3–2.0× | 0.2–0.4× |
compact (Zstd-9) | 3–6× | 0.18–0.35× |
Actual numbers depend heavily on data entropy. High-entropy data (UUIDs, hashes, random text) compresses poorly regardless of level. Low-entropy data (repeated values, sequential IDs, timestamps) compresses exceptionally well even at level 3.
Run the cross-tool harness (dev/bench/smoke.py, see docs/bench/README.md) against your own tables for concrete
numbers.
See also
Recovery and Resume
Rivet stores export progress in a SQLite state file (.rivet_state.db) located
next to the config file. This guide covers how to inspect, resume, and reset
export state correctly.
State file location
The state file is always created next to the config file:
./rivet.yaml ← config
./.rivet_state.db ← state (created automatically on first run)
To use a different location, point --config at the desired directory.
Export modes and state
| Mode | What is stored | Resume behaviour |
|---|---|---|
full | Completed file list (manifest) | No resume needed — re-run starts a fresh export |
incremental | Last cursor value | Re-run starts from where it left off |
chunked | Per-chunk completion status | --resume continues from the last completed chunk |
time_window | Nothing — no cursor is stored | Each re-run re-evaluates the rolling window from NOW(); windows overlap by design |
cdc | Log position (PostgreSQL slot / MySQL binlog checkpoint / SQL Server LSN / MongoDB resume token) | Resumes streaming from the last committed change position |
--resume for chunked exports
--resume is only meaningful for chunked mode with chunk_checkpoint: true
(not the default — set it so progress is recorded per chunk). It requires an
in-progress (not yet completed) checkpoint run in the state file. On a
full/incremental export --resume has no effect and warns.
Resume an interrupted export
# Start the export
rivet run --config rivet.yaml --export big_table
# If it was interrupted, resume it
rivet run --config rivet.yaml --export big_table --resume
What happens if no checkpoint exists
If --resume is called without a prior in-progress run, Rivet exits non-zero
with a clear message:
error: --resume requires an in-progress chunked export in state;
run without --resume to start a fresh export.
Do not use --resume to start a fresh export. It is only for continuing
interrupted runs.
What happens after a completed export
After a chunked export completes normally, --resume also exits non-zero:
error: --resume found a completed export (not in-progress);
use `rivet run` (without --resume) to start a new run.
This prevents accidentally treating a completed export as resumable.
--resume on full or incremental mode
--resume is silently validated for full/incremental exports — a plan
validation warning is emitted:
[resume-no-checkpoint] export 'X': --resume has no effect on full/incremental
exports. Remove --resume to suppress this warning.
The export proceeds normally. The flag is ignored.
Inspecting state
rivet state show --config rivet.yaml
This shows the current cursor value for each incremental export. For chunk
completion status use rivet state chunks --config rivet.yaml --export big_table,
and for per-run history (rows, bytes, duration, peak RSS) use
rivet metrics --config rivet.yaml.
Resetting state
Reset cursor for incremental exports
rivet state reset --config rivet.yaml --export incremental_export
The next run will re-export all rows from the beginning.
Reset chunk state for chunked exports
rivet state reset-chunks --config rivet.yaml --export big_table
After reset, the next rivet run (without --resume) starts fresh from
chunk 0.
Important: After reset-chunks, do not use --resume — there is no
checkpoint to resume from.
Common operator mistakes
Mistake 1: Using --resume after reset
rivet state reset-chunks --config rivet.yaml --export big_table
rivet run --config rivet.yaml --export big_table --resume # WRONG
Fix: omit --resume after a reset.
rivet run --config rivet.yaml --export big_table # correct
Mistake 2: Using --resume to start a fresh chunked export
# First run ever — no state exists
rivet run --config rivet.yaml --export big_table --resume # WRONG
Fix: do not use --resume on the first run.
Mistake 3: Pointing to a different config file for resume
The state file is tied to its config directory. If you copy the config to a new location, the state file is not copied with it — the resumed export starts fresh.
Crash recovery
If the process is killed mid-export:
-
Incremental — the cursor is committed once per run, after the run’s manifest is durable. A crash mid-export leaves the cursor at the previous run’s value, so re-running re-exports the whole window — into new, uniquely-timestamped part files (names embed a per-run millisecond stamp). Files the crashed run already committed are complete, never partial, and are not overwritten — they remain in the prefix as at-least-once duplicates, which downstream consumers must tolerate (load from the manifest, see semantics.md).
-
Chunked — each chunk is committed to state only after it writes successfully. A crash mid-chunk means that chunk is retried on
--resume. Completed chunks are not re-exported. This holds for both the sequential checkpoint loop (parallel: 1) and the parallel worker pool (parallel: Nwithchunk_checkpoint: true); when one parallel worker panics,reset_stale_running_chunk_tasksresets everyrunningtask back topendingon resume so no work is lost. Coverage:live_chunked_recoveryC1–C4 (see reliability-matrix.md § Failure-mode coverage). -
Full — full exports have no cursor. Re-running after a crash starts from the beginning and writes new, uniquely-timestamped part files; anything the crashed run left behind stays in the prefix as an orphan (no manifest names it) — load from the manifest, or clean orphans with
gc_orphans.
See also
Quality Checks
Rivet can run lightweight data quality assertions at export time and block the pipeline if they fail. Quality checks are declared per-export and run as the data flows through the sink — no separate query is needed.
Available checks
| Check | Field | Severity | Description |
|---|---|---|---|
| Row count minimum | row_count_min | Fail | Export fails if fewer rows than threshold |
| Row count maximum | row_count_max | Fail | Export fails if more rows than threshold |
| Null ratio | null_ratio_max | Fail | Export fails if null fraction exceeds threshold per column. Single-runner only — not enforced on chunked / keyset / parallel-Mongo (each part is independent). |
| Uniqueness | unique_columns | Fail | Export fails if duplicate values detected. Single-runner only — not enforced on the multi-part runners; only row_count bounds run there. |
| Uniqueness cap | unique_max_entries | Warn | Stops tracking after N distinct values; emits a warning |
Row count gates
Useful for detecting empty or truncated source tables:
quality:
row_count_min: 10000 # fail if source returned fewer than 10 000 rows
row_count_max: 5000000 # fail if source returned more than 5M rows (sanity guard)
Both checks fire after all rows are exported, so the partial file is still written. The export exits non-zero and the manifest records the failure.
Null ratio
Useful for detecting upstream data quality regressions:
quality:
null_ratio_max:
email: 0.01 # fail if > 1% of email values are null
user_id: 0.0 # fail if any user_id is null
description: 0.5 # fail if > 50% of descriptions are null
The ratio is computed as null_count / total_rows over the full export.
Columns not listed are not checked.
Uniqueness checks
Rivet uses typed xxHash3-64 internally — numeric and binary columns are hashed from their native bytes without string formatting. This is fast and memory-efficient for most tables.
quality:
unique_columns: [id, transaction_id]
unique_max_entries: 1000000
How uniqueness tracking works
For each row in the export, Rivet hashes the value of each unique_columns
entry and adds the hash to a per-column HashSet<u64>. After all rows are
exported:
duplicates = total_rows - distinct_hashes
If duplicates > 0, the export fails with a message indicating how many
duplicates were found.
Hash collisions
xxHash3-64 has a collision probability of ~10⁻¹⁸ for random data. For practical uniqueness checks this is negligible. For cryptographic guarantees or exact warehouse-grade distinct counting, use a warehouse query directly.
unique_max_entries — the most important setting
Without unique_max_entries, the uniqueness hash set grows unboundedly with
the number of distinct values. For a 50-million-row UUID column, this means
~400 MB of memory just for the hash set.
Always set unique_max_entries when enabling unique_columns.
quality:
unique_columns: [id, email]
unique_max_entries: 1000000 # 1M entries ≈ ~8 MB of hash set memory
When the cap is reached:
- Tracking stops for that column (subsequent values are not hashed).
- A
Severity::Warnquality issue is emitted:"column 'X': uniqueness check capped at N entries; result may be incomplete". - The export still succeeds — the warning is advisory, not a hard failure.
If you need exact uniqueness verification on a 50M-row column, set
unique_max_entries to at least the expected distinct count, or run a
SELECT COUNT(DISTINCT ...) query separately.
Memory cost of unique_max_entries
Each entry in the hash set costs ~8 bytes (a u64). HashSet overhead adds
~40–60% for the allocation and load factor.
unique_max_entries | Approximate memory |
|---|---|
| 100 000 | ~1 MB |
| 1 000 000 | ~10 MB |
| 10 000 000 | ~100 MB |
| 50 000 000 | ~500 MB |
For high-cardinality columns (UUIDs, emails, transaction IDs), a cap of 1 000 000–10 000 000 provides a meaningful uniqueness sample without unbounded memory growth.
Plan validation warning
If unique_columns is configured without unique_max_entries, Rivet emits a
plan validation warning at export time:
[quality-unique-no-cap] export 'orders': unique_columns is configured without
unique_max_entries — uniqueness tracking may grow without bound on large tables.
Add unique_max_entries to cap memory usage.
This warning does not block the export. It is visible in RUST_LOG=warn output
and in the rivet plan summary.
Complete example
quality:
row_count_min: 1000
row_count_max: 10000000
null_ratio_max:
user_id: 0.0
email: 0.02
unique_columns: [user_id, email]
unique_max_entries: 500000
Quality checks as signals, not guarantees
Quality checks in Rivet are fast, in-pipeline quality signals designed to catch common data problems (empty tables, unexpected nulls, duplicate primary keys) without a separate validation query.
They are not a replacement for:
- Warehouse-grade exact distinct counts (
COUNT(DISTINCT ...)) - Schema validation (column types, constraints)
- Referential integrity checks (foreign key validation)
- Statistical distribution checks (min/max/median)
For comprehensive data quality, combine Rivet’s export-time checks with a downstream validation tool (dbt tests, Great Expectations, etc.).
See also
Benchmark Methodology
How to run, interpret, and compare Rivet’s benchmark suites.
Rivet has two benchmark layers:
| Layer | Tool | Purpose |
|---|---|---|
| Micro-benchmarks | Criterion (benches/) | Hot-path throughput, compilation check, per-function regression gate |
| Cross-tool / cross-engine E2E | dev/bench/smoke.py + docs/bench/matrix.yaml | rivet vs 6 other tools on Postgres / MySQL / SQL Server / MongoDB — throughput, peak RSS, source-harm, type fidelity |
Cross-tool / cross-engine E2E harness
The E2E harness compares rivet to duckdb, clickhouse-local, sling, ingestr, dlt,
and odbc2parquet exporting the same fixture to Parquet, and captures what each
tool does to the source (a co-running OLTP probe, longest query/txn, locks,
native engine counters). It is a single source of truth: everything is
driven from docs/bench/matrix.yaml by the runner
dev/bench/smoke.py, which fails if the yaml declares
a metric the code doesn’t capture. See docs/bench/README.md
for prerequisites and docs/bench/report.html for the
rendered results.
# system python has PyYAML + dlt; the homebrew pythons ship a broken pyexpat
/usr/bin/python3 dev/bench/smoke.py --engine postgres --table content_items
/usr/bin/python3 dev/bench/smoke.py --engine mysql --table content_items
/usr/bin/python3 dev/bench/smoke.py --engine mssql --table orders
Fixtures are seeded into a dedicated rivet_bench per engine (via the Rust
seed tool; sizes in matrix.yaml) so the live-test fixtures are untouched.
Three matrices print per run: benchmark, harm, type-loss.
Comparing rivet versions is a special case of the same harness — point
RIVET_BIN (or $PATH rivet) at each build and re-run; the benchmark matrix’s
rows_s / peak_mb columns are the comparison. rivet’s own steelman
(mode: full, tuning.profile: fast, zstd) was chosen this way — a measured +24 %
rows/s from dropping the balanced 50 ms/batch throttle.
Micro-benchmarks (Criterion)
Criterion benchmarks live in benches/ and measure specific hot paths in isolation.
# Run all benchmarks (full Criterion measurement)
cargo bench
# Run a specific group
cargo bench --bench hot_paths
cargo bench --bench resource_aware
# Compile and smoke-check (1 sample, no regression gate)
cargo bench --bench hot_paths -- --warm-up-time 1 --measurement-time 1 --sample-size 10
# Compare to a saved baseline
cargo bench --bench hot_paths -- --save-baseline main
# ... make changes ...
cargo bench --bench hot_paths -- --baseline main
Available benchmarks
| Binary | Group | What it measures |
|---|---|---|
hot_paths | parquet_write_batch | Parquet writer throughput for narrow / wide batches |
hot_paths | quality_uniqueness | Quality uniqueness tracking throughput |
hot_paths | csv_write_batch, hash_column, column_scan, shape_tracking, mysql_parse_time, mysql_int_bytes, mysql_utf8_text_append, csv_binary_hex, csv_timestamp | Remaining hot-path groups (CSV writer, hashing, column scan, shape tracking, MySQL decode paths) |
resource_aware | auto_shrink | Split overhead at different cap levels |
resource_aware | compression_profiles | Per-codec wall time for a 10,000-row batch |
resource_aware | row_group_computation | Row group target computation for narrow / wide schemas |
resource_aware | quality_uniqueness_cap | Uniqueness tracking throughput with and without a cap |
Criterion saves HTML reports to target/criterion/. Open target/criterion/index.html in a browser for violin plots and per-sample distribution.
CI integration
Only the Criterion micro-benchmark layer belongs in CI — it compiles and
smoke-samples the Rust hot paths (a compile/panic check, not a regression gate).
The cross-tool E2E harness is run manually: it needs four live database
engines and per-engine vendor drivers, so it is not a CI job — reproduce it from
docs/bench/README.md and publish
docs/bench/report.html.
To add a micro-bench regression gate in the future, save a Criterion --baseline
from a release tag and add a comparison step to ci.yml.
Interpreting results
Normal variance
E2E runs on shared CI (or a busy laptop) can show ±10–20% variance in wall time and ±5% in RSS depending on filesystem cache warmth and page cache pressure. Run each suite 3 times and take the median for a stable comparison.
When numbers look wrong
| Symptom | Likely cause |
|---|---|
| RSS much higher than expected | Filesystem cache not warm; first run always higher |
| Wall time much higher than expected | Postgres query planner chose a sequential scan; check indexes on bench tables |
Files > 1 unexpectedly | File splitting triggered; check max_file_size (export-level size string, e.g. “512MB”) in the config |
Size(MB) unexpectedly large | Wrong compression profile in the config template |
Relating E2E numbers to rivet plan output
rivet plan shows a narrow–wide memory range for each export:
Batch memory : ~2 MB (narrow) – ~95 MB (wide)
The narrow bound assumes ~200 B/row; the wide bound assumes ~10 KB/row. The E2E benchmarks let you validate which bound your real table shape falls closer to by running with the same config and comparing the measured RSS(MB) against the plan estimate.
See also
- Resource-aware extraction — memory budgets and policies
- Parquet tuning — row group targets and downstream read implications
- Compression profiles — codec mapping and trade-offs
- Low-memory runners — settings for constrained environments
dev/bench/smoke.py+docs/bench/matrix.yaml— the unified cross-tool / cross-engine harnessdocs/bench/report.html— the rendered resultsbenches/— Criterion micro-benchmark sources (Rust hot paths, separate layer)
Last updated: 2026-05-19.
Pilot guide — operator runbook
This folder is for engineers who are evaluating Rivet seriously: they have already run the 5-minute install + first export and now want the full flow on their own database, with production-ready guardrails.
If you have not run a first export yet, do that first — docs/getting-started.md. Come back here when you want to take it further.
“Done” looks like
- Minimum: config validates,
rivet runfinishes, files land where you expect, you can read them back. - Full pilot (chunked + checkpoints): you can also read progression, reconcile against the source, and run targeted repair without surprising the database or storage.
Pick one path
| Goal | Time | Where to start |
|---|---|---|
| Scripted evaluation on a 14-table seeded fixture — prove every feature works end-to-end, no real data risk | ~10 min | Demo quickstart — needs Docker + repo checkout + cargo build + a seed step |
| Full pilot on your own database — discovery → chunked → reconcile → repair → verified | 1–2 sessions | Pilot walkthrough |
| Sign-off on a pilot you’ve already run | ~20 min | UAT checklist |
Don’t mix paths until the first one is green.
Standard pilot order of operations
The walkthrough expands every step with examples, YAML, and commands. Use this list as the order; use the walkthrough for the detail.
Minimum pilot — steps 1–5
Enough for a serious first pass: validated config, successful run, optional plan/apply.
- Read once: Production checklist — access model, TLS, pooler/proxy detection, tuning, destinations. Skim before pointing at production.
- Scaffold:
rivet init→ YAML + optionaldiscovery.json(walkthrough Step 1). - Author config: match mode to the table —
full/incremental/chunked/time_window/cdc. For reconcile + repair later, usechunkedwithchunk_checkpoint: true(walkthrough Step 2). - Preflight:
rivet doctor+rivet checkon the final YAML. - Execute:
rivet plan→rivet runand/orrivet apply(walkthrough Steps 3–4).
Chunked + trusting the data — steps 6–8
Only when you have chunked exports with chunk_checkpoint: true. Skip this block for pure full / simple incremental pilots.
- Verified extraction:
rivet state progression→rivet reconcile→rivet repairif dirty → reconcile again (walkthrough Steps 5–8). Background contract: ADR-0009. - Automate: cron / CI pattern in walkthrough Step 9.
- Sign-off: UAT checklist when you’re ready to call the pilot complete.
Documents in this folder
| Document | Use when |
|---|---|
| demo-quickstart.md | Scripted demo on the 14-table fixture |
| pilot-walkthrough.md | Full flow on your own data (discovery → verified) |
| production-checklist.md | Before production or high-stakes databases |
| uat-checklist.md | Structured sign-off after the pilot |
| reconcile-runbook.md | Verify an export against the live source with SQL only |
| rivet-vs-cursor-pipeline.md | Like-for-like vs an existing cursor/watermark ELT pipeline |
Full doc index: docs/README.md. Concept glossary (run_id, cursor, chunk, manifest, journal, progression): docs/concepts.md.
Demo Quickstart — Pilot Evaluation in ≈10 Minutes
Where this fits: the Pilot guide explains which doc to use first (quickstart vs demo vs full walkthrough).
A scripted, reproducible end-to-end demo that exercises every post-Epic feature against a pre-seeded fixture. Use this when evaluating Rivet for a pilot: you get a 14-table database, a 12-export campaign, partition-level reconcile, targeted repair, and the full committed/verified progression — all wired together.
For the conceptual tour of the same features with your own data, see pilot-walkthrough.md. For supported database versions and the CI compat matrix, see reference/compatibility.md.
What this demo shows
| Capability | Where it surfaces | ADR |
|---|---|---|
| Metadata-driven discovery | rivet init --discover — ranked cursor + chunk candidates per table | 0006 |
| Source-aware prioritization | rivet plan emits a per-export score, class, and wave | 0006 |
| Campaign-level planning | Multi-export plan includes ordered list + source_group warnings | 0006 |
Cursor policy (coalesce) | Composite cursor COALESCE(updated_at, created_at) for nullable primaries | 0007 |
| Plan / Apply contract | Sealed JSON artifact (PlanArtifact) + staleness + credential redaction | 0005 |
| Chunked + checkpoint | 800k-row audit_log split into chunks, each tracked in state | ADR-0001 I5 |
| Partition reconcile | rivet reconcile re-counts every chunk on the source | 0009 |
| Targeted repair | Inject mismatch → rivet repair --execute fixes only affected chunks | 0009 |
| Committed / verified progression | rivet state progression surfaces both boundaries | 0008 |
Prerequisites
-
Docker Desktop running,
docker compose up -d postgres mysqlfinished healthy. -
Rust toolchain; build once:
cargo build --release --bin rivet cargo build --release --features dev-seed --bin seed(The seeder is gated behind the off-by-default
dev-seedcargo feature — a bare--bin seedbuild errors.) -
python3(used for parsing/pretty-printing JSON artifacts below). The §5 Parquet-schema peek also needspyarrow(pip install pyarrow).
Container quick check:
docker compose ps postgres mysql
0 — Seed the demo fixtures
Two SQL files in demo/ create the 14-table landscape with varied cardinalities, cursor qualities, and source-group scenarios:
# PostgreSQL fixture — ≈2 seconds. Adds 7 tables alongside the bundled dev schema.
PGPASSWORD=rivet psql -h localhost -U rivet -d rivet \
-f demo/setup_demo_tables.sql
# MySQL fixture — ≈10 seconds. Same 7 tables, idiomatic MySQL.
mysql -h 127.0.0.1 -P 3306 -u rivet -privet rivet \
< demo/setup_demo_tables_mysql.sql
# Bundled dev tables + orders_coalesce (composite-cursor fixture) come from the
# Rust seeder — tunable scale.
cargo run --release --features dev-seed --bin seed -- --target postgres \
--users 2000 --orders-per-user 5 --events-per-user 20 \
--page-views 200000 --content-items 20000 \
--sparse-chunk-demo --sparse-chunk-rows 500 --sparse-chunk-id-gap 5000 \
--coalesce-rows 5000 --coalesce-null-ratio 0.35
Base schema first. The seeder fills the bundled dev tables (
users,orders,events,page_views,content_items) — it does not create them. They are created bydev/postgres/init.sql(anddev/mysql/init.sql), which the bundleddocker composeruns automatically the first time each container initializes. So this works against the bundledrivetdatabase out of the box. If you point--pg-url/--mysql-urlat a fresh database instead, apply thatinit.sqlthere first, or the seeder’sTRUNCATEfails withrelation "content_items" does not exist.
Verify the landscape (PostgreSQL):
PGPASSWORD=rivet psql -h localhost -U rivet -d rivet -c "
SELECT relname AS table_name, reltuples::bigint AS est_rows,
pg_size_pretty(pg_total_relation_size(c.oid)) AS total_size
FROM pg_class c JOIN pg_namespace n ON n.oid = c.relnamespace
WHERE n.nspname = 'public' AND c.relkind IN ('r','p')
ORDER BY reltuples::bigint DESC;"
Expected counts (≈): audit_log 800k · metric_samples 400k · transactions 300k · page_views 200k · logs_archive 100k · sessions 50k · events 40k · content_items 20k · email_queue 20k · orders 10k · orders_coalesce 5k · product_catalog 3k · users 2k · orders_sparse 500.
1 — Discovery (rivet init --discover)
export DATABASE_URL='postgresql://rivet:rivet@localhost:5432/rivet'
cd demo && mkdir -p {out,plans}
# Credentials never hit the command line.
../target/release/rivet init \
--source-env DATABASE_URL \
--schema public --discover -o discovery.json
Per-table summary:
python3 <<'PY'
import json
d = json.load(open('discovery.json'))
print(f"{d['scope']}\n")
for t in d['tables']:
top = t['cursor_candidates'][0] if t['cursor_candidates'] else None
top_s = f"{top['column']}({top['score']})" if top else '-'
fb = t.get('suggested_cursor_fallback_column') or '-'
note = '⚠ coalesce' if fb != '-' else ''
print(f"{t['table']:<20} {t['row_estimate']:>7} mode={t['suggested_mode']:<11} "
f"cursor={top_s:<16} fallback={fb:<12} {note}")
PY
Expected: page_views, audit_log, metric_samples, transactions → chunked. orders_coalesce and logs_archive → ⚠ coalesce (automatic hint when the best cursor is nullable and a NOT NULL sibling exists).
2 — The demo campaign (rivet plan)
A curated, 12-export YAML lives at demo/demo_pipeline.yaml with deliberate source_group collisions to trigger the campaign-level warning.
../target/release/rivet plan \
-c demo_pipeline.yaml \
--format json > plans.json
For a multi-export config this emits one pretty-printed JSON array of artifacts (a single object only when there is exactly one export).
Render the embedded campaign block:
python3 <<'PY'
import json
arts = json.load(open('plans.json'))
camp = arts[0]['prioritization']['campaign']
print(f"{'score':>5} {'wave':<4} {'export':<18} {'class':<7} {'cost':<10} {'group':<20}")
for e in camp['ordered_exports']:
sg = e.get('source_group') or '-'
print(f"{e['priority_score']:>5} w{e['recommended_wave']:<3} {e['export_name']:<18} "
f"{e['priority_class']:<7} {e['cost_class']:<10} {sg:<20}")
print('\nSource-group warnings:')
for w in camp['source_group_warnings'] or ['(none)']: print(f" ⚠ {w}")
PY
Expected:
- Wave 1 (score 76–88) — indexed-cursor incrementals:
events,sessions,transactions. - Wave 2 —
orders_coalesce(composite-cursor incremental). - Wave 3 — small full exports plus the lighter chunked ones (
metric_samples,page_views). - Wave 4 — the heaviest chunked exports at the bottom:
audit_logandlogs_archive(reconcile_required + chunking_heavy + degraded verdict). - Warning:
Source group 'replica_primary': 3 exports share this source — stagger large runs.
3 — Plan / Apply (sealed workflow)
Pick one wave-1 export and run it the plan/apply way:
../target/release/rivet plan \
-c demo_pipeline.yaml -e events \
--format json -o plan_events.json
# Verify the artifact does not leak secrets (PA9 — ADR-0005).
grep -c 'password' plan_events.json # ≥ 0 matches as field names; the values are null
grep -E '"password":\s*"[^"]+"' plan_events.json || echo "✅ no plaintext password"
../target/release/rivet apply plan_events.json
Expected: 40000 rows, success, a Parquet in out/, and last_cursor advanced.
4 — Chunked + reconcile + progression
The reconcile-repair GIF above shows the mechanics on a smaller 10k-row fixture; the commands below repeat the same flow on the demo’s 800k audit_log table.
../target/release/rivet run -c demo_pipeline.yaml -e audit_log
# 800000 rows, 4 chunks, ≈3s, `chunk_checkpoint: true` persists per-chunk state.
../target/release/rivet reconcile -c demo_pipeline.yaml -e audit_log
# Partitions: 4 (4 match, 0 mismatch, 0 unknown)
../target/release/rivet state progression -c demo_pipeline.yaml
# audit_log chunked chunk #3 ... chunked chunk #3 ← committed = verified
5 — Composite cursor demo
orders_coalesce and logs_archive have nullable updated_at; the demo YAML declares incremental_cursor_mode: coalesce with cursor_fallback_column: created_at:
../target/release/rivet run -c demo_pipeline.yaml -e logs_archive
# 100000 rows exported; the stored cursor is the max of COALESCE(updated_at, created_at)
# Second run — predicate filters everything out:
../target/release/rivet run -c demo_pipeline.yaml -e logs_archive
# status: success, rows: 0
The synthetic _rivet_coalesced_cursor column never reaches the Parquet file (ADR-0007 CC5):
# Peek at Parquet schema — no _rivet_coalesced_cursor column.
python3 - <<'PY'
import pyarrow.parquet as pq, glob
fn = sorted(glob.glob('out/logs_archive_*.parquet'))[-1]
print(pq.read_schema(fn))
PY
6 — Targeted repair (simulated mismatch)
Inject a 50k-row delete that flows through reconcile → repair:
# 1) Break chunk 2 on the source:
PGPASSWORD=rivet psql -h localhost -U rivet -d rivet -c \
"DELETE FROM audit_log WHERE id BETWEEN 400001 AND 450000;"
# 2) Reconcile surfaces exactly one dirty partition:
../target/release/rivet reconcile -c demo_pipeline.yaml -e audit_log
# Partitions: 4 (3 match, 1 mismatch, 0 unknown)
# Repair candidates: chunk 2 [400001..600000] — diff=-50000
# 3) Dry-run the repair plan (RR2 — nothing executes without --execute):
../target/release/rivet repair -c demo_pipeline.yaml -e audit_log
# Actions: 1 — chunk 2 [400001..600000]
# 4) Execute — only the flagged chunk range runs, new file written alongside:
../target/release/rivet repair -c demo_pipeline.yaml -e audit_log --execute
# Summary: planned 1 · executed 1 · rows 150000
RR4 holds: last_committed_* in rivet state progression is not re-stamped by repair. The committed boundary tracks first-write coverage; verified re-advances only if a subsequent clean reconcile runs.
7 — MySQL parity (same demo, different engine)
Everything above works on MySQL too. One command sets up a parallel stack:
export DATABASE_URL='mysql://rivet:rivet@localhost:3306/rivet'
../target/release/rivet init \
--source-env DATABASE_URL \
--schema rivet --discover -o discovery_mysql.json
../target/release/rivet plan -c demo_pipeline_mysql.yaml --format json \
> plans_mysql.json
A few MySQL notes:
- The same
source_groupwarnings fire when 3+ exports share a replica. rivet checkgives weaker cursor signals on MySQL than on PostgreSQL (MySQLEXPLAINdoesn’t always annotatetype=rangefor indexed incrementals), so some scores shift. This is an observable difference, not a bug.- Composite cursor SQL uses backticks (
`updated_at`) instead of double-quoted identifiers — same contract, different dialect (ADR-0007 CC9).
Cleanup
# Destroy demo output + state, keep containers. (`.rivet` holds the per-run
# reports each run writes to demo/.rivet/runs/<run_id>/{summary.md,summary.json}.)
rm -rf demo/{out,out_mysql,plans,*.json,*.jsonstream,.rivet_state.db,.rivet}
# Drop the demo tables (keeps the dev base schema).
PGPASSWORD=rivet psql -h localhost -U rivet -d rivet -c "
DROP TABLE IF EXISTS transactions, audit_log, sessions, product_catalog,
logs_archive, email_queue, metric_samples CASCADE;"
mysql -h 127.0.0.1 -P 3306 -u rivet -privet rivet -e "
DROP TABLE IF EXISTS transactions, audit_log, sessions, product_catalog,
logs_archive, email_queue, metric_samples,
orders_coalesce;"
What to report after the demo
For a pilot sign-off (pilot/uat-checklist.md) the demo above exercises every box; record:
- Output of
rivet state progressionbefore and after each stage. - The reconcile report (saved JSON from step 4 / 6) for audit.
- The
planartifact used by apply (confirms PA9 redaction, PA6 fingerprint). cargo testresult from your own build (offline suite, no Docker needed — see reference/testing.md for the current per-release count).
If any command above produces output unexpectedly, capture the full log with RUST_LOG=debug — that level includes the effective SQL queries and per-chunk state transitions.
Pilot Walkthrough — From Discovery to Verified Repair
How to use this page: work the sections in order (Steps 1 → 9). Each step lists the exact Rivet commands and the contracts they satisfy. For a one-page “what to run in what order” summary, start at Pilot guide (README).
This is the end-to-end pilot guide that exercises the full contract stack: discovery, plan/apply, prioritization, chunked extraction with checkpoint, partition-level reconcile, targeted repair, and the committed/verified progression boundary.
If you just want to export one table, start with Getting Started (covers both Postgres and MySQL). This walkthrough is for pilots preparing a real production rollout.
Contracts referenced below: PA1–PA8 plan/apply · CC1–CC10 cursor policy · PG1–PG8 progression · RC1–RC6 / RR1–RR8 reconcile / repair.
Prerequisites
- Postgres or MySQL you can reach (structured creds or a
DATABASE_URL). rivet --versionworks.- A writeable local path or an S3/GCS bucket for output.
The repo ships a docker-compose.yaml with both engines pre-seeded by dev/postgres/init.sql / dev/mysql/init.sql and the bench seed tool (cargo run --features dev-seed --bin seed — the seeder is gated behind the off-by-default dev-seed cargo feature, so a bare cargo run --bin seed errors). Follow along on that if you don’t have a source handy.
docker compose up -d postgres mysql
cargo run --features dev-seed --bin seed -- --target both # postgres + mysql: fills users, orders, events, page_views, content_items, orders_coalesce
# orders_sparse is created and truncated but left EMPTY — add --sparse-chunk-demo to fill it
export DATABASE_URL='postgresql://rivet:rivet@localhost:5432/rivet'
For a bigger / richer fixture (14 tables, source-group conflict scenarios, composite cursor) use the dedicated demo fixture — see demo-quickstart.md.
Production note — TLS and credential handling
Everything below works with local-dev settings. For a real pilot against a managed database:
-
TLS is on by default when you set
tls:. The recommended shape:source: type: postgres url_env: DATABASE_URL tls: mode: verify-full ca_file: /etc/ssl/certs/rds-ca-2019-root.pem # if your CA is not in system trustSee reference/config.md § TLS for the full matrix (
disable|require|verify-ca|verify-full). Omittingtls:is only allowed for loopback hosts (localhost / 127.0.0.0/8 / ::1), which connect in plaintext; against any remote (non-loopback) host rivet refuses the connection before any network I/O with a “TLS required” error. To opt into remote plaintext you must settls: { mode: disable }explicitly. -
Never put the DB URL on the command line in prod. Use
--source-envforrivet init:export DATABASE_URL='postgresql://…' rivet init --source-env DATABASE_URL --schema public --discover -o discovery.jsonAnd use
url_env:/password_env:in YAML. See reference/init.md.
Step 1 — Discovery (rivet init)
Scaffold a YAML from the live schema and, in parallel, emit a machine-readable discovery artifact for review or automation.
# YAML scaffold for a whole schema
rivet init --source-env DATABASE_URL --schema public -o pilot.yaml
# JSON discovery artifact — per-table ranked cursor + chunk candidates,
# row estimate, on-disk size, coalesce hints when `updated_at` is nullable.
rivet init --source-env DATABASE_URL --schema public --discover -o discovery.json
Inspect discovery.json to decide modes and cursor policies:
jq '.tables[] | {table, suggested_mode, best_cursor: (.cursor_candidates[0].column // null),
coalesce_fallback: .suggested_cursor_fallback_column, notes}' discovery.json
Step 2 — Write a chunked + checkpoint config
For any non-trivial table, use chunked mode with chunk_checkpoint: true. Checkpointing is what unlocks reconcile, repair, and progression.
source:
type: postgres
url_env: DATABASE_URL
tuning:
profile: balanced
exports:
- name: orders
query: "SELECT id, user_id, product, price, status, updated_at FROM orders"
mode: chunked
chunk_column: id
chunk_size: 100000
chunk_checkpoint: true # required for reconcile/repair/progression
parallel: 2
format: parquet
destination:
type: local
path: ./output
columns:
price: decimal(10,2) # bare NUMERIC needs an explicit precision/scale
# Composite cursor fixture — `updated_at` is nullable, fall back to `created_at`.
- name: orders_coalesce
query: "SELECT id, product, price, updated_at, created_at FROM orders_coalesce"
mode: incremental
cursor_column: updated_at
cursor_fallback_column: created_at
incremental_cursor_mode: coalesce # ADR-0007 CC1
format: parquet
skip_empty: true
destination:
type: local
path: ./output
columns:
price: decimal(10,2)
Validate structural constraints:
rivet check -c pilot.yaml
rivet doctor -c pilot.yaml
Step 3 — Plan (see the full intent)
rivet plan seals the execution intent into an auditable artifact (ADR-0005 PA1) and embeds source-aware prioritization (ADR-0006) when multiple exports are planned.
rivet plan -c pilot.yaml
A single-export plan prints a Priority block; a multi-export plan adds a Campaign block with waves and source_group warnings (if set). A JSON artifact is what CI/CD pipelines should consume:
rivet plan -c pilot.yaml --format json -o plan.json
For a multi-export config, plan is read-only: it prints the recommended schedule and never touches your config. Pass --annotate-waves to write the wave: and parallel_safe: fields into the config in place (preserving your comments and field order) — visible, hand-editable, and consumed by rivet apply <config> in Step 4. The flag replaces the whole schedule with the plan’s recommendations, absent fields and hand-tuned ones alike, so review the printed schedule first. The plan suggests; you stay in control.
rivet plan -c pilot.yaml # review the schedule (read-only)
rivet plan -c pilot.yaml --annotate-waves # then persist it into the config
What the plan guarantees (PA1–PA8):
- PA1 — the artifact is the sole input to
apply. - PA3 — apply bails on plans older than 24h (override with
--force). - PA4 — for incremental exports, apply bails if another run moved the cursor in the meantime.
- PA5 — chunk ranges in the artifact are monotonic by construction.
Step 4 — Run, or apply by wave
Three ways to execute, by how much orchestration you want.
Run live — straightforward, config order, no waves:
rivet run -c pilot.yaml --validate
Apply the whole config wave-by-wave — rivet plan --annotate-waves (Step 3) wrote a wave: onto each export; apply runs them lowest-wave first, with a barrier between waves. Exports with no wave: run last, as one implicit final wave — so a config you never annotated still applies, just in a single band. Tables are independent, so a failed export does not block its wave-mates: apply collects the failure, runs the rest, and exits non-zero. Add --parallel-export-processes to run the cheap (parallel_safe) exports within a wave concurrently — the heavy ones still run alone (they chunk-parallelize internally):
rivet apply pilot.yaml # wave-ordered, sequential
rivet apply pilot.yaml --parallel-export-processes # + within-wave parallelism for cheap exports
Apply a sealed single-export artifact — the auditable split between “what will happen” and “do it”:
rivet apply plan.json
What happens under the hood for chunked:
- For each chunk task:
SELECT ... WHERE id BETWEEN start AND end ORDER BY id→ Arrow → Parquet → destination → manifest entry →chunk_task.status = 'completed'. - Ordering: write → manifest → cursor → metric (ADR-0001 I1–I4).
- On success:
last_committed_chunk_indexadvances inexport_progression(PG2, PG4).
Step 5 — Inspect progression
Get the explicit committed / verified boundary per export:
rivet state progression -c pilot.yaml
EXPORT COMM MODE COMMITTED COMMITTED AT VERI MODE VERIFIED
orders chunked chunk #9 2026-04-18 12:20:15 UTC - -
orders_coalesce incremental 2026-04-18T00:05 2026-04-18 12:21:02 UTC - -
At this point:
- Committed = “data is at the destination and recorded in the manifest” (PG2).
- Verified is still empty — no reconcile has run yet (PG5).
Step 6 — Reconcile
The GIF above walks through the whole sequence — reconcile clean, simulated drift, targeted repair, and final state progression showing RR4 (committed unchanged by repair). Steps 6–8 below expand the same flow in prose.
Partition-level COUNT(*) on the source, compared with per-chunk rows_written stored in the checkpoint.
rivet reconcile -c pilot.yaml -e orders
Possible outcomes per partition (RC3):
match— source and exported counts equal.mismatch— both counts known but differ → repair candidate.unknown— a count is missing (chunk never completed, unparseable keys) → repair candidate.
If every partition matches (zero mismatches and zero unknowns), last_verified_chunk_index advances (RC6 / PG5). Save a JSON report for audit:
rivet reconcile -c pilot.yaml -e orders --format json -o reconcile.json
The reconcile SQL uses exactly the same build_chunk_query_sql shape the pipeline used during extraction (RC2), so the comparison is apples-to-apples.
Step 7 — Targeted repair
If the reconcile report is dirty, derive a repair plan from it:
# Dry run — prints the plan, runs no queries, writes no files (RR2).
rivet repair -c pilot.yaml -e orders --report reconcile.json
# Execute just the flagged chunks.
rivet repair -c pilot.yaml -e orders --report reconcile.json --execute
What --execute does:
- Re-runs only the flagged chunk ranges via
run_chunked_sequential(ChunkSource::Precomputed)— same SQL shape as extraction and reconcile (RR3). - Writes new output files alongside originals with
<export>_<ts>_chunk<idx>_<16-hex-nonce>.<ext>naming (e.g.orders_20260611_120000_chunk2_a1b2c3d4e5f6a7b8.parquet; the random nonce is what guarantees a repair part can never overwrite the original) — Rivet does not delete or overwrite prior files (RR5), but the manifest declares the replacement: the chunk’s original part(s) are markedsuperseded, sorivet loadandrivet validatesee each row once. The superseded files stay on disk untilload.gc_orphans: truecollects them. A warehouse that already loaded the original part keeps those rows unless it dedups by primary key. - Leaves
last_committed_*untouched (RR4) — the chunk index was already covered at the original run; repair is corrective, not commitment.
Step 8 — Re-verify
After repair, rerun reconcile to advance verified:
rivet reconcile -c pilot.yaml -e orders
rivet state progression -c pilot.yaml
EXPORT COMM MODE COMMITTED COMMITTED AT VERI MODE VERIFIED
orders chunked chunk #9 2026-04-18 12:20:15 UTC chunked chunk #9
orders_coalesce incremental ... ... - -
Now both boundaries agree: everything committed is also verified against the source.
Step 9 — Automate
A minimal daily cron that runs, reconciles, and fails loudly on unresolved mismatches:
#!/usr/bin/env bash
set -euo pipefail
cd /opt/rivet && export DATABASE_URL='…'
rivet run -c pilot.yaml --validate
rivet reconcile -c pilot.yaml -e orders --format json -o /var/log/rivet/reconcile-$(date +%F).json
# Fail the job if reconcile is not clean (zero mismatches AND zero unknowns).
if ! jq -e '.summary.mismatches == 0 and .summary.unknown == 0' \
/var/log/rivet/reconcile-$(date +%F).json > /dev/null; then
echo "reconcile dirty — see report"
exit 1
fi
For CI-style review, use the plan/apply split:
# In CI (build stage)
rivet plan -c pilot.yaml --format json -o plan.json
# Review plan.json in a PR — prioritization block tells you what's heavy/risky.
# In CI (deploy stage)
rivet apply plan.json
Contract cheat sheet
| Question | Contract | Answer |
|---|---|---|
| “Will apply run on a stale plan?” | PA3 | No, hard reject at 24h without --force. |
“Can apply run if another rivet run advanced the cursor?” | PA4 | No, apply bails with a drift message (incremental only). |
| “Can repair accidentally regress the cursor?” | PG3, RR4 | No: incremental committed is monotonic; repair never touches committed. |
“Does coalesce mode leak a synthetic column to my files?” | CC5 | No, _rivet_coalesced_cursor is stripped before write. |
| “Is a chunk whose file landed but whose manifest write failed lost?” | I7, PG2 | No — file is at the destination; only manifest is missing. rivet reconcile surfaces it as unknown. |
| “Does reconcile write anything other than progression?” | RC5, PG5 | No — reports are ephemeral JSON; only last_verified_* is persisted when all partitions match. |
“Does rivet repair --execute delete old bad files?” | RR5 | No. New files sit alongside originals; the manifest marks the originals superseded and load.gc_orphans collects them. |
What’s next
- Production checklist — hardening before real workloads.
- UAT checklist — pilot sign-off structure.
- Tuning — profiles, batch_size, memory-aware FETCH.
- Prioritization — reading and trusting the advisory block.
Production Checklist
For pilot ordering (discovery → run → reconcile → sign-off), use the Pilot guide and Pilot walkthrough; this page is the readiness gate before touching production systems.
Complete this checklist before running Rivet against a production database.
Database access
- Read-only user: create a dedicated database user with
SELECT-only privileges - Credential management: use
url_envorpassword_env— never hardcode passwords in YAML - Read replica: if available, point Rivet at the replica to avoid load on the primary
- Connection limits: confirm the database connection pool has room for Rivet’s connections — 1 per export, but chunked exports with
parallel: Nopen N concurrent backend connections (one per worker; see the Connection budget note below and ADR-0011) - Connection pooler / proxy awareness: if traffic is routed through pgBouncer, Odyssey, ProxySQL, MaxScale, or HAProxy, read the Connection poolers and proxies section below before the first run
Connectivity
-
rivet doctorpasses for all destinations - Network: Rivet host can reach the database and destination (S3/GCS) endpoints
- Firewall / security groups: ports are open (5432 for Postgres, 3306 for MySQL, 1433 for SQL Server, 27017 for MongoDB, 443 for S3/GCS/Azure)
Configuration
-
rivet checkpasses for all exports - Tuning profile: use
safefor production OLTP;balancedfor moderate load;fastonly on read replicas -
batch_size: start conservative (1,000-5,000) for wide tables; increase after monitoring memory -
statement_timeout_s: set to prevent runaway queries (recommended: 60-300s) -
lock_timeout_s: set to prevent lock contention (recommended: 10-30s) -
throttle_ms: add 50-500ms between batches for busy databases
Export design
- Mode selection: choose the right mode for each table:
Table type Recommended mode Small reference table fullAppend-only events incrementalLarge table, initial load chunkedRolling window analytics time_windowContinuous low-latency replication cdc - Query optimization: test your queries with
EXPLAIN ANALYZEfirst - Indexes: ensure
cursor_column,chunk_column, andtime_columnare indexed -
skip_empty: true: record incremental runs with no new data asskippedrather thansuccess(no file is written for 0 rows either way) -
max_file_size: set for large exports to keep output files manageable
Destination
- Bucket/directory exists: Rivet does not create S3/GCS buckets
- IAM permissions: write access confirmed (
s3:PutObject/storage.objects.create) - Storage lifecycle: configure retention policies on S3/GCS buckets to manage costs
- Disk space: for local destinations, ensure sufficient disk space
Quality gates
-
--validate: always run with--validateto verify output row counts -
--reconcile: use on critical exports to verify sourceCOUNT(*)matches - Quality rules: set
row_count_min/null_ratio_maxfor critical data
Monitoring and alerting
- Slack notifications: configure
notifications.slack.on: [failure, degraded] - Cron scheduling: set up cron with logging (
>> /var/log/rivet.log 2>&1) - Metrics review: periodically check
rivet metricsfor duration/size trends - Exit codes: your scheduler should alert on non-zero exit codes
First production run
- Run
rivet doctor– verify all connections - Run
rivet check– review preflight analysis - Run
rivet run --validate --reconcile– first real export - Inspect output files – verify data correctness
- Check
rivet metrics– confirm timing and row counts - Run again to test incremental/chunked behavior
- Set up cron / scheduler
Auditable extraction (plan/apply)
For CI/CD pipelines, GitOps workflows, or any run that requires a pre-execution review before data is touched:
- Generate a plan artifact — preflight analysis + chunk boundaries pre-computed, no data exported:
rivet plan -c rivet.yaml --format json --output plan.json - Review the plan — inspect
verdict,warnings, chunk count, row estimate. Commitplan.jsonto a PR or store as a CI artifact. - Apply the sealed artifact — executes exactly the pre-computed plan:
rivet apply plan.json
Key guarantees:
applynever re-reads the config file or re-runs preflight queries- Plans older than 1 hour emit a warning; older than 24 hours require
--force - For incremental exports,
applyrejects the artifact if the cursor has advanced since plan time (another run completed in between)
Many tables in one run. For a config with several exports, rivet plan -c rivet.yaml --annotate-waves writes a wave: and parallel_safe: onto each export (plain rivet plan is read-only — review first, then annotate), and rivet apply rivet.yaml runs them wave by wave (lowest first), with a barrier between waves. Tables are independent, so a failed export does not block its wave-mates — apply collects failures, runs the rest, and exits non-zero. Add --parallel-export-processes to run the cheap (parallel_safe) exports within a wave concurrently. See getting-started § 5.
Security note:
plan.jsonembeds the resolved source connection config. Plaintextpassword:values andscheme://user:pass@userinfo are stripped by ADR-0005 PA9; references (password_env:/url_env:/url_file:) are preserved so the apply environment can re-resolve them. Plans still contain query SQL, schema and cursor state — treat them as sensitive.
See CLI reference and ADR-0005 for the full contract specification.
Connection poolers and proxies
Many production stacks place pgBouncer / Odyssey / ProxySQL / MaxScale / HAProxy in front of the database. Rivet detects the connection shape at startup and emits a one-line warning if a pooler or multiplexing proxy is involved. Acting on that warning is the operator’s call — the export still runs.
What Rivet detects, and what it does about it
| Stack in front of the DB | Rivet’s classification | What still works | What may silently NOT work |
|---|---|---|---|
| Direct connection | Postgres: no warning · MySQL: MysqlProxyKind::Direct | Everything | — |
| pgBouncer / Odyssey (transaction mode) | Postgres: “transaction-mode connection pooler detected” | SET LOCAL inside our BEGIN … COMMIT (each export wraps its work in a txn); destination write; cursor/manifest writes | LISTEN/NOTIFY, advisory locks, prepared statements that outlive a transaction |
| pgBouncer / Odyssey (session mode) | No warning (PIDs stay stable) | Everything direct works | — |
| ProxySQL (default config) | MySQL: MysqlProxyKind::ProxySql | Session vars per statement when transaction_persistent=1 is on the user (we set it in our dev fixture) | Long-lived prepared statements; assumptions that two consecutive queries hit the same backend |
| MariaDB MaxScale | MySQL: MysqlProxyKind::MaxScale | Read-write splitting under readwritesplit router | Queries the router decides to reject or rewrite; backend-side statement timeouts may diverge from what tuning.statement_timeout_s sets |
| HAProxy MySQL mode, in-house balancers | MySQL: MysqlProxyKind::Multiplexed | Per-statement behaviour | Anything session-scoped |
Recommended posture for production
- Read the startup log line. A warning like
transaction-mode connection pooler detected (pgBouncer/Odyssey)orMySQL proxy multiplexer detected (ProxySQL)is intentional, one-time per source connect. - Prefer session mode (Postgres) or
transaction_persistent=1(ProxySQL) for any Rivet user that needsstatement_timeout,lock_timeout, ortime_zoneto actually take effect for the full export. - If you must run through transaction mode, do not assume per-export tuning that depends on session state is enforced for anything outside Rivet’s own
BEGIN ... COMMITblock. The destination commit and state writes are unaffected —live_pool_safety.rsexercises both paths against pgBouncer (pool_size=1) and ProxySQL nightly. - Connection budget: chunked exports with
parallel: Nopen N concurrent backends. Multiply by the number of exports running simultaneously. Verify your pooler / backendmax_connectionsheadroom — see ADR-0011 for why we don’t share a connection across workers.
The full coverage table is in docs/reliability-matrix.md § Pool and load pressure, and the detection internals are described in docs/architecture.md § Connection pooler / proxy detection.
Memory budgeting
| batch_size | Approximate RSS (narrow table) | Approximate RSS (wide table) |
|---|---|---|
| 1,000 | 50-100 MB | 100-500 MB |
| 5,000 | 100-300 MB | 300 MB - 1.5 GB |
| 10,000 | 200-500 MB | 500 MB - 3 GB |
| 50,000 | 500 MB - 2 GB | 2-10 GB |
For memory-constrained environments, use profile: safe. (jemalloc is already the default allocator in standard builds — no build flag needed; it is only absent if you built with --no-default-features.)
UAT Checklist
For the full pilot instruction sequence (what to run before you get here), see Pilot guide.
Audience: pilot users validating Rivet before production use.
When to use: at the end of a pilot, before promoting to production, or when verifying a new release.
Prerequisites: completed Getting Started and at least one successful export.
For the full internal acceptance test plan with detailed suites and smoke-test scripts, see dev/USER_TEST_PLAN.md.
Pre-flight
-
rivet doctorpasses — source and all destinations authenticated -
rivet checkpasses — all exports showEFFICIENTorACCEPTABLEverdict - No
UNSAFEexports (full table scans on very large tables)
Basic export
-
rivet run -c rivet.yaml --validatecompletes withstatus: success - Row count in summary matches expected
- Output files exist at the configured destination
Incremental / re-run
- Second run produces only new rows (cursor advanced correctly)
-
rivet state showreflects the updated cursor -
rivet metricsshows both runs in history
Mode-specific
- Full mode: complete snapshot on each run
- Incremental mode: only new/updated rows on subsequent runs
- Chunked mode: all chunks complete,
rivet state chunksshows no pending tasks - Time-window mode: only rows within the configured window
- CDC mode (if used): changes streamed to the destination as they occur; a second run resumes from the checkpoint and captures only new changes (PostgreSQL / MySQL / SQL Server / MongoDB)
Destinations
- Local: files written to correct path
- S3 (if used): files visible in bucket with correct prefix
- GCS (if used): files visible in bucket with correct prefix
- Azure (if used): files visible in container with correct prefix
Plan/Apply (if using auditable execution)
-
rivet plan -c rivet.yaml -o plan.jsonsucceeds -
rivet apply plan.jsonruns and matches the plan artifact - Re-running
rivet applywith an unchanged plan succeeds; a tampered or hand-edited plan artifact is rejected (PA10 integrity check). Note: apply never re-reads the config file — altering rivet.yaml does not affect applying an existing plan. Apply’s own gates are the PA10 integrity check (non-bypassable), plan staleness (warns at 1 h, errors at 24 h), and cursor drift; the last two are bypassable with--force
Observability
-
rivet metrics --last 10shows accurate run history -
rivet state fileslists files produced by each run - Schema change warnings appear when column structure changes
Error recovery
- Interrupted export can be safely re-run without data loss
-
rivet state reset -c <config> --export <name>correctly resets cursor for a re-export
Progression, reconcile, and repair (chunked exports with chunk_checkpoint: true)
-
rivet state progressionshowsCOMMITTEDboundary per export after a successful run -
rivet reconcile --export <name>runs cleanly (all partitionsmatch) and advances theVERIFIEDboundary - Injected mismatch:
rivet reconcilesurfaces it;rivet repair --executewrites corrective files without touchingCOMMITTED - Post-repair
rivet reconcilere-advancesVERIFIED
Next steps
- Production checklist — readiness gates before go-live
- Reference: CLI — full command reference
- Reference: Config — all YAML fields
Zero-code reconciliation runbook (pilot)
Verify a rivet export against the live source with nothing but SQL on both sides. No rivet code involved — the whole point: this check stays valid even if every rivet-internal guard were wrong.
Requires: a per-row hash column on the source (any deterministic digest of the business columns). Example (MySQL, generated column — zero app changes):
ALTER TABLE t ADD COLUMN row_hash CHAR(32)
AS (MD5(CONCAT_WS('#', id, amount, status))) STORED;
The row hash rides through the export like any other column, which removes
the classic cross-engine trap (numeric/text rendering differences under
CONCAT — both sides aggregate the same stored string).
Step 1 — cheap aggregates (run daily)
-- source (MySQL)
SELECT COUNT(*), SUM(amount), MIN(id), MAX(id) FROM t;
-- destination (DuckDB over the exported parquet)
SELECT COUNT(*), SUM(amount), MIN(id), MAX(id)
FROM read_parquet('s3://bucket/prefix/*.parquet');
Step 2 — global row-hash fold (order-independent)
-- source
SELECT BIT_XOR(CONV(SUBSTRING(row_hash,1,15),16,10)) FROM t;
-- destination
SELECT bit_xor(CAST(concat('0x', substring(row_hash,1,15)) AS UBIGINT))
FROM read_parquet('…/*.parquet');
Equal ⇒ every row’s full content matches, regardless of order. XOR is blind to pairs of identical compensating differences — step 3 covers localization and double-checks by range.
Step 3 — bucket hashes: localize a mismatch to a PK range
-- both sides, same expression family:
SELECT id DIV 1000, BIT_XOR(CONV(SUBSTRING(row_hash,1,15),16,10))
FROM t GROUP BY 1 ORDER BY 1; -- MySQL
SELECT id // 1000, bit_xor(CAST(concat('0x', substring(row_hash,1,15)) AS UBIGINT))
FROM read_parquet('…') GROUP BY 1 ORDER BY 1; -- DuckDB
diff the two outputs → the diverging bucket names a 1000-row range.
Step 4 — pinpoint the row inside the bucket
SELECT id, row_hash FROM t WHERE id DIV 1000 = <bucket> ORDER BY id;
diff again → the exact id and both hash values.
The live-source race, and how each step avoids it
- Closed windows: filter both sides with
WHERE updated_at <= <yesterday>— an immutable slice has no race. Default daily mode for append-mostly tables. - CDC converge: drain to current → measure source → drain again; an empty second drain proves no write landed between measure and stream, so the comparison is exact at the checkpoint position. Retry on busy tables — converges in 1–2 rounds off-peak.
- A transient bucket diff on a hot range is churn; a diff that survives two consecutive sync cycles is real.
Verified live (2026-07-04, MySQL 8.0 → parquet, 10k rows)
Steps 1–2: byte-equal both sides. One row mutated on the source
(UPDATE … WHERE id = 4321): global fold diverged, bucket scan flagged
exactly bucket 4, row scan named id 4321 with both hashes. Detection →
localization → pinpoint, zero code.
Warehouse-side duplicate check (post-merge)
rivet delivers at-least-once: a crash-resumed CDC run can re-emit rows, and a
merge is the warehouse’s job. After the MERGE, assert the target has no
duplicate primary keys — the same check pip_db_replicator runs in BigQuery
(duplicates_check.sql). This belongs HERE, not in rivet validate: inside a
single batch run a duplicate PK is already prevented (the wire-name guard +
chunk-boundary hardening), and on CDC parts pre-merge, overlaps are
expected (at-least-once), so an extractor-side dup check would false-alarm.
-- composite PK: CONCAT the key columns
SELECT COUNT(*) - COUNT(DISTINCT CONCAT(CAST(id AS STRING))) AS duplicate_rows
FROM `project.dataset.target_table`;
-- 0 ⇒ the merge deduplicated correctly.
Cross-run gap check (from the manifest, no source needed)
The manifest’s source.extraction ships the cursor RANGE each run covered.
Continuity is verifiable from manifests ALONE — run N+1’s cursor_low must
equal run N’s cursor_high; a gap is a silently-skipped range:
# for two consecutive incremental runs' manifests:
jq -r '.source.extraction | "\(.cursor_low // "-") .. \(.cursor_high)"' run_N/manifest.json
jq -r '.source.extraction | "\(.cursor_low) .. \(.cursor_high)"' run_N1/manifest.json
# run_N1.cursor_low MUST equal run_N.cursor_high — else the ids between were never extracted.
Rivet vs a cursor-based ELT pipeline — like-for-like
Positioning for teams that already run a cursor/watermark ELT pipeline
(typically odbc2parquet + orchestration glue: extract by cursor → parquet →
MERGE into the warehouse → dedup → a metadata/reconciliation table).
Honest scope
- Compared here: rivet’s cursor-based extraction (
mode: full/incremental/chunked) against the same paradigm — a cursor pipeline. Same job, same shape, head to head. - Deliberately NOT the baseline: CDC. Log-based capture is the evolution step (§4), not the comparison — comparing rivet-CDC against a cursor pipeline is apples-to-oranges.
- What rivet is: an extraction engine. A full ELT pipeline also merges, dedups, and keeps metadata. Rivet lands typed parquet + a manifest and leaves the MERGE to the warehouse. So rivet slots under an existing merge/metadata layer, replacing the extract-and-glue tier — not the whole pipeline.
- When NOT to adopt: if the data is append-mostly, memory fits the box, and log-only observability is tolerable, a working pipeline should not be replaced. The honest boundary is in §5.
1. Like-for-like: extraction in the same (cursor) paradigm
| Dimension | Rivet (cursor: full / incremental / chunked) | odbc2parquet + orchestration glue | Felt or latent |
|---|---|---|---|
| Peak memory | Bounded by construction — a per-flush memory target (default ~32 MB) with streaming rollover; memory is O(batch), not O(table). Measured ~70–90 MB per table. | The --batch-size-memory flag is a hint, not a hard cap; ODBC driver + Arrow buffering + wide columns drive the real footprint, which is effectively unbounded per subprocess. | Felt |
| Failure recovery | Resumable chunk checkpoints — a crashed run resumes from the last committed chunk. | Typically a full re-load on failure. | Felt |
| Observability | Structured run journal + file manifest + metrics + schema-drift tracker in a state DB; queryable via rivet state / rivet metrics. | Unstructured log lines (logger.info); observability is grepping logs. | Felt |
| Cursor state | Persisted (.rivet_state.db) with drift detection; resume reads the last committed value. | Often recomputed from source MIN/MAX each run; the watermark can be an injected run timestamp. | Minor |
| Type fidelity | A per-engine type resolver hardened against the known lossy cases (unsigned 64-bit, decimals, timestamps, JSON, UUIDs). | ODBC type mapping; e.g. bigint unsigned → INT64 silently overflows above ~9.2e18. | Latent¹ |
| Value verification | Always-on two-ended value checksum (independent source-side fold vs a fold of the built Arrow column) + rivet validate re-reads and re-verifies at the destination. | Reconciliation compares two destination datasets (staging vs raw) by row count — an internal count, not a source-vs-target value check. | Latent¹ |
| Completeness | Full cycle: extract → typed parquet + manifest → rivet load into BigQuery / Snowflake; with mode: cdc on the export and a pk: in the config’s load: block, the load maintains a current-state dedup view. | Full cycle: extract → MERGE → dedup → metadata. | — |
¹ Latent = real as code, but unexercised by an append-mostly, cursor-always-moves workload with in-range values. A long clean run is genuine evidence the shape does not trigger it — the value is insurance against shape changes, not a claim that the current pipeline is broken.
Verdict. The three felt rows — bounded memory, resumable recovery, observability — are solved in the same cursor paradigm, with no CDC. The adoption case stands on the extraction engine alone. The honest cost: rivet is not a full pipeline, so it goes under the existing merge/metadata layer.
2. The extraction contract — what rivet ships and guarantees
What a downstream consumer (or a DBA auditing a run) can rely on, per export, without trusting rivet’s internal state:
_SUCCESSmarker — the prefix is complete and safe to load. Absent ⇒ do not consume.manifest.json—row_count, and per part: relative path, row count, size, and a content fingerprint (xxh3) + content MD5. The manifest is self-consistent orrivet validatefails loudly.- Two-ended value checksums (Form A/B) — recorded per column;
rivet validatere-reads the parts and re-verifies, catching an Arrow→Parquet encode or post-write corruption a row count cannot see. source.extraction(incremental) — the strategy, cursor column, and the cursor range this run covered (cursor_low..cursor_high). Continuity is verifiable from manifests alone: run N+1’scursor_lowmust equal run N’scursor_high; a non-contiguous low is a silently-skipped range. No access to rivet’s private state required.- Run journal + metrics — a typed, queryable record of what was planned, what happened, what committed, and the outcome.
- Schema-drift tracker — column adds/removes/retypes surface on the next
run under
on_schema_drift: warn | continue | fail.
This is the “contract in the extraction part”: every run leaves a portable, verifiable, warehouse-consumable record — not just files.
3. DBA / SRE like-for-like
| Concern | Rivet (cursor) | odbc2parquet + glue |
|---|---|---|
| Memory envelope | Bounded per worker (~70–90 MB); N parallel workers = N × bounded ⇒ plannable. On a fixed box you know how many fit. | Per-subprocess footprint is effectively unbounded (flag is a hint); capacity must be discovered empirically. |
| Concurrent starts | Parallel workers are threads in one process (shared runtime, one destination instance, one connection pool); a synchronous start fits a known envelope. | A subprocess per chunk (fork/exec + driver + interpreter each); concurrent heavy loads can OOM the box, forcing staggered starts. |
| Throttling | Not needed — memory is bounded by construction, not throttled after the fact. | Reactive: watch memory and downshift parallel→sequential at a threshold (e.g. 70 %). |
| Scheduling pressure | Bounded profile ⇒ heavy loads need no weekend-only window. | Uncapped worker memory can force spreading heavy refreshes to off-peak/weekends. |
| Retries | Transient-error classifier + backoff, plus resumable chunk checkpoints — a failure continues, it does not restart. | Retries scoped to connection + storage transients; a failed LOAD/MERGE fails fast, and a re-load is typically full. |
| Source hold model | Chunked reads are short queries (PG: server cursor + FETCH N, longest single query sub-second on millions of rows; MySQL: PK-range chunks). No minutes-long open transaction. throttle_ms, statement_timeout_s, lock_timeout_s, profile: safe are first-class. Server-side cost is reproducibly measurable. | odbc2parquet issues the extraction query per chunk; hold time depends on chunk size and driver. |
| Telemetry | rivet state / rivet metrics — queryable per-run record. | Log lines only. |
| Schema drift | Static explicit column lists ⇒ adds ignored, a dropped column fails the query loudly (both tools). Rivet additionally tracks drift in the state DB and can gate on it. | Static SELECTs already make adds safe and drops loud; no persistent drift record. |
| Hard deletes | Not captured in cursor mode (a DELETE moves no cursor) — the CDC evolution (§4) captures them. | Not captured (same structural limit of watermark sync). |
Reading it: the operational wins a DBA/SRE feels weekly — bounded memory, no reactive throttle, synchronous starts, resumable recovery, queryable telemetry — are all in the cursor paradigm. Deletes are the one thing neither cursor path captures; that is the evolution, not a like-for-like gap.
4. CDC as the evolution (not the comparison)
Once on rivet’s cursor path — a better extraction engine in the same paradigm, same orchestration, same downstream merge layer — CDC is a mode flip, not a re-architecture:
mode: cdc # was: incremental
cdc: { initial: snapshot, ... }
It removes the cursor’s two structural blind spots that no tuning or retry can fix:
- Hard deletes — a DELETE moves no cursor; a watermark sync never sees it.
- Out-of-cursor updates — an update that does not move the cursor column
(e.g. a status change with no
updated_atbump) is never re-extracted.
Same tool, same destination contract (__op / __pos typed change events +
manifest + _SUCCESS), same downstream merge. Adopt cursor-first for the
operational wins; grow into CDC when deletes or out-of-cursor updates start to
matter.
5. When NOT to adopt (the honest boundary)
- Data is append-mostly (no hard deletes), the cursor always moves (no out-of-cursor updates), and 64-bit values stay in range → the latent rows in §1 never fire; a long clean run is real evidence of this.
- The worker’s memory already fits the box without weekend staggering → the strongest felt win does not apply.
- Log-only observability is tolerable for the team’s incident load.
If all three hold, a working pipeline should not be replaced. The credible pitch is naming this boundary, not claiming the incumbent is broken.
Prove an export is correct — on your own data
You should not have to trust that rivet copied your table faithfully. Verify it: compare a content fingerprint of the source query against the same fingerprint of the exported Parquet. If rivet dropped, duplicated, or corrupted a single row, a fingerprint field diverges.
The check is independent of rivet’s own bookkeeping — it never reads rivet’s counters, manifest, or summary. Both fingerprints are computed by DuckDB: one over the live source (via DuckDB’s Postgres/MySQL scanner), one over the Parquet rivet wrote. The data sources are independent; DuckDB is just the calculator.
One-time setup
pip install duckdb # the only dependency; the postgres/mysql scanner
# extensions auto-install on first use
The script lives at dev/correctness/verify_export.py.
Run it
Point it at the same query your rivet.yaml export used and the Parquet it
produced:
python dev/correctness/verify_export.py \
--source-type postgres \
--dsn "host=127.0.0.1 port=5432 dbname=mydb user=me password=secret" \
--query "SELECT id, name, amount, updated_at FROM orders" \
--parquet "/data/exports/orders/*.parquet" \
--key id
field source export
rows 1000000 1000000
distinct_id 1000000 1000000
nn_id 1000000 1000000
sum_id 500000500000 500000500000
nn_name 1000000 1000000
len_name 18994214 18994214
sum_amount 42130995.51 42130995.51
...
PASS: source and export agree on all 11 fingerprint fields (1000000 rows).
The export is complete and uncorrupted.
Exit code is 0 on PASS, 1 on FAIL, so it drops straight into a gate:
rivet run --config rivet.yaml --export orders \
&& python dev/correctness/verify_export.py --source-type postgres \
--dsn "$DSN" --query "$Q" --parquet "/data/exports/orders/*.parquet" --key id \
&& deploy
MySQL is the same with --source-type mysql and a MySQL DSN
(host=… user=… password=… database=…).
What the fingerprint covers
The fingerprint is built automatically from the source query’s schema, so it adapts to your columns:
| Field | Built for | Catches |
|---|---|---|
rows | always | row loss / duplication |
distinct_<key> | --key | duplication of the key |
nn_<col> | every column | per-column loss (non-null count) |
sum_<col> | numeric columns | value corruption |
len_<col> | text columns | truncation / mangling |
A row that is dropped, duplicated, or whose value changed moves at least one field. The check is order-independent (it is all aggregates), so chunk ordering and multi-file output don’t matter.
Limits (be honest about them)
- At-least-once duplication after a crash is real (see
semantics.md). If you verify a prefix
that includes an orphaned pre-crash part,
rows/sumread high — that is the documented duplicate, not corruption. Verify the parts named inmanifest.jsonfor the exactly-once view, or runrivet reconcile. - The fingerprint is strong but not cryptographic: it does not compare date/time/blob/boolean values directly (only their non-null counts), to stay free of cross-engine representation differences. For those, rivet’s live test suite uses DuckDB/ClickHouse/pyarrow as full-type oracles (type_roundtrip).
- It verifies the data, not your
query:. A query that selects the wrong rows will fingerprint-match a faithful export of those wrong rows.
The same technique runs continuously in rivet’s own CI as
tests/live_differential.rs — this script
is that test, pointed at your database.
Recipe: Recover from an Interrupted Run
A short, action-first cookbook for the most common Rivet recovery scenarios. For the full execution-semantics contract, see docs/semantics.md. For deeper concepts, see docs/best-practices/recovery-and-resume.md.
Mental model in one line
written → manifested → committed → validated → reconciled
| Command | Question it answers |
|---|---|
rivet run | Write parts and manifest.json, then _SUCCESS. |
rivet validate | Do the files Rivet says it wrote still exist and match the manifest? |
rivet reconcile | Does the destination row count match the source row count per chunk? |
rivet repair | Re-export the chunks reconcile flagged. |
validate reads only the destination. reconcile reads both source and
destination. repair writes new parts; it never deletes or overwrites.
Scenario 1 — Job was killed mid-export (chunked)
Symptoms: rivet run exited non-zero, _SUCCESS is missing, some
parts exist at the destination prefix.
# Continue from the last completed chunk
rivet run --config rivet.yaml --export big_table --resume
# Confirm the run finished cleanly
rivet validate --config rivet.yaml --export big_table
What --resume does:
- Walks the destination prefix, cross-checks against the state DB and
the prior manifest, and decides per-chunk: skip (already
committed), rewrite (in-progress / missing part), or quarantine
(untracked or corrupt object — moved under
_quarantine/<run_id>/). - Refused with an actionable error if the prior run already finished
cleanly (
_SUCCESSpresent + chunks complete). Userivet runwithout--resumeto start a new run.
--resume is meaningful only for chunked mode. For full and
incremental, just re-run — incremental picks up from the persisted
cursor.
Scenario 2 — Files exist, but validate fails
Symptoms: _SUCCESS is present, but rivet validate reports a missing
or short part, or a manifest fingerprint mismatch.
# 1. Inspect what the verifier saw
rivet validate --config rivet.yaml --export big_table --format json
# 2. Look at recorded state for the export (chunks, manifest, last verified)
rivet state show --config rivet.yaml
rivet state files --config rivet.yaml --export big_table --last 5
# 3. Drill into per-chunk completion
rivet state chunks --config rivet.yaml --export big_table
# 4. Compare against the source per chunk
rivet reconcile --config rivet.yaml --export big_table
If reconcile reports match everywhere but validate still fails,
the destination object set diverged after the export — typically
something else wrote into the prefix (different tool, manual
cleanup, lifecycle policy). Quarantine the prefix and re-run.
If reconcile reports mismatch or unknown chunks, proceed to
Scenario 3.
Scenario 3 — Reconcile flagged some chunks; rewrite them
Symptoms: per-chunk source counts disagree with destination counts on
specific ranges. This is what rivet repair was built for.
# 1. Capture a reconcile report
rivet reconcile --config rivet.yaml --export big_table --format json --output reconcile.json
# 2. Dry-run the repair plan (default — nothing is written)
rivet repair --config rivet.yaml --export big_table --report reconcile.json
# 3. Execute the plan — re-exports only the flagged chunk ranges
rivet repair --config rivet.yaml --export big_table --report reconcile.json --execute
# 4. Re-reconcile to confirm the gap closed
rivet reconcile --config rivet.yaml --export big_table
# 5. Re-validate the destination contract
rivet validate --config rivet.yaml --export big_table
What repair --execute does and does not:
- Re-runs only the flagged chunk ranges via
ChunkSource::Precomputed— same SQL shape as extraction and reconcile (RR3). - Writes new files alongside originals with the
<export>_<ts>_chunk<idx>_<nonce>.<ext>naming scheme (RR5), where<nonce>is a random 16-hex-digit suffix — the nonce, not the timestamp, is what guarantees a repair re-export never overwrites the original part. - Does not delete or overwrite prior files, but the manifest
declares the replacement: the chunk’s original part(s) are marked
superseded, sorivet load,rivet validate, and any reader of the committed parts see each row once. The superseded files stay on disk untilload.gc_orphans: truecollects them. If repair cannot map an original part to its chunk without guessing, it warns and keeps both declared for that chunk. A warehouse that loaded the original part before the repair keeps those rows unless it dedups by primary key. - Leaves
last_committed_*untouched (RR4).last_verified_*re-advances only on a subsequent clean reconcile (zero mismatches, zero unknowns). Seerivet state progression.
Scenario 4 — State DB is stuck (chunks never advance)
Symptoms: rivet run --resume exits with “in-progress export not
found” or “chunks stuck in checkpoint state”; the state DB contains
checkpoints from a process that no longer exists.
# Inspect the stuck records
rivet state show --config rivet.yaml
rivet state chunks --config rivet.yaml --export big_table
# Reset the chunk rows for ONE export (preserves manifest + cursor).
# --export targets a single export by name...
rivet state reset-chunks --config rivet.yaml --export big_table
# ...OR --stuck-checkpoints (alias --failed) resets every export in the config
# whose latest chunk run is stuck in checkpoint state. Pick exactly one target —
# --export and --stuck-checkpoints are mutually exclusive.
rivet state reset-chunks --config rivet.yaml --stuck-checkpoints
# Then resume
rivet run --config rivet.yaml --export big_table --resume
rivet state reset-chunks is targeted on purpose: it does not wipe
manifests, cursors, or run journals. See
rivet state reset-chunks
for the flag matrix.
What this recipe does not cover
- Cross-process race against the state DB. Two
rivet runagainst the same.rivet_state.dbis not supported; the state layer enforces a single-writer invariant via SQLite locking. See ADR-0001. - Recovering after the destination prefix was deleted by something else. Rivet detects this on next resume but cannot reconstruct data that no longer exists; re-run from scratch.
- Recovering after the source schema drifted. See
on_schema_driftin docs/reference/config.md and thelive_schema_drifttest suite for the policy hook. - Multi-export campaign recovery.
rivet apply --plan plan.jsonre-runs the full sealed plan idempotently; per-export recovery falls back to the recipes above.
See also
- docs/semantics.md — full crash / retry / resume contract, including the non-guarantees.
- docs/best-practices/recovery-and-resume.md
— deeper notes on
--resumesemantics and state-DB layout. - ADR-0008 — Export progression —
formal
committed/verifiedboundaries (PG1–PG8). - ADR-0009 — Reconcile and repair — formal RR1–RR8 invariants.
Recipe: Idempotent Downstream Warehouse Loading
Rivet provides at-least-once file delivery to its destination. After a clean run, the destination prefix carries:
- one or more data parts — names are per-runner (single/incremental
{export}_{YYYYMMDD_HHMMSS_mmm}.parquetfor a single-part run, with a_part0.._partN-1suffix on every part when the run rotates into multiple parts; chunked{export}_{ts}_chunk{idx}_{nonce}.parquet; keyset{export}_{run-tag}_keyset_{seek-tag}.parquet, …) — always take them from the manifest, never pattern-match them, - a
manifest.jsonlisting every committed part withsize_bytesandcontent_fingerprint(xxh3 over the part bytes), - a
_SUCCESSmarker whose body fingerprints the exactmanifest.jsonbytes.
What Rivet does not provide:
- exactly-once delivery to a destination,
- exactly-once load semantics into a downstream warehouse,
- transactional coupling between the export run and a downstream
MERGE/COPY INTO.
A downstream loader that ignores the manifest and processes “every file
under this prefix” will eventually double-load — chunked retries write
new files alongside originals (RR5), and rivet repair --execute
explicitly does so. Treat the manifest as the source of truth: after a
repair it lists the chunk’s original part(s) as superseded and only the
replacement as committed, so a reader of the committed parts sees each
row once. A warehouse that already loaded the original part before the
repair still holds those rows; without a primary-key dedup it keeps them.
The built-in path: rivet load (BigQuery, Snowflake, ClickHouse)
For BigQuery, Snowflake and ClickHouse you do not build any of this — rivet load is
idempotent by construction:
- Count gate before cleanup. The load refuses to finish — and refuses to
clean the source — unless the warehouse
COUNT(*)equals the summed manifestrow_count. A partial or double load fails loudly instead of silently corrupting. - Manifest-driven, not a glob. It reads the run manifests and loads exactly their committed parts, never “every file under the prefix” — so a repair retry’s extra files or a half-finished run can’t double-load.
mode: fullOVERWRITEs. Re-running a full load re-materialises the latest snapshot; the table lands identical, not doubled (live-verified: two loads of a 3-row table → 3 rows, not 6).mode: incremental/mode: cdcappend + dedup. For mutable sources the load appends to<table>__changesand exposes a current-state view (latest-per-PK, deletes flagged) — the built-in equivalent of the manualMERGEbelow, no staging table or upsert SQL to write. On ClickHouse the log is aReplacingMergeTreeread through aFINALview (ClickHouse load).
load:
target: bigquery # or: snowflake / clickhouse (+ that target's connection keys)
project: my-proj
dataset: analytics
pk: [id] # incremental/cdc dedup key; default: the source primary key
cleanup_source: true # wipe staging only after the count gate passes
The rest of this recipe is the manual pattern — what to do for a warehouse
rivet load does not target (Redshift, Trino, Databricks, dbt), or to understand
the contract rivet load itself builds on.
The contract you build on
Every committed part is recorded in manifest.json:
{
"manifest_version": 1,
"run_id": "orders_20260523T120000.123",
"schema_fingerprint": "xxh3:…",
"row_count": 200000,
"part_count": 2,
"parts": [
{"part_id": 0, "path": "orders_20260523_120000_123_part0.parquet", "rows": 100000,
"size_bytes": 4194304, "content_fingerprint": "xxh3:…", "content_md5": "…", "status": "committed"},
{"part_id": 1, "path": "orders_20260523_120000_123_part1.parquet", "rows": 100000,
"size_bytes": 4198400, "content_fingerprint": "xxh3:…", "content_md5": "…", "status": "committed"}
]
}
(Abridged — the real manifest also records export_name, status, timestamps,
source/destination blocks, format/compression, and optional per-column
checksums. Each part’s object name is its path field.)
_SUCCESS is a single line: xxh3:<16-hex> where the hex is the
fingerprint of the exact manifest.json bytes. See
ADR-0012 for the formal
invariants (M1–M9).
The manifest gives a downstream loader two things it cannot easily recover from raw object listing:
- The exact set of parts that were committed in this run (vs.
parts left over from earlier interrupted runs, parts a repair
superseded (
status: superseded), or external writes). - A content-addressable identity per part (
content_fingerprint) that survives object renames, lifecycle migrations, and CDN copies.
content_fingerprint is the supported dedup key: it is an xxh3 over the
exact part bytes, computed deterministically. Because rivet pins the Parquet
created_by to a version-independent constant, identical rows produce
identical bytes — and therefore the same content_fingerprint — across rivet
releases, not just within one build. So a re-extraction of the same window
(e.g. a crash + --resume, or a deliberate re-run) yields parts a downstream
MERGE can dedup on by fingerprint alone. Two parts with the same
content_fingerprint are byte-identical and interchangeable; drop one.
(The fingerprint is over file bytes, not logical rows — so it is stable for
the same rows + schema + compression settings. Changing compression: or the
column projection changes the bytes, hence the fingerprint.)
Manual pattern — warehouses rivet load doesn’t target
For a warehouse rivet load doesn’t reach (Redshift / Trino / Databricks / dbt),
the pattern is the same across targets:
- Read
manifest.jsonfrom the resolved destination prefix. - Verify
_SUCCESSmatches. If it does not, abort — the export is not complete. - Load only the parts listed in
manifest.jsonwithstatus: committed. Do not glob the prefix, and skipsuperseded/quarantinedentries. - Record the manifest identity (
run_id+schema_fingerprint+_SUCCESSbody) in a downstream control table. - Deduplicate by primary key (or natural key) when merging into the final table.
- Commit the warehouse table only after the load succeeds end-to-end.
If step 4 records the run identity before step 3 starts and after step 6 finishes (an “intent + commit” pair), the load is restartable: on retry, skip any manifest already marked committed.
BigQuery pattern
-- 1. Stage parts referenced by manifest.json into a per-run staging table.
LOAD DATA INTO project.dataset.orders_stage_<run_id>
FROM FILES (
format = 'PARQUET',
-- list the exact `parts[].path` values from manifest.json — never a glob
uris = ['gs://my-bucket/exports/2026-05-23/orders/orders_20260523_120000_123_part0.parquet',
'gs://my-bucket/exports/2026-05-23/orders/orders_20260523_120000_123_part1.parquet']
);
-- 2. Tag every staged row with the run identity.
ALTER TABLE project.dataset.orders_stage_<run_id>
ADD COLUMN _rivet_run_id STRING,
ADD COLUMN _rivet_manifest_fingerprint STRING;
UPDATE project.dataset.orders_stage_<run_id>
SET _rivet_run_id = '<run_id>', _rivet_manifest_fingerprint = '<xxh3>'
WHERE _rivet_run_id IS NULL;
-- 3. Merge into final table on primary key.
MERGE project.dataset.orders AS target
USING project.dataset.orders_stage_<run_id> AS src
ON target.id = src.id
WHEN MATCHED THEN UPDATE SET ... -- or DO NOTHING for append-only sources
WHEN NOT MATCHED THEN INSERT ROW;
-- 4. Drop the staging table after the merge commits.
DROP TABLE project.dataset.orders_stage_<run_id>;
For LOAD DATA, prefer the explicit URI list from manifest.parts
over a wildcard. The wildcard form is fine when you trust the prefix
contains exactly the manifest’s parts (i.e. there is no concurrent
write into the same prefix), but the explicit list is what lets you
prove which bytes were loaded.
Native types. Bare autoload degrades several columns:
json/uuidload asBYTES, a naivetimestampasTIMESTAMP(an instant, not wall-clockDATETIME), and arrays as a nestedRECORD. BigQuery will not coerce these on load — declaring native types in a load schema is rejected — so recover them with a post-loadCREATE TABLE … AS SELECTover the staging table. Load the staging table with--parquet_enable_list_inference(so arrays flatten withUNNEST), then run the recovery SQL thatrivet check --type-report --target bigqueryprints per export. Full table: type-mapping.md § BigQuery autoload & recovery.
Wide decimals (
NUMERIC/DECIMALprecision > 38). The load’s default decimal target isNUMERIC(max precision 38, scale 9) and fails on wider columns; pass--decimal_target_types=NUMERIC,BIGNUMERIC,STRING(repeated flag inbq: one value per flag).BIGNUMERICstill caps at ~5.79×10³⁸ — 38 integer digits — so aDECIMAL(50,10)column loads but a value with 39+ integer digits does not fit ANY BigQuery numeric type; withSTRINGin the list such columns load losslessly as text (verified live). Caveat for verification tooling: DuckDB misreads Parquet fixed-len-byte-array decimals wider than 16 bytes as a garbageDOUBLE— cross-check wide-decimal columns with ClickHouse or BigQuery, not DuckDB.
Snowflake pattern
-- 1. COPY INTO a staging table, listing the exact files from manifest.json.
COPY INTO @my_stage/orders/orders_stage_<run_id>
FROM ('@my_stage/exports/2026-05-23/orders/orders_20260523_120000_123_part0.parquet',
'@my_stage/exports/2026-05-23/orders/orders_20260523_120000_123_part1.parquet',
...)
FILE_FORMAT = (TYPE = PARQUET);
-- 2. Snowflake's COPY automatically deduplicates already-loaded files
-- via load history (default 14d). For longer retention or external
-- coordination, record the manifest fingerprint in a control table
-- and gate the COPY on it.
-- 3. Merge into the final table by primary key.
MERGE INTO orders target
USING orders_stage_<run_id> src
ON target.id = src.id
WHEN MATCHED THEN UPDATE SET ...
WHEN NOT MATCHED THEN INSERT ...;
Snowflake’s per-stage COPY INTO load history gives you a built-in
“don’t load the same file twice” property within the retention window.
That is not a substitute for the manifest fingerprint check on the
client side — load history protects against accidental double-COPY,
not against loading a stale prefix from a half-finished export.
When append-only is safe
Skipping the merge step is acceptable only when all of the following hold:
- The source is immutable for the period in question (event logs, audit trails, time-partitioned analytics tables).
- The export carries a stable primary key that downstream consumers can use to deduplicate at query time.
- The downstream table is partitioned by event date so duplicate
rows from a re-run land in the same partition and a one-time
DELETE WHERE _rivet_run_id NOT IN (current_run_id)clean-up is cheap.
For mutable upstream tables (orders, users, accounts), always use the merge pattern. At-least-once + mutable source + append-only loader = silent data corruption that is invisible until a downstream join breaks.
What Rivet does not do downstream
- Load targets BigQuery, Snowflake and ClickHouse only.
rivet loadcovers those three (see the built-in path above); for Redshift / Trino / Databricks / dbt the operator wires up the load with the manual pattern here. - No transactional coordination. Rivet does not coordinate with a
downstream
MERGE/COMMIT. If the export run succeeds and the warehouse load fails, the operator is responsible for retry logic. - No dead-letter queue for poisoned parts. A part that fails warehouse parse (e.g. a Parquet version bump on the loader’s side) is the loader’s problem; Rivet’s manifest still says the part is committed.
See also
- docs/cloud-destinations.md — the common output contract and the per-backend support matrix.
- docs/semantics.md § Known non-guarantees — what Rivet explicitly does not promise.
- ADR-0012 — Cloud manifest contract (M1–M9) — the formal invariants this recipe builds on.
- docs/recipes/recover-interrupted-run.md — what to do before you load downstream when the export itself was interrupted.
Loading rivet Parquet into Snowflake
Use rivet load. As of 0.20.0 Snowflake is a first-class load target: a
top-level load: block plus one command COPYs a resolved export off a GCS
external stage into a native-typed table — no hand-written stage, upload, or
type-recovery SQL.
# cfg.yaml — extraction PLUS the load target, one file
source: { type: postgres, url_env: DATABASE_URL }
exports:
- name: orders
table: orders
mode: full
format: parquet
destination: { type: gcs, bucket: my-bucket, prefix: exports/orders/ }
load:
target: snowflake
connection: my_conn # a `snow` CLI connection (key-pair / JWT auth)
warehouse: COMPUTE_WH
database: ANALYTICS
schema: PUBLIC
storage_integration: MY_GCS_INT # a pre-created GCS STORAGE INTEGRATION granting Snowflake read on the bucket
cleanup_source: true
$ rivet run -c cfg.yaml # extract → gs://my-bucket/exports/orders/
$ rivet load -c cfg.yaml # COPY → ANALYTICS.PUBLIC.orders
integrity ✓ source ? → files 3 → warehouse 3 rows in ANALYTICS.PUBLIC.orders (source cleaned)
What it handles for you — every autoload quirk the by-hand appendix below
recovers manually, rivet load does automatically (live-verified against a
type-rich Postgres source):
| Source type | Lands as | How rivet load gets it right |
|---|---|---|
JSON / jsonb | VARIANT — navigable (meta:k) | PARSE_JSON($1:col) in the COPY transform |
timestamptz | TIMESTAMP_TZ — instant preserved (…Z) | ALTER SESSION SET TIMEZONE = 'UTC' before COPY |
binary / bytea | BINARY — raw bytes, 0xFF-safe | BINARY_AS_TEXT = FALSE in the file format |
| multi-byte UTF-8 | intact (日本語 🚀) | — |
BIGINT UNSIGNED > 2^63-1 | exact NUMBER | a decimal(20,0) column override at extract |
A CDC export (mode: cdc) additionally appends a <table>__changes log and
rebuilds a (__pos, __seq)-ordered current-state view (PARSE_JSON(__pos) on
Snowflake). The count gate (manifest rows == warehouse COUNT(*)) runs before
cleanup_source wipes the staging prefix.
Appendix — loading Parquet into Snowflake by hand
Everything below is the manual sequence rivet load automates: land Parquet in a
stage yourself and run a two-step COPY + CREATE TABLE AS SELECT that recovers
each autoload quirk. Reach for it only when you load Snowflake outside rivet,
or to understand what the loader does under the hood. Built around Snowsight web
Worksheets (the snowsql CLI needs MFA many new accounts lack).
Verified end-to-end against the type-matrix Parquet from
tests/type_roundtrip/fixtures/{postgres,mysql}_*.sql. All 28 PG columns and 38 MySQL columns roundtrip with values intact (microsecond precision,u64::MAX, raw binary bytes, canonical UUID, multi-byte UTF-8).
Prerequisites
-
A rivet export produced with format
parquet. For MySQL columns that may carryBIGINT UNSIGNEDvalues above2^63-1, add a column override to ride that field as exact decimal — Snowflake’s Parquet reader rejects raw UINT64 above that bound:exports: - name: my_export columns: c_bigint_u: decimal(20,0)(
stringalso works as an alternative if you prefer to cast on the warehouse side.) -
A Snowflake account with at least one warehouse, database, and schema you can write to. The examples below assume:
WAREHOUSE = COMPUTE_WH DATABASE = RIVET_DATA_TOOL SCHEMA = PUBLIC STAGE = RIVET_STG (created in step 3) -
Access to Snowsight with a role that can
CREATE STAGE,CREATE TABLE, and upload files.
The load
1. Create the stage
Open a Worksheet and run:
USE WAREHOUSE COMPUTE_WH;
USE DATABASE RIVET_DATA_TOOL;
USE SCHEMA PUBLIC;
CREATE STAGE IF NOT EXISTS RIVET_STG
FILE_FORMAT = (TYPE = PARQUET);
2. Upload the Parquet files
In the Snowsight left nav: Data → Databases → RIVET_DATA_TOOL → PUBLIC →
Stages → RIVET_STG → “+ Files”. Drop the .parquet files there. No
subdirectory needed.
3. Run the load script
Pick pg or mysql below and run it in a Worksheet. Replace the filename in
the FROM @RIVET_STG/... clause with the actual file you uploaded.
The script uses a two-step pattern — COPY into a staging table with
“forgiving” types (NUMBER for raw int64 µs, VARCHAR for JSON text, BINARY for
raw bytes) followed by a CREATE TABLE AS SELECT that applies the necessary
transforms (TIME_FROM_PARTS, TO_TIMESTAMP_NTZ, PARSE_JSON, canonical
UUID formatting). This is the only shape we found that survives all the
autoload caveats listed below.
Postgres matrix
USE WAREHOUSE COMPUTE_WH;
USE DATABASE RIVET_DATA_TOOL;
USE SCHEMA PUBLIC;
-- Snowflake autoload for Parquet `Timestamp(MICROSECOND, isAdjustedToUTC=true)`
-- into TIMESTAMP_TZ uses the *session* offset as the recorded TZ, which shifts
-- the absolute instant by that offset. Pinning the session to UTC for the
-- duration of the load keeps (wall_clock, offset) = (UTC, +00:00) and preserves
-- the original instant.
ALTER SESSION SET TIMEZONE = 'UTC';
CREATE OR REPLACE TABLE PG_STAGE (
id NUMBER(38,0),
c_smallint NUMBER(38,0),
c_integer NUMBER(38,0),
c_bigint NUMBER(38,0),
amount NUMBER(18,2),
fee NUMBER(20,6),
price NUMBER(10,2),
c_real FLOAT,
c_double FLOAT,
c_date DATE,
c_time NUMBER(38,0), -- µs of day (Parquet Time64)
created_at NUMBER(38,0), -- µs of epoch (no-tz)
created_at_tz TIMESTAMP_TZ(6),
label VARCHAR,
c_varchar VARCHAR,
c_bpchar VARCHAR,
raw_bytes BINARY,
uid BINARY, -- 16-byte UUID payload
attrs VARCHAR, -- JSON text
attrs_json VARCHAR,
c_bool BOOLEAN,
interval_col VARCHAR,
enum_col VARCHAR,
tags ARRAY,
nums ARRAY,
large_text VARCHAR,
note_nullable VARCHAR,
note_all_null VARCHAR
);
COPY INTO PG_STAGE
FROM @RIVET_STG/<your_pg_file>.parquet
FILE_FORMAT = (TYPE = PARQUET BINARY_AS_TEXT = FALSE)
MATCH_BY_COLUMN_NAME = CASE_INSENSITIVE;
CREATE OR REPLACE TABLE PG AS
SELECT
id, c_smallint, c_integer, c_bigint,
amount, fee, price, c_real, c_double, c_date,
TIME_FROM_PARTS(0, 0, 0, c_time * 1000) AS c_time,
TO_TIMESTAMP_NTZ(created_at, 6) AS created_at,
created_at_tz,
label, c_varchar, c_bpchar,
raw_bytes,
REGEXP_REPLACE(LOWER(HEX_ENCODE(uid)),
'^(.{8})(.{4})(.{4})(.{4})(.{12})$', '\\1-\\2-\\3-\\4-\\5') AS uid,
PARSE_JSON(attrs) AS attrs,
PARSE_JSON(attrs_json) AS attrs_json,
c_bool, interval_col, enum_col, tags, nums,
large_text, note_nullable, note_all_null
FROM PG_STAGE;
DROP TABLE PG_STAGE;
MySQL matrix
USE WAREHOUSE COMPUTE_WH;
USE DATABASE RIVET_DATA_TOOL;
USE SCHEMA PUBLIC;
ALTER SESSION SET TIMEZONE = 'UTC';
CREATE OR REPLACE TABLE MS_STAGE (
id NUMBER(38,0),
c_tinyint NUMBER(38,0),
c_tinyint_u NUMBER(38,0),
c_bool BOOLEAN,
c_boolean BOOLEAN,
c_smallint NUMBER(38,0),
c_smallint_u NUMBER(38,0),
c_int NUMBER(38,0),
c_int_u NUMBER(38,0),
c_bigint NUMBER(38,0),
c_bigint_u NUMBER(20,0), -- export with `c_bigint_u: decimal(20,0)` override
amount NUMBER(18,2),
fee NUMBER(20,6),
price NUMBER(10,2),
c_float FLOAT,
c_double FLOAT,
c_date DATE,
c_time NUMBER(38,0),
created_at_dt NUMBER(38,0),
created_at_ts TIMESTAMP_TZ(6),
label VARCHAR,
c_char VARCHAR,
c_text VARCHAR,
c_varchar VARCHAR,
long_text VARCHAR,
medium_text VARCHAR,
raw_bytes BINARY,
var_bytes BINARY,
blob_bytes BINARY,
uid VARCHAR(36),
extras VARCHAR,
enum_col VARCHAR,
set_col VARCHAR,
year_col NUMBER(4,0),
c_bit1 BOOLEAN,
c_bit8 NUMBER(38,0),
note_nullable VARCHAR,
note_all_null VARCHAR
);
COPY INTO MS_STAGE
FROM @RIVET_STG/<your_mysql_file>.parquet
FILE_FORMAT = (TYPE = PARQUET BINARY_AS_TEXT = FALSE)
MATCH_BY_COLUMN_NAME = CASE_INSENSITIVE;
CREATE OR REPLACE TABLE MS AS
SELECT
id, c_tinyint, c_tinyint_u, c_bool, c_boolean,
c_smallint, c_smallint_u, c_int, c_int_u, c_bigint, c_bigint_u,
amount, fee, price, c_float, c_double, c_date,
TIME_FROM_PARTS(0, 0, 0, c_time * 1000) AS c_time,
TO_TIMESTAMP_NTZ(created_at_dt, 6) AS created_at_dt,
created_at_ts,
label, c_char, c_text, c_varchar, long_text, medium_text,
raw_bytes, var_bytes, blob_bytes,
uid,
PARSE_JSON(extras) AS extras,
enum_col, set_col, year_col, c_bit1, c_bit8,
note_nullable, note_all_null
FROM MS_STAGE;
DROP TABLE MS_STAGE;
Why these specific options
The non-obvious choices, in order of how surprising they were:
BINARY_AS_TEXT = FALSEis required in theFILE_FORMAT. Snowflake’s default treats ParquetBYTE_ARRAYwithout a logical type as UTF-8 text, so binary columns containing0xFFbyte fail withInvalid UTF8 detected while decoding. Text and JSON columns carry their ownLogicalTypeand are unaffected.- Two-step (stage → final) instead of
COPY INTO final FROM (SELECT ...). The$1:col::varcharsyntax that the single-step pattern needs also hits the UTF-8 decode on raw-binary BYTE_ARRAY columns — even when the target cast is::binary.MATCH_BY_COLUMN_NAMEon a stage table withBINARYcolumns avoids that path. ALTER SESSION SET TIMEZONE = 'UTC'before the load. Snowflake’s autoload ofTimestamp(MICROSECOND, isAdjustedToUTC=true)intoTIMESTAMP_TZrecords the session offset as the column’s TZ, which shifts the absolute instant by that offset. Pinning the session to UTC makes the recorded offset+00:00so the instant survives. (BigQuery does not have this issue.)NUMBER(38,0)forc_time,created_at,created_at_dtin staging. Snowflake’s autoload does not recognize ArrowTime64(MICROSECOND)orTimestamp(MICROSECOND, isAdjustedToUTC=false)asTIME/TIMESTAMP_NTZ; it surfaces the rawint64µs. We accept the raw value into NUMBER and convert withTIME_FROM_PARTS/TO_TIMESTAMP_NTZin the final SELECT.HEX_ENCODE(uid)+ regex becauseLogicalType::Uuidarrives asBINARY(16 bytes); the canonical8-4-4-4-12hyphenated form is rebuilt by SQL.PARSE_JSON(...)forattrs/attrs_json/extrasbecauseLogicalType::Jsonarrives asVARCHAR, notVARIANT. The bytes are already valid UTF-8 JSON so the parse is cheap.
Sanity checks
After the final tables are populated, the following queries should all return the original source values:
-- microseconds preserved on Time / Timestamp
SELECT id,
TO_VARCHAR(c_time, 'HH24:MI:SS.FF6') AS c_time_us,
TO_VARCHAR(created_at, 'YYYY-MM-DD HH24:MI:SS.FF6') AS created_at_us,
TO_VARCHAR(created_at_tz, 'YYYY-MM-DD HH24:MI:SS.FF6 TZH:TZM') AS created_at_tz_iso
FROM PG ORDER BY id;
-- Multi-byte UTF-8 survives
SELECT note_nullable, HEX_ENCODE(note_nullable) FROM MS WHERE id = 4;
-- expected hex: 756E69636F64653A20E697A5E69CACE8AA9E20F09F9A80
-- ^^^^^^^^^^^^^^^^^^^^^^^^ '日本語 🚀'
-- UINT64 max round-trips through the decimal override
SELECT c_bigint_u FROM MS WHERE id = 1;
-- expected: 18446744073709551615
-- Binary bytes recovered (no hex string substitution)
SELECT id, HEX_ENCODE(raw_bytes) FROM PG ORDER BY id;
-- expected: 00FF012345, DEADBEEF, CAFE, 00
Autoload fidelity table
For reference — what Snowflake’s MATCH_BY_COLUMN_NAME does out of the box
versus what we need:
| Parquet column | Snowflake autoload | What we want | Recovered via |
|---|---|---|---|
BYTE_ARRAY (no logical type) | VARCHAR (fails on non-UTF8) | BINARY | BINARY_AS_TEXT = FALSE |
BYTE_ARRAY + LogicalType::String | VARCHAR | VARCHAR | (unchanged) |
BYTE_ARRAY + LogicalType::Json | VARCHAR | VARIANT | PARSE_JSON(col) in final |
FixedSizeBinary(16) + LogicalType::Uuid | BINARY | canonical UUID | HEX_ENCODE + regex in final |
Time64(MICROSECOND) | (fails to bind to TIME) | TIME(6) | stage as NUMBER + TIME_FROM_PARTS |
Timestamp(MICROSECOND, no-tz) | (fails to bind to NTZ) | TIMESTAMP_NTZ | stage as NUMBER + TO_TIMESTAMP_NTZ |
Timestamp(MICROSECOND, UTC) | TIMESTAMP_TZ shifted | TIMESTAMP_TZ | ALTER SESSION SET TIMEZONE = 'UTC' |
UINT64 > 2^63-1 | overflow error | NUMBER(20,0) | rivet c_bigint_u: decimal(20,0) override |
List<X> | ARRAY | ARRAY | (unchanged) |
BigQuery’s bq load (with --parquet_enable_list_inference) handles items 4–7
natively. Snowflake autoload behavior may improve in future releases; treat
this recipe as a snapshot.
Continuous proof
The BigQuery half of this table is pinned by an end-to-end validator that
exports the canonical type matrices, runs bq load, and asserts the schema
- key values against the same expectations documented above:
gcloud auth application-default login
BIGQUERY_TEST_PROJECT=<your-gcp-project> make test-types-bigquery
Skips silently without BIGQUERY_TEST_PROJECT. Implementation:
tests/type_roundtrip/bigquery_load.rs. The Snowflake half is currently
verified manually against this recipe — a similar oracle would be welcome
once a service-account login path exists for new Snowflake trial accounts.
Loading rivet Parquet into ClickHouse (preview)
Status: Preview. Live-tested against ClickHouse 24.8 (the stand’s
clickhousecompose service). See Known limits and engine maturity for what is still open before GA.
rivet load writes an export’s Parquet into ClickHouse over the HTTP interface
(ADR-0035). The export may land in GCS, S3
or Azure (rivet init takes --gcs-bucket or --s3-bucket); the ClickHouse
database must already exist.
Generate the config
export DATABASE_URL="postgresql://user:pass@host/db"
export CLICKHOUSE_PASSWORD=...
rivet init --source-env DATABASE_URL --mode cdc --tls verify-full \
--gcs-bucket my-bucket \
--clickhouse-url http://clickhouse:8123 --clickhouse-database raw --clickhouse-user loader \
-o rivet.yaml
rivet run -c rivet.yaml # Parquet into GCS
rivet load -c rivet.yaml # Parquet into ClickHouse
A CDC scaffold captures changes from its anchor on; rows that existed before are not
in it. For them, set cdc.initial: snapshot (or a cdc.backfill:) before the first run.
The generated block:
load:
target: clickhouse
url: http://clickhouse:8123
database: raw
user: loader
password_env: CLICKHOUSE_PASSWORD
pk: auto
cluster_by: auto
cleanup_source: true
One cycle is run + load — no compact step
rivet run -c rivet.yaml
rivet load -c rivet.yaml
Put those two lines on the schedule. There is no third step: a CDC table’s change
log is a ReplacingMergeTree(__ver), and ClickHouse itself collapses the versions
of a key in its background merges. The view <table> reads the log with FINAL, so
it returns one row per key — the latest version — whether or not those merges have
run yet. A change delivered twice (at-least-once after an interrupted run, or a
re-run load) carries the same key and version, so it collapses the same way.
rivet compact on a ClickHouse config does nothing: it passes a change-log table
by with “this warehouse keeps a change log behind a view and never compacts; nothing
to merge” (and a full-load table with “a full load overwrites its table”). A deleted key stays in the log as its last version with __is_deleted
set, so live state is WHERE NOT __is_deleted.
What lands
| Export mode | In ClickHouse |
|---|---|
full, chunked, time_window | <table>, a MergeTree replaced whole by every load (filled beside it, then swapped in) |
cdc | <table>__changes, a ReplacingMergeTree keyed on the primary key, and the view <table> |
incremental | the first run lands <table> as a MergeTree; the first delta renames it to <table>__changes and <table> becomes a view picking the latest cursor per key |
For a CDC table the engine keeps one version per key: the highest version, computed
from the change’s source position (PostgreSQL LSN, MySQL binlog file number + offset,
SQL Server LSN) and its order within the transaction. Insert order does not matter as
long as the source’s positions only grow; a MySQL binlog renumbered by RESET MASTER
or a failover breaks that (see Known limits). The view reads the log
with FINAL and flags deletes:
SELECT * FROM raw.orders WHERE NOT __is_deleted;
ClickHouse does not allow PREWHERE on the view. If you read <table>__changes FINAL
directly, filter non-key columns in WHERE: a PREWHERE runs before the engine
collapses versions and can return an old one.
Letting ClickHouse read the bucket itself
By default rivet reads each part from GCS and sends it to ClickHouse. With a named collection ClickHouse reads the part directly, and no data passes through the host running rivet:
-- once, as an administrator. GCS: HMAC keys from "Interoperability"; S3: the service
-- endpoint (e.g. https://s3.<region>.amazonaws.com/ — rivet appends the bucket) and keys;
-- Azure: a connection string (the container is the export's bucket).
CREATE NAMED COLLECTION gcs_raw AS
url = 'https://storage.googleapis.com/',
access_key_id = '...',
secret_access_key = '...';
CREATE NAMED COLLECTION azure_raw AS connection_string = '...';
GRANT NAMED COLLECTION ON gcs_raw TO loader;
load:
target: clickhouse
# …
named_collection: gcs_raw
Known limits
-
Timestamp range.
DateTime64holds 1900-01-01 to 2299-12-31. When rivet sends a part, it reads the part’s footer first and refuses it, inserting nothing, if a timestamp column holds a value outside that range or has no min/max statistics (RIVET_LOAD_VALUE_OUT_OF_TARGET_RANGE). A part ClickHouse pulls through a named collection is not inspected: an out-of-range timestamp is stored as the nearest end of the range, silently. ADate32outside the same range fails the insert: ClickHouse refuses it itself (measured on a part rivet sends). -
Types that land as something else.
uuidlands asFixedString(16)(the 16 raw bytes; the type report carries thetoUUIDexpression to recover it),json/jsonbasStringholding the JSON text,timeasDecimal64seconds since midnight, and a NULL array as[](a ClickHouseArraycannot be NULL).rivet check --type-report --target clickhouselists each one. -
No retries. Every statement is one HTTP request with a fixed 1200-second timeout; a failed request fails the load. A CDC load re-run inserts the same versions, which the engine collapses; a full load re-run swaps in a fresh table.
-
MySQL binlog renumbering. The version orders MySQL changes by binlog file number, then offset. After
RESET MASTER, or a failover to a server whose binlog files are numbered lower, new changes carry lower versions and lose to older versions of the same keys. -
Grants. The load’s user needs, on the target database (measured on 24.8):
GRANT SELECT, INSERT, ALTER ADD COLUMN, CREATE TABLE, DROP TABLE, CREATE VIEW, DROP VIEW ON raw.* TO loader;DROP TABLEcovers the full load’sCREATE OR REPLACEof its swap table and theEXCHANGE TABLESthat swaps it in; the catalog reads (system.tables,system.columns) need nothing more. A pulled load also needsGRANT NAMED COLLECTION ON <name>. -
TLS. An
https://URL uses rustls with the Mozilla root certificates built into rivet. A server certificate signed by a private CA is not accepted, and there is no option to add one.
Not supported
- MongoDB CDC into ClickHouse: the resume token has no integer order the change log can version by. Load it into BigQuery or Snowflake.
partition:: a change log collapses versions only within a partition.rivet compactandlayout: base_buffer: the engine collapses the log itself, so there is nothing to merge.- A CDC stream over a table from an earlier full load: refused; drop or
rename the table first. The change log holds only changes from the stream’s
anchor on, so to keep the table’s existing rows also set
cdc.initial: snapshot(or acdc.backfill:) andrivet runagain before the load; the stream is already anchored, so the snapshot overlaps it and nothing falls between them. - A primary-key update leaves the old key live, as on every warehouse (ADR-0030).
Run Rivet on Apache Airflow
Rivet extracts your tables; Airflow schedules and watches them. This recipe makes
Airflow’s graph be Rivet’s extraction plan — small tables parallelised, heavy
tables run one at a time, a barrier between waves — with per-table retries, logs,
and alerting for free, and a real rivet binary doing the work. It builds one
DAG per source database (PostgreSQL, MySQL, SQL Server) from a single factory.
MongoDB fits the same pattern. MongoDB is a first-class Rivet source (full + CDC), so a
mongo.yamlconfig yields arivet_waves_mongoDAG analogous to the relational ones — same factory, same plan → waves → graph. The checked-in demo ships the three relational engines; add a Mongo config to extend it.
docs/recipes/airflow/
├── Dockerfile # apache/airflow + the rivet release binary baked in
├── docker-compose.2.10.yaml # official Airflow 2.10 stack, adapted
└── dags/
├── rivet_waves_dag.py # factory → rivet_waves_{postgres,mysql,mssql}
├── postgres.yaml / mysql.yaml / mssql.yaml # the configs you edit ← yours
└── postgres.plan.json / mysql.plan.json / … # rivet plan output (auto-refreshed)
Try it locally
This is the official Apache Airflow docker-compose stack (Postgres metadata +
Redis + CeleryExecutor — not SQLite/Sequential), adapted three ways: example DAGs
are off, the worker image has rivet baked in, and a dedicated TLS-enabled
Postgres holds Rivet’s durable run state.
cd docs/recipes/airflow
docker compose -f docker-compose.2.10.yaml up --build # Airflow 2.10.5
First boot builds the image and migrates the metadata DB (~2-3 min). Then open
http://localhost:8080 (login airflow / airflow). There are seven DAGs
— rivet_waves_postgres, rivet_waves_mysql, rivet_waves_mssql
(local Parquet), the same three with an _s3 suffix (shared MinIO bucket), and
rivet_waves_postgres_gcs — all from the same factory (a MongoDB config would
add an eighth, rivet_waves_mongo). Un-pause and trigger one, and open Graph:
plan ──> wave_2 ──────────> wave_3 ───────────────> wave_4
[small tables [bench_decimal → [bench_narrow →
in parallel] bench_hc → content_items]
orders → bench_wide] (one at a time)
- The demo runs against the project’s fixtures on the host (Postgres :5432, MySQL
- 3306, SQL Server :1433), so
docker compose upin the rivet repo first.docker compose -f … down -vtears everything down (-vdrops the state too).
(The DAG keeps a try/except around the BashOperator import so it still parses
on Airflow 3.x — where it moved to the standard provider — if you point it at a
3.x stack yourself.)
What the graph does
plan → waves. rivet plan scores every export (size, cursor quality, chunk
geometry, risk) and groups them into waves. The DAG runs the waves lowest-first
with a barrier between them — wave N+1 starts only after every task in wave N
succeeds.
Cheap parallel, heavy serial — within a wave. This is the part that matters:
only the cheap exports (planner cost_class: low) run in parallel. The heavier
ones run one at a time (a sequential chain). The whole reason the planner
defers big tables into a late wave is to not pile several large scans onto the
source at once — so running them in parallel would defeat the point. (Same split
as the in-engine rivet apply --parallel-export-processes.)
Each task is a real rivet run. A wave task is rivet run --config <source>.yaml --export <table> — a single table, with --reconcile (source
COUNT(*) vs exported rows) on a fresh full/chunked export. The task log is the
actual rivet output:
✓ orders incremental 250,000 rows 1 files 3.4 MB 2.7s RSS 64 MB
A failing reconcile (or any error) exits non-zero with a stable [RIVET_*] code,
so the task fails loudly and the wave barrier stops everything downstream — before
a half-extracted table reaches a warehouse load.
Config → plan → graph (no manual steps)
The graph is generated from Rivet’s planner, and each DAG’s plan task keeps it
fresh:
dags/<source>.yamlis the config you edit (postgres.yamletc).rivet init --source <url>scaffolds one from your live schema (use--exclude '<glob>'to drop test / junk tables); the checked-in samples are the fixtures trimmed to a clean set.- The DAG’s first task,
plan, runsrivet plan --format jsonand atomically rewrites<source>.plan.json(temp file, swapped in only if rivet succeeded and the output is valid JSON — a failed plan can’t truncate the graph source and break the DAG). - The DAG reads
<source>.plan.jsonat parse time to lay out the waves. So editing the config and re-running the DAG re-shapes the graph on the next parse — no hand-run CLI, no committing the plan by yourself. The checked-in sample makes the DAG work on the very first boot.
Same-named tables across engines never collide: each source writes to its own
./output/<engine>/<table>/ and keeps its own state database, so a bench_hc in
Postgres and one in MySQL don’t share cursor / shape / file-log state.
Skip tables — you don’t have to extract everything
Set an env var on the workers (or in the compose environment:):
| Variable | Effect |
|---|---|
RIVET_EXCLUDE | Comma-separated tables to drop. A wave left empty disappears. |
RIVET_ONLY | Comma-separated allow-list — run only these. |
Many sources → one bucket
For a shared S3 / GCS data lake, point each export’s destination: block —
nested inside every exports[] entry, as in the checked-in
dags/postgres.s3.yaml; there is no top-level destination in rivet configs —
at the same bucket with a per-source prefix so same-named tables across
engines never collide:
# postgres.s3.yaml
exports:
- name: bench_hc
# ...
destination:
type: s3
bucket: my-data-lake # ← one bucket for every source
prefix: rivet/postgres/{export}/ # ← namespaced by source; {export} = table
# mysql.s3.yaml → prefix: rivet/mysql/{export}/
# mssql.s3.yaml → prefix: rivet/mssql/{export}/
A bench_hc then lands at s3://my-data-lake/rivet/postgres/bench_hc/, the MySQL
one at …/rivet/mysql/bench_hc/ — separate objects. The namespace is required,
not cosmetic: different databases are different data, and the same logical table
yields different Arrow types per engine (uuid_col is FixedSizeBinary(16) on
PG/MSSQL but Utf8 on MySQL; MySQL drops the timestamp’s UTC tz) — merging them
under one prefix would write a dataset with incompatible schemas.
The checked-in *.s3.yaml / postgres.gcs.yaml configs build the cloud DAGs
(rivet_waves_<source>_s3, rivet_waves_postgres_gcs); the demo writes to the
project’s MinIO / fake-gcs emulators (worker env supplies AWS_ACCESS_KEY_ID /
AWS_SECRET_ACCESS_KEY). A real bucket drops the endpoint + allow_anonymous
and uses normal cloud credentials.
Recovery — all from Airflow, no shell
A chunked export checkpoints per chunk, so a kill mid-chunk is recoverable. The whole recovery story is operable from the Airflow UI:
| Situation | What to do |
|---|---|
| Transient crash mid-chunk (worker killed, timeout, retry) | Nothing — automatic. The retry’s plain run resumes the crashed checkpoint from the last good chunk. A checkpoint still held by a LIVE rivet process is refused, and the task fails rather than touch it. |
| Unresumable checkpoint (chunk params changed, or you want a clean re-extract) | Admin → Variables → rivet_reset = comma-list of tables → trigger the DAG. Each listed table’s checkpoint is wiped (rivet state reset-chunks) before its run. Clear the Variable afterwards. |
| Anything else | the normal task Clear / re-trigger in the UI. |
A resumed run writes only the chunks left after the crash, so the reconcile gate
is dropped on the resume path (a full-table COUNT(*) would false-mismatch the
remainder) — the same reasoning as skipping reconcile on incremental exports.
Architecture
rivetbinary — baked into the worker image from the published release (Dockerfile, arch-aware: pulls thex86_64oraarch64linux build). To pin a version, setRIVET_VERSIONin the composebuild.args.- Durable state —
rivet-state-db, a dedicated TLS Postgres service, with a separate database per source (rivet_state_postgres/_mysql/_mssql); the factory passes each DAG its ownRIVET_STATE_URLwithsslmode=require. SQLite state in a bind-mount corrupts under parallel writers; Rivet refuses to send state credentials in cleartext to a non-loopback host (CWE-319), so the service speaks TLS (a self-signed cert generated at startup — fine in-cluster). - Source credentials — Airflow Connections. Each source is an Airflow
Connection (
rivet_postgres/rivet_mysql/rivet_mssql), editable in the UI (Admin → Connections); the demo seeds them viaAIRFLOW_CONN_*in the compose so it works out of the box. The DAG builds the URL from the connection’s fields in rivet’s scheme — notget_uri(), whose scheme differs per engine (Airflow emitsmssql://, rivet wantssqlserver://) — and exports it as the env var the config’surl_envreads. Nothing about a database is hard-coded in the DAG. The demo opts into plaintext to the fixtures withsource.tls: { mode: disable }; a real remote DB usesmode: verify-full. - State schema is created up front.
initdbcreates the state databases, but rivet’s tables are created on first connect — under parallelism that races (“create version table: db error”). A one-shotrivet-state-schema-initservice runsrivet state showagainst every state DB at boot, so the schema exists before any wave task runs. The Airflow services wait for it.
Why this shape
Rivet’s planner is deliberately advisory (ADR-0006):
it scores and groups, it does not schedule. That’s what lets a real scheduler own
execution — retries, backfills, SLAs, alerting — while Rivet owns source safety
(which tables to defer, which to run serially, how hard to push the database).
This recipe is the seam between the two: the planner’s waves and cost classes
become Airflow’s graph, and nothing about your database or its credentials leaves
your environment.
CLI Guide
📌 The exhaustive command/flag reference is generated from the code: cli-reference.md — rendered from the clap definitions (the same source as
--help), so it cannot drift and needs no manual verification. This page is the guide: the same commands with worked examples, output samples, and the why. For the guaranteed-current flag list of any command, trust the generated reference (or runrivet <command> --help).
Machine-readable output. Most commands emit JSON via a boolean
--jsonflag (run,check,doctor,metrics,state …);validate(and thereconcile/planreport writers) instead take--format json. This split is a known inconsistency to be unified in a future release — until then, pass--helpto confirm which idiom a given command uses.
Global
rivet [--json-errors] [COMMAND] [OPTIONS]
rivet --version # print version
rivet --help # show help
| Flag | Description |
|---|---|
--json-errors | Output errors as {"error":"..."} JSON to stderr instead of plain text. Applies to all subcommands. Useful for machine-readable orchestration and CI pipelines. |
rivet --json-errors run --config rivet.yaml
rivet run --config rivet.yaml --json-errors # global flag accepted in any position
rivet run
Run export jobs defined in a config file.
rivet run --config <PATH> [OPTIONS]
| Flag | Short | Type | Description |
|---|---|---|---|
--config | -c | string | Path to YAML config file (required) |
--export | -e | string | Run only a specific export by name |
--validate | bool | Validate output file row count after writing | |
--reconcile | bool | Run COUNT(*) on source query and compare with exported rows | |
--resume | bool | Resume an in-progress chunked export. Exits non-zero with an actionable message if no in-progress checkpoint exists — run without --resume to start fresh, or rivet state reset-chunks to clear a stuck run | |
--force | bool | Override safety gates that would otherwise refuse the run. Today: with --resume, allows starting against a destination prefix whose _SUCCESS marker is already present (ADR-0012 M8). Without it, resume against a complete run refuses so an operator cannot accidentally re-export over a verified dataset | |
--parallel-exports | bool | Run the config’s exports concurrently, at most 16 at once; a CDC export run alone also takes its pending baseline snapshots at most 16 at once | |
--parallel-export-processes | bool | Run each export as a separate child process | |
--summary-output | PATH | Write run aggregate to this file as JSON | |
--json | bool | Print run aggregate to stdout as JSON after the run | |
--param | -p | KEY=VALUE | Query parameter (repeatable). Substitutes ${key} in queries |
Examples
# Basic run
rivet run -c my_export.yaml
# Run with validation and reconciliation
rivet run -c my_export.yaml --validate --reconcile
# Run a single export
rivet run -c my_export.yaml -e orders_daily
# Resume interrupted chunked export
rivet run -c my_export.yaml -e big_table --resume
# Parameterized query
rivet run -c my_export.yaml -p region=us-east -p year=2026
# Parallel exports (all at once)
rivet run -c my_export.yaml --parallel-exports
# Parallel exports — one OS process per export, parent-side cards UI
rivet run -c my_export.yaml --parallel-export-processes
--parallel-export-processes — one card per export
--parallel-exports runs the exports in the same Rivet process on up to 16
worker threads. That keeps logs simple, but every export shares the same source
connection pool / global allocator. A panic in one export is caught and reported
as that export’s failure while the others finish (release builds unwind; the
release-min profile aborts instead).
--parallel-export-processes instead spawns one rivet child process per
export — full memory and connection isolation, no shared allocator. The parent
process owns the screen and renders one card per export with a live
progress bar, ETA, row count, and elapsed time. When a child finishes, the
progress bar is replaced in place with the export’s final metrics, so the
on-screen card becomes a self-contained per-export summary; below the cards a
single aggregated Run summary block prints once for the whole run.
▸ orders chunked 11/20 chunks 1.1M rows 8.7K r/s 2m 06.0s ETA 1m 43.1s
One card line per export (▸ running, ✓ finished), redrawn in place; the
children’s verbose per-export output goes to a timestamped log file beside the
config.
Children emit structured NDJSON events (Started, ProgressInit,
Progress, Finished) on stdout via the RIVET_IPC_EVENTS=1 env var; the
parent multiplexes them into the cards UI. If a child crashes without a
Finished event, its card is marked failed with a synthetic warning so a
silent crash never leaves the run looking healthy.
rivet cdc
Stream log-based change data capture directly (without a config). The engine is
chosen from the URL scheme — mysql:// (binlog) / postgresql:// (logical slot) /
sqlserver:// (change tables) / mongodb:// (change stream). Emits NDJSON to
stdout by default, or typed Parquet/CSV with --output (--output requires
exactly one --table — the schema is resolved from the source); --checkpoint
persists a resume position.
rivet cdc --source-env DATABASE_URL --table orders # NDJSON to stdout
rivet cdc --source-env DATABASE_URL --table orders --output ./cdc --format parquet --checkpoint ./o.ckpt
The full reference — per-engine prerequisites, --slot / --capture-instance /
--server-id, --stream (opt into continuous; bounded is the default), the config-driven rivet run + mode: cdc path
(the fuller path, all four engines incl. MongoDB), and the failure/recovery
playbook — is in cdc.md.
rivet plan
Generate a sealed execution plan artifact — no data is exported.
rivet plan runs preflight analysis (row estimate, index check, sparsity), computes chunk boundaries for chunked exports, snapshots the current cursor for incremental exports, and writes everything to a PlanArtifact JSON file. The artifact can be reviewed, committed, stored as a CI artifact, or passed to rivet apply.
rivet plan --config <PATH> [OPTIONS]
| Flag | Short | Type | Default | Description |
|---|---|---|---|---|
--config | -c | string | — | Path to YAML config file (required) |
--export | -e | string | all | Plan only a specific export |
--param | -p | KEY=VALUE | — | Query parameter (repeatable) |
--output | -o | string | stdout | Write plan JSON to this file |
--format | pretty|json | pretty | pretty prints a human summary; json writes the full artifact |
Examples
# Human-readable summary (no file written)
rivet plan -c rivet.yaml
# Write full JSON artifact to a file
rivet plan -c rivet.yaml --format json --output plan.json
# Plan a single export
rivet plan -c rivet.yaml -e orders --format json -o orders_plan.json
Pretty output (example)
Plan ID : a1b2c3d4e5f6...
Created : 2026-04-14 10:00:00 UTC
Expires : 2026-04-15 10:00:00 UTC
Export : orders
Strategy : chunked
Chunks : 42
Row est. : ~2,100,000
Verdict : Acceptable
Profile : balanced
Warnings :
• sparse id range: ~12% fill
Resources:
Batch size : 10,000 rows
Batch memory : ~2 MB (narrow) – ~95 MB (wide)
RSS guard : 4,096 MB
Throttle : 50 ms between batches
Output : local → ./out
Format : parquet + zstd
The Resources section shows:
| Line | Meaning |
|---|---|
Batch size | Rows fetched per query. adaptive if batch_size_memory_mb is set. |
Batch memory | Estimated range: narrow (~200 B/row) to wide (~10 KB/row) tables. |
RSS guard | Process-level RSS threshold. Fetching pauses if exceeded (0 = disabled). |
Throttle | Delay between batches to reduce source load (omitted when 0). |
⚠ Wide tables may use… | Shown when the upper bound exceeds 128 MB/batch — consider batch_size_memory_mb or a lower batch_size. |
Memory estimate methodology — advisory only
The memory estimate in
rivet planis a heuristic, not a guarantee. Treat it as a planning signal, not a hard prediction.
rivet plan does not sample the table. It computes the batch memory range using two fixed assumptions:
- Narrow bound — 200 B per row (all INTEGER / BIGINT / TIMESTAMPTZ columns)
- Wide bound — 10 KB per row (all TEXT / JSONB / BYTEA columns)
For most real tables the actual per-row size falls between these two bounds. The narrow bound is a reliable floor for numeric-heavy schemas; the wide bound is a reliable ceiling for text-heavy schemas.
What the estimate does not capture:
| Factor | Effect on actual RSS |
|---|---|
| Highly variable TEXT/BLOB values | Actual batches can be 2–10× the wide estimate |
| Sparse nullable columns | Actual batches will be below the narrow estimate |
| Compression buffers in the Parquet writer | Adds 50–200 MB on top of the Arrow batch size |
| Tokio runtime, connection pool, jemalloc | Adds 50–150 MB baseline overhead |
How to get a precise number: run rivet run once with RUST_LOG=info against a representative sample, then check the peak_rss in the logged summary or in rivet metrics. That measured value from your actual data is more reliable than any pre-run estimate.
Planned enhancement: a future rivet plan --sample N flag will query up to N rows to compute a data-driven row-width estimate. This will narrow the uncertainty for variable-width schemas without a full table scan.
Plan artifact structure
The JSON artifact (--format json) contains:
{
"rivet_version": "0.18.0",
"plan_id": "a1b2c3d4...",
"created_at": "2026-04-14T10:00:00Z",
"expires_at": "2026-04-15T10:00:00Z",
"export_name": "orders",
"strategy": "chunked",
"plan_fingerprint": "0123456789abcdef",
"resolved_plan": { ... },
"computed": {
"chunk_ranges": [[1, 50000], [50001, 100000], "..."],
"chunk_count": 42,
"cursor_snapshot": null,
"row_estimate": 2100000
},
"diagnostics": {
"verdict": "Acceptable",
"warnings": ["sparse id range: ~12% fill"],
"recommended_profile": "balanced"
}
}
Security note:
resolved_planembeds the full source connection config including credentials. Treat plan files with the same care as your rivet config file.
rivet apply
Execute a sealed plan artifact, or run a config’s exports wave-by-wave. The mode is chosen by the path’s extension:
.json→ a sealedPlanArtifact: deserialize, validate staleness + cursor integrity, then execute the single export using the artifact’s pre-computed chunk boundaries — noSELECT min/maxqueries against the source..yaml/.yml→ a config: run every export wave by wave in ascendingwave:order (the wave each export was assigned byrivet plan). See Wave-ordered execution below.
rivet apply <PLAN_FILE | CONFIG> [OPTIONS]
| Argument/Flag | Type | Description |
|---|---|---|
PLAN_FILE / CONFIG | string | Path to a plan JSON artifact, or a YAML config for wave-ordered execution (required) |
--force | bool | Overrides whichever safety gate refuses the run (ADR-0013). JSON-artifact mode: bypasses the staleness check (plans > 24 h) and the incremental cursor-drift check (both logged and recorded in the run’s apply_context). YAML config mode: meaningful only with --resume, where it overrides the refusal to resume into a destination whose _SUCCESS marker is already present; without --resume it is a warned no-op |
Staleness rules
| Plan age | Behavior |
|---|---|
| < 1 hour | Proceeds silently |
| 1–24 hours | Warns and proceeds |
| > 24 hours | Rejects — use --force to override |
Cursor drift (Incremental exports)
If another rivet run completed after the plan was generated, the cursor will have advanced. rivet apply detects this and rejects the artifact to prevent re-exporting already-exported rows. Regenerate with rivet plan.
Examples
# Apply the plan
rivet apply plan.json
# Apply an old plan (override staleness check)
rivet apply plan.json --force
What apply does NOT do
- Does not re-read the config file
- Does not re-run preflight queries
- Does not recompute chunk boundaries (uses pre-computed ranges from the artifact)
- Does not enforce preflight verdict (diagnostics are advisory — see ADR-0005)
State location
rivet apply opens .rivet_state.db next to the config file recorded inside the plan artifact (artifact.config_path), so apply shares the same state (cursors, manifests, schema history) as rivet run. It falls back to the plan file’s own directory — with a warning — only when the recorded config directory no longer exists or the artifact was generated before 0.7.5. Plan files do not need to sit beside the config.
Wave-ordered execution (YAML config)
rivet apply <config>.yaml runs every export in the config wave by wave, lowest wave: first, with a barrier between waves — every export in wave 1 finishes before wave 2 starts. Exports with no wave: run last. rivet plan --annotate-waves writes the wave: and parallel_safe: fields onto each export (you can hand-edit them; apply respects your order). Plain rivet plan is read-only and leaves the config untouched.
Within-wave parallelism. With parallel_export_processes: true in the config (or rivet apply --parallel-export-processes), the cheap exports within a wave — those rivet plan marked parallel_safe: true (cost class Low, < ~100K rows) — run concurrently as separate processes. A heavier export already chunk-parallelizes its own ranges internally, so it runs alone in its wave; two large tables at once would multiply load on the source. Each child still self-throttles via the adaptive governor. Without the flag, every export runs sequentially. parallel_safe also respects the campaign’s isolate_on_source — a cheap export on a contended shared source still runs alone.
# plan assigns waves → you review/edit → apply executes them, lowest wave first
rivet plan -c rivet.yaml # review the schedule (read-only)
rivet plan -c rivet.yaml --annotate-waves # write wave:/parallel_safe: into the config
rivet apply rivet.yaml
A failing export does not stop its wave-mates: failures are collected and the run exits non-zero with the most stop-worthy error (data-integrity > internal > refusal > schema-drift > retryable > generic).
Resuming after a partial failure. Re-run with rivet apply <config>.yaml --resume: exports a prior run already completed (their destination carries a _SUCCESS marker) are skipped, and an incomplete chunked export continues from its checkpoint — so recovering a run that failed mid-way does not redo the tables that already succeeded. Without --resume, a re-run re-exports everything.
partition_by exports are not expanded in this path yet — use rivet run for those.
rivet validate
Re-run manifest-aware verification against an existing destination — no extraction.
rivet validate --config <PATH> [OPTIONS]
The same M5/M6 checks rivet run --validate performs at end-of-run, exposed as a standalone command for between-run polling and triage. Reads manifest.json + _SUCCESS at the destination and head-checks every committed part for presence and recorded size_bytes. The source is not queried (use rivet reconcile for that). See ADR-0013 §“Subcommand carveouts” and ADR-0012 M5/M6.
By default validate resolves the destination prefix the same way run does ({date} becomes today’s UTC date). Use --date, --run-id, or --prefix to point at a prior run instead.
| Flag | Short | Type | Description |
|---|---|---|---|
--config | -c | string | Path to YAML config file (required) |
--export | -e | string | Validate only a specific export by name |
--format | pretty|json | Output format: pretty (human summary) or json (machine-readable) | |
--depth | light|sample|full | Verification depth: light (manifest + _SUCCESS), sample (+ part reconcile + untracked surplus), full (+ value-checksum re-read of every part; default). CSV parts carry no value checksum: at full each CSV part’s rows are re-counted against the manifest and a RIVET_VERIFY_VALUE_CHECK_NOT_AVAILABLE warning says no cell values were re-read | |
--output | -o | PATH | Write the JSON report to this file (only with --format json) |
--date | YYYY-MM-DD | Resolve {date} to this date instead of today (UTC) | |
--run-id | string | Substitute {run_id} in the destination prefix template (composes with --date). No run lookup is performed — if the template has no {run_id} placeholder this has no effect; use --prefix for an arbitrary path | |
--prefix | string | Point at an explicit destination prefix |
Exits non-zero when the manifest references a part that is missing or whose size does not match, and when the manifest records its last run as anything but success (RIVET_VERIFY_RUN_NOT_SUCCESSFUL, exit 1: a failed, interrupted or still-running export is not a completed dataset). A legacy prefix (no manifest) falls back to the M6 reduced-guarantee path and is labelled legacy_run: true.
Examples
# Verify today's run at the configured destination
rivet validate -c my_export.yaml
# Verify a prior run by id, JSON report to a file
rivet validate -c my_export.yaml --run-id orders_20260521T120000 --format json -o verdict.json # -o is ignored unless --format json is set
rivet reconcile
Partition/window reconciliation — re-runs per-chunk COUNT(*) on the source and compares with the stored per-chunk row counts from the last run. Surfaces matches, mismatches, and repair candidates without re-exporting data (Epic F).
rivet reconcile --config <PATH> --export <NAME> [OPTIONS]
| Flag | Short | Type | Description |
|---|---|---|---|
--config | -c | string | Path to YAML config file (required) |
--export | -e | string | Export name to reconcile (required) |
--format | pretty | json | Output format (default pretty) | |
--output | -o | string | Write JSON report to this file (use with --format json) |
--param | -p | KEY=VALUE | Query parameter (repeatable) |
Scope (v1)
- Chunked exports — supported. Requires a previous run with
chunk_checkpoint: trueso per-chunk ranges and row counts are persisted in.rivet_state.db. - Time-window — returns an error (“use chunked with
chunk_by_days” for partition reconcile). - Snapshot / Incremental — no natural partitions; use
rivet run --reconcilefor a whole-export count check.
What it does
For each completed chunk task from the latest chunk run:
- Rebuilds the exact chunk query the pipeline used (same
WHEREpredicate, same dense/range shape —build_chunk_query_sql). - Runs
SELECT COUNT(*) FROM (<chunk_query>) AS _rc. - Compares the source count with the stored
rows_writtenfor that chunk.
Each partition is classified as:
match— source and exported counts are equal.mismatch— counts differ; partition is a repair candidate (note includesdiff).unknown— one of the counts is unavailable (chunk never completed, unparseable chunk keys); also a repair candidate.
Examples
# Human-readable summary
rivet reconcile -c my_export.yaml -e orders
# JSON report to file
rivet reconcile -c my_export.yaml -e orders --format json -o reconcile.json
Reports never re-export on their own — they surface what needs repair. They are not merely advisory though: a detected mismatch exits non-zero with the data-integrity class (exit 3), so CI can gate on it.
Verification strategy tradeoffs
Rivet has three verification mechanisms at different cost/precision tradeoffs:
| Mechanism | What it checks | Cost | When to use |
|---|---|---|---|
rivet run --reconcile | COUNT(*) source vs exported rows for the whole export | 1 extra query | Snapshot / incremental exports; cheap sanity check after every run |
rivet reconcile | Per-chunk COUNT(*) source vs stored chunk row counts | 1 query per chunk | Chunked exports with chunk_checkpoint: true; catches partial writes in individual chunks |
rivet check --type-report | Column type fidelity + warehouse compatibility | 1 LIMIT-0 probe | Before first export of a new table; after source schema changes |
Rule of thumb:
- Use
--reconcilealways for snapshot/incremental exports — cost is negligible. - Use
rivet reconcilefor chunked exports if data correctness is critical or the source is volatile. - Use
rivet repaironly whenrivet reconcilesurfaces mismatches — it re-exports only the flagged chunks.
rivet repair
Targeted repair of chunks flagged by reconcile. Prints a RepairPlan by default; with --execute, re-exports only the flagged chunk ranges (Epic H, ADR-0009 RR1–RR8).
rivet repair --config <PATH> --export <NAME> [OPTIONS]
| Flag | Short | Type | Description |
|---|---|---|---|
--config | -c | string | Path to YAML config file (required) |
--export | -e | string | Export name to repair (must be mode: chunked) (required) |
--report | path | Path to a reconcile JSON report (from rivet reconcile --format json). Omit to run reconcile in-process against the latest chunk run | |
--execute | bool | Actually re-export the flagged chunk ranges. Without this flag, the plan is printed and nothing is executed (RR2) | |
--format | pretty | json | Output format for the plan / post-execute report (default pretty) | |
--output | -o | string | Write plan / report JSON to this file (with --format json) |
--param | -p | KEY=VALUE | Query parameter (repeatable) |
Examples
# Dry run from the latest reconcile — prints the plan, nothing executes
rivet repair -c my_export.yaml -e orders
# Dry run from a saved reconcile report
rivet repair -c my_export.yaml -e orders --report reconcile.json
# Execute — re-runs only the flagged chunks
rivet repair -c my_export.yaml -e orders --report reconcile.json --execute
What --execute does and does not do
- Re-runs only the flagged chunk ranges via
ChunkSource::Precomputed— same SQL shape as extraction and reconcile (RR3). - Writes new files alongside originals named
<export>_<ts>_chunk<idx>_<nonce>.<ext>, where<nonce>is a random 16-hex-digit value (RR5) — the nonce, not the second-granularity timestamp, is what guarantees a repair landing in the same second as the original can never clobber it. Rivet does not delete or overwrite prior files. Downstream deduplication (or a versioned output prefix) is the operator’s responsibility. - Leaves
last_committed_*untouched (RR4) — repair is corrective, not commitment.last_verified_*re-advances only if a subsequent cleanrivet reconcileruns.
rivet check
Preflight analysis: diagnose source health, estimate row counts, check indexes, recommend tuning. With --type-report, also introspects column types and validates them against a target warehouse.
rivet check --config <PATH> [OPTIONS]
| Flag | Short | Type | Description |
|---|---|---|---|
--config | -c | string | Path to YAML config file (required) |
--export | -e | string | Check only a specific export |
--param | -p | KEY=VALUE | Query parameter (repeatable) |
--type-report | bool | Run a type fidelity report: show each column’s source type, Rivet type, Arrow type, and fidelity | |
--strict | bool | Exit non-zero if any column mapping is lossy or unsupported (use with --type-report) | |
--json | bool | Emit type report as newline-delimited JSON instead of a table | |
--target | string | Validate types against a warehouse target: bigquery | snowflake | duckdb | clickhouse |
Examples
# Standard preflight check
rivet check -c my_export.yaml
# Type fidelity report (human-readable table)
rivet check -c my_export.yaml --type-report
# Type report with BigQuery compatibility column
rivet check -c my_export.yaml --type-report --target bigquery
# Type report as JSON — pipe-friendly, one object per export
rivet check -c my_export.yaml --type-report --json
# Strict mode — exits 1 if any lossy or unsupported mapping exists
rivet check -c my_export.yaml --type-report --strict
Type report output
Export: orders [target: bigquery]
Column Source type Rivet type Arrow type Fidelity Target type Status
---------- ---------------- --------------- -------------------- -------------- ----------- ------
id int4 int4 Int32 exact INT64 ok
amount numeric(15,4) decimal(15,4) Decimal128(15, 4) exact NUMERIC ok
created_at timestamptz timestamp_tz Timestamp(us, UTC) exact TIMESTAMP ok
metadata jsonb json Utf8 logical_string STRING ok ~
tags text[] list<text> List(Utf8) exact REPEATED… ok
Fidelity levels:
| Level | Meaning |
|---|---|
exact | Round-trips without loss |
compatible | Structurally compatible; minor representation difference |
logical_string | Serialized to STRING/text (no native Arrow type) |
lossy | Precision or range reduction |
unsupported | No safe mapping exists; the export fails with N column(s) have no safe Rivet mapping — add column overrides in rivet.yaml, and rivet check --strict exits non-zero |
Output includes: table existence, estimated row count, index analysis, tuning recommendation.
rivet doctor
Verify source and destination connectivity/auth before running exports.
rivet doctor --config <PATH>
| Flag | Short | Type | Description |
|---|---|---|---|
--config | -c | string | Path to YAML config file (required) |
Example
rivet doctor -c my_export.yaml
Output:
rivet doctor: verifying auth for config 'my_export.yaml'
[OK] Config parsed successfully
[OK] Source auth (Postgres)
[OK] Destination Local(./output)
All checks passed.
When tls: is omitted from source: and the host is loopback, nothing is printed (local dev is exempt). On a remote host the [WARN] source: TLS is not enforced… line appears and the source check fails (TLS required — refusing to connect to a remote (non-loopback) host without TLS): fix it with tls: { mode: verify-full }, or explicitly opt into remote plaintext with tls: { mode: disable } on an already-trusted network path — see reference/config.md § TLS.
rivet init
Generate a YAML config scaffold (or a machine-readable discovery artifact) by connecting to PostgreSQL, MySQL, SQL Server, or MongoDB and introspecting tables/collections (read-only). Does not run an export. YAML scaffolds include meta_columns (exported_at / row_hash on by default); scaffolds with heuristic mode: chunked also include chunk_checkpoint: true — see init.md.
rivet init (--source <URL> | --source-env <ENV_VAR> | --source-file <PATH>)
[--table <NAME>] [--schema <NAME>] [-o <PATH>] [--discover]
Exactly one of --source, --source-env, --source-file must be provided (enforced by the argument group).
| Flag | Short | Type | Description |
|---|---|---|---|
--source | string | Connection URL: postgresql:// | mysql:// | sqlserver:// | mongodb://. Visible in shell history / ps — avoid in production | |
--source-env | env var name | Name of an env var that holds the URL (e.g. DATABASE_URL). URL never hits the command line. Recommended. | |
--source-file | path | Path to a file containing just the URL on one line. Credentials stay on disk | |
--table | string | Single table; optionally schema-qualified (public.orders on PostgreSQL, dbo.orders on SQL Server). Omit to scaffold all tables/views in a Postgres/SQL Server schema or MySQL database | |
--schema | string | PostgreSQL: schema to list (default public). MySQL: database name when the URL omits one; a --schema naming a different database than the URL’s is refused — put the database in the URL instead | |
--output | -o | string | Write output to file (default: print to stdout) |
--discover | bool | Emit a machine-readable JSON discovery artifact instead of YAML — includes ranked cursor/chunk candidates, row estimates, on-disk sizes, and coalesce-fallback hints |
Examples
# One table → one export block
rivet init --source-env DATABASE_URL --table orders -o rivet.yaml
# PostgreSQL: entire schema (default public)
rivet init --source-env DATABASE_URL --schema public -o all_public.yaml
# MySQL: entire database from URL path
rivet init --source-file /run/secrets/mysql_url -o all_mydb.yaml
# JSON discovery artifact — ranked cursor/chunk candidates per table
rivet init --source-env DATABASE_URL --schema public --discover -o discovery.json
Narrative guide, heuristics, and Docker Compose examples: init.md.
rivet metrics
Show export run history (duration, row count, file size, status).
rivet metrics --config <PATH> [OPTIONS]
| Flag | Short | Type | Default | Description |
|---|---|---|---|---|
--config | -c | string | — | Config file (required) |
--export | -e | string | all | Filter by export name |
--last | -l | integer | 20 | Number of recent runs to show |
Example
rivet metrics -c my_export.yaml --last 10
rivet metrics -c my_export.yaml -e orders_daily
rivet journal
Inspect the structured run journal for an export — per-run event log with status, file/row/byte summary, retries, quality issues, schema changes, and the first error line.
rivet journal --config <PATH> --export <NAME> [OPTIONS]
| Flag | Short | Type | Default | Description |
|---|---|---|---|---|
--config | -c | string | — | Path to YAML config file (required) |
--export | -e | string | — | Export name to inspect (required) |
--last | -l | integer | 5 | Number of recent runs to show |
--run-id | string | — | Show a single specific run by ID |
Examples
# Last 5 runs for the orders export
rivet journal -c my_export.yaml -e orders
# Last 10 runs
rivet journal -c my_export.yaml -e orders --last 10
# Single run by ID
rivet journal -c my_export.yaml -e orders --run-id orders_20260513T120000.123
Output
Each run is shown as a block:
✓ orders success 12.3s
run_id: orders_20260513T120000.123
files: 3 rows: 150000 size: 4.2 MB
✓ = succeeded · ✗ = failed · • = partial / unknown.
Retries, quality issues, schema changes, and first-line error text are appended when present.
Journal entries are persisted to .rivet_state.db (SQLite, migration v7) at the end of every run. An empty result means the export has not run yet in this state DB, or --run-id does not match any stored run.
rivet state
Manage export state (cursors, file manifests, chunk checkpoints).
rivet state show
Show current cursor state for all incremental exports.
rivet state show --config <PATH>
rivet state reset
Reset the cursor for a specific export (next run will re-export all rows).
rivet state reset --config <PATH> --export <NAME>
rivet state files
List files produced by exports.
rivet state files --config <PATH> [--export <NAME>] [--last <N>]
| Flag | Short | Default | Description |
|---|---|---|---|
--export | -e | all | Filter by export name |
--last | -l | 50 | Number of recent files |
rivet state chunks
Show chunk checkpoint status for a chunked export.
rivet state chunks --config <PATH> --export <NAME>
rivet state reset-chunks
Clear persisted chunk checkpoint rows (chunk_run / chunk_task) so the next chunked run starts a fresh plan.
One export — same as targeting a single table name:
rivet state reset-chunks --config <PATH> --export <NAME>
Every “stuck” export in this config — resets checkpoints only when chunk_run.status is still 'in_progress' (process killed mid-run, concurrent worker left state behind, etc.). Exports whose chunk run already finished normally (completed) are skipped. Names that appear in state but were removed from the YAML are skipped with a printed note.
rivet state reset-chunks --config <PATH> --stuck-checkpoints
Alias (same semantics — checkpoint stuck, not “last metric row failed”):
rivet state reset-chunks --config <PATH> --failed
Then run rivet run --config <PATH> --resume (or a normal run without --resume) as needed.
rivet state progression
Show explicit committed and verified export boundaries (Epic G / ADR-0008).
rivet state progression --config <PATH> [--export <NAME>]
| Column | Meaning |
|---|---|
COMM MODE / COMMITTED | Strategy (incremental / chunked) and boundary value (cursor string or chunk #N) durably committed to the destination |
COMMITTED AT | UTC timestamp of the committing run |
VERI MODE / VERIFIED | Same shape, but only advanced by a full-match rivet reconcile (zero mismatches, zero unknowns) |
The progression table is advisory: it does not gate rivet run, rivet apply, or rivet reconcile. Consumers are operators and external monitoring.
rivet completions
Generate shell completion scripts.
rivet completions <SHELL>
| Shell | Command |
|---|---|
| Bash | rivet completions bash > ~/.local/share/bash-completion/completions/rivet |
| Zsh | rivet completions zsh > ~/.zfunc/_rivet |
| Fish | rivet completions fish > ~/.config/fish/completions/rivet.fish |
| PowerShell | rivet completions powershell > _rivet.ps1 |
| Elvish | rivet completions elvish > ~/.config/elvish/lib/rivet.elv |
rivet schema
Emit machine-readable schemas for Rivet’s data contracts.
rivet schema config
Today rivet schema config prints the JSON Schema for the rivet.yaml config to stdout. The schema is generated from the running binary’s Rust types, so it always matches the config grammar this version accepts. Pipe it to a file and reference it via a # yaml-language-server: $schema=… header so VS Code / Neovim’s YAML language server highlights invalid keys, suggests enum values, and surfaces required fields as you edit:
rivet schema config > rivet.schema.json
# then, at the top of rivet.yaml:
# yaml-language-server: $schema=./rivet.schema.json
State backend
By default Rivet keeps all run state (cursors, metrics, manifests, chunk checkpoints, schema drift, run journal, progression) in a SQLite file — .rivet_state.db — placed next to the config file. This works for local and single-node deployments.
For stateless containers / Kubernetes where the rivet pod is ephemeral or replicated, set RIVET_STATE_URL to a PostgreSQL connection string:
export RIVET_STATE_URL=postgresql://rivet:rivet@localhost:5433/rivet_state
rivet run --config rivet.yaml
Rivet creates all state tables automatically on first connect, running the full migration ladder up to the current schema version (the same schema-version sequence as SQLite). No manual DDL required.
Docker Compose (local dev)
docker-compose.yaml includes a dedicated postgres-state service on port 5433 (separate from the source postgres service on port 5432 so data and state never mix):
docker compose up -d postgres-state
export RIVET_STATE_URL=postgresql://rivet:rivet@localhost:5433/rivet_state
rivet run --config pilot.yaml
Security
- Passwords are redacted from all log and error messages:
postgresql://user:***@host/db. - A
WARNis emitted when connecting to a non-localhost host without TLS. For production use asslmode=requireURL:
export RIVET_STATE_URL="postgresql://rivet:secret@db.internal/rivet_state?sslmode=require"
- The
RIVET_STATE_URLvalue is not embedded in plan artifacts or config files. It is resolved from the environment at runtime.
Environment variables
| Variable | Description |
|---|---|
RUST_LOG | Log level: error, warn, info, debug, trace |
DATABASE_URL | Commonly used with url_env: DATABASE_URL in source config |
RIVET_STATE_URL | PostgreSQL URL for the state backend. When set (and starts with postgres), activates the PG backend instead of the default SQLite file. Example: postgresql://rivet:rivet@localhost:5433/rivet_state |
Example: verbose logging
RUST_LOG=debug rivet run -c my_export.yaml
Example: PostgreSQL state backend
export RIVET_STATE_URL=postgresql://rivet:rivet@localhost:5433/rivet_state
RUST_LOG=info rivet run -c my_export.yaml
Exit codes
| Code | Meaning |
|---|---|
| 0 | All exports succeeded |
| 1 | Usage / config error — config parsing/validation, a bad command, or an export error no other class claims. Fix the input; retrying won’t help |
| 2 | Retryable transient failure (connection loss, timeout, throttling) — safe to retry. Clap argument-parse errors also exit 2 (distinguishable by the usage text and absence of an Error: line) |
| 3 | Data-integrity failure (quality gate / reconcile / validate / duplicate-guard) — stop and investigate |
| 4 | Schema drift (on_schema_drift: fail tripped) |
| 5 | Protective refusal — rivet stopped on purpose so as not to lose, duplicate or overwrite data (a foreign checkpoint, a newer state DB, a cursor-owner mismatch, …). Retrying unchanged refuses again; a human decides |
| 6 | Internal — an invariant rivet relies on did not hold; a bug, please report it |
Every coded error and the exit its kind maps to: errors.md.
Command-Line Help for rivet
This document contains the help content for the rivet command-line program.
Command Overview:
rivet↴rivet run↴rivet check↴rivet doctor↴rivet cdc↴rivet load↴rivet compact↴rivet state↴rivet state show↴rivet state reset↴rivet state files↴rivet state reset-chunks↴rivet state chunks↴rivet state progression↴rivet state runs↴rivet state finish-run↴rivet state loads↴rivet completions↴rivet init↴rivet plan↴rivet apply↴rivet repair↴rivet validate↴rivet reconcile↴rivet metrics↴rivet schema↴rivet schema config↴rivet schema cli↴rivet schema errors↴rivet journal↴
rivet
Export data from databases to files
Usage: rivet [OPTIONS] <COMMAND>
Getting started (the happy path):
- rivet init scaffold a config from your database
- rivet doctor test source + destination auth
- rivet check column-type & schema report
- rivet run export your data
Docs: https://github.com/panchenkoai/rivet/blob/main/docs/getting-started.md
Subcommands:
run— Run export jobs defined in configcheck— Column-type & schema report for each export (needs a working connection; rundoctorfirst if it can’t connect)doctor— Verify source + destination auth/connectivity (run this first)cdc— Stream change data capture (CDC) from a source’s transaction logload— Load an export’s Parquet into a warehouse (BigQuery / Snowflake)compact— Merge each base-and-buffer CDC table’s<table>__changesbuffer into its base table (MERGEby primary key: updates, inserts, deletes flagged as__is_deleted) and drop the buffer — the billed step of the cyclerun → load → compact, labelledrivet_op:mergeper tablestate— Manage export statecompletions— Generate shell completionsinit— Generate a config scaffold from a live database (connect + introspect)plan— Generate an execution plan artifact (no data exported)apply— Execute a sealed plan artifact, or run a config’s exports wave-by-waverepair— Targeted repair of chunks flagged by reconcile: emit a repair plan, or re-export only mismatched rangesvalidate— Re-run manifest-aware verification against an existing destination, no extractionreconcile— Partition/window reconciliation: re-count per-partition on source and report mismatches. Requires a chunked export previously run withchunk_checkpoint: true. Exits non-zero when a mismatch is detected, so CI / orchestrators can gate on it (anunknownpartition warns but does not fail)metrics— Show export metrics historyschema— Emit machine-readable schemas for Rivet’s data contractsjournal— Inspect structured run journal (events, files, retries, quality issues)
Options:
--json-errors— Output errors as {“error”:“…”} JSON to stderr; useful for machine-readable orchestration
rivet run
Run export jobs defined in config
Usage: rivet run [OPTIONS] --config <CONFIG>
Options:
-
-c,--config <CONFIG>— Path to YAML config file -
-e,--export <EXPORT>— Run only a specific export by name -
--validate— Validate output files after writing -
--reconcile— Row-count audit: run COUNT(*) on the source and compare with the exported row count; a mismatch fails the run. Implies--validate(also verifies the output file manifest) -
--resume— Resume a chunked export withchunk_checkpoint: true(same query/chunk_column/chunk_size) -
--force— Override safety gates that would otherwise refuse the run.Today: with
--resume, allows starting against a destination prefix whose_SUCCESSmarker is already present. Without--force, resume against an already-complete run refuses, so an operator cannot accidentally re-export over a verified dataset. -
--parallel-exports— Run the config’s exports concurrently, at most 16 at once (needs 2+ exports); a CDC export run alone also takes its pending baseline snapshots at most 16 at once -
--parallel-export-processes— Run each export as a separaterivetchild process (parallel; true per-export peak RSS; more overhead than threads) -
--summary-output <PATH>— Write the run aggregate summary as JSON to this file (in addition to .rivet_state.db) -
--json— Print the run aggregate summary as JSON to stdout at the end of the run -
-p,--param <KEY=VALUE>— Query parameter: key=value (repeatable, substitutes ${key} in queries)
rivet check
Column-type & schema report for each export (needs a working connection; run doctor first if it can’t connect)
Usage: rivet check [OPTIONS] --config <CONFIG>
Options:
-c,--config <CONFIG>— Path to YAML config file-e,--export <EXPORT>— Check only a specific export by name-p,--param <KEY=VALUE>— Query parameter: key=value (repeatable, substitutes ${key} in queries)--type-report— Show per-column type fidelity report (source type → Rivet type → Arrow type)--strict— Fail with non-zero exit code if any column has an unsafe type mapping--json— Output type report as JSON (implies –type-report)--target <TARGET>— Check compatibility against a target warehouse (e.g. bigquery)
rivet doctor
Verify source + destination auth/connectivity (run this first)
Usage: rivet doctor [OPTIONS] --config <CONFIG>
Options:
-c,--config <CONFIG>— Path to YAML config file--json— Emit the probe results as a JSON object ({config_path, all_ok, checks: [{name, ok, detail?, hint?}]}) instead of the text report
rivet cdc
Stream change data capture (CDC) from a source’s transaction log.
The engine is chosen from the URL scheme: mysql:// (binlog), postgresql:// (logical slot), sqlserver:// (change tables), or mongodb:// (change stream). Emits one JSON object per row change to stdout (NDJSON) and, with --checkpoint, persists a resume position; --output writes typed Parquet/CSV instead. Per-engine prerequisites (ROW binlog + REPLICATION grant, wal_level=logical, enabled CDC, a replica set) are in docs/reference/cdc.md. The fuller, config-driven path is rivet run with mode: cdc.
Usage: rivet cdc [OPTIONS] <--source <SOURCE>|--source-env <ENV_VAR>|--source-file <PATH>>
Options:
-
--source <SOURCE>— Database URL —postgresql://,mysql://,sqlserver://, ormongodb://(engine chosen from the scheme). Visible inps; prefer--source-env/--source-fileoutside local dev -
--source-env <ENV_VAR>— Name of an environment variable holding the database URL -
--source-file <PATH>— Path to a file containing just the database URL (one line) -
--server-id <SERVER_ID>— Replica server-id for the binlog connection (must be distinct from the source’s and any other replica)Default value:
4271 -
--checkpoint <PATH>— Persist/resume the engine’s log position to this file (MySQL binlog coordinates / PostgreSQL slot-resume marker / SQL Server from-LSN / MongoDB resume token). If omitted, each engine falls back to its own anchor: MySQL and MongoDB start at the source’s CURRENT position (nothing written before now is captured), PostgreSQL resumes from the slot itself (server-side — a slot created here pins at the current WAL position), and SQL Server starts at the capture instance’sfn_cdc_get_min_lsn(it over-reads the retained backlog rather than skipping) -
--table <TABLE>— Only emit changes for this table (repeatable; default: all tables) -
--max-events <N>— Stop at the first COMMIT BOUNDARY once N change events have been emitted — a soft cap, so the run may overshoot N by the remainder of the transaction the cap lands in. A hard per-event stop cannot checkpoint inside a transaction, so a transaction longer than N left the run re-reading the same position on every restart. Without it the default bounded run drains to the log end as of open and exits; streaming until interrupted needs--stream -
--output <DIR>— Write typed Parquet/CSV files to this directory (the upsert/after-image shape) instead of NDJSON to stdout. Requires exactly one--table— its schema is resolved from the source -
--format <FORMAT>— Output file format when--outputis set:parquet(default) orcsvDefault value:
parquet -
--rollover <N>— Rows per output file (rollover) when--outputis set. Larger ⇒ fewer, bigger files but more drain memory (the PostgreSQL peek reads a part’s worth per batch: memory is O(rollover)). Turn it up/down per workloadDefault value:
100000 -
--slot <NAME>— PostgreSQL logical slot name (CDC; created if absent)Default value:
rivet_slot -
--capture-instance <INSTANCE>— SQL Server CDC capture instance, e.g.dbo_orders— required forsqlserver://sources -
--stream— Stream continuously instead of the DEFAULT bounded “read to the log end and exit” drain. What “continuously” means is per engine: MySQL (a blocking binlog dump) and MongoDB (a change stream that blocks awaiting events) stay up until stopped; PostgreSQL and SQL Server are poll adapters that STILL EXIT ON CATCH-UP — there this is one unbounded pass, not a daemon, so run it under a supervisor that restarts it. Omit it for the scheduler-friendly bounded run (the default). For MySQL the bounded run is a non-blocking binlog dump; PostgreSQL / SQL Server drain their backlog and exit
rivet load
Load an export’s Parquet into a warehouse (BigQuery / Snowflake)
The native column schema, target table, partition, and source URIs are all derived from the config’s top-level load: block — nothing is hand-typed. A multi-table config loads its exports into the shared target on a POOL of up to 16 worker threads, capped at the number of tables; --pool 1 is the strictly sequential pass. Column types come from the state DB, recorded by each export’s last successful rivet run; the load never connects to the source.
Usage: rivet load [OPTIONS] --config <CONFIG>
Options:
-c,--config <CONFIG>— Path to YAML config file — extraction PLUS a top-levelload:block. ONE file drives both the export and the load: the mode (full/incremental/cdc),pk:,cleanup_source:,gc_orphans:andallow_source_drift:all live in the config, not on the CLI--run-id <RUN_ID>— Correlation id stamped on every warehouse job/query of this load run (BigQueryrivet_runlabel / SnowflakeQUERY_TAG), so cost slices per run as well as per table. Defaults to a generated id--rebuild-changelog— Rebuild a<table>__changeswhose partitioning differs from the config’sload.partition— a billed query copying every row — and swap it in. Without this flag such a load is refused naming the difference; a rebuild is never a side effect of a scheduled load--pool <N>— Load the config’s tables on N worker threads instead of one after another: every freeing worker takes the next table, so a slow table no longer blocks the ones queued behind it. A failing table still isolates to itself and the rest keep loading, and the per-table lease is unchanged —rivet loadandrivet compactstill refuse a table the other holds. Each worker opens its own ledger connection, so N is also N connections to the state backend; a worker that cannot reopen the ledger takes no table, and the other workers load the queue. Defaults to 16 — the ceiling — capped at the number of tables. Pass--pool 1for the strictly sequential pass
rivet compact
Merge each base-and-buffer CDC table’s <table>__changes buffer into its base table (MERGE by primary key: updates, inserts, deletes flagged as __is_deleted) and drop the buffer — the billed step of the cycle run → load → compact, labelled rivet_op:merge per table
Usage: rivet compact [OPTIONS] --config <CONFIG>
Options:
-c,--config <CONFIG>— Path to YAML config file — the same onerivet loadreads--run-id <RUN_ID>— Correlation id stamped on every warehouse job of this compaction (BigQueryrivet_runlabel). Defaults to a generated id--pool <N>— Merge the config’s tables on N worker threads instead of one after another: every freeing worker takes the next table. A failing table still isolates to itself, and the per-table lease is unchanged — a tablerivet loadholds is still refused. Each worker opens its own ledger connection, so N is also N connections to the state backend; a worker that cannot reopen the ledger takes no table, and the other workers compact the queue. Defaults to 16 — the ceiling — capped at the number of tables. Pass--pool 1for the sequential pass
rivet state
Manage export state
Usage: rivet state <COMMAND>
Subcommands:
show— Show current state for all exportsreset— Reset state for an exportfiles— Show file manifest (files produced by exports)reset-chunks— Clear persisted chunk checkpoint rows (chunk_run/chunk_task)chunks— Show chunk checkpoint status for an exportprogression— Show committed / verified export boundaries (the last fully-exported cursor position)runs— Show the run-status ledger (extraction-run lifecycle rows gc/cleanup read)finish-run— Terminal-stamp a run-status row you KNOW is dead (hard crash, no successful successor) — the escape hatch for a prefix frozen by a stalerunningrowloads— Show the load ledger (rivet loadruns recorded in the state DB)
rivet state show
Show current state for all exports
Usage: rivet state show [OPTIONS] --config <CONFIG>
Options:
-c,--config <CONFIG>--json— Emit the incremental-cursor state as a JSON array to stdout instead of the text table. Empty →[]
rivet state reset
Reset state for an export
Usage: rivet state reset --config <CONFIG> --export <EXPORT>
Options:
-c,--config <CONFIG>-e,--export <EXPORT>— Export name to reset
rivet state files
Show file manifest (files produced by exports)
Usage: rivet state files [OPTIONS] --config <CONFIG>
Options:
-
-c,--config <CONFIG> -
-e,--export <EXPORT>— Show files for a specific export -
-l,--last <LAST>— Number of recent files to showDefault value:
50 -
--json— Emit the file list as a JSON array to stdout (CI completeness checks) instead of the text table. Empty →[]
rivet state reset-chunks
Clear persisted chunk checkpoint rows (chunk_run / chunk_task)
Usage: rivet state reset-chunks --config <CONFIG> <--export <EXPORT>|--stuck-checkpoints>
Options:
-
-c,--config <CONFIG> -
-e,--export <EXPORT>— Export whose chunk checkpoints should be cleared (same aschunk_checkpointruns) -
--stuck-checkpoints[alias:failed] — Reset checkpoints for every export named in this config that currently haschunk_run.status = 'in_progress'(crash, SIGKILL, stale concurrent worker).Ignores exports whose latest chunk run already finished (
completed). Runs listed in the database but removed from the YAML are skipped with a printed note.Alias
--failedrefers to “checkpoint state stuck”, not HTTP-style failures or metric rows.
rivet state chunks
Show chunk checkpoint status for an export
Usage: rivet state chunks [OPTIONS] --config <CONFIG> --export <EXPORT>
Options:
-c,--config <CONFIG>-e,--export <EXPORT>--json— Emit the checkpoint (run header + per-chunk tasks) as a JSON object to stdout instead of the text table. No checkpoint →null
rivet state progression
Show committed / verified export boundaries (the last fully-exported cursor position)
Usage: rivet state progression [OPTIONS] --config <CONFIG>
Options:
-c,--config <CONFIG>-e,--export <EXPORT>— Show progression for a specific export
rivet state runs
Show the run-status ledger (extraction-run lifecycle rows gc/cleanup read)
Usage: rivet state runs [OPTIONS] --config <CONFIG>
Options:
-
-c,--config <CONFIG> -
--running— Show onlyrunningrows — the ones that can freeze a prefix -
-l,--last <LAST>— Number of recent rows to showDefault value:
50 -
--json— Emit the rows as a JSON array to stdout instead of the text table. Empty →[]
rivet state finish-run
Terminal-stamp a run-status row you KNOW is dead (hard crash, no successful successor) — the escape hatch for a prefix frozen by a stale running row
Usage: rivet state finish-run --config <CONFIG> --run-id <RUN_ID>
Options:
-c,--config <CONFIG>--run-id <RUN_ID>— The run id to close (find it withrivet state runs -c <config> --running)
rivet state loads
Show the load ledger (rivet load runs recorded in the state DB)
Usage: rivet state loads [OPTIONS] --config <CONFIG>
Options:
-
-c,--config <CONFIG> -
-t,--target <TARGET>— Show only loads into this fully-qualified target (proj.ds.table) -
-l,--last <LAST>— Number of recent loads to showDefault value:
50
rivet completions
Generate shell completions
Usage: rivet completions <SHELL>
Arguments:
-
<SHELL>— Shell to generate completions forPossible values:
bash,elvish,fish,powershell,zsh
rivet init
Generate a config scaffold from a live database (connect + introspect)
Usage: rivet init [OPTIONS] <--source <SOURCE>|--source-env <ENV_VAR>|--source-file <PATH>>
Options:
-
--source <SOURCE>— Database URL (postgresql://, mysql://, sqlserver://, mongodb://, or oracle://). Visible in shell history /ps; prefer--source-envor--source-filefor anything other than local dev -
--source-env <ENV_VAR>— Name of an environment variable holding the database URL (e.g. DATABASE_URL). The URL never touches the command line -
--source-file <PATH>— Path to a file containing just the database URL (one line). Credentials stay on disk instead of entering the process command line -
--table <TABLE>— Single table, optionally schema-qualified (e.g. public.orders, dbo.orders). Omit to emit all tables/views in a Postgres/SQL Server schema or MySQL database -
--schema <SCHEMA>— PostgreSQL: schema to export (default public). SQL Server: schema (default dbo). MySQL: database name when the URL omits it (a –schema naming a DIFFERENT database than the URL is refused — put the database in the URL) -
--include <GLOB>— Whole-schema only: keep only tables/views matching these globs (*/?) — several after one flag (--include orders users) or the flag repeated; a table is kept if it matches any. No--include= keep all -
--exclude <GLOB>— Whole-schema only: drop tables/views matching these globs (*/?) — several after one flag or the flag repeated;--excludewins over--include -
-o,--output <OUTPUT>— Write output to this file instead of stdout -
--discover— Emit a machine-readable JSON discovery artifact instead of a YAML scaffold. Includes row estimates, size bytes, ranked cursor candidates, chunk candidates, and advisory notes. Mutually exclusive with the YAML-only--gcs-bucket/--s3-bucketflags -
--mode <MODE>— Override the suggested extraction mode for every scaffolded export.cdcscaffolds a change-data-capture export (mode: cdc + a cdc: block with engine-specific stream params) instead of a batch query; on MySQL, and on PostgreSQL when every table is inpublic, over two or more tables it writes one batch recipe per table plus onetables:stream withbackfill: auto(one export per table otherwise). Other values (full / incremental / chunked / time_window) just override the auto-suggested mode -
--gcs-bucket <NAME>— Scaffolddestination: type: gcswith this bucket (each export getsprefix: exports/<table>/). Incompatible with--s3-bucketand--discover -
--gcs-credentials-file <PATH>— Optional path forcredentials_file:on GCS scaffolds. Omit entirely to use ADC (gcloud auth application-default login) orGOOGLE_APPLICATION_CREDENTIALS— no key in YAML -
--s3-bucket <NAME>— Scaffolddestination: type: s3with this bucket (each export getsprefix: exports/<table>/). Incompatible with--gcs-bucketand--discover -
--s3-region <REGION>— Optional AWS region for S3 scaffolds (when using--s3-bucket) -
--bigquery-project <PROJECT>— Scaffold aload:block for this BigQuery project. With--bigquery-datasetthe generated config carries the warehouse target, a per-table partition guess and the base+buffer layout, sorivet loadandrivet compactwork from it after a review. Needs--gcs-bucket: the load reads GCS only, so a local or S3 scaffold with aload:block is a configrivet loadrefuses -
--bigquery-dataset <DATASET>— The dataset the load creates its tables in (with--bigquery-project) -
--clickhouse-url <URL>— Scaffold aload:block for this ClickHouse HTTP endpoint, e.g.http://localhost:8123. Needs--clickhouse-databaseand a bucket the export stages in (--gcs-bucketor--s3-bucket) -
--clickhouse-database <DATABASE>— The ClickHouse database the load creates its tables in (with--clickhouse-url) -
--clickhouse-user <USER>— The ClickHouse user the load authenticates as (with--clickhouse-url)Default value:
default -
--tls <MODE>— TLS posture for BOTH the introspection connection init opens AND thesource.tls:block written into the scaffold. Required (ordisable, explicitly) for any non-loopback host — without it the TLS gate refuses before connecting, and at init time there is no config file to add atls:block to yetPossible values:
disable: Plaintext. Use only inside trusted networks (loopback, cgroup-private)require: Require a TLS handshake; accept the server certificate without verifying issuer or hostname. Protects against passive sniffing, not MITMverify-ca: TLS + verify certificate chains to the configured / system trust store. Does not check hostname (useful for IP-addressed or internal names)verify-full: TLS + verify chain and hostname against the server cert’s SAN/CN. Recommended default for production
-
--tls-ca <PATH>— PEM CA certificate for--tls verify-ca/verify-fullagainst a private CA; written into the scaffold asca_file:. Refused withdisable/require, where it would be silently meaningless
rivet plan
Generate an execution plan artifact (no data exported)
Usage: rivet plan [OPTIONS] --config <CONFIG>
Options:
-
-c,--config <CONFIG>— Path to YAML config file -
-e,--export <EXPORT>— Plan only a specific export by name -
-p,--param <KEY=VALUE>— Query parameter: key=value (repeatable) -
-o,--output <OUTPUT>— Write plan JSON to this file (default: print summary to stdout) -
--annotate-waves— Write this plan’swave:/parallel_safe:schedule into the config, (over)writing every export. WITHOUT this flagrivet planis READ-ONLY: it prints the schedule and the reviewable plan but never touches the config file — not even to fill in absent fields. This makes config mutation an explicit, opt-in act (a read-only-lookingrivet planonce turned a hand-tuned 5-per-wave split into one 76-export wave) -
--format <FORMAT>— Output format: “pretty” (human summary) or “json” (machine-readable)Default value:
prettyPossible values:
pretty: Human-readable summary printed to stdoutjson: Pretty-printed JSON (written to –output file or stdout)
rivet apply
Execute a sealed plan artifact, or run a config’s exports wave-by-wave
Usage: rivet apply [OPTIONS] <PLAN_FILE>
Arguments:
<PLAN_FILE>— A plan JSON artifact fromrivet plan(sealed single-export replay), OR a YAML config (.yaml/.yml) to run its exports wave-by-wave in ascendingwave:order — the wave each export was assigned byrivet plan
Options:
--parallel-export-processes— Run the cheap (low-cost) exports within each wave concurrently, as separate processes (same asparallel_export_processes: truein the config). Config-wave mode only; heavier exports — which already chunk-parallelize internally — still run one at a time--resume— Config-wave mode: skip exports a prior run already completed (_SUCCESSpresent) and resume incomplete chunked exports from their checkpoints, so a re-run after a partial failure does not redo finished tables. Independent tables are never re-exported--force— Override whichever safety gate refuses the run: in JSON-artifact mode the plan staleness check (> 24 h) and the incremental cursor-drift check (each bypass is recorded in the run’sapply_context); in YAML config mode, with--resume, the refusal to resume into a prefix whose_SUCCESSmarker is already present--pool <N>— Run the whole config as ONE bounded work-stealing pool of N export slots (config mode only, #166): exports start longest-first (LPT, by each export’s last measured duration) and every freeing slot pulls the next — no wave barriers, so the wall approachesmax(longest, total/N). Prioritywave:tiers are NOT honored (makespan mode); exports that are notparallel_safenever run concurrently with EACH OTHER (one heavy at a time; cheap exports backfill the remaining slots)--split— With--pool: when ONE export dominates the pool floor (its predicted duration ≫ the next-longest, #167), split it into N range sub-exports over its key span — separate scheduler units the pool places concurrently, so the giant stops being the makespan floor. The units share one destination prefix and fold to one family, so the load view reads them as a single logical table. Only full/chunked/keyset exports with achunk_by_key:/chunk_column:are split (never incremental/CDC). Off by default; ignored without--pool
rivet repair
Targeted repair of chunks flagged by reconcile: emit a repair plan, or re-export only mismatched ranges
Usage: rivet repair [OPTIONS] --config <CONFIG> --export <EXPORT>
Options:
-
-c,--config <CONFIG>— Path to YAML config file -
-e,--export <EXPORT>— Export name to repair (must bemode: chunked) -
--report <REPORT>— Path to a reconcile JSON report produced byrivet reconcile --format json. Omit to run reconcile in-process against the latest chunk run -
--execute— Actually re-export the affected chunks. Without this flag, the plan is printed and nothing is executed -
--format <FORMAT>— Output format for plan / reportDefault value:
prettyPossible values:
pretty,json -
-o,--output <OUTPUT>— Write plan / report JSON to this file (with--format json) -
-p,--param <KEY=VALUE>— Query parameter: key=value (repeatable)
rivet validate
Re-run manifest-aware verification against an existing destination, no extraction.
The same file-manifest checks rivet run --validate performs at end-of-run, exposed as a standalone command for between-run polling and triage. Reads manifest.json + _SUCCESS at the destination, head-checks every committed part for presence and recorded size_bytes. Source is not queried — use rivet reconcile for a source-vs-export row audit.
By default validate resolves the destination prefix the same way run does — {date} becomes today’s UTC date. Use --date, --run-id, or --prefix to point at a prior run instead of today.
Usage: rivet validate [OPTIONS] --config <CONFIG>
Options:
-
-c,--config <CONFIG>— Path to YAML config file -
-e,--export <EXPORT>— Validate only this export (default: every export in the config) -
--format <FORMAT>— Output format: “pretty” (human summary) or “json” (machine-readable)Default value:
prettyPossible values:
pretty,json -
--depth <DEPTH>— How deep to verify: “light” (manifest + _SUCCESS only, no prefix listing), “sample” (light + part reconcile + untracked surplus), or “full” (sample + the value-checksum re-read of every part; CSV parts carry no value checksum, so for CSV only each part’s row count is re-counted).fullis the default and matches the pre-graded behaviour. Uselightfor a fast “is this a complete, marked run?” poll, orsamplefor full structural verification without downloading parts.Default value:
fullPossible values:
light: Manifest read + self-consistency +_SUCCESSonly (no prefix listing)sample: Light + part reconcile + untracked surplus (onelist_prefix)full: Sample + the Form B value-checksum re-read (downloads parts; CSV: row counts only)
-
-o,--output <OUTPUT>— Write JSON report to this file (only with--format json) -
--date <YYYY-MM-DD>— Resolve{date}to this ISO-8601 day (e.g.2026-05-21) instead of today.Use when a run that landed on a prior day’s prefix needs to be re-verified — without this flag
validatelooks at today’s resolved prefix and reports “no manifest” for yesterday’s data. -
--run-id <RUN_ID>— Substitute{run_id}in the destination template with this value.Composes with
--date. Has no effect if the template does not contain{run_id}. -
--prefix <PREFIX>— Skip placeholder resolution entirely and verify exactly this prefix.Use when the resolved template no longer matches the physical layout (e.g. data was relocated, or the template changed since the run landed). The destination type still comes from config (
local,s3,gcs,azure); only the resolvedpath/prefixstring is overridden.
rivet reconcile
Partition/window reconciliation: re-count per-partition on source and report mismatches. Requires a chunked export previously run with chunk_checkpoint: true. Exits non-zero when a mismatch is detected, so CI / orchestrators can gate on it (an unknown partition warns but does not fail)
Usage: rivet reconcile [OPTIONS] --config <CONFIG> --export <EXPORT>
Options:
-
-c,--config <CONFIG>— Path to YAML config file -
-e,--export <EXPORT>— Export name to reconcile (must bemode: chunked) -
--format <FORMAT>— Output format: “pretty” (human summary) or “json” (machine-readable report)Default value:
prettyPossible values:
pretty,json -
-o,--output <OUTPUT>— Write report JSON to this file (only with--format json) -
-p,--param <KEY=VALUE>— Query parameter: key=value (repeatable)
rivet metrics
Show export metrics history
Usage: rivet metrics [OPTIONS] --config <CONFIG>
Options:
-
-c,--config <CONFIG>— Path to YAML config file -
-e,--export <EXPORT>— Show metrics for a specific export -
-l,--last <LAST>— Number of recent runs to showDefault value:
20 -
--json— Emit the metrics as a JSON array to stdout (for CI / dashboards) instead of the text table. Empty history prints[]
rivet schema
Emit machine-readable schemas for Rivet’s data contracts.
Today: rivet schema config prints the JSON Schema for the rivet.yaml config to stdout. Operators pipe this into a file and reference it via a # yaml-language-server: $schema=... header so VS Code / Neovim’s YAML language server highlights invalid keys, suggests enum values, and surfaces required fields as the YAML is edited. See docs/cloud-destinations.md for the broader contract.
Usage: rivet schema <COMMAND>
Subcommands:
config— Print the JSON Schema describingrivet.yamlto stdoutcli— Print a Markdown CLI reference (every command + flag) to stdout, generated from the clap definitions — the same source as--help, so it cannot drift from the actual commandserrors— Print the Markdown error-code reference (everyRIVET_*code, its kind, exit code and operator action) to stdout, generated from the code registry
rivet schema config
Print the JSON Schema describing rivet.yaml to stdout.
The schema is generated from the running binary’s Rust types, so it always matches the config grammar this version accepts. Pipe to a file and reference it via a # yaml-language-server: $schema=… header in your config:
rivet schema config > rivet.schema.json
Usage: rivet schema config
rivet schema cli
Print a Markdown CLI reference (every command + flag) to stdout, generated from the clap definitions — the same source as --help, so it cannot drift from the actual commands.
rivet schema cli > docs/reference/cli-reference.md
Usage: rivet schema cli
rivet schema errors
Print the Markdown error-code reference (every RIVET_* code, its kind, exit code and operator action) to stdout, generated from the code registry.
rivet schema errors > docs/reference/errors.md
Usage: rivet schema errors
rivet journal
Inspect structured run journal (events, files, retries, quality issues)
Usage: rivet journal [OPTIONS] --config <CONFIG> --export <EXPORT>
Options:
-
-c,--config <CONFIG>— Path to YAML config file -
-e,--export <EXPORT>— Export name to show journal for -
-l,--last <LAST>— Number of recent runs to show (newest first)Default value:
5 -
--run-id <RUN_ID>— Show journal for a specific run_id instead of recent runs
This document was generated automatically by
clap-markdown.
Error codes
Every failure rivet names carries a stable RIVET_<FAMILY>_<NAME> code: in --json-errors output as code, and as a [CODE] prefix on the text error line. The KIND decides the exit code.
| exit | meaning |
|---|---|
| 1 | usage — fix the config or the command; retrying fails the same way |
| 2 | a transient failure — retry the same command |
| 3 | integrity — the data may be wrong; stop and investigate |
| 4 | schema drift — the source shape changed; review before re-running |
| 5 | refusal — rivet stopped on purpose to protect data; a human decides |
| 6 | internal — an invariant did not hold; a bug, please report it |
| code | kind | exit | what to do |
|---|---|---|---|
RIVET_CONFIG_NO_EXPORTS | usage | 1 | declare at least one export under exports: |
RIVET_CONFIG_CHUNK_COUNT_INVALID | usage | 1 | set chunk_count to 1 or more |
RIVET_CONFIG_CHUNK_BY_DAYS_INVALID | usage | 1 | set chunk_by_days to 1 or more |
RIVET_CONFIG_DUPLICATE_EXPORT | usage | 1 | give every export a unique name |
RIVET_CONFIG_CDC_RESOURCE_CONFLICT | usage | 1 | give each CDC export its own slot / server_id / checkpoint path |
RIVET_CONFIG_CDC_ROLLOVER_INVALID | usage | 1 | set cdc.rollover to 1 or more, or omit it |
RIVET_CONFIG_CDC_CONTINUOUS_UNSUPPORTED | usage | 1 | omit cdc.until_current (or --stream) and run the bounded drain on a schedule |
RIVET_CONFIG_CSV_LOAD_UNSUPPORTED | usage | 1 | use format: parquet for an export with a load: section |
RIVET_CONFIG_SOURCE_MODE_UNSUPPORTED | usage | 1 | use a mode this source supports (MongoDB: full) |
RIVET_CONFIG_SOURCE_URL_SCHEME_MISMATCH | usage | 1 | make source.type and the URL scheme name the same engine |
RIVET_CONFIG_KEYSET_KEY_UUID_OVERRIDE | usage | 1 | key the keyset on another unique column, or use mode: full for this table |
RIVET_CONFIG_CURSOR_COLUMN_CASE | usage | 1 | spell cursor_column exactly as the result set names the column |
RIVET_CONFIG_COLUMN_OVERRIDE_CASE | usage | 1 | spell the columns: key exactly as the result set names the column |
RIVET_SOURCE_STATEMENT_TIMEOUT | environment | 2 if transient, else 1 | raise tuning.statement_timeout_s, or narrow the chunk |
RIVET_SOURCE_CURSOR_FINER_THAN_MICROSECOND | refusal | 5 | cursor on a column at microsecond precision or coarser, or cast the cursor to TIMESTAMP(6) in a curated query |
RIVET_SOURCE_CDC_FOREIGN_CHECKPOINT | refusal | 5 | delete the checkpoint so the next run anchors afresh FIRST, then re-snapshot the tables |
RIVET_SOURCE_CDC_CHECKPOINT_INVALID | refusal | 5 | restore the checkpoint file, or delete it so the stream anchors FIRST, then re-snapshot |
RIVET_SOURCE_CDC_LOG_GAP | refusal | 5 | restore the missing log, or delete the checkpoint so the stream anchors FIRST, then re-snapshot |
RIVET_SOURCE_CDC_TRUNCATED | refusal | 5 | delete the checkpoint so the stream anchors FIRST, then re-snapshot the table |
RIVET_SOURCE_CDC_UNDECODABLE | refusal | 5 | re-snapshot the table: delete the checkpoint first so the stream anchors, then snapshot |
RIVET_SOURCE_CDC_CELL_UNSUPPORTED | refusal | 5 | leave the column out of the capture (SQL Server: @captured_column_list), then re-snapshot |
RIVET_SOURCE_CDC_PREREQUISITE | environment | 2 if transient, else 1 | apply the setup statement the message names, then re-run (docs/reference/cdc.md) |
RIVET_SOURCE_VALUE_UNREPRESENTABLE | refusal | 5 | map the value to a representable one in the export’s query:, or exclude the column |
RIVET_SOURCE_OVERRIDE_WIRE_MISMATCH | usage | 1 | remove or correct the column’s columns: override, or CAST the column to that type in the export’s query: |
RIVET_STATE_SCHEMA_NEWER | refusal | 5 | upgrade rivet, or point this binary at a state DB it created |
RIVET_STATE_CURSOR_OWNER_MISMATCH | refusal | 5 | rivet state reset -c <config> --export <name> to start the new cursor with a full pass, or restore the previous cursor column |
RIVET_STATE_KEYSET_SEQUENTIAL_ANCHOR_UNFINISHED | refusal | 5 | re-run once with parallel: 1 to finish the interrupted run, then raise parallel: |
RIVET_LOAD_VALUE_OUT_OF_TARGET_RANGE | refusal | 5 | the warehouse type cannot hold this value; declare a wider type (e.g. String) for the column, or fix the source value |
RIVET_LOAD_COUNT_MISMATCH | integrity | 3 | compare the warehouse table with the run’s manifest before re-running; the source is kept |
RIVET_LOAD_ADOPTION_COLUMN_MISMATCH | refusal | 5 | add the export’s new columns to the table (ALTER TABLE … ADD COLUMN) and re-run; do not rename it aside |
RIVET_INTERNAL_VALUE_CONVERTER | internal | 6 | a value changed between the source and the written part — a bug; report it with the column’s type |
RIVET_INTERNAL_SPILL | internal | 6 | the CDC spill log is inconsistent — a bug or a damaged spill directory; report it and re-run |
RIVET_INTERNAL_TYPE_BUILDER | internal | 6 | a column builder got a type it cannot build — a bug; report it with the column’s type |
YAML Config Guide
📌 The exhaustive, always-current field reference is generated from the code: config-reference.md — rendered from
rivet schema config(the schemars-derived JSON Schema), so it cannot drift and needs no manual verification. This page is the guide: the same options with defaults, rationale, and worked examples. For the guaranteed-current field/type/enum list, trust the generated reference.
The most-used options, grouped by section, with the why and examples.
Root
| Field | Type | Required | Description |
|---|---|---|---|
source | object | yes | Database connection and global tuning |
exports | list | yes | One or more export definitions |
notifications | object | no | Slack / webhook notification settings |
source
| Field | Type | Required | Default | Description |
|---|---|---|---|---|
type | postgres | mysql | mssql | mongo | oracle | yes | — | Database type. mssql = SQL Server (URL scheme sqlserver://); mongo = MongoDB (URL scheme mongodb://, see mongodb.md); oracle = Oracle Database (URL scheme oracle://…/SERVICE, see oracle.md). |
url | string | one of url/url_env/url_file or structured | — | Full connection URL (postgresql:// / mysql:// / sqlserver:// / mongodb:// / oracle://) |
url_env | string | — | Env var name containing the URL | |
url_file | string | — | Path to file containing the URL | |
host | string | for structured | — | Database hostname |
port | integer | no | 5432 (PG) / 3306 (MySQL) / 1433 (MSSQL) / 27017 (MongoDB) / 1521 (Oracle) | Database port |
user | string | for structured | — | Database user |
password | string | no | — | Not recommended — plaintext; see Credentials & plan artifacts below |
password_env | string | no | — | Env var name containing the password (recommended) |
database | string | for structured | — | Database name |
tuning | object | no | — | Global tuning (see tuning.md) |
tls | object | no | — | Transport security (see TLS below). Omit → plaintext + WARN log. |
Connection approaches (mutually exclusive):
- URL-based: provide exactly one of
url,url_env, orurl_file - Structured: provide
host,user,database(+ optionalport,password/password_env)
TLS
| Field | Type | Default | Description |
|---|---|---|---|
mode | disable | require | verify-ca | verify-full | verify-full | Enforcement level (mirrors libpq sslmode semantics) |
ca_file | string | — | PEM-encoded CA certificate for private trust stores; required for verify-ca/verify-full against custom CAs |
accept_invalid_certs | boolean | false | Dangerous — disables certificate verification. Only honored when explicitly true. |
accept_invalid_hostnames | boolean | false | Dangerous — disables hostname (SAN/CN) verification. Only honored when explicitly true. |
Example (production):
source:
type: postgres
url_env: DATABASE_URL
tls:
mode: verify-full
ca_file: /etc/ssl/certs/rds-ca-2019-root.pem
Example (local dev only — no TLS):
source:
type: mysql
host: 127.0.0.1
port: 3306
user: dev
password_env: DEV_PWD
database: rivet
tls: { mode: disable } # explicit opt-out — silences the plaintext WARN
Example (SQL Server — sqlserver:// scheme, port 1433):
source:
type: mssql
url_env: MSSQL_URL # sqlserver://user:pass@host:1433/database
tls:
ca_file: /etc/ssl/certs/your-sql-server-ca.pem # private CA, or:
# accept_invalid_certs: true # self-signed dev cert
SQL Server always encrypts the login handshake, so TLS is on regardless; the
tls: block only controls how the server certificate is trusted. Supported
export modes and types are listed in compatibility.md.
When tls: is omitted entirely, Rivet connects without TLS and emits a WARN so you notice. See reference/compatibility.md for which servers ship TLS-ready and Rivet’s dev-environment defaults.
Credentials & plan artifacts
A PlanArtifact (produced by rivet plan) is designed to be committed / reviewed; it must not carry plaintext credentials. Rivet enforces ADR-0005 PA9 (SourceConfig::redact_for_artifact):
password:field → always stripped from the artifact (set toNone).url:containingscheme://user:pass@…→ userinfo rewritten toREDACTED.password_env/url_env/url_file→ preserved as references so apply-time can re-resolve against the apply-environment.
When redaction runs, rivet plan logs:
WARN plan 'orders': plaintext credentials stripped from artifact —
apply time must have equivalent env/file-based auth available
Recommendation: use password_env (or url_env) everywhere; only use plaintext password: for one-off local scripts. See ADR-0005 PA9.
exports[]
Each entry in the exports list defines one export job.
| Field | Type | Required | Default | Description |
|---|---|---|---|---|
name | string | yes | — | Unique identifier for this export |
query | string | one of query/query_file/table/tables | — | Inline SQL SELECT query |
query_file | string | — | Path to .sql file (relative to config dir) | |
table | string | — | Whole-table shortcut (name or schema.table) — enables PK auto-chunking; required for chunk_by_key / chunk_size_memory_mb | |
tables | list | — | CDC only (mode: cdc): capture several tables through one change stream (one slot/binlog connection); rejected at config load for batch exports (batch is one query/table per export). Mutually exclusive with table:; not supported for SQL Server | |
mode | full | incremental | chunked | time_window | cdc | no | full | Export mode. cdc = log-based change data capture (cdc.md). MongoDB supports full + cdc only (a document store has no chunked/incremental/time_window). |
format | parquet | csv | yes | — | Output format |
compression | zstd | snappy | gzip | lz4 | none | no | zstd | Compression codec (low-level; prefer compression_profile) |
compression_level | integer | no | codec default | Compression level (low-level; prefer compression_profile) |
compression_profile | none | fast | balanced | compact | no | — | High-level preset — overrides compression and compression_level. See Compression profiles below. |
destination | object | yes | — | Where to write output (see below) |
verify | size | content | no | size | Integrity depth required of --validate. content checks every part’s MD5 against the store’s listing (no download) and fails validation for any part only size-verified — e.g. a part too large to upload as a single PUT (lower max_file_size so it fits) or a backend that exposes no checksum (local FS, streamed multipart). See Verification depth below. |
skip_empty | boolean | no | false | Record a 0-row batch run as skipped instead of success (no file is written for 0 rows either way; a full load then keeps the previous data). Not read by mode: cdc |
max_file_size | string | no | — | Split output: "256MB", "1GB", etc. |
wave | integer | no | — | Advisory execution wave (1 = highest priority, runs first). Written by rivet plan from the source-aware prioritization score (ADR-0006); consumed by rivet apply <config>, which runs exports wave-by-wave in ascending order (no wave: runs last). Hand-editable; a later rivet plan refreshes it. |
parallel_safe | boolean | no | — | Whether this export is cheap enough (cost class Low, < ~100K rows, and not isolate_on_source) to run concurrently with its wave-mates under rivet apply --parallel-export-processes. Written by rivet plan; a heavier export runs alone in its wave (it already chunk-parallelizes internally). Hand-editable. |
meta_columns | object | no | — | Extra columns added to output |
quality | object | no | — | Data quality checks |
tuning | object | no | — | Per-export tuning overrides |
source_group | string | no | — | Logical group for shared source capacity (replica, host). Drives campaign-level warnings in rivet plan (advisory only — ADR-0006) |
reconcile_required | boolean | no | false | Advisory hint: treat this export as reconcile-sensitive in planning, independent of the --reconcile CLI flag (ADR-0006, Epic C) |
columns | map | no | — | Per-column type overrides (see below) |
on_schema_drift | warn|continue|fail | no | warn | Policy when structural schema drift is detected (see below) |
shape_drift_warn_factor | float | no | 2.0 | Warn when a string/binary column’s max byte length grows beyond N × stored_max. Set to 0 to disable shape tracking. |
parquet | object | no | — | Parquet row group tuning (Parquet format only). See Parquet row group tuning below. |
Compression profiles
compression_profile is the recommended way to pick a codec. It maps to a (codec, level) pair and takes precedence over any compression / compression_level fields.
| Profile | Codec | Level | Best for |
|---|---|---|---|
none | no compression | — | Debug, local scratch, fast iteration |
fast | snappy | — | Backfills, pilot runs, low-CPU environments |
balanced | zstd | 3 | Default for production — good ratio, moderate CPU |
compact | zstd | 9 | Storage- or network-cost-sensitive pipelines |
exports:
- name: events
format: parquet
compression_profile: balanced # zstd level 3
destination: { type: local, path: ./out }
If you need a specific codec that is not covered by the presets, use compression + compression_level directly and omit compression_profile.
Verification depth
verify controls how thoroughly --validate (and rivet validate) checks each
part at the destination:
size(default) — confirm each part exists at its recordedsize_bytes, plus manifest self-consistency and_SUCCESS. Content is also MD5-checked for free whenever the store surfaces a checksum in its listing, but a part without one is accepted as size-only.content— require every part’s content MD5 to match the store’s listing checksum (no download). Any part that could only be size-verified fails validation with an actionable message.
How content verification works: Rivet computes each part’s MD5 before upload and
records it in the manifest; GCS and Azure compute their own for a part uploaded
as a single PUT and return it in object listings. --validate compares the two
with no download. Parts large enough to stream as multipart / block-list get
no checksum, and neither does S3 (its ETag is not an MD5 under SSE-KMS / SSE-C, so
rivet does not trust it) or local FS. Under verify: content on GCS / Azure, set
destination.oneshot_budget_mb (default 64 MB) comfortably above your part size:
the budget is shared by concurrent uploads, so a part one-shots only if it fits
what is free at that moment. S3 cannot meet verify: content.
The run report and rivet validate show coverage explicitly, e.g.
3 verified (2 md5, 1 size-only).
Parquet row group tuning
Parquet row groups affect memory usage during write, compression ratio, and downstream query performance (predicate pushdown, column skipping). When parquet: is omitted, Rivet uses the library default of 1,048,576 rows per group, which is optimal for narrow tables but can be large for wide tables.
exports:
- name: events
format: parquet
parquet:
row_group_strategy: auto # auto | fixed_rows | fixed_memory
target_row_group_mb: 128 # target Arrow buffer size per group (auto + fixed_memory)
max_row_group_mb: 256 # optional upper bound (all strategies)
| Field | Type | Default | Description |
|---|---|---|---|
row_group_strategy | auto | fixed_rows | fixed_memory | auto | How to determine row group size |
row_group_rows | integer | — | Exact rows per group; used with fixed_rows only |
target_row_group_mb | integer | 128 | Target Arrow buffer per group in MB; used with auto and fixed_memory |
max_row_group_mb | integer | — | Hard upper bound on group memory in MB (all strategies) |
| Strategy | Behavior |
|---|---|
auto | Estimates row width from schema column types, computes rows-per-group to hit target_row_group_mb. Narrow tables get large groups; wide tables get smaller groups. |
fixed_rows | Use row_group_rows exactly. Simple and deterministic, but does not adapt to row width. |
fixed_memory | Same math as auto (target / estimated row bytes), but the strategy name is explicit in logs. |
Examples:
# Auto-tune for a wide JSON table — groups sized to ~64 MB
parquet:
row_group_strategy: auto
target_row_group_mb: 64
max_row_group_mb: 128
# Fixed row count — useful when downstream tooling requires exact group sizes
parquet:
row_group_strategy: fixed_rows
row_group_rows: 500000
Note:
rivet planshows the selected strategy and target in the Format section whenparquet:is configured.
rivet initauto-generates this block for chunked exports and large full-mode tables, pre-selectingtarget_row_group_mb: 64for wide schemas (≥ 5 text/JSON/bytea columns) and128for narrow ones.
exports[].on_schema_drift — schema drift policy
Controls what Rivet does when it detects a structural change in the output schema (column added, removed, or retyped) compared to the snapshot stored from the previous run.
| Value | Behavior |
|---|---|
warn | (default) Log a warning, store the new schema fingerprint, and continue the run. |
continue | Silently accept — store the new schema, no log output. |
fail | Abort the run with exit code 4 (the schema-drift exit class). The schema store is not updated, so the next run will detect the same change again. |
fail is useful in CI pipelines where schema changes must be reviewed before the new shape is exported downstream.
exports:
- name: orders
on_schema_drift: fail
When fail triggers, behavior depends on the runner: in single, keyset, and parallel-Mongo modes the schema check runs post-extraction, so the output file has already been written to the destination (but no cursor advance or manifest commit occurs). In chunked mode the check runs pre-chunk from a scan-free type probe, so the run aborts before any chunk is written. Re-run after confirming the schema change is intentional, or switch to warn to accept it.
exports[].columns — per-column type overrides
Override the Arrow type Rivet infers for a specific column. Useful when:
- a
NUMERIC/DECIMALcolumn has no explicit precision/scale in the source schema (beyondrivet init’s defaultdecimal(38,18)placeholder), or - you need a narrower precision for BigQuery NUMERIC compatibility.
columns:
<column_name>: <type> # applies to every captured table with the column
"<table>.<column>": <type> # applies to ONE table, wins over the bare key
Supported override types: decimal(p,s) / numeric(p,s) (both precision and
scale required; precision > 38 produces Decimal256), integer widths
(smallint/int/bigint/int16/int32/int64), floats
(real/float4/double/float8), bool, text/string/varchar,
uuid, json/jsonb, date, the timestamp* family (naive / tz /
_ns variants), and binary (bytea/binary/varbinary/blob).
Overrides apply to batch and CDC identically (the same resolution
surface). Key shapes: a bare column name applies to every captured table that
has the column — on a multi-table CDC export that means ALL of them; a
qualified "table.column" key targets one table and wins over the bare
key there. A qualified key naming a table the export does not capture — or
used on a query-shaped export — is a config error at load.
Example:
exports:
- name: orders
query: "SELECT id, amount, fee FROM orders"
format: parquet
destination:
type: local
path: ./out
columns:
amount: decimal(18,2)
fee: decimal(18,6)
rivet init generates these automatically. When introspecting a table, rivet init reads numeric_precision and numeric_scale from information_schema.columns. If both are present, it emits a concrete override (decimal(p,s)). If the column is unbounded (NUMERIC without explicit precision), rivet init emits a working default decimal(38,18) plus a # REVIEW: YAML comment — the config header adds a # NOTE: line, and rivet init -o … prints a stderr reminder so you tighten precision when you know the real domain rules:
columns:
price: decimal(38,18) # REVIEW: DDL has no numeric(p,s); edit to the real decimal(p,s) …
Type overrides are applied at export time and are reflected in rivet check --type-report output.
Some PostgreSQL types have no Arrow representation and cannot be exported directly. Rivet will report an error listing all unmappable columns before the run starts.
| PostgreSQL type | Reason | Workaround |
|---|---|---|
geometry (PostGIS) | No Arrow equivalent | Cast to text: ST_AsText(col) AS col in your query |
geography (PostGIS) | No Arrow equivalent | Cast to text: ST_AsText(col) AS col |
hstore | No Arrow equivalent | Cast to JSON text: hstore_to_json(col)::text AS col |
tsvector, tsquery | No Arrow equivalent | Cast to text: col::text AS col |
point, line, polygon, etc. | No Arrow equivalent | Cast to text: col::text AS col |
Use a SQL expression in your query field to work around any unsupported type:
exports:
- name: locations
query: >
SELECT id, name, ST_AsText(geom) AS geom_wkt
FROM locations
format: parquet
destination:
type: local
path: ./out
Rivet exports the WKT text as a Utf8 (string) column. Downstream tools (DuckDB, GeoPandas, QGIS) can reconstruct geometry from WKT.
Mode-specific fields
Incremental (mode: incremental):
| Field | Type | Required | Default | Description |
|---|---|---|---|---|
cursor_column | string | yes | — | Primary progression column. Must be strictly per-row-distinct and monotonically increasing — resume uses WHERE cursor > last_value, so rows that tie on the high-watermark value and become visible after it is passed are skipped. A low-resolution updated_at (second granularity) can tie; prefer a sequence/identity id or a sub-value-unique timestamp. See semantics.md → Known non-guarantees. |
cursor_fallback_column | string | when coalesce | — | Fallback column used when primary is NULL. Only valid with incremental_cursor_mode: coalesce |
incremental_cursor_mode | single_column | coalesce | no | single_column | coalesce progresses on COALESCE(primary, fallback). See modes/incremental-coalesce.md and ADR-0007. |
settle | object | no | — | Hold rows back until they stop changing: { after: 1h } ages the cursor itself, { after: 1h, column: server_time } ages another date/timestamp column. A row exports only once it is older than after (s/m/h/d) by the source clock. See modes/incremental.md § Settle window. |
Chunked (mode: chunked):
| Field | Type | Required | Default | Description |
|---|---|---|---|---|
chunk_column | string | yes* | — | Numeric or date/timestamp column to partition by. *Required unless chunk_by_key is set (mutually exclusive). |
chunk_by_key | string | yes* | — | Single index-backed UNIQUE NOT NULL column for keyset (seek) pagination — the source-safe shape for tables with no single-integer PK (UUID / string / composite). Requires the table: shortcut; mutually exclusive with chunk_column. See chunked modes and ADR-0020. |
chunk_size | integer | no | 100000 | Rows per chunk (numeric mode), or page size for keyset. Ignored when chunk_count is set. |
chunk_size_memory_mb | integer | no | — | Target memory budget per chunk in MB; chunk_size is derived from a per-engine row-size estimate, clamped to [10000, 5000000] rows. Works on PostgreSQL, MySQL and SQL Server (PG: pg_relation_size / reltuples; MySQL: information_schema AVG_ROW_LENGTH with InnoDB overflow correction; SQL Server: no estimate, falls back to 512 B/row with a warning). Requires the table: shortcut, mutually exclusive with an explicit non-default chunk_size:. |
chunk_count | integer | no | — | Divide the column range into exactly this many equal chunks. chunk_size is computed dynamically from min/max. Must be ≥ 1. Mutually exclusive with chunk_by_days. |
chunk_by_days | integer | no | — | Enable date chunking: window size in days. Mutually exclusive with chunk_count. |
parallel | integer | no | 1 | Concurrent chunk workers |
chunk_dense | boolean | no | false | Removed. true is refused at config load (it skipped or duplicated rows under concurrent writes); use chunk_by_key or chunk_column. |
chunk_checkpoint | boolean | no | false | Persist per-chunk progress for resume |
chunk_max_attempts | integer | no | — | Max retry attempts per chunk |
Time-window (mode: time_window):
| Field | Type | Required | Default | Description |
|---|---|---|---|---|
time_column | string | yes | — | Timestamp column to filter on |
time_column_type | timestamp | unix | no | timestamp | Column type |
days_window | integer | yes | — | Rolling window size in days |
exports[] — value-based partitioning
Splits a full, chunked or incremental export’s rows into Hive-style
col=value/ destination sub-folders by a date column. See partitioning.md.
| Field | Type | Required | Default | Description |
|---|---|---|---|---|
partition_by | string | no | — | Date/timestamp column to bucket rows by. Requires a {partition} token in destination.path/prefix. NULLs → col=__HIVE_DEFAULT_PARTITION__/. Not compatible with mode: time_window, mode: cdc, chunk_by_key, a load: block (per-export or top-level), or a MongoDB source. |
partition_granularity | day | month | year | no | day | Bucket width. |
exports[].meta_columns
| Field | Type | Default | Description |
|---|---|---|---|
exported_at | boolean | false | Add _rivet_exported_at column (Timestamp UTC; one value captured at sink construction and shared by every batch/row that sink writes — effectively one value per export run in single mode, per chunk (or keyset page) in multi-part modes) |
row_hash | boolean or list of column names | false | Add _rivet_row_hash column — lower 64 bits of xxHash3-128, written as Int64 for fast PARTITION BY / JOIN. true hashes every column; a list (row_hash: [id, status, updated_at]) hashes exactly those columns in that order and records the covered set in the run manifest. Deterministic across runs; distinguishes NULL from empty string. |
exports[].quality
| Field | Type | Description |
|---|---|---|
row_count_min | integer | Fail if fewer rows exported |
row_count_max | integer | Fail if more rows exported |
null_ratio_max | map (column → float) | Fail if null ratio exceeds threshold |
unique_columns | list of strings | Fail if values are not unique |
unique_max_entries | integer | Cap on distinct values tracked per column during uniqueness checks. When reached, a Warn is emitted and checking stops for that column; duplicates already found before the cap still fail the run. Prevents unbounded memory growth on high-cardinality columns (UUIDs, email addresses, event IDs). |
Uniqueness tracking uses typed xxHash3-64 internally — numeric and binary columns are hashed directly from raw bytes without string formatting. unique_max_entries is the primary knob to control memory on very large tables.
Example:
quality:
row_count_min: 100
null_ratio_max:
email: 0.05 # email must be <5% null
unique_columns:
- id
- email
unique_max_entries: 1000000 # stop after 1M unique values; warn if limit hit
Without unique_max_entries — tracking is unbounded. Safe for tables with hundreds of thousands of rows; may use significant RAM on tables with tens or hundreds of millions of distinct values.
With unique_max_entries — tracking stops at the limit and the run summary shows a warning. Duplicates found before the limit still fail the run; ones past it go unseen. Use when you want a best-effort uniqueness check without memory risk.
exports[].destination
The complete per-backend field list (local / s3 / gcs / azure / stdout)
is in the generated config-reference.md (section
exports[].destination). Per-backend setup, auth flows, and permissions:
destinations/ — local ·
s3 · gcs ·
azure · stdout, plus the
cloud auth matrix.
Path and prefix placeholders
The path (local) and prefix (S3 / GCS) fields support template placeholders, substituted at plan-build time:
| Placeholder | Value |
|---|---|
{date} | UTC date as YYYY-MM-DD |
{export} | Export name from config |
{table} | Alias for {export} |
{run_id} | The run’s unique id — substituted only by rivet validate --run-id, which re-targets validation at that run’s prefix. run and apply resolve destinations without a run id, so the token is always left verbatim there and the destination open fails fast rather than aliasing to an unintended prefix (and rivet load refuses a {run_id} prefix outright — it cannot know which run’s output to load). |
destination:
type: s3
bucket: my-data
prefix: exports/{date}/{export}/
region: us-east-1
With an export named orders running on 2026-05-14, this resolves to exports/2026-05-14/orders/.
notifications
| Field | Type | Description |
|---|---|---|
slack | object | Slack notification config |
notifications.slack
| Field | Type | Description |
|---|---|---|
webhook_url | string | Slack incoming webhook URL |
webhook_url_env | string | Env var containing webhook URL |
on | list | Events to notify on: failure, schema_change, degraded |
Example:
notifications:
slack:
webhook_url_env: SLACK_WEBHOOK
on: [failure, schema_change]
Environment variable interpolation
Any string value can reference environment variables:
source:
url: "postgresql://${DB_USER}:${DB_PASS}@${DB_HOST}:5432/mydb"
Query parameters
Queries can use ${key} placeholders filled by --param key=value:
exports:
- name: filtered
query: "SELECT * FROM orders WHERE region = '${region}'"
rivet run --config export.yaml --param region=us-east
Config reference (generated — rivet-cli 0.30.0)
Rendered from the JSON Schema rivet schema config emits (schemars ← the Rust Config types). It cannot drift from the code. Hand-written guidance lives in the surrounding config guide; this table set is generated — edit the Rust structs, not this block.
Top level (rivet.yaml)
| Field | Type | Required | Description |
|---|---|---|---|
source | SourceConfig | yes | |
exports | array of ExportConfig | yes | |
notifications | NotificationsConfig | ||
parallel_exports | boolean | Same as rivet run --parallel-exports: the exports run concurrently, at most 16 at once; a CDC export run alone also takes its pending baseline snapshots at most 16 at once. | |
parallel_export_processes | boolean | ||
load | LoadSection | The warehouse load target — consumed by rivet load, so ONE config drives both the export and the downstream load. The extraction commands validate it (a malformed block fails rivet check before an extract runs) and otherwise ignore it: it shapes the load, not the extract. |
source
| Field | Type | Required | Description |
|---|---|---|---|
type | postgres | mysql | mssql | oracle | mongo | yes | |
url | string | ||
url_env | string | ||
url_file | string | ||
host | string | ||
port | integer | ||
user | string | ||
password | string | ||
password_env | string | ||
database | string | ||
environment | local | replica | production | Operational profile of the source database. Selects the default tuning profile when none is explicitly set in source.tuning.profile or export.tuning.profile: | |
tuning | TuningConfig | ||
tls | TlsConfig | Transport security settings (ADR: SecOps). When absent, Rivet connects without TLS — a warning is emitted so operators are aware. See [TlsConfig]. | |
mongo | MongoConfig | MongoDB-specific read options (source.mongo:). Honoured only when type: mongo; ignored by the SQL engines. See [MongoConfig]. |
source.mongo (MongoDB read options)
| Field | Type | Required | Description |
|---|---|---|---|
json | relaxed | canonical | JSON rendering of the document column. relaxed (default) keeps common scalars native (42, "x"); canonical wraps every number ({"$numberLong":"…"}) so Int64/Double round-trip losslessly through a JSON-number parser that would otherwise clamp values beyond 2^53. | |
read_concern | server | snapshot | Read concern for the collection scan. snapshot gives a point-in-time consistent full export (no doc missed/double-read under concurrent writes) — requires MongoDB 5.0+ on a replica set; a standalone rejects it. Default (server) uses the server’s default read concern. | |
no_cursor_timeout | boolean | Keep the scan cursor alive past the server’s idle timeout (default 10 min) so a slow destination cannot let the server reap the cursor mid-scan and silently drop the tail of a large collection. Default: true. | |
page_size | integer | When set, read the collection with keyset (seek) pagination on _id instead of one long-held cursor: each page is a bounded find({_id: {$gt: last}}).sort({_id: 1}).limit(page_size) — an indexed range scan that becomes one output part file. Bounds longest-query time (no 35-minute cursor to hit a timeout / snapshot window) and is the base for parallel _id-range reads. Works with any uniform _id type (ObjectId — the default — integer, string, date, …); a collection mixing _id type brackets errors with a clear message pointing at the full ordered scan (Mongo’s $gt compares only within a type bracket, so a mixed key would silently drop every bracket but one). Unset ⇒ the single-cursor full scan. | |
resume | boolean | With keyset paging (page_size), persist the last committed _id and resume from it next run — a crashed export continues where it left off, and a re-run captures only documents inserted since (ObjectId _id is time-ordered). Default false re-reads the whole collection each run (plain mode: full semantics). No effect without page_size. |
source.tls
| Field | Type | Required | Description |
|---|---|---|---|
mode | disable | require | verify-ca | verify-full | Enforcement level. See [TlsMode]. | |
ca_file | string | PEM-encoded CA certificate to trust for server verification. Required for [TlsMode::VerifyCa] and [TlsMode::VerifyFull] against a private CA. | |
accept_invalid_certs | boolean | Accept certificates not chained to a trusted CA. Dangerous — disables server authentication — and only honored when explicitly true. | |
accept_invalid_hostnames | boolean | Accept certificates whose subjectAltName does not match the connection hostname. Dangerous — disables hostname verification. |
exports[]
| Field | Type | Required | Description |
|---|---|---|---|
name | string | yes | |
query | string | ||
query_file | string | ||
table | string | Shortcut for query: "SELECT * FROM <schema>.<table>". Accepts table or schema.table with ASCII-only identifiers ([A-Za-z_][A-Za-z0-9_]*). Generates an unquoted single-table query so the Postgres NUMERIC catalog-hint resolver recognises it and auto-types numeric(p,s) columns without manual overrides. Mutually exclusive with query and query_file. | |
tables | array of string | CDC only: capture several tables through ONE change stream (one PostgreSQL slot / one MySQL binlog connection) instead of one export — and one slot — per table. Each table’s parts land under <destination>/<table>/ with their own manifest.json + _SUCCESS; the checkpoint (stream position) is shared. Mutually exclusive with table:. Not yet supported for SQL Server (capture instances are per-table). | |
mode | full | incremental | chunked | time_window | cdc | ||
cdc | CdcExportConfig | Change-data-capture settings, required when mode: cdc. Reuses the export’s table, destination, and format; carries only the CDC-specific knobs (resume checkpoint, per-engine stream params). | |
cursor_column | string | ||
cursor_fallback_column | string | Secondary column for [IncrementalCursorMode::Coalesce] only (see ADR-0007). | |
incremental_cursor_mode | single_column | coalesce | How primary (and optional fallback) columns drive incremental progression. | |
settle | SettleConfig | Incremental only: export a row once it is older than settle.after (source clock). | |
chunk_column | string | ||
chunk_dense | boolean | Removed. Kept only so a config that still sets chunk_dense: true is refused at load. | |
chunk_size | integer | ||
chunk_size_memory_mb | integer | Target memory budget per chunk in MB. When set, chunk_size is derived from this budget at plan-build time using the engine’s row-size estimate (PostgreSQL pg_relation_size / reltuples; MySQL information_schema average row length; a defensive 512 B/row default when no estimate exists, e.g. SQL Server), clamped to [10_000, 5_000_000] rows. Mutually exclusive with an explicit non-default chunk_size:. Requires mode: chunked and the table: shortcut (the row-size probe needs a known relation); any SQL engine works. yaml exports: - name: page_views table: public.page_views mode: chunked chunk_size_memory_mb: 256 | |
chunk_count | integer | Divide the column range into exactly this many equal chunks. Mutually exclusive with chunk_by_days. When set, chunk_size is computed dynamically from min/max. | |
chunk_by_days | integer | ||
chunk_by_key | string | Keyset (seek) pagination on this single index-backed unique key — the source-safe shape for tables without a single-integer PK (OPT-4). The column MUST be backed by a usable index (PK or unique); the planner refuses a non-indexed key rather than emit a full-scan + filesort query. | |
parallel | integer | Concurrent chunk/page workers (default 1). On a RANGE chunk (chunk_column) or KEYSET (chunk_by_key) export, parallel: N fans the table into N ROW-percentile ranges that seek concurrently over separate connections — the half-open intervals partition the key, so the union reads every row exactly once (structural parity, all engines). Extraction is I/O-bound, so the win plateaus early (~3x at N=4, little beyond). SWEET SPOT: indexed tables up to ~10M rows at parallel: 4. rivet init scaffolds a row-scaled value (<=500K -> 1, <5M -> 2, >=5M -> 4); a preflight warns past ~5M rows (peak RSS ~= N x chunk_size). Beyond ~10M the KEYSET boundary sampler (an index OFFSET skip) grows costly at setup — prefer a range chunk_column there. | |
wave | integer | Advisory execution wave (1 = highest priority, run first). Written by rivet plan from the source-aware prioritization score (see ADR-0006) and consumed by rivet apply, which runs exports wave-by-wave in ascending order. None = unscheduled (apply treats it as the last wave). Operators may hand-edit it; a later rivet plan refreshes it in place. | |
parallel_safe | boolean | Whether this export is cheap enough to run concurrently with its wave-mates under rivet apply --parallel-export-processes. Written by rivet plan (true when the source-aware cost class is Low, i.e. < ~100K rows); a heavier table already chunk-parallelizes internally, so two of them at once would overload the source. None/false → the export runs alone within its wave. Operators may hand-edit it; a later rivet plan refreshes it in place. | |
time_column | string | ||
time_column_type | timestamp | unix | ||
days_window | integer | ||
partition_by | string | Date/time output partitioning: split this export’s rows into one destination sub-prefix per calendar bucket of this DATE or TIMESTAMP column, bucketed by partition_granularity (day / month / year), in a Hive-style col=value/ layout (created_at=2023-01-01/, created_at=2023-01/, created_at=2023/). Requires a {partition} token in destination.path / destination.prefix. This is not arbitrary value partitioning: the column’s min/max is read and parsed as a date to generate contiguous calendar buckets, so a non-temporal column (e.g. partition_by: status) fails at run time with “could not parse partition min <value> from column <col> as a date”. To split by a categorical column, write one export per value with a WHERE filter instead. Applies to full, chunked and incremental exports on a SQL source: each partition runs the export’s own mode, so mode: chunked chunks within a day. Rows whose partition column is NULL land in col=__HIVE_DEFAULT_PARTITION__/ (Hive default partition) so no row is silently dropped. Not compatible with mode: time_window, mode: cdc, chunk_by_key, a load: block (per-export or top-level), or a MongoDB source — each is refused when the config loads. yaml exports: - name: events table: events partition_by: created_at # must be a DATE or TIMESTAMP column partition_granularity: day destination: type: s3 bucket: my-bucket prefix: "events/{partition}/" # → events/created_at=2023-01-01/ | |
partition_granularity | day | month | year | Calendar bucket width for partition_by: day (default), month, or year. Determines how the partition column’s date/timestamp range is split into contiguous Hive buckets (col=2023-01-01/ / col=2023-01/ / col=2023/). Has no effect unless partition_by is set. | |
format | parquet | csv | yes | |
compression | zstd | snappy | gzip | lz4 | none | ||
compression_level | integer | ||
compression_profile | none | fast | balanced | compact | ||
skip_empty | boolean | Record a batch run that delivers 0 rows as skipped (with a reason) instead of success, on every batch runner. No file is written for 0 rows either way, and a skipped run leaves the prefix describing the last run that delivered, so a full load keeps the previous data. mode: cdc does not read it. | |
destination | DestinationConfig | yes | |
verify | size | content | Integrity depth required of --validate for this export’s parts. size (default) accepts size-only verification; content requires every part’s content MD5 to be checked against the store’s listing (no download) and fails validation for any part that could only be size-verified — a part too large for a single PUT (on GCS / Azure, raise destination.oneshot_budget_mb above the part size), or a backend that exposes no trusted checksum (S3, local FS). | |
meta_columns | MetaColumns | ||
quality | QualityConfig | ||
max_file_size | string | Rotate to a new part when the current file reaches this size. Accepts B/KB/MB/GB (case-insensitive) or a bare byte count; a fractional value is allowed (1.5GB). Units are binary (IEC-style): KB = 1024 bytes, MB = 1024 KB, GB = 1024 MB. Example: 256MB. Parquet row groups are capped at a quarter of it, so a part stays within about one row group of the size whatever parquet.row_group_strategy says. | |
chunk_checkpoint | boolean | Persist per-chunk / per-page progress so a crashed run resumes from the last durably committed point instead of re-reading from the start. This is pure crash-recovery: a clean re-run (the prior run finished) still does a full pass — it never silently skips already-exported rows. Safe to enable on any table; rivet init defaults it on for chunked and keyset exports. | |
keyset_incremental | boolean | Keyset only (chunk_by_key): on a clean re-run, continue from the last exported key — pull ONLY rows with a key past the high-water mark. This is incremental-by-key, correct ONLY for APPEND-ONLY tables (a mutable row whose key already passed is silently never re-read). Opt-in and off by default; crash-recovery does not need it (that is chunk_checkpoint). For a mutable table use mode: incremental on a timestamp cursor instead. | |
chunk_max_attempts | integer | ||
tuning | TuningConfig | ||
source_group | string | Optional logical group for shared source capacity (replica, host). Advisory prioritization only. | |
reconcile_required | boolean | Hint (Epic C / ADR-0006) that this export should always be treated as reconcile-heavy by planning, independent of the --reconcile CLI flag. Advisory only. | |
columns | object | Per-column type overrides (roadmap §8). Keys are column names; values are short type strings such as decimal(18,2), timestamp_tz, json. yaml exports: - name: payments columns: amount: decimal(18,2) fee: decimal(18,6) created_at: timestamp_tz Overrides take priority over autodetection and are validated at plan time — an invalid type string fails before the export runs. | |
target | string | Downstream warehouse this export targets (bigquery / bq, duckdb). When set, rivet check --type-report resolves each column against it (native type, honest autoload type, recovery hint) without needing --target on the CLI — the CLI flag still wins when both are present. The Parquet interchange stays target-neutral (ADR-0014 T2); target: only drives guidance and the future load-schema artifact. yaml exports: - name: payments target: bigquery | |
load | LoadOverride | Per-export overrides for the top-level load: block (pk, cleanup_source, gc_orphans, cluster_by, partition, allow_source_drift); any field omitted here inherits the top-level value. The warehouse target is shared and stays in the top-level load: — it cannot be overridden per export. yaml load: { target: bigquery, project: p, dataset: d } # shared default exports: - name: orders table: orders mode: cdc load: pk: [id] # this table's pk partition: { column: created_at, granularity: day, expiration_days: 400 } | |
on_schema_drift | warn | continue | fail | Policy applied when structural schema drift is detected (column added, removed, or retyped). Defaults to warn: log a warning and continue. | |
shape_drift_warn_factor | number | Growth-factor threshold for data shape drift warnings (Epic 8). When a string/binary column’s max observed byte length in the current run exceeds stored_max * shape_drift_warn_factor, Rivet logs a warning. None uses the default of 2.0. Set to 0.0 to disable shape tracking. Applies to every batch mode — multi-part runs compare the largest value any chunk, page or worker saw. mode: cdc does not check it. | |
parquet | ParquetConfig | Parquet row group tuning. Only meaningful when format: parquet. When absent, the parquet library default (1,048,576 rows/group) is used. |
exports[].cdc (mode: cdc)
| Field | Type | Required | Description |
|---|---|---|---|
initial | snapshot | First-run behaviour: snapshot = anchor → full snapshot → drain (see [CdcInitialMode]). Omitted ⇒ capture changes only, with no anchor step (the default; the operator owns the initial load). snapshot anchors, and on engines with no server-side anchor (MySQL, SQL Server) that makes checkpoint: mandatory — the checkpoint file IS the anchor there. This doc line is what the generated config reference renders, so every accepted value must be explained HERE: the reference lists the variants from the enum but describes only this sentence, so an explanation left on a variant alone documents a value the reader is told exists and never told the meaning of. | |
checkpoint | string | Persist/resume the source log position to this file. Omit to tail from the current position without checkpointing. | |
until_current | boolean | Catch up to the source’s current end and exit (a bounded run), instead of streaming indefinitely — ideal for a scheduler. For MySQL this is a non-blocking binlog dump; PostgreSQL / SQL Server already drain-and-exit. Defaults to true (bounded): the OSS model is scheduler-driven, and omitting this must NOT silently start a never-terminating stream. Setting false opts into the continuous model, which is engine-specific: a true daemon on MySQL (blocking binlog dump) and MongoDB (the change stream blocks awaiting events; ends only if the stream is invalidated/closed); PostgreSQL / SQL Server still exit on catch-up — one unbounded pass, run it under a supervisor. Oracle refuses false: LogMiner is always a bounded drain to the SCN current at open. | |
max_events | integer | Stop at the first COMMIT BOUNDARY once N change events have been captured (default: until end of stream / interrupted). A soft cap, like rollover: a transaction is never split, so the run may overshoot N by the remainder of the transaction the cap landed in — a hard per-event stop cut transactions mid-flight and left the stream unable to advance past them. | |
rollover | integer | Rows per output part file (default 100000). A part also rolls at a transaction boundary, so it never splits a transaction. Larger ⇒ fewer, bigger files but more drain memory — the PostgreSQL peek reads a part’s worth per batch, so drain RSS is O(rollover). Tune per workload: raise it to cut file count, lower it to cap memory on a small extractor. | |
rollover_memory_mb | integer | Roll a part once its buffered changes reach this many MB, whichever comes first with rollover. Caps the in-memory buffer and the part file size by bytes instead of a fixed row count — predictable for tables with wide (large JSON / blob) rows, mirroring the batch path’s batch_size_memory_mb. Defaults to 256 (MiB): the row count alone is a budget for one row width, and absence must not mean “no byte budget”. The bytes are the buffered changes’ RESIDENT cost (struct + commit position + values), not the part file’s size on disk. It bounds the buffer, not the process: a roll encodes up to 16 tables’ parts at once, each a columnar copy of its buffered rows, so peak RSS sits above the budget (measured +31% on a 60-table stream). | |
server_id | integer | MySQL replica server-id for the binlog connection (default 4271; must be distinct from the source’s and any other replica). | |
slot | string | PostgreSQL logical replication slot name (default rivet_slot). | |
capture_instance | string | SQL Server CDC capture instance, e.g. dbo_orders — required for sqlserver:// sources. | |
backfill | auto | Which EXPORTS supply the baseline read (see [CdcBackfill]). Absent ⇒ no baseline: the stream captures changes only, and the operator owns the initial load. |
exports[].tuning
| Field | Type | Required | Description |
|---|---|---|---|
profile | fast | balanced | safe | ||
batch_size | integer | ||
batch_size_memory_mb | integer | Target memory per batch in MB. Mutually exclusive with batch_size. | |
throttle_ms | integer | ||
statement_timeout_s | integer | ||
max_retries | integer | ||
retry_backoff_ms | integer | ||
lock_timeout_s | integer | ||
memory_threshold_mb | integer | ||
max_batch_memory_mb | integer | Hard cap on Arrow batch memory in MB. When a batch exceeds this limit, on_batch_memory_exceeded determines the response. | |
on_batch_memory_exceeded | warn | fail | auto_shrink | Policy applied when a batch exceeds max_batch_memory_mb. Default: warn. | |
adaptive | boolean | Enable real-time batch size adaptation based on DB pressure metrics. The batch loop samples the export’s OWN extraction pressure: Postgres pg_stat_bgwriter checkpoint pressure; MySQL the read-spill pair Created_tmp_disk_tables and Innodb_buffer_pool_wait_free. SQL Server takes no batch sample — its batch size comes from the memory cap alone. It also arms the OPT-2 concurrency governor when parallel > 1. The governor samples a DIFFERENT, write-driven signal on its own monitoring connection — one a read-only export cannot inflate, so it can never shed its own workers over its own reads: Postgres checkpoints_req, MySQL Innodb_log_waits, SQL Server Log Flush Waits/sec (_Total). | |
min_parallel | integer | Floor for the concurrency governor (lowest parallelism under pressure). Default 1. Ceiling is the export’s parallel. | |
max_value_mb | integer | Hard per-value size ceiling in MB. A single text/JSON/blob cell larger than this aborts the run with RIVET_VALUE_TOO_LARGE. 0 disables the guard. Default: 256. |
exports[].destination
| Field | Type | Required | Description |
|---|---|---|---|
type | local | s3 | gcs | azure | stdout | yes | |
bucket | string | ||
prefix | string | ||
path | string | ||
region | string | ||
endpoint | string | ||
credentials_file | string | ||
access_key_env | string | ||
secret_key_env | string | ||
session_token_env | string | Name of an env var holding an AWS STS session token, for use with short-lived credentials issued by AWS IAM Identity Center / SSO, aws sts assume-role, MFA-protected sessions, EKS IAM Roles for Service Accounts, etc. Pair with access_key_env + secret_key_env. See docs/cloud-auth.md for the AWS auth-flow matrix. | |
aws_profile | string | ||
account_name | string | Azure storage account name (the prefix in <account>.blob.core.windows.net). Plain string — not a secret. Pair with account_key_env. See docs/cloud-auth.md for the Azure auth-flow matrix. | |
account_key_env | string | Name of an env var holding the Azure Storage account key. Treated as a credential and wiped from heap on drop — same SecOps treatment as access_key_env. Pair with account_name. Mutually exclusive with sas_token_env. | |
sas_token_env | string | Name of an env var holding an Azure Storage SAS token — typically a short-lived, scope-limited credential issued out-of-band (Azure portal / az storage container generate-sas / Azure SDK). Use this instead of account_key_env when the operator does not have the long-lived account key or wants per-job scoped access. Pair with account_name. Mutually exclusive with account_key_env. The token value is wiped from heap on drop via the same Zeroizing<String> wrapper as account_key_env. Leading ? is trimmed transparently so the operator can paste either the full ?sv=…&sig=… query string or the raw token body. | |
allow_anonymous | boolean | ||
oneshot_budget_mb | integer | Cap on the RAM one-shot (single-PUT) upload buffers may hold, in MB (default 64; cloud destinations only). A one-shot PUT buffers the whole part; on GCS and Azure the store then records a Content-MD5 that validate checks, and on every store it is one request instead of a sequential multipart (S3 verifies size-only either way). A part that does not fit the remaining budget streams instead (memory-bounded). 0 streams every non-empty part. Each distinct value is one pool per rivet process, shared by every destination configured with it (including each table of a CDC export). Different values are separate pools, so worst-case one-shot RAM is the sum of the distinct values in use; under parallel_export_processes every child has its own. |
exports[].quality
| Field | Type | Required | Description |
|---|---|---|---|
row_count_min | integer | ||
row_count_max | integer | ||
null_ratio_max | object | ||
unique_columns | array of string | ||
unique_max_entries | integer | Cap on the number of distinct values tracked per column during uniqueness checks. When the limit is hit, a Warn issue is emitted and tracking stops for that column. Prevents unbounded HashSet growth on high-cardinality columns. |
exports[].parquet
| Field | Type | Required | Description |
|---|---|---|---|
row_group_strategy | auto | fixed_rows | fixed_memory | How to determine the row group size. Default: auto. | |
row_group_rows | integer | Exact number of rows per group (fixed_rows only). | |
target_row_group_mb | integer | Target Arrow buffer memory per row group in MB (auto and fixed_memory). Default: 128. | |
max_row_group_mb | integer | Hard upper bound on row group memory in MB. When set, further reduces computed row count. |
load (the warehouse target, consumed by rivet load)
| Field | Type | Required | Description |
|---|---|---|---|
target | bigquery | snowflake | clickhouse | yes | The warehouse: bigquery, snowflake or clickhouse. |
project | string | BigQuery: the project the dataset lives in. | |
dataset | string | BigQuery: the dataset the tables are created in. | |
connection | string | Snowflake: the snow CLI connection name. | |
warehouse | string | Snowflake: the virtual warehouse the load runs on. | |
database | string | Snowflake / ClickHouse: the database the tables are created in. | |
schema | string | Snowflake: the schema the tables are created in. | |
storage_integration | string | Snowflake: a pre-created GCS STORAGE INTEGRATION. | |
url | string | ClickHouse: the HTTP endpoint, e.g. http://localhost:8123. | |
user | string | ClickHouse: the user the load authenticates as. | |
password_env | string | ClickHouse: the env var holding that user’s password. | |
named_collection | string | ClickHouse: a server-side named collection holding the bucket’s URL and HMAC keys; ClickHouse then reads the Parquet itself instead of rivet sending it. | |
cleanup_source | boolean | After a successful load, delete the staged Parquet under the export prefix. | |
pk | auto | none | Dedup key of the incremental/CDC current-state view: auto (the source primary key rivet run recorded), none, or explicit columns; ignored for full. | |
layout | log_view | base_buffer | log_view or base_buffer — where the current state lives. Absent derives it from the mode: a CDC stream with a backfill: is base+buffer, the rest changelog+view. base_buffer needs target: bigquery — rivet compact is what merges the buffer into the base, and it is BigQuery-only. | |
deleted_flag | boolean | Whether the base carries a __is_deleted column. Absent derives it from the mode: a CDC stream expresses deletes and gets the flag, a query-based export cannot express one and does not — an extra column per row otherwise. | |
allow_source_drift | boolean | Load even when a run manifest’s source count disagrees with what it extracted (source→file drift): warn instead of blocking. | |
gc_orphans | boolean | After a successful load, delete staged Parquet under the export prefix that no Success manifest references — crash leftovers. Only when no extract writes the prefix concurrently. | |
cluster_by | auto | none | CLUSTER BY of the table the load writes: auto (the primary key), none, or explicit columns (at most 4 on BigQuery). | |
partition | none | How the table the load writes is partitioned: none (default), or exactly one of column (+ granularity), an integer range, or ingestion time. |
exports[].load and exports[].load.tables.<table>
| Field | Type | Required | Description |
|---|---|---|---|
pk | auto | none | Dedup key of this table’s current-state view. | |
cleanup_source | boolean | ||
gc_orphans | boolean | ||
cluster_by | auto | none | CLUSTER BY of this table. | |
allow_source_drift | boolean | ||
layout | log_view | base_buffer | Where this table’s current state lives; inherits when absent. | |
deleted_flag | boolean | Whether this table’s base carries __is_deleted; inherits when absent. | |
partition | none | This table’s partitioning; none clears an inherited one. | |
tables | object | On a multiplex tables: CDC export: the override for ONE captured table, keyed by its name, layered over this block — six tables through one stream rarely share a partition column or a key. Every name must be one of the export’s tables:; a nested tables: is refused. |
rivet init — config scaffolding
rivet init connects to PostgreSQL, MySQL, SQL Server, or MongoDB, introspects tables (collections on MongoDB), and prints a YAML scaffold you can save and edit before running rivet check / rivet run.
Generated configs use url_env: DATABASE_URL so secrets are not embedded in the file. Set DATABASE_URL (or switch to url: / structured credentials) before running exports.
Modes
Single table
Provide --table (optionally schema-qualified: public.orders on PostgreSQL, dbo.orders on SQL Server).
export DATABASE_URL='postgresql://user:pass@localhost:5432/mydb'
rivet init --source "$DATABASE_URL" --table orders -o rivet.yaml
# Qualified name (PostgreSQL)
rivet init --source "$DATABASE_URL" --table analytics.facts -o rivet.yaml
export DATABASE_URL='mysql://user:pass@localhost:3306/mydb'
rivet init --source "$DATABASE_URL" --table orders -o rivet.yaml
Rivet emits one export block: SELECT of all columns, a suggested mode (full, incremental, or chunked) from row estimates and column types, plus chunk_* or cursor_column when applicable. Every scaffold uses format: parquet and, by default, meta_columns with exported_at: true and row_hash: true (lineage and row fingerprinting in the output — see exports[].meta_columns in config). When the heuristic picks chunked, the scaffold also includes chunk_checkpoint: true (resumable runs, rivet run --resume, and reconcile/repair — see chunked mode).
Whole PostgreSQL schema
Omit --table. All base tables and views in the target schema are introspected; the file contains one export per object, sorted by name.
--schema— PostgreSQL schema name (default:public).
export DATABASE_URL='postgresql://user:pass@localhost:5432/mydb'
rivet init --source "$DATABASE_URL" --schema public -o rivet_all_public.yaml
# Non-default schema
rivet init --source "$DATABASE_URL" --schema analytics -o rivet_analytics.yaml
The database itself comes from the connection URL path (/mydb).
Whole MySQL database
Omit --table. All base tables and views in the database are listed from information_schema.
- If the URL already includes the database (
mysql://.../mydb), that database is used. - If the URL has no database path, pass
--schema <database>(same flag name as for Postgres; on MySQL it selects the database name for listing).
rivet init --source 'mysql://user:pass@localhost:3306/rivet' -o rivet_mysql.yaml
# URL without database — name it explicitly
rivet init --source 'mysql://user:pass@localhost:3306/' --schema rivet -o rivet_mysql.yaml
Heuristics (suggested mode)
| Condition | Suggested mode |
|---|---|
| Estimated rows ≤ 100k | full |
| Rows > 100k and an integer chunk column or a keyset-usable single-column PK (integer / float / uuid / string / timestamp / date — not decimal/numeric) | chunked — range chunking with chunk_column / chunk_size on the integer column, or keyset via chunk_by_key for a non-integer PK; chunk_checkpoint: true by default, and sometimes parallel |
| Rows > 100k, no integer chunk column and no keyset-usable single PK, but a timestamp column | incremental with cursor_column (updated_at / created_at preferred) |
The table above applies to the SQL engines (PostgreSQL / MySQL / SQL Server).
MongoDB is schemaless — rivet init introspects no columns, primary keys,
or cursor / chunk candidates — so every collection scaffolds mode: full
(one export per collection), regardless of document count. MongoDB’s only batch
mode is full; use --mode cdc for change capture.
Chunked exports and checkpointing
When the suggested mode is chunked, the scaffold always includes chunk_checkpoint: true. That enables resumable chunk runs after crashes or transient errors (rivet run --resume), chunk state in rivet state chunks, and reconcile/repair workflows. Set it to false only if you intentionally do not want checkpoint state on disk.
Meta columns (defaults)
The YAML scaffold enables exported_at and row_hash for every export. Set either to false, or remove the meta_columns block entirely, to turn them off.
Row estimates are cheap metadata (pg_class.reltuples on PostgreSQL, information_schema.TABLES.TABLE_ROWS on MySQL), not exact COUNT(*).
Always run rivet check --config <file> and adjust modes, destinations, and tuning before production runs.
DECIMAL / NUMERIC column overrides
Rivet reads numeric_precision and numeric_scale from information_schema.columns during introspection. When a NUMERIC or DECIMAL column has explicit precision and scale, the scaffold automatically emits a columns: block with the correct decimal(p,s) override — so exports don’t fail at runtime with an “unsupported type” error:
exports:
- name: payments
query: >
SELECT id, amount, fee
FROM payments
mode: chunked
chunk_column: id
chunk_size: 100000
chunk_checkpoint: true
format: parquet
columns:
amount: decimal(18,2)
fee: decimal(18,6)
destination:
type: local
path: ./output
If the column is declared as plain NUMERIC (no precision / scale in the DDL), rivet init still emits columns: so exports run: it uses decimal(38,18) as a wide default (Decimal128 in Arrow), prefixes the YAML header with a # NOTE: pointing at these lines, and adds # REVIEW: inline on each such column — plus a rivet: note line on stderr when you write rivet init -o <file>. Replace the defaults with precision/scale from your domain (or constrain the DDL) before trusting the export:
columns:
price: decimal(38,18) # REVIEW: DDL has no numeric(p,s); edit to the real decimal(p,s) or change the column type — values outside this bound may truncate or fail export.
Flags (summary)
| Flag | Required | Description |
|---|---|---|
--source | one-of --source* | postgresql://, mysql://, sqlserver://, or mongodb:// URL — visible in shell history / ps output; avoid in production |
--source-env | one-of --source* | Name of an env var holding the URL (e.g. DATABASE_URL). URL never hits the command line. Recommended. |
--source-file | one-of --source* | Path to a file containing just the URL on one line. Credentials stay on disk. |
--table | no | Single table; omit for schema-wide / database-wide scaffold |
--schema | no | PostgreSQL: schema to scan (default public). SQL Server: schema (default dbo). MySQL: database name when the URL omits one (a --schema naming a different database than the URL’s is refused — put the database in the URL instead) |
-o / --output | no | Write output to file; default is stdout |
--discover | no | Emit a JSON discovery artifact (Epic B) instead of a YAML scaffold — see below |
--mode | no | Override the suggested mode for every scaffolded export. --mode cdc scaffolds a change-data-capture config (mode: cdc + an engine-specific cdc: block) instead of a batch query — see cdc.md. Other values (full / incremental / chunked / time_window) just override the auto-suggested mode |
Avoiding credentials on the command line
Shell history, process listings (ps, /proc/<pid>/cmdline), and container inspect logs all capture --source "postgresql://user:pass@host/db" verbatim. For anything beyond local dev, use --source-env or --source-file:
# Recommended — env var resolved inside the process only.
export DATABASE_URL='postgresql://user:pass@host:5432/db'
rivet init --source-env DATABASE_URL --schema public -o cfg.yaml
# File-based — useful when the URL is managed by your secrets mount.
rivet init --source-file /run/secrets/database_url --table orders -o cfg.yaml
Exactly one of --source, --source-env, --source-file must be provided (enforced by clap’s ArgGroup).
Discovery artifact (--discover)
rivet init --discover runs the same introspection but emits a machine-readable JSON document (schema described in src/init/artifact.rs). Intended consumers: external orchestration tools, code review, and automated config generators.
rivet init --source "$PG_URL" --schema public --discover -o discovery.json
rivet init --source "$MY_URL" --table orders --discover # pipes JSON to stdout
Per-table fields (tables[]):
| Field | Description |
|---|---|
schema, table, row_estimate | Table identity and cheap row metadata |
total_bytes | Physical size (pg_total_relation_size; DATA_LENGTH + INDEX_LENGTH) when available |
suggested_mode | full / incremental / chunked — same heuristic as the YAML scaffold |
cursor_candidates[] | Ranked list with {column, data_type, is_nullable, is_primary_key, score, reasons[]}. Reasons use a stable snake_case vocabulary: name_suggests_updated, name_suggests_created, timestamp_type, integer_monotonic, primary_key, nullable |
suggested_cursor_fallback_column | Set when the top cursor is nullable and a NOT-NULL timestamp sibling exists — hint to enable incremental_cursor_mode: coalesce (ADR-0007) |
chunk_candidates[] | Ranked integer columns for chunked mode |
notes[] | Advisory strings surfaced to operators reviewing the artifact |
The artifact is advisory — same policy as plan prioritization (ADR-0006): no runtime effect, no auto-application.
Docker Compose in this repository
The repo root docker-compose.yaml defines Postgres and MySQL (rivet / rivet users, database rivet) with the same schema as dev/postgres/init.sql and dev/mysql/init.sql.
docker compose up -d postgres mysql
export PG_URL='postgresql://rivet:rivet@localhost:5432/rivet?sslmode=disable'
export MY_URL='mysql://rivet:rivet@localhost:3306/rivet'
# One table
rivet init --source "$PG_URL" --table orders -o rivet_orders.yaml
# Whole PostgreSQL schema public
rivet init --source "$PG_URL" --schema public -o rivet_public.yaml
# Whole MySQL database from URL
rivet init --source "$MY_URL" -o rivet_mysql.yaml
To refresh many files at once (per-table YAMLs plus combined schema snapshots), run python3 -m dev.pytools.dev_scripts regen-docker-configs from the repo root after the DBs are up (and optionally seeded).
Warehouse scaffold: --bigquery-project / --bigquery-dataset / --gcs-bucket
With the three flags together, the generated config carries the warehouse half of
the cycle — a top-level load: block (target: bigquery, pk: auto,
cluster_by: auto, cleanup_source: true), a per-table partition: guess (the
creation stamp — created_at / CreatedDate … — at granularity: day, never a
mutation stamp, which would move a row between partitions on every update) and,
for a mode that carries deltas (incremental, cdc), layout: base_buffer so
rivet compact has a base to merge into. Every value is a guess from the catalog:
review the block before the first load.
rivet init --source "$PG_URL" --table orders --mode incremental \
--gcs-bucket my-bucket --bigquery-project my-proj --bigquery-dataset my_ds -o rivet.yaml
rivet run -c rivet.yaml # Parquet → gs://my-bucket/exports/orders/
rivet load -c rivet.yaml # → the base on the first pass, the buffer on later ones
rivet compact -c rivet.yaml # MERGE the buffer into the base and drop it
--gcs-bucket is required with the BigQuery flags: rivet load reads GCS only, so a
load: block over a local or S3 destination is a config its own next step refuses.
For a whole-database CDC scaffold (one tables: stream with backfill: auto) the
partition guesses are written on the stream’s load.tables.<table> blocks — the
place the load reads them — not on the per-table recipes, which the load never reads.
Limitations
- Not a migration or DDL tool — only read-only introspection and YAML output.
- Views are included in schema-wide / database-wide runs; ensure each view is selectable for your user.
- Suggested modes are heuristics; large or sparse tables may need manual
chunked/chunk_by_key/chunk_by_daystuning (see chunked mode).
Tuning Reference
Tuning controls how Rivet queries the source database: batch sizes, timeouts, throttling, and retries.
MongoDB sources don’t use the SQL tuning on this page — a document store has no chunked mode or
chunk_size, thoughtuning.batch_size(per-batch row cap) andmax_batch_memory_mb(per-batch byte cap) ARE honored. Mongo’s tuning levers are the driver connection pool andparallel: N_id-range fan-out; see MongoDB → Connection pool & parallel tuning.
Where to place tuning
Tuning can be set at two levels:
- Global (
source.tuning) – applies to all exports - Per-export (
exports[].tuning) – overrides global for that export
Per-export values take precedence. Unset per-export fields fall back to the global value.
source:
type: postgres
url_env: DATABASE_URL
tuning:
profile: balanced # global default
batch_size: 10000
exports:
- name: small_table
query: "SELECT * FROM users"
format: parquet
destination: { type: local, path: ./out }
# inherits global tuning (balanced, batch_size=10000)
- name: huge_table
query: "SELECT * FROM events"
format: parquet
destination: { type: local, path: ./out }
tuning:
profile: safe # override for this export only
batch_size: 2000
Common mistake: placing
batch_sizedirectly undersource:or in the export root instead of undertuning:. Rivet will reject such configs with a clear error message.
Profiles
A profile sets sensible defaults for all tuning parameters. Individual fields override the profile.
| Parameter | fast | balanced (default) | safe |
|---|---|---|---|
batch_size | adaptive: 64 MB/flush¹ | adaptive: 32 MB/flush¹ | 2,000 (static) |
throttle_ms | 0 | 50 | 500 |
statement_timeout_s | 0 (none) | 300 | 120 |
max_retries | 1 | 3 | 10 |
retry_backoff_ms | 1,000 | 2,000 | 5,000 |
lock_timeout_s | 0 (none) | 30 | 10 |
memory_threshold_mb | 0 (none) | 4,096 | 2,048 |
¹ fast and balanced size the batch from memory, not a row count:
batch = target_mb / estimated_row_bytes, clamped to 1,000–150,000 rows. A
~320-byte row therefore batches at ~100k rows under balanced; a 4 KB row at
~8k. The static bases (50,000 / 10,000) apply only when the schema is not yet
known (e.g. plan before resolve) and as the advisory base in reports. An
explicit batch_size: disables adaptive sizing. Either way the batch is a
CLIENT-side fetch window — it never enters the source SQL (page size is
chunk_size), so a larger batch shortens cursor hold-time without adding
server work.
What stays open on the server while a chunk drains (per-engine hold
model): PostgreSQL reads through a server cursor — between FETCH N calls
nothing executes, but the snapshot transaction stays open (vacuum-horizon
cost); MySQL and SQL Server hold one streaming SELECT per chunk, drained
under socket flow control — the query stays visible (Sending data) for the
chunk’s drain duration and holds the MVCC read view. Consequence:
throttle_ms lowers burst IO but lengthens per-chunk hold time on
MySQL/MSSQL and the snapshot window on PostgreSQL. For hold-time-sensitive
primaries prefer fast in an off-peak window or a replica; reserve safe
throttling for replicas and IO-sensitive hosts. chunk_size bounds the
worst case held by any single query.
When to use each profile
| Profile | Use case |
|---|---|
| fast | Dedicated read replica, off-peak hours, small tables |
| balanced | General purpose, shared database, production reads |
| safe | Busy production database, OLTP systems, wide tables with large rows |
All tuning parameters
| Field | Type | Default | Description |
|---|---|---|---|
profile | fast | balanced | safe | balanced | Base profile (sets defaults for all other fields) |
batch_size | integer | profile default | Rows fetched per query batch. Explicit value disables the profile’s adaptive (memory-based) sizing — see footnote ¹ above |
batch_size_memory_mb | integer | — | Target memory per batch in MB (adaptive sizing; mutually exclusive with batch_size) |
throttle_ms | integer | profile default | Delay in ms between batches (reduces source load) |
statement_timeout_s | integer | profile default | Database statement timeout in seconds (0 = no timeout) |
max_retries | integer | profile default | Max retry attempts for transient errors |
retry_backoff_ms | integer | profile default | Base delay between retries in ms (exponential backoff) |
lock_timeout_s | integer | profile default | Database lock timeout in seconds (0 = no timeout) |
memory_threshold_mb | integer | profile default | RSS threshold in MB; pauses fetching if exceeded (0 = disabled). balanced defaults to 4096, safe to 2048, fast to 0 (no limit). |
max_batch_memory_mb | integer | — | Hard cap on a single Arrow batch in MB. When exceeded, on_batch_memory_exceeded determines the response. |
on_batch_memory_exceeded | warn | fail | auto_shrink | warn | Policy applied when a batch exceeds max_batch_memory_mb. |
max_value_mb | integer | 256 | Hard ceiling on a single cell (text/JSON/blob) in MB. A value larger than this aborts the run with RIVET_VALUE_TOO_LARGE. Guards against one giant cell OOM-ing the process — the batch cap is average-based and can’t bound a lone outlier. Set 0 to disable. See Per-value ceiling. |
adaptive | boolean | false | Sample source write-pressure at runtime and react: shrink/restore the fetch batch size, and — on a parallel > 1 chunked or keyset export — drive the concurrency governor (see that section for the exact per-runner coverage). |
min_parallel | integer | 1 | Floor for the concurrency governor: the fewest workers it will back down to under pressure. Ceiling is the export’s parallel. Only consulted when adaptive is on and parallel > 1. |
Batch memory cap (max_batch_memory_mb)
memory_threshold_mb is a process-level RSS guard — it fires after the OS has already committed memory. max_batch_memory_mb is an earlier, batch-level guard: it measures the actual Arrow buffer footprint of each batch before it is written.
tuning:
max_batch_memory_mb: 128
on_batch_memory_exceeded: warn # warn | fail | auto_shrink
| Policy | Behaviour |
|---|---|
warn | (default) Log a warning with the actual size, the limit, and a suggested batch_size. Continue the export. |
fail | Return an error immediately. The export stops. Use in strict pipelines where oversized batches indicate a configuration problem. |
auto_shrink | Split the oversized batch in half recursively until each sub-batch fits within the limit, then write the sub-batches individually. Transparent to the rest of the pipeline — total row count and output are identical. |
The warning and error messages include a suggested batch_size:
batch memory 184 MB exceeds max_batch_memory_mb=128 MB (5000 rows).
Consider lowering batch_size to ~3478.
Use auto_shrink when you want protection against accidental wide-table OOM without needing to tune batch_size manually. Use fail in CI pipelines where any oversized batch should block the run.
Per-value ceiling (max_value_mb)
max_batch_memory_mb and the adaptive byte budget are average-based — they size a batch from its mean row width. Neither bounds a single pathological cell: one 300 MB JSONB document or bytea blob among otherwise-small rows still lands whole in memory and can OOM the process (and the auto_shrink splitter can’t divide a single oversized value).
max_value_mb is a hard per-value ceiling. Before a batch is split or encoded, Rivet checks every variable-length cell (text / JSON / binary — fixed-width types can’t be individually huge); a value over the limit aborts the run:
RIVET_VALUE_TOO_LARGE: column 'body' has a single value of 301.2 MB, exceeding the
per-value ceiling of 256 MB. ...Raise `tuning.max_value_mb` (or set it to 0 to
disable the guard) if this value is expected.
It is on by default at 256 MB — high enough to never trip on realistic data, low enough to catch a runaway cell before it OOMs. Raise it for tables that legitimately store large blobs, or set max_value_mb: 0 to disable the guard entirely.
Choosing batch_size
batch_size is the most impactful parameter for both performance and memory usage.
| batch_size | Memory per batch (narrow table) | Memory per batch (wide table) | Best for |
|---|---|---|---|
| 1,000 | ~1-5 MB | ~20-100 MB | Wide tables, low-memory environments |
| 5,000 | ~5-25 MB | ~100-500 MB | Medium tables, shared databases |
| 10,000 | ~10-50 MB | ~200 MB - 1 GB | General purpose (default balanced) |
| 50,000 | ~50-250 MB | ~1-5 GB | Read replicas, fast profile |
For wide tables (50+ columns, TEXT/JSONB fields), start with batch_size: 1000-2000.
Adaptive batch sizing
Instead of a fixed row count, let Rivet adjust batch size based on memory:
tuning:
batch_size_memory_mb: 64 # target ~64 MB per batch
Rivet samples the first batch to estimate row size, then adjusts subsequent batches. Cannot be used together with batch_size.
Choosing chunk_size (and bounding statement duration)
chunk_size is a different lever from batch_size. batch_size is internal —
how many rows Rivet buffers in Arrow memory at a time (RSS only). chunk_size
is the unit of work and output: in chunked mode it is the size of one
WHERE key BETWEEN … (or keyset … LIMIT n) window, which is one SQL
statement and one output part file.
That makes chunk_size the knob for the longest single query the source
sees — the thing a DBA’s statement_timeout, long-running-query alert, or
lock-duration monitor reacts to. On a wide table, one chunk statement transfers
chunk_size × row_width bytes and stays active on the server for that whole
duration. Measured on MySQL content_items (wide ~4 KB rows; one chunk
statement, wall):
chunk_size | one chunk statement | output files (for 1 M rows) |
|---|---|---|
| 1,000 | ~0.4 s | 1,000 small files |
| 10,000 | ~0.6 s | 100 files |
| 100,000 (default) | ~3.4 s (≈9 s at ~12 KB rows) | 10 large files |
If a strict statement_timeout on the source trips your chunk queries, or you
want to keep each read short and gentle on a busy OLTP source, lower
chunk_size (e.g. chunk_size: 10000):
exports:
- name: orders
mode: chunked
chunk_column: id
chunk_size: 10000 # ~0.5 s per statement instead of ~3-9 s
The trade-off is more, smaller part files and a small (~25%) increase in total wall time (more index seeks / round-trips for the same rows). It is not a throughput win — it trades total speed and query count for shorter individual statements. Pick the point that fits your source’s tolerance.
PostgreSQL is unaffected: it streams each chunk through a server-side cursor (
DECLARE … FETCH N,Ncapped bywork_mem), so its per-statement work is already bounded regardless ofchunk_size. The lever above matters for MySQL / SQL Server, which run one statement per chunk.Why not give MySQL the same server-side cursor? Because its read-only cursor works differently: it materialises the whole result into temp tables when the cursor opens, then fetches cheaply — the open itself is the long statement, and it adds tempdb pressure. Measured directly with a
libmysqlclientprobe: cursor-open 0.8–1.8 s and 3 temp tables created, every run (dev/spikes/mysql_cursor_efficacy.c). So a MySQL cursor would be worse than just loweringchunk_size(short pages, no temp tables). Loweringchunk_sizeis the right lever; there is no free server-cursor shortcut on MySQL.
Adaptive concurrency governor
On an export with parallel > 1, setting adaptive: true arms a governor that adjusts how many workers (and therefore source connections) run concurrently, in response to source write-pressure. It backs parallelism down when the source is under load and recovers it when the load eases, staying within [min_parallel, parallel].
Which runners it covers, precisely — the governor is per-runner wiring, so this list is the contract, not an approximation:
| Runner | Governed? |
|---|---|
mode: chunked, parallel > 1 | yes — sheds at chunk granularity |
mode: chunked + chunk_checkpoint: true, parallel > 1 (the shape rivet init scaffolds) | yes — sheds at claimed-task granularity |
chunk_by_key (keyset), parallel > 1 | yes — sheds at page granularity |
MongoDB parallel: N (_id-range fan-out) | no — that runner has no shared permit ceiling to shrink. adaptive still drives Mongo’s batch-size adaptation; it does not vary worker count. |
Anything with parallel: 1 (or unset) | no — one worker has nothing to shed. |
source:
type: postgres
url_env: DATABASE_URL
tuning:
adaptive: true # arm batch-size adaptation + the governor
min_parallel: 2 # never drop below 2 workers (default 1)
exports:
- name: orders
table: public.orders
mode: chunked
chunk_column: id
parallel: 8 # ceiling — governor varies the live count in [2, 8]
format: parquet
destination: { type: local, path: ./out }
How it decides. A dedicated monitoring connection polls a source write-pressure counter every ~1.5 s and compares it to the previous reading. A rising counter means pressure is climbing, so the governor sheds one worker; a flat/falling counter lets it recover one. The counter is:
| Engine | Governor pressure proxy | Read via |
|---|---|---|
| PostgreSQL (< 17) | pg_stat_bgwriter.checkpoints_req | SELECT checkpoints_req FROM pg_stat_bgwriter |
| PostgreSQL (17+) | pg_stat_checkpointer.num_requested | SELECT num_requested FROM pg_stat_checkpointer |
| MySQL | global Innodb_log_waits | SHOW GLOBAL STATUS LIKE 'Innodb_log_waits' |
| SQL Server | Log Flush Waits/sec, cumulative cntr_value of the _Total row | SELECT cntr_value FROM sys.dm_os_performance_counters WHERE counter_name LIKE 'Log Flush Waits%' AND instance_name = '_Total' |
Two per-engine details worth knowing if you correlate rivet’s decisions with your own monitoring:
- PostgreSQL 17 moved the counter.
pg_stat_bgwriter.checkpoints_reqwas removed in PG 17 and lives on aspg_stat_checkpointer.num_requested. rivet picks the right one at runtime with an existence probe (SELECT to_regclass('pg_catalog.pg_stat_checkpointer') IS NOT NULL) rather than a singleCASEstatement, because PG plans the whole statement up front — a dead branch referencing the missing column still ERRORs, and that error would abort the export’s own cursor transaction. Each sample is preceded bypg_stat_clear_snapshot(). - SQL Server reads the
_Totalrow, it does not SUM. TheSQLServer:Databasesobject exposes one row per database plus a_Totalrow (verified live:_Totalequals the sum of the others), so aSUM(cntr_value)over all rows double-counts — and it shrinks when a database is dropped, which the governor would read as “pressure eased”. Use the_Total-filtered single-row read above if you want the series rivet actually sees.
The governor’s proxy is deliberately NOT the adaptive batch loop’s. On
MySQL the batch loop listens to own-extraction pressure (spill/temp
counters the export’s own reads inflate — shrinking the batch genuinely
shrinks the per-query spill); on PostgreSQL the batch loop shares
checkpoints_req with the governor; SQL Server’s batch loop currently has no
pressure sampling (batch adaptation is inert there). The governor asks a
different question — is someone ELSE
straining this server while I run? — so it listens to write/redo
counters a read-only export cannot move. Feeding it the batch loop’s spill
counters makes it read its own exhaust: a keyset export whose pages spill by
design would shed workers 4→3→2→1 and never recover (the counter keeps
rising as long as its own pages run) — measured on a production pool run as
every keyset export slowing 2–2.7×.
Required privileges (read-only is enough)
The governor needs no elevated privileges. A plain read-only role can run every query it issues — verified against PostgreSQL 16 and MySQL 8:
-
PostgreSQL — a role with only
CONNECT+USAGE ON SCHEMA+SELECT ON TABLEScan readpg_stat_bgwriter(< PG 17) orpg_stat_checkpointer(PG 17+), run theto_regclassprobe that chooses between them, and callpg_stat_clear_snapshot()— all are available toPUBLIC. Nopg_read_all_stats, no superuser.CREATE ROLE rivet_ro LOGIN PASSWORD '…'; GRANT CONNECT ON DATABASE mydb TO rivet_ro; GRANT USAGE ON SCHEMA public TO rivet_ro; GRANT SELECT ON ALL TABLES IN SCHEMA public TO rivet_ro; -
MySQL — a user with only
SELECTon the target schema can runSHOW GLOBAL STATUS; it needs noPROCESSor other global privilege.CREATE USER 'rivet_ro'@'%' IDENTIFIED BY '…'; GRANT SELECT ON mydb.* TO 'rivet_ro'@'%';
Graceful degradation — a transient miss holds flat, a dead signal fails OPEN. An unreadable pressure sample (locked-down role, unsupported engine view, a statement timeout on a busy catalog view) never fails the run. It degrades in two stages:
- Transient miss — fewer than 3 consecutive unreadable samples hold parallelism exactly where it is, and keep the last real reading as the baseline so the next successful sample is still compared against it.
- Signal lost — at 3 consecutive unreadable samples (~4.5 s at the default
1.5 s interval) the governor says so once for the episode — at
warnwhen a signal it had been reading died — and then steps parallelism back up one worker per tick until it reaches the export’sparallelceiling. A signal that cannot be READ is not evidence of pressure, so the governor fails open rather than leaving the run pinned at whatever level the last shed reached for the rest of its hours. If you need a hard cap while blind, lowerparallel(the ceiling) —min_parallelis a floor and does not bound the recovery.
A failed monitoring connection (as opposed to a failed sample) logs a warning
and disables the governor entirely for that run; parallelism then stays static
at parallel. Neither case aborts the export.
Note on richer signals. A future iteration may read lock waits /
idle in transactionfrompg_stat_activityorSHOW PROCESSLIST. Those do require elevated privileges (pg_read_all_statson PostgreSQL; thePROCESSprivilege on MySQL) to observe sessions other than your own. The current proxy was chosen specifically so the default least-privilege, read-only setup keeps working. When the richer signals land, this section will document the additional grants.
Visibility. Every adjustment is recorded in the run journal as a
ParallelismAdjusted event (from, to, reason). The log level is
asymmetric on purpose: a shed is a deliberate slowdown of your run, so it
must be visible at the default level (an info-level “this will be slower” is
functionally silent — a field pool run lost 1h48m to invisible sheds), while a
recovery is good news and stays quiet.
| Event | Level | Line |
|---|---|---|
| Governor armed | info | export 'orders': adaptive concurrency governor active (parallel 2..8) |
| Shed | warn | export 'orders': governor parallelism 8 → 7 (source pressure rising: backed off) — raise `min_parallel` to floor it, or set `adaptive: false` to disarm |
| Recovery | info | export 'orders': governor parallelism 7 → 8 (source pressure eased: recovered) |
| Armed but no signal at all (first probe) | warn | export 'orders': governor armed, but the source provides no pressure signal … — parallelism stays at 8 |
| Signal died mid-run (see above) | warn | export 'orders': governor lost its pressure signal … parallelism was pinned at 3 of 8; stepping back toward 8 … |
| Monitoring connection failed | warn | export 'orders': governor monitoring connection failed; parallelism stays static at 8: … |
The lines above are quoted to show the level and the shape; grep for
governor parallelism (adjustments) and governor (everything else) rather
than matching a full line, since the trailing hints get refined between
releases.
Write pipelining
For single/snapshot exports (mode: full), Rivet runs the fetch+convert
stage and the Parquet encode+compress stage on two threads with a small
bounded channel between them, so the database round-trip wait overlaps the
compression CPU. It is on by default, FIFO-ordered (byte-identical output),
and free — no measurable RSS penalty at the default depth, and the commit-
critical finalize still runs on the main thread.
- Disable it (old synchronous path):
RIVET_PIPELINE_WRITES=0. - Tune the channel depth (memory ↔ overlap):
RIVET_PIPELINE_WRITES=<n>.
The gain scales with how much real work compression does: on diverse data the encoder is busy and the overlap is worth it; on trivially-compressible data (near-zero zstd work) there is little to overlap. Chunked exports already run each chunk on its own worker and are not intra-chunk pipelined.
Memory optimization tips
- Reduce
batch_size– the single most effective knob - Use
safeprofile for wide tables on production databases - jemalloc is the default allocator – ordinary builds (
cargo build,cargo install rivet-cli) already include it (a default cargo feature), so its 20-40% RSS reduction is in effect out of the box; only a--no-default-featuresbuild loses it - Set
memory_threshold_mb– Rivet pauses fetching when RSS exceeds this
Examples
Minimal (use defaults)
source:
type: postgres
url_env: DATABASE_URL
# No tuning block → balanced profile with all defaults
Aggressive (read replica)
source:
type: postgres
url_env: REPLICA_URL
tuning:
profile: fast
batch_size: 100000
throttle_ms: 0
Conservative (production OLTP)
source:
type: postgres
url_env: DATABASE_URL
tuning:
profile: safe
batch_size: 1000
throttle_ms: 1000
statement_timeout_s: 60
memory_threshold_mb: 512
Capacity and memory planning
Peak RSS formula
peak_rss ≈ batch_size × avg_row_bytes × parallel_workers
+ Σ distinct destination.oneshot_budget_mb (64 MB when unset; cloud only)
The one-shot term is per rivet process: under parallel_export_processes each
child adds its own. Add ~50–150 MB overhead for the Tokio runtime, the source connection pool, jemalloc bookkeeping, and the OS page cache on the temp file.
Rule of thumb by table width
| Table type | Avg row bytes | Recommended batch_size | Expected peak RSS |
|---|---|---|---|
| Narrow (IDs, timestamps, small text) | ~100 B | 50 000–100 000 | ~50–200 MB |
| Medium (mixed text, JSON) | ~1 KB | 10 000–25 000 | ~50–250 MB |
| Wide (TEXT/JSONB payloads ≥ 10 KB avg) | ~10 KB | 500–2 000 | ~50–200 MB |
Use the safe profile for wide tables — it uses a conservative static
batch_size of 2 000 and the tightest throttle. For an explicit memory ceiling
regardless of profile, set batch_size_memory_mb (memory-driven sizing) or a
smaller batch_size directly.
How memory_threshold_mb works
When tuning.memory_threshold_mb is set, the chunked runners sample RSS at each chunk boundary (via mach_task_basic_info on macOS, /proc/self/statm on Linux). What happens above the threshold depends on the path: the parallel chunked runner (without checkpointing) holds the next chunk back, re-polling every 2 s until RSS falls back below the threshold; the sequential and checkpointed chunked paths pause once for a fixed 2–5 s and then proceed with the next chunk even if RSS is still above the threshold. There is no hysteresis band, and no per-batch check. Full, incremental, keyset, and mongo-parallel exports never pause on this knob; there RSS is only recorded for the peak-RSS metric. For a memory ceiling on those paths use batch_size_memory_mb / max_batch_memory_mb instead.
source:
tuning:
memory_threshold_mb: 1024 # pause fetching above 1 GB RSS
The RSS syscall costs ~1–2 ms, paid once per chunk. The guard is enabled by default on balanced (4096 MB) and safe (2048 MB) profiles; set memory_threshold_mb: 0 to disable it.
Parallelism and source capacity
Each parallel chunk worker opens its own source connection. Postgres max_connections is typically 100–200 for shared instances and 20–50 for read replicas. rivet check warns when parallel >= max_connections.
Safe upper bound: parallel ≤ max_connections / 4 to leave headroom for application traffic.
Per-export memory isolation
--parallel-export-processes spawns one OS process per export — each export has its own allocator and heap, so peak RSS is per-export rather than aggregate. Use this mode when running many wide-table exports at once on memory-constrained hosts.
Testing matrix
Rivet’s test suite is organised into two tiers, selected by the standard
#[ignore] convention. No test runner beyond cargo test is required.
Tiers
| Tier | Selection | Infrastructure required | What it covers |
|---|---|---|---|
| Offline | cargo test | none | Unit tests, pure-function property/fuzz smoke, state-layer contracts, format round-trip, CLI help snapshots, invariants I1–I7, F1–F5 crash-boundary F-matrix, validation regressions |
| Live | cargo test -- --ignored | docker compose up -d | Full rivet binary against real Postgres/MySQL/SQL Server/MongoDB, MinIO (S3), fake-gcs, Toxiproxy; Parquet round-trip E2E; type/trust golden DB → rivet → Parquet → Arrow read-back (postgres + mysql); cross-database parity; destination parity; resume; retry and mid-stream faults; schema drift; performance smoke; crash-point recovery matrix |
Both tiers run in CI (.github/workflows/ci.yml):
- Offline suite runs in the
test/test-invariants/test-recovery/test-compatibilityjobs on every push and PR. - Live suite runs in two dedicated jobs:
test-type-golden— starts only Postgres + MySQL, runs--test live_type_golden -- --ignored. Named branch-protection gate for type-contract regressions.e2e— full stack (Postgres, MySQL, SQL Server, MinIO, fake-gcs, Azurite, Toxiproxy, plus DuckDB/ClickHouse targets and thecdc/replica/poolcompose profiles); seeds databases, builds a debug binary (deliberately — the e2e layer checks correctness, not throughput; the release profile is exercised by the separate release-build job), runspython3 -m dev.pytools.e2e, then runs all remaining--ignoredtests except the MongoDB suites (live_mongo*/live_cdc_mongo), which run in the dedicated nightlymongo-versionsmatrix (4.4 → 8.0,nightly-live.yml).
Offline suite
Covers the full public API and every pure function in the crate. Runs in under two seconds on a developer laptop.
cargo test
# → example: cargo test: ~1360 passed, ~60 ignored (~32 suites, ~3s) — counts drift; check your local footer
Each integration file under tests/ maps to one domain:
| File | Domain | QA backlog task |
|---|---|---|
invariants.rs | ADR-0001 state invariants I1–I7 | – |
journal_invariants.rs | Journal event ordering and PlanSnapshot contract | – |
recovery.rs | F1–F5 crash-boundary state expectations | – |
state_compat.rs | Corrupted DB handling + cross-version migration | Task 1.3, 1.4 |
schema_evolution.rs | Schema drift detection algorithm | – |
chunked_sparse_ids.rs | Sparse-ID chunk planner edge cases | – |
retry_integration.rs | classify_error classifier table | Task 4.3 |
format_golden.rs | CSV + Parquet writer goldens including extreme values | Task 2.4 |
format_fuzz.rs | Deterministic fuzz-smoke for format serialization | Task 4A.3 |
validate_regression.rs | Validate-output contract (row count, empty, corrupt) | Task 2.1 |
config_fuzz.rs | YAML + placeholder fuzz-smoke | Task 4A.1 |
config_secrets.rs | Error-message secret-redaction contract | Task 5.4 |
planner_fuzz.rs | SQL-shaping and planner fuzz-smoke | Task 4A.2 |
cli_contract.rs | --help structure and exit-code contract | Task 5.3 |
run_summary_contract.rs | Structured RunSummary and journal contract | Task 8.1 |
time_window.rs | Time-window SQL builder goldens | – |
resource_smoke.rs | RSS sampler, memory threshold module | – |
Inline #[cfg(test)] mod tests blocks in src/ cover pure-function unit
tests (config parsing, chunk math, cursor round-trip, format writers,
destination capabilities, Slack payload formation) and benefit from
pub(crate) access. cargo test --all-targets runs them automatically.
Live suite
Runs the full pipeline against the docker-compose stack. Every test carries
#[ignore = "live: ..."] so the default offline run ignores them; invoking
with --ignored activates them. If any service is unreachable, live tests
fail with an actionable message naming the missing container and port
(require_alive helper in tests/common/mod.rs).
docker compose up -d
cargo test -- --ignored
# → counts vary (~50+ ignored live tests). Check the cargo footer after `cargo test -- --ignored`.
| File | Domain | QA backlog task |
|---|---|---|
live_harness_canary.rs | Reachability probe for every service (Postgres primary + via Toxiproxy, MySQL primary + via Toxiproxy, MinIO, fake-gcs, Toxiproxy admin); harness sanity (PgTable/MysqlTable RAII guards, unique_name no-collision, CARGO_BIN_EXE_rivet visibility) | Phase A |
type_roundtrip (make test-types / make test-types-live) | 0.18.0 type matrix: offline YAML contracts + live PG/MySQL × Parquet/CSV | docs/type-mapping.md |
live_type_golden.rs | Trust & reproducibility: paired Postgres and MySQL golden pipelines | Trust milestone §1 (“Golden E2E for type safety”); complements live_parquet_roundtrip.rs |
live_parquet_roundtrip.rs | Postgres → rivet → Parquet → reader; schema/row-count/nullability/unicode/empty-dataset contracts; --validate flag | Task 2.2 |
live_cross_db_parity.rs | Same dataset via Postgres vs MySQL under full and chunked modes; row-count and id-set equivalence | Task 3.3 |
live_destination_parity.rs | Local vs S3 (MinIO) vs GCS (fake-gcs); per-backend file materialisation + parity row-count | Task 6.3 |
live_resume.rs | Full-mode file accumulation across runs; incremental cursor round-trip; --resume gate message | Task 1.2 |
live_retry_and_faults.rs | Baseline via Toxiproxy; latency toxic tolerated; proxy disable → clean non-zero exit; mid-stream proxy disable/enable → recovery via retries; permanent-error short-circuit | Task 4.1, 4.2 |
live_chaos.rs | High-latency false-positive guard; chunked export survives mid-stream outage; S3 missing bucket fails cleanly; S3 recovery after transient-outage simulation | Task 4A.4, 6.2 |
live_schema_drift.rs | Added column / removed column / stable schema — detection flag in export_metrics.schema_changed | Task 7.1, 7.2 |
live_performance_smoke.rs | 5 000-row + 200B payload finishes within 30 s; split-by-size produces multiple files with no row loss; parallel-4 chunked export materialises every id exactly once | Task 9.1, 9.2 |
live_crash_recovery.rs | Four fault points (after_source_read, after_file_write, after_manifest_update, after_cursor_commit) × expected post-crash state × recovery run | Task 1.1 |
live_mongo*.rs | MongoDB batch (JSON-blob _id + document): distinct-_id set vs source, verbatim document round-trip, crash recovery, retry/faults, permission-harm | – |
live_mssql_*.rs | SQL Server batch: chunked (range + keyset), resume, crash recovery, reconcile/repair — twins of the Postgres/MySQL suites | – |
live_cdc*.rs | CDC capture/resume for all five engines (live_cdc.rs, live_cdc_mongo.rs, live_cdc_mssql.rs, live_cdc_oracledb.rs, plus golden/oracle/property/MBT) — at-least-once, no gap/dup | – |
Trust milestone: type golden round-trip
tests/live_type_golden.rs implements the roadmap contract database → Rivet (rivet run) → Parquet → Arrow read-back → exact assertions so type handling stays provable end-to-end, not only in unit tests (format_golden.rs covers writers in isolation).
Each test targets both engines where the contract applies:
| Scenario | Postgres | MySQL |
|---|---|---|
Decimal exact sums + Decimal128(p,s) in Parquet | NUMERIC(18,2/6), YAML columns: decimal(...) | DECIMAL(18,2/6), same YAML overrides |
Timestamp semantics (tz=None vs UTC tag + µs parity) | TIMESTAMP / TIMESTAMPTZ with offset row | DATETIME(6) / TIMESTAMP(6) (Rivet sets SET time_zone = '+00:00' on the MySQL session) |
| Binary round-trip | BYTEA | BLOB (avoid reserved identifiers like blob as column SQL names) |
Canonical UUID-ish text (Utf8) | native UUID | VARCHAR(36) with hyphenated lowercase literal |
INTERVAL → ISO 8601 Utf8 | INTERVAL '1 year 2 months 3 days' → "P1Y2M3D", INTERVAL '-1 year' → "P-1Y", INTERVAL '0' → "PT0S" | — (no MySQL INTERVAL type) |
CI runs these in the dedicated test-type-golden job (cargo test --test live_type_golden -- --ignored) as well as in the full e2e job. Local:
docker compose up -d
cargo test --test live_type_golden -- --ignored
Not yet in this matrix (future roadmap items): JSON logical metadata parity, unsupported-type strict failures, classified schema-drift variants as dedicated goldens (live_schema_drift.rs already covers drift telemetry for Postgres).
Test-only fault injection
A small env-var-driven hook in src/test_hook.rs lets the crash-matrix tests
panic at precise pipeline boundaries without any cargo feature flag:
RIVET_TEST_PANIC_AT=after_file_write rivet run --config ... --export ...
# → process panics between dest.write() and record_file()
Valid point names are listed in src/pipeline/single.rs inline comments;
see also dev/CRASH_MATRIX.md and ADR-0001.
Cost when the env var is unset: one relaxed atomic load per call, roughly
a nanosecond.
Live-test harness (tests/common/mod.rs)
| Helper | Purpose |
|---|---|
require_alive(service) | Fast reachability probe; clear message if the service is down |
unique_name(prefix) | PID + atomic counter → race-free table / export / prefix names for parallel test-threads |
pg_connect / seed_pg_numeric_table / PgTable | Postgres client + seeded table + RAII DROP TABLE on scope exit |
mysql_connect / seed_mysql_numeric_table / MysqlTable | MySQL analogue |
write_config / run_rivet / run_rivet_export | Spawn the freshly-built rivet binary (CARGO_BIN_EXE_rivet) with a temp YAML config |
ensure_toxi_proxy / toxi_add_latency / toxi_disable / toxi_enable / toxi_reset_toxics | Minimal Toxiproxy admin client over raw TcpStream (no reqwest blocking runtime) |
toxiproxy_guard | Cross-process flock(2) lock on $TMPDIR/rivet_qa_toxiproxy.lock — serialises Toxiproxy mutations across cargo’s parallel integration test binaries |
ensure_minio_bucket / ensure_gcs_bucket | Idempotent bucket creation via docker compose exec minio mc and fake-gcs HTTP API |
files_with_extension | Enumerate files produced by rivet under a test’s tempdir |
Running from scratch
# Offline (default — used by PR-gate jobs):
cargo test
# Live (requires docker compose):
docker compose up -d
cargo test -- --ignored
docker compose down
Both command lines are what the corresponding CI jobs execute. If your
cargo test diverges from the CI matrix, something is out of sync —
check .github/workflows/ci.yml for the exact invocation.
Shell regression matrices
Binary-level regression guards under dev/matrices/
complement the Rust integration tests above. They drive the release rivet
binary through fixture scenarios and diff stdout/stderr/exit codes, file
layouts, EXPLAIN plans, and perf thresholds against committed baselines.
python3 -m dev.pytools.matrix_common setup-links # one-time
python3 -m dev.pytools.matrices --tier=pr # cli + cfg + path (PR CI)
See dev/matrices/README.md for the full taxonomy
and tier map.
QA / roadmap alignment
Task IDs in tables above are historical QA labels. Trust & reproducibility
(golden DB → Rivet → Parquet → Arrow read-back, Postgres and MySQL) lives in
tests/live_type_golden.rs and is described
above. Strategic tracking: rivet_roadmap.md §Phase 1
(Epic 14 / execution status).
CDC conformance gate
tests/cdc_conformance_gate.rs runs in plain cargo test and enforces two
hard rules over the live CDC suite’s SOURCES:
- Every engine × every conformance case (resume, idle-first-run,
crash-before-ack, full type matrix, update/delete, initial snapshot,
vanished anchor, mixed-transaction boundary, schema-qualified routing,
non-UTC session, …) must have a live test — or an explicit
NA("reason")in the matrix. A new engine cannot merge with a coverage hole; a new case must decide for all engines. Motivation: per-engine coverage drifts silently, and each engine’s missing case is exactly where a real bug lived (mixed-transaction existed only for MySQL, qualified-name only for PostgreSQL — ultrareview found the two matching bugs). - Every live CDC test that runs a capture must read back an outcome (manifest rows, a batch comparison, a destination listing, the state DB) — a bare exit-0 assertion would wave a 0-row silent success through, which is how three of the campaign’s worst bugs hid.
Mutation testing (nightly)
mutants-nightly in nightly-live.yml runs cargo-mutants on a rotating
tier group per night (day-of-year modulo the group count: ledger/pipeline,
CDC/value/integrity, planning/formats/gates, …) against the offline suite,
and passes/fails on the diff against docs/mutants-baseline.txt — a NEW
missed mutant fails the job; known misses live in the baseline and only ever
shrink. A surviving mutant is a named test blind spot — the meta-gate that
finds holes in the gates above.
Config-key composition gate (per PR)
config-key-composition in ci.yml diffs schemas/rivet.schema.json against
the PR base: a NEW config key must be named by at least one test. The
campaign’s worst bugs lived at the intersection of two individually-correct
knobs (initial × vanished-slot, initial × skip_empty) — a new knob
enters review with its interaction tests or not at all.
CDC gremlins (real faults)
tests/live/gremlin_cdc.rs (+ the capture-job stall in live_cdc_mssql.rs)
injects REAL fault classes — SIGKILL, a TCP cut mid-binlog-stream, a hard
destination outage, a failed checkpoint write, a stalled capture job — and
asserts the at-least-once contract from the outside: the failure is loud, and
after healing the union of all parts holds every source row (overlap fine,
gap never). Panic-hook tests cannot cover these: a panic unwinds and runs
Drop guards; none of the above do. Requires toxiproxy + fake-gcs from the
compose stack; each case is a row in the conformance matrix.
Known-equivalent mutants (decimal canon)
The six surviving mutants in src/types/decimal.rs are all < → <= on
branch guards where BOTH branches compute identical values at the boundary
(e.g. scale < 0 vs scale <= 0: at scale 0 the negative-scale arm divides
by 10⁰ = 1 — the same result as the plain path; frac.len() < scale vs <=:
at equality the pad loop pads zero characters). They are mathematically
unkillable; do not write pseudo-tests for them. Everything else in the file
is caught (92) or timeouts-as-caught (4).
Architecture
How Rivet extracts data end-to-end: the pipeline, the traits that make it pluggable, the memory model, and the source tree layout.
This is a reference document. If you only want to configure or run an export, start with getting-started.md.
Data flow
Every export, regardless of mode, follows the same streaming shape:
Source (PostgreSQL / MySQL / SQL Server / MongoDB)
│
├─ begin_query / DECLARE CURSOR
│
├─ FETCH batch_size rows ─► Arrow RecordBatch ─► FormatWriter ─► temp file
│ │ │ │
│ │ sleep(throttle_ms) │ (dropped after │ flush per batch
│ │ │ hand-off) │
│ │ │ │
├─ FETCH next batch ──────► Arrow RecordBatch ─► FormatWriter ─► temp file
│ ... ... ...
│
├─ close_query / COMMIT
│
└─ Destination.write(temp_file) ─► local / S3 / GCS / Azure / stdout
No batch accumulates in memory beyond the current FETCH. Parquet
writers flush after each batch. The destination upload happens once per
output file at the end of the writer’s lifetime.
For the exact sequence of state-store updates that surrounds this pipeline (manifest, cursor, metrics, progression), see ADR-0001 — State update invariants and ADR-0008 — Committed / verified progression.
Key traits
The pipeline is composed of four traits. Adding a new database engine, output format, or destination means implementing exactly one of them.
#![allow(unused)]
fn main() {
// Read-only inputs for a single export call. Packs the parameters that
// used to live as 5 positional args on Source::export into a named struct.
pub struct ExportRequest<'a> {
pub query: &'a str,
pub catalog_hint_query: Option<&'a str>, // unwrapped base query for catalog-dependent type hints
pub incremental: Option<&'a IncrementalCursorPlan>,
pub cursor: Option<&'a CursorState>,
pub tuning: &'a SourceTuning,
pub column_overrides: &'a ColumnOverrides,
pub page_limit: Option<usize>, // keyset (seek) page size
pub base_relation: Option<&'a str>, // ADR-0027 read-relation seam
pub upper_bound: Option<&'a str>, // parallel-keyset inclusive range cap
}
// Source pushes data through a sink callback. `Send` not `Sync`
// — see ADR-0011.
pub trait Source: Send {
fn export(&mut self, request: &ExportRequest<'_>, sink: &mut dyn BatchSink) -> Result<()>;
fn query_scalar(&mut self, sql: &str) -> Result<Option<String>>;
// Returns column type mappings via a LIMIT-0 probe query (used by `rivet check --type-report`).
fn type_mappings(
&mut self,
query: &str,
column_overrides: &ColumnOverrides,
) -> Result<Vec<TypeMapping>>;
}
// Sink receives schema and batches one at a time.
pub trait BatchSink {
fn on_schema(&mut self, schema: SchemaRef) -> Result<()>;
fn on_batch(&mut self, batch: &RecordBatch) -> Result<()>;
}
// Format writer streams output incrementally.
pub trait FormatWriter {
fn write_batch(&mut self, batch: &RecordBatch) -> Result<()>;
fn finish(self: Box<Self>) -> Result<()>;
fn bytes_written(&self) -> u64; // for max_file_size splitting
}
pub trait Format {
fn create_writer(
&self,
schema: &SchemaRef,
writer: Box<dyn Write + Send>,
) -> Result<Box<dyn FormatWriter>>;
fn file_extension(&self) -> &str;
}
}Implementations:
| Trait | Concrete types |
|---|---|
Source | PostgresSource (DECLARE CURSOR + FETCH N), MysqlSource (exec_iter, binary protocol), MssqlSource (tiberius; OFFSET … FETCH NEXT), MongoSource (JSON-blob: _id + document) |
Format | CsvFormat, ParquetFormat |
FormatWriter | CsvFormatWriter (hand-rolled escaping over Box<dyn Write>), ParquetFormatWriter (arrow ArrowWriter) |
Destination | LocalDestination, StdoutDestination, CloudDestination<B: CloudBackend> (OpenDAL) with backends S3Backend, GcsBackend, AzureBackend |
Change-data capture seam
Batch export is one shape; log-based change-data capture (mode: cdc, and
the rivet cdc command) is the other. It has its own pluggable seam, parallel
to Source: the ChangeStream trait in src/source/cdc/mod.rs.
#![allow(unused)]
fn main() {
// A blocking pull of canonical changes. `None` ⇒ no more changes right now.
pub(crate) trait ChangeStream {
fn next_change(&mut self) -> Option<Result<ChangeEvent>>;
// Acknowledge that every change up to `position` is durably persisted.
// Consume-on-read engines (PostgreSQL slot advance) defer the real consume
// here so a crash before a durable write re-reads (at-least-once).
fn ack(&mut self, _position: &Position) -> Result<()> { Ok(()) }
}
}All four engines implement it — PgChangeStream (logical replication slot),
MysqlChangeStream (binlog), MssqlChangeStream (change tables / from-LSN),
MongoChangeStream (change stream, requires a replica set). The factory
create_change_stream dispatches by engine exactly as create_source does for
the batch path. Each adapter yields a canonical ChangeEvent (op, schema,
table, before/after image, resume position); the CDC sink writes the
after-image typed, prefixed with the meta columns __op / __pos / __seq
(__seq is the total intra-transaction change order for correct current-state
dedup). Resume is per-engine — PostgreSQL slot, MySQL binlog checkpoint file,
SQL Server from-LSN, MongoDB resume token — and each is at-least-once.
Memory model
Peak in-flight Arrow memory per export:
peak ≈ batch_size * avg_row_size * parallel_threads
Real process RSS is higher because of database connection pools, the
Tokio runtime used by destinations, jemalloc overhead, and the OS page
cache on the temp file. For wide tables (TEXT / JSONB payloads), keep
batch_size low and prefer the safe profile; for narrow tables on a
read replica, fast with a larger batch_size extracts faster at
higher peak RSS.
- Full guidance: reference/tuning.md.
- Optional runtime guard: set
tuning.memory_threshold_mbto pause fetching / chunk dispatch above a chosen RSS.
The resource module implements the RSS sampler — macOS uses
mach_task_basic_info; Linux uses /proc/self/statm.
Connection pooler / proxy detection
Rivet relies on a number of session-scoped primitives at connect time:
Postgres SET LOCAL statement_timeout, MySQL SET SESSION max_execution_time, SET time_zone = '+00:00', server-side cursors
(DECLARE CURSOR), and per-statement diagnostics like
pg_backend_pid() and CONNECTION_ID(). Transaction-mode poolers
(pgBouncer, ProxySQL with default settings) hand each statement to a
different backend connection — silently making those primitives
ineffective.
So the SQL drivers (PostgreSQL, MySQL, SQL Server) detect the wire-level shape of the connection at open time and warn once when it is a pooler / proxy / gateway, rather than letting the operator find out later through an inexplicably long-running query or session-state leak:
-
Postgres —
detect_pg_transaction_poolerinsrc/source/postgres/mod.rscomparespg_backend_pid()across two consecutive queries. Different PIDs imply transaction-mode pooling (pgBouncer, Odyssey). The warning explicitly names what does not work:SET LOCALis transaction-scoped, advisory locks /LISTENare unavailable. -
MySQL —
classify_mysql_proxyinsrc/source/mysql/proxy.rsis a pure classifier over four signals, in this precedence order:PROXYSQL INTERNAL SESSIONaccepted as a query (strongest — ProxySQL intercepts this on its client port; vanilla MySQL returns a syntax error).@@version_commentbanner containsproxysqlormaxscale.@@proxy_versionis set (ProxySQL-only system variable).CONNECTION_ID()differs across two consecutive queries on the sameConn(generic transaction-mode multiplexing — catches HAProxy MySQL mode, in-house balancers, ProxySQL/MaxScale that hide their banner).
The classifier yields
MysqlProxyKind { Direct, ProxySql, MaxScale, Multiplexed }. The non-Directvariants log a one-time warning describing the specific risk (session-state non-persistence, query rewriting, etc.). -
SQL Server —
classify_mssql_proxyinsrc/source/mssql/proxy.rsis a pure classifier over the same shape, in precedence order:@@SPIDdiffers across two consecutive queries →Multiplexed(statement-level connection multiplexing — the session-scoped primitives do not persist).SERVERPROPERTY('EngineEdition')of5(Azure SQL DB) or8(Managed Instance), or an Azure@@VERSIONbanner →AzureGateway(the connection may be redirected through the gateway).
It yields
MssqlProxyKind { Direct, Multiplexed, AzureGateway }; the non-Directvariants log a one-time warning as above.
This detection is best-effort and intentionally never fails an export —
it gives the operator one observable line in the logs. The session
cleanup code (RAII PgTxnGuard on Postgres; explicit SET resets on
MySQL) runs unconditionally because the same code is correct against
both direct and proxied backends; the warning is about behavioural
side-effects (timeouts, locks, NOTIFY) that the cleanup cannot recover.
Coverage: 18 unit tests on classify_mysql_proxy exhaustively cover
the signal precedence; tests/live/live_pool_safety.rs runs the full
session-leak suite against pgBouncer (transaction mode, pool_size=1)
and ProxySQL (transaction-persistent pool) under the pool
docker-compose profile. See docs/reliability-matrix.md § Pool and load
pressure.
Project structure
src/
main.rs Thin entry: env_logger init → cli::Cli::parse → cli::dispatch
lib.rs Public modules for integration tests + rivet-mcp binary
enrich.rs Meta columns (_rivet_exported_at, _rivet_row_hash via xxh3_128)
error.rs Result type alias
journal.rs RunJournal / RunEvent / JournalEntry / PlanSnapshot (top-level
so state/journal_store does not have to import from pipeline)
mcp.rs Stdio JSON-RPC server (read-only PG/MySQL/pgBouncer diagnostics);
wrapped by the dedicated bin/rivet-mcp.rs binary
notify.rs Slack webhook notifications
quality.rs Data quality checks (row count, null ratio, uniqueness)
resource.rs RSS sampling (macOS + Linux)
sql.rs Identifier quoting + cursor escaping (CC9 / CC10)
test_hook.rs Test-only fault injection (see reference/testing.md)
cli/ Clap surface, validation, dispatch (split from a 1000-line main.rs)
mod.rs Re-exports Cli + dispatch
args.rs Clap derive types (Cli, Commands, StateAction, *Format) — pure grammar
validate.rs Cross-flag invariants that clap cannot express
params.rs --param KEY=VALUE parsing + --source/--source-env/--source-file resolution
dispatch.rs match Commands → pipeline / init / preflight entry points
config/ YAML parsing, validation, env/file resolution
mod.rs, source.rs, export.rs, destination.rs, format.rs, schema.rs,
lints.rs, notifications.rs, resolve.rs, cursor.rs, tests/
tuning/ Tuning profiles + memory model (split from a single 678-line file)
mod.rs Re-exports the externally-used names
profile.rs SourceTuning + TuningConfig + TuningProfile + BatchMemoryPolicy
memory.rs estimate_row_bytes + compute_batch_size_from_memory
adaptive.rs ADAPTIVE_SAMPLE_INTERVAL + next_adaptive_batch_size feedback loop
source/ Database drivers, query shaping, pooler detection, CDC
mod.rs Source / BatchSink traits; ExportRequest; TableIntrospection;
create_source factory; warn_if_tls_disabled
batch_controller.rs Shared batch-loop driver (fetch → sink → throttle) across engines
postgres/ DECLARE CURSOR + FETCH N; PgTxnGuard (RAII); detect_pg_transaction_pooler
mod.rs, arrow_convert.rs, from_parse.rs, cdc.rs (PgChangeStream — logical slot)
mysql/ exec_iter (binary protocol); MysqlProxyKind (Direct/ProxySql/MaxScale/Multiplexed)
mod.rs, arrow_convert.rs, proxy.rs (classify_mysql_proxy), cdc.rs (MysqlChangeStream — binlog)
mssql/ tiberius OFFSET/FETCH + keyset; MssqlProxyKind (Direct/Multiplexed/AzureGateway)
mod.rs, arrow_convert.rs, proxy.rs (classify_mssql_proxy), cdc.rs (MssqlChangeStream — change tables)
mongo/ JSON-blob model (_id + document); keyset / parallel / resume; full + cdc only
mod.rs, cdc.rs (MongoChangeStream — change stream, replica set)
cdc/ Engine-neutral CDC seam
mod.rs ChangeStream trait + ChangeEvent + create_change_stream factory
sink.rs Typed after-image sink (__op / __pos / __seq meta columns)
validate.rs, value.rs Descent validation + canonical RivetValue → JSON rendering
pg_numeric_wire.rs NUMERIC wire-format decoding (preserves precision through subquery wrap)
query.rs build_incremental_query (dialect-specific WHERE/ORDER BY injection)
tls.rs Postgres native-tls connector builder (verify-full / verify-ca / require)
value_checksum.rs Per-value integrity checksum (decoded-value → file)
format/ Streaming writers
mod.rs, csv.rs, parquet.rs
destination/ Output backends
mod.rs, local.rs, s3.rs, gcs.rs, gcs_auth.rs, azure.rs, stdout.rs
pipeline/ Orchestration — the actual export work
mod.rs, cli.rs Pipeline entry points called by cli::dispatch
single.rs Single-export full / incremental loop (BEGIN → DECLARE → FETCH → COMMIT)
job.rs Chunked-quality-gate wiring + per-job journal hand-off
retry.rs classify_error → RetryClass {Permanent | Transient {needs_reconnect, extra_delay_ms}}
summary.rs RunSummary builder + per-export aggregate
aggregate.rs Multi-export run aggregate (--parallel-exports, --json output)
parallel_children.rs --parallel-export-processes orchestrator (subprocess fan-out)
parent_ui.rs Multi-progress UI for parallel runs
ipc.rs Parent ↔ child JSON line protocol (the child side is a plain
`rivet run` subprocess gated on RIVET_IPC_EVENTS=1; it emits
ChildEvent JSON lines on stdout, read in parallel_children.rs)
progress.rs Indicatif progress bars (ChunkProgress, single-export progress)
validate.rs --validate output verification (row count, schema)
sink/ ExportSink (writer + temp file lifecycle); cursor.rs sink-cursor helper
chunked/ Chunked engine
mod.rs run_chunked_*; sequential and parallel checkpoint loops
detect.rs auto-resolve chunk_column from PK; chunk_sparsity_from_counts
exec.rs Per-chunk SQL build + retry classification per worker
math.rs Range-splitting, dense-ordinal math, by-days windowing
plan_cmd.rs, apply_cmd.rs Plan generation + sealed apply
reconcile_cmd.rs, repair_cmd.rs Reconcile / targeted repair (ADR-0009)
plan/ Plan artifacts + source-aware prioritization
mod.rs, artifact.rs, build.rs, contract.rs, inputs.rs, recommend.rs,
prioritization.rs, campaign.rs, history.rs, reconcile.rs, repair.rs, validate.rs
types/ Canonical type system (roadmap §14 / M1–M6)
mod.rs Re-exports: RivetType, TypeMapping, TypeFidelity, ColumnOverrides
rivet_type.rs RivetType enum (Bool, Int*, Float*, Decimal, Date, Time, Timestamp,
String, Text, Binary, Json, Uuid, Enum, Interval, List{inner}, Unsupported)
mapping.rs TypeMapping struct: source_native_type → RivetType → Arrow DataType + fidelity
fidelity.rs TypeFidelity (Exact / Compatible / LogicalString / Lossy / Unsupported)
policy.rs TypePolicy (Fail/Warn/Allow per fidelity); PolicyViolation; `--strict` gate
target.rs ExportTarget (DuckDB / BigQuery / Snowflake / ClickHouse); TargetCompat (Ok/Warn/Fail); per-target type mapping
decimal.rs NUMERIC / DECIMAL precision+scale resolution
override_type.rs `exports[].columns:` per-column type overrides
source_column.rs SourceColumn (driver-neutral column metadata)
cursor.rs CursorState (last_cursor_value + type tag)
preflight/ EXPLAIN analysis, verdicts, doctor, type reports
mod.rs, analysis.rs, postgres.rs, mysql.rs, doctor.rs, cursor_expr.rs
type_report.rs `rivet check --type-report`: collects TypeMappings, applies TypePolicy,
checks ExportTarget compat, renders table or NDJSON
state/ Backend-pluggable state store (schema v4+): SQLite by default
(.rivet_state.db beside the config); PostgreSQL when RIVET_STATE_URL
is set (StateConn::Sqlite | Postgres), for stateless/replicated deployments
mod.rs StateStore facade; transaction management
cursor.rs export_state.last_cursor_value (incremental cursor persistence)
file_log.rs file_log (per-export file ledger; renamed from file_manifest in v8)
metrics.rs export_metrics history (CLI: `rivet metrics`)
checkpoint.rs chunk_run / chunk_task tables (chunked checkpoint state machine)
progression.rs export_progression (committed / verified boundaries — ADR-0008)
journal_store.rs Persist RunJournal entries (linked to run_id)
shape.rs export_shape + shape_drift_warn_factor
run_aggregate.rs Cross-export aggregate persistence
schema.rs Schema migrations v1 → v4+
init/ `rivet init` scaffolding + discovery artifact
mod.rs, artifact.rs, candidates.rs, postgres.rs, mysql.rs, yaml_scaffold.rs
bin/
rivet-mcp.rs Dedicated MCP stdio binary (Claude Desktop / Claude Code integration)
seed/ Test data generator (dev fixture): main.rs, args.rs, insert.rs,
fast.rs, copy_pg.rs, mssql.rs
tests/ Offline (cargo test) + live (cargo test -- --ignored)
dev/ docker-compose fixtures, seed SQL, e2e harness
dev/proxysql/proxysql.cnf — backend config for the `pool` profile
docs/ User-facing documentation (this tree)
The shape of this tree is mostly stable — feature work usually extends
an existing module. Earlier moves (v0.5.3 → v0.6.0) reduced the
number of multi-purpose files: tuning.rs (678 LoC) → tuning/ (4
files), cli/mod.rs (~1000 LoC) → cli/ (4 files), journal.rs
moved from pipeline/ to a top-level crate module, and mcp.rs now
ships as a separate rivet-mcp binary rather than a rivet mcp
subcommand. The source/ tree since grew from two flat driver files
(postgres.rs, mysql.rs) into a per-engine directory each with its
own arrow_convert.rs and cdc.rs, plus SQL Server (mssql/),
MongoDB (mongo/), and the engine-neutral cdc/ seam.
Where to read next
- reference/cli.md — every command and flag.
- reference/config.md — every YAML field.
- reference/testing.md — offline + live test tiers.
- adr/ — binding contracts (state invariants, plan/apply, cursor policy, progression, reconcile / repair).
Reliability Matrix
What Rivet actually tests, where, and how often. This is the operational answer to “is this path covered or am I about to find out the hard way?”
The matrix is derived from the workflows in .github/workflows/ and the test suites under tests/. It is updated when a coverage tier changes — not on every test addition.
Coverage tiers
| Tier | What runs | Trigger | Wall time budget |
|---|---|---|---|
| PR CI | unit + integration + named semantic gates + e2e (incl. PG / MySQL / SQL Server CDC) + type-golden against live PG / MySQL / SQL Server | every push and PR to main | ~10 min |
| Nightly | full live suite incl. content_load against ~60k-row fixture; pgBouncer profile; MongoDB version matrix (4.4 → 8.0, batch + CDC) | 03:30 UTC cron + manual dispatch | up to 60 min |
| Manual | 1M-row stress, full legacy DB matrix (PG 12–15, MySQL 5.7), wide-table memory benchmarks | operator-invoked from dev/ scripts | varies |
PR CI defines branch protection — the named gates (fmt, clippy, test — whose invariant / recovery / compatibility / type-contract / stability / generated-docs steps each fail under their own name — and e2e, whose type-golden / type-validator / differential / PR-matrix steps do the same on one set of containers) block merges on regression.
Core extraction paths
| Area | PR CI | Nightly | Manual | Suite |
|---|---|---|---|---|
| PostgreSQL — full export | ✅ | ✅ | ✅ | live_destination_parity, e2e |
| PostgreSQL — incremental (cursor) | ✅ | ✅ | ✅ | live_resume, live_cli_flags |
| PostgreSQL — chunked | ✅ | ✅ | ✅ | live_chunked_recovery, live_reconcile_repair |
| PostgreSQL — time_window | ✅ | ✅ | — | time_window, live_cli_flags |
| MySQL — full export | ✅ | ✅ | partial | live_destination_parity, e2e |
| MySQL — incremental (cursor) | ✅ | ✅ | partial | live_resume |
| MySQL — chunked | ✅ | ✅ | partial | live_chunked_recovery |
| MySQL — time_window | ✅ | ✅ | — | time_window |
| SQL Server — full export | ✅ | ✅ | ✅ | live_mssql_resume (full), live_mssql_crash_recovery |
| SQL Server — incremental (cursor) | ✅ | ✅ | ✅ | live_mssql_resume, live_mssql_crash_recovery |
| SQL Server — chunked (range + keyset/seek) | ✅ | ✅ | ✅ | live_mssql_chunked, live_mssql_chunked_recovery |
| MongoDB — full snapshot (batch) | — | ✅ | — | live_mongo, live_mongo_crash_recovery (nightly mongo-versions 4.4→8.0) |
| MongoDB — keyset / parallel / resume | — | ✅ | — | live_mongo (JSON-blob model; mode: full only) |
| CDC — PostgreSQL (logical replication slot) | ✅ | ✅ | — | live_cdc (PG cases) |
| CDC — MySQL (binlog) | ✅ | ✅ | — | live_cdc (MySQL cases) |
| CDC — SQL Server (change tables / from-LSN) | ✅ | ✅ | — | live_cdc_mssql |
| CDC — MongoDB (change stream, replica set) | — | ✅ | — | live_cdc_mongo (nightly mongo-versions) |
| CDC engine conformance gate (per-engine × case) | ✅ gate | ✅ | — | cdc_conformance_gate (offline; fails on missing engine/case) |
| Cross-DB parity (PG ↔ MySQL same query) | ✅ | ✅ | — | live_cross_db_parity |
Failure-mode coverage
| Scenario | PR CI | Nightly | Manual | Suite |
|---|---|---|---|---|
| State invariants (ADR-0001 I1–I7) | ✅ gate | ✅ | — | invariants |
| Journal event ordering | ✅ gate | ✅ | — | journal_invariants |
| Chunk checkpoint resume (I5, I6) | ✅ gate | ✅ | — | recovery |
| Crash and resume (live DB, Postgres) | ✅ | ✅ | ✅ | live_crash_recovery |
| Crash and resume (live DB, MySQL) | ✅ | ✅ | — | live_mysql_crash_recovery (parallel matrix to the PG suite) |
| Crash and resume (live DB, SQL Server) | ✅ | ✅ | — | live_mssql_crash_recovery (4 crash-point twins to the PG suite) |
| Chunked checkpoint resume (live DB, MySQL) | ✅ | ✅ | — | live_mysql_chunked_recovery (C1–C4 twins) |
| Chunked checkpoint resume (live DB, SQL Server) | ✅ | ✅ | — | live_mssql_chunked_recovery (C1–C4 twins, incl. parallel) |
| Resume across modes (live DB, MySQL) | ✅ | ✅ | — | live_mysql_resume (full / incremental / chunked –resume validation) |
| Resume across modes (live DB, SQL Server) | ✅ | ✅ | — | live_mssql_resume (full / incremental / chunked –resume validation) |
| Schema drift (live DB, MySQL) | ✅ | ✅ | — | live_mysql_schema_drift (added / removed / stable matrix) |
| Retry + Toxiproxy faults (live DB, MySQL) | ✅ | ✅ | — | live_mysql_retry_and_faults (baseline / latency / disabled / mid-stream / permanent) |
| Reconcile + targeted repair (live DB, MySQL) | ✅ | ✅ | — | live_mysql_reconcile_repair (RR1–RR6 twins) |
| Reconcile + targeted repair (live DB, SQL Server) | ✅ | ✅ | — | live_mssql_reconcile_repair (reconcile/repair twins) |
| Retry classification under injected faults | ✅ | ✅ | — | live_retry_and_faults, retry_integration |
| Toxiproxy-driven network chaos | ✅ | ✅ | — | live_chaos |
| Schema drift between runs | ✅ | ✅ | — | live_schema_drift, schema_evolution |
| Reconcile + repair flow | ✅ | ✅ | — | live_reconcile_repair |
| Plan/apply contract (ADR-0005) | ✅ | ✅ | — | live_plan_apply, validate_regression |
| State-DB schema compatibility (v1 → v4 migrations) | ✅ | ✅ | — | state_compat |
| Config fuzz + planner fuzz | ✅ | ✅ | — | config_fuzz, planner_fuzz |
| Secret redaction in errors / artifacts | ✅ | ✅ | — | config_secrets |
| Gremlin (concurrent state mutation) | ✅ | ✅ | — | gremlin |
Destination coverage
| Backend | PR CI | Nightly | Manual | Notes |
|---|---|---|---|---|
| Local filesystem | ✅ | ✅ | ✅ | Default for unit + e2e |
| S3 (MinIO container) | ✅ | ✅ | partial | live_destination_parity |
| GCS (fake-gcs container) | ✅ | ✅ | partial | live_destination_parity |
| Azure Blob Storage | ✅ | ✅ | ✅ | Added 0.7.1; live-verified against a real Azure account on 2026-05-21. SAS token auth added 0.7.2. CI runs the live_azure_multipart suite against an Azurite emulator (PR CI + nightly); real-account endpoints remain manual smoke. |
| stdout | ✅ | ✅ | — | Constrained — rejects chunked + max_file_size |
Per-backend commit contracts: ADR-0004. Production credentials for real S3 / GCS / Azure endpoints are not exercised in CI.
Pool and load pressure
| Scenario | PR CI | Nightly | Manual | Notes |
|---|---|---|---|---|
| pgBouncer (transaction mode, pool_size=1) | ✅ | ✅ | ✅ | live_pool_safety — F1–F6 / G1 DBA-audit fixes |
| ProxySQL (MySQL transaction-persistent pool) | — | ✅ | ✅ | live_pool_safety::mysql_proxysql_* — detection + cleanup-through-proxy |
| MySQL proxy / multiplexer classification (unit) | ✅ | ✅ | — | source::mysql::tests::proxy_* — pure classifier over the 4 signals |
| SQL Server pooler / Azure-gateway classification (unit) | ✅ | ✅ | — | source::mssql::proxy::tests::* — pure classifier (@@SPID drift → Multiplexed, EngineEdition 5/8 → AzureGateway) |
| SQL Server direct-connection classification (live) | ✅ | ✅ | — | live_pool_safety::mssql_direct_connection_classified_as_direct (false-positive guard) |
| Parallel chunk checkpoint recovery (panic + resume) | ✅ | ✅ | — | live_chunked_recovery::parallel_chunked_* (C3 / C4) |
| OLTP load on source during export | partial | ✅ | ✅ | live_oltp_load |
| ~60k-row content extraction under update pressure | — | ✅ | ✅ | live_content_load (nightly only — minutes to seed) |
| 1M-row full extraction under load | — | — | ✅ | pg_full_content_export_max_pressure (skipped in nightly; 3–5 min runtime) |
| Performance smoke (throughput regression) | partial | ✅ | ✅ | live_performance_smoke |
Type system coverage
| Area | PR CI | Nightly | Manual | Notes |
|---|---|---|---|---|
| Per-type golden round-trip (PG + MySQL) | ✅ gate | ✅ | — | live_type_golden — runs in dedicated test-type-golden job with live DBs |
| Per-type round-trip via oracle (SQL Server) | ✅ gate | ✅ | — | type_roundtrip::{duckdb,clickhouse}_validates_mssql_type_matrix_parquet — test-type-validators job (DuckDB + ClickHouse readers) |
| Parquet round-trip | ✅ | ✅ | — | live_parquet_roundtrip, format_golden, format_fuzz |
| Format writer (CSV + Parquet, row-group golden) | ✅ gate | ✅ | — | format_golden, the Tests job’s stability step |
| Type policy + ExportTarget compat (BigQuery) | ✅ | ✅ | — | covered in live_cli_flags --type-report |
Database version coverage
| Engine | Version | PR CI | Manual | Notes |
|---|---|---|---|---|
| PostgreSQL | 16 | ✅ | ✅ | Primary target |
| PostgreSQL | 12, 13, 14, 15 | — | ✅ | python3 -m dev.pytools.legacy_stand full-matrix, opt-in compose profile |
| MySQL | 8.0 | ✅ | ✅ | Primary target |
| MySQL | 5.7 | — | ✅ | python3 -m dev.pytools.legacy_stand full-matrix — known view-syntax gap in init.sql, see reference/compatibility.md |
| SQL Server | 2022 | ✅ | ✅ | Primary target; test-type-validators (type matrix) + e2e (live_mssql_* recovery/resume/reconcile) jobs |
| MongoDB | 7.0 | — | ✅ | Primary target; nightly mongo-versions matrix (dispatchable) |
| MongoDB | 4.4, 5.0, 6.0, 8.0 | — | ✅ | Nightly mongo-versions matrix (batch + CDC); CDC capability tiers — 4.4/5.0 current-state, 6.0+ full pre-images |
Each legacy target runs the full 83-assertion e2e suite when selected. Status table in reference/compatibility.md.
Shell regression matrices (dev/matrices/)
Five harnesses that drive the release binary against docker fixtures and
diff captured artifacts against committed baselines. Each one is bound to a
specific CI tier; the orchestrator at python3 -m dev.pytools.matrices --tier=<tier>
runs the right set per gate.
| Matrix | Layer | What it pins | Tier | Trigger |
|---|---|---|---|---|
cli | Surface | CLI exit codes (88) + 36 stderr/stdout substring assertions per scenario | PR (mandatory) | every push |
cfg | Surface | 83 YAML × 3 probes (doctor/check/plan) + 17 message substrings | PR (mandatory) | every push |
path | Execution | 7 scenarios × on-disk layout snapshot + summary.json row/file accounting | PR (mandatory) | every push |
query | Execution | 5 representative queries × PG EXPLAIN (COSTS OFF) plan shape | Nightly | 03:30 UTC cron |
soak | Resources | 3 modes × 10k-row PG × per-scenario duration_ms/peak_rss_mb thresholds | Nightly | 03:30 UTC cron |
cross_version | Compatibility | doctor/check/plan rc agreement across PG 12–16 + MySQL 5.7/8.0 | Release | before tag |
legacy | Compatibility | Full e2e (83 assertions) per DB version | Manual | operator-invoked |
Branch-protection guarantees: the PR row must stay green to merge — the
runs as a step of the e2e job in .github/workflows/ci.yml.
Nightly matrices run from .github/workflows/nightly-live.yml;
a red nightly emails the on-call. Release matrices run as part of the
release checklist; the artifact is the matrix log in
docs/release-checklist.md § Cross-version smoke.
Manual matrices are operator-invoked from dev/.
Operational tooling
| Area | PR CI | Nightly | Manual | Suite |
|---|---|---|---|---|
| CLI flag contract (no silent flag drift) | ✅ | ✅ | — | cli_contract, live_cli_flags |
rivet init scaffolding | ✅ | ✅ | — | live_init, live_init_extended |
rivet doctor preflight | ✅ | ✅ | — | covered in live_cli_flags |
| Run-summary JSON contract | ✅ | ✅ | — | run_summary_contract |
| MCP server contract | ✅ | — | — | mcp_contract |
| Quality gates (row-count, null-ratio, uniqueness) | ✅ | ✅ | — | quality_live, the Tests job’s stability step |
| Resource sampler (RSS) | ✅ | ✅ | — | resource_smoke |
Batch memory policy (auto_shrink / warn / fail) | ✅ | ✅ | — | batch_memory_policy |
Supply chain
| Control | PR CI | Notes |
|---|---|---|
| RustSec advisory audit | ✅ | audit job — fails on any known CVE in declared deps |
| Rustfmt | ✅ gate | fmt |
Clippy (-D warnings) | ✅ gate | clippy |
Release-artifact signing and checksums are roadmap (see SECURITY.md § Supply chain).
What is not in CI
These remain operator-driven:
- Real S3 / GCS / Azure production endpoints with real IAM / RBAC. CI uses MinIO and fake-gcs containers; the real-cloud path (incl. Azure Blob Storage end-to-end) is exercised manually before each release. The manual matrix and last-verified dates live in docs/cloud-smoke-tests.md; the release process gates on it via docs/release-checklist.md § Cloud smoke.
- Cross-platform binaries. Release builds run on the matrix in .github/workflows/release.yml; the per-PR
build-releasejob only builds for Linux x86_64. - Long-horizon soak tests (24h+ continuous extraction). Not run; planned for future hardware.
- Real production-shape datasets beyond the 60k content_items fixture and operator-seeded fixtures from
dev/.
If your environment depends on any of the above, run the corresponding scripts under dev/ before adopting Rivet.
Manual / release-gated coverage
Coverage that lives outside automated tiers but is gated on the release checklist.
| Area | How verified | Last verified |
|---|---|---|
| Real S3 destination (env keys, session token, profile) | Manual smoke per cloud-smoke-tests.md | 2026-05-22 |
| Real GCS destination (ADC, service account JSON) | Manual smoke per cloud-smoke-tests.md | 2026-05-22 |
| Real Azure Blob destination (account key + SAS token) | Manual smoke per cloud-smoke-tests.md | 2026-05-22 |
| Cross-platform release binaries (macOS arm64/Intel, Linux arm64) | .github/workflows/release.yml matrix on tag push | per-release |
Updating this matrix
When you add or remove a coverage tier:
- Edit the relevant row(s) here.
- If you add a new semantic gate, also list it in the branch-protection comment at the top of .github/workflows/ci.yml.
- Note the change in
CHANGELOG.mdunder a### Reliability matrixsub-section.
Cross-tool, cross-engine benchmark
How rivet compares to six other extraction tools — duckdb, clickhouse-local,
sling, ingestr, dlt, odbc2parquet — reading Postgres / MySQL / SQL Server
/ MongoDB → Parquet on the same fixture, and how to reproduce it.
One source of truth, one runner, one report:
| File | Role |
|---|---|
matrix.yaml | the SINGLE source — metric catalog, tool set + versions + steelman configs, seed sizes, per-engine harm metrics |
../../dev/bench/smoke.py | the runner — reads matrix.yaml, runs each tool, prints three matrices; guards against metric drift |
report.html | the rendered headline report (open in a browser) |
What it measures — three matrices, one run per tool
- Benchmark — wall, rows/s, peak RSS, output MB, output files, type-drift count.
- Harm to the source — the point of the bench. Universal axes (a co-running
OLTP p99 probe, longest query / txn, held locks, connections, cache footprint,
source CPU) plus each engine’s native counters (pg
pg_stat_database, mysqlSHOW GLOBAL STATUS+data_locks, mssql DMVs, mongoserverStatus). - Type fidelity — every source column vs each tool’s Parquet type family (jsonb→text, naive-ts→timestamptz, bool→int drift). N/A for MongoDB (JSON-blob).
Headline
rivet wins peak memory (15–60× lower — it streams via a server-side cursor,
never buffering the result set) and type fidelity (0 drift on every engine,
while also checksumming every value). It is not the throughput leader —
ingestr and clickhouse beat its rows/s, and the report says so. Full numbers and
the honest tradeoffs are in report.html.
Engine coverage: Postgres (8 tools) · MySQL (8) · SQL Server (6 — duckdb/clickhouse have no native reader) · MongoDB (3 — rivet/sling/ingestr only).
Reproducing
Prereqs — docker compose up -d (the project’s postgres/mysql/mssql/mongo
containers), then run with the system python (it has PyYAML + dlt; the homebrew
pythons ship a broken pyexpat):
# postgres, one table, all tools:
/usr/bin/python3 dev/bench/smoke.py --engine postgres --table content_items
# another engine / table:
/usr/bin/python3 dev/bench/smoke.py --engine mysql --table content_items
/usr/bin/python3 dev/bench/smoke.py --engine mssql --table orders
/usr/bin/python3 dev/bench/smoke.py --engine mongo --table content_items --tools rivet,ingestr,sling
Fixtures are seeded into a dedicated rivet_bench database per engine so
the live-test rivet fixtures are never touched. Seed via the Rust tool
(cargo run --release --bin seed --features dev-seed -- --target <engine> \ --mssql-url/--mysql-url ...); sizes live in matrix.yaml’s seed: block. MongoDB
is seeded via the mongo driver.
Per-tool drivers (documented in each tool’s matrix.yaml note): odbc2parquet
needs a vendor ODBC driver per engine (psqlodbc / MariaDB Unicode / msodbcsql18);
dlt needs psycopg2 / pymysql / pyodbc; clickhouse’s mysql() needs 127.0.0.1
(not localhost); the rivet MongoDB source needs the worktree build (RIVET_BIN
prefers target/release/rivet).
Notes on fidelity of the numbers
- The OLTP p99 probe is cleanest on Postgres (server-side
\timing). On mysql/mssql it is a per-querydocker exec, whose ~230 ms overhead compresses the signal toward 1×; on MongoDB it is skipped (mongosh cold-start). Read the harm story primarily from longq / memory / native counters on non-PG engines. - Steelman applied to everyone — each tool runs its lowest-memory config that still completes; memory caps flatter competitors (lower RSS), and a self-audit removed a stray clickhouse thread cap. rivet’s numbers include its always-on per-value checksum (~7%) that no competitor performs.
- SQL Server heavy NVARCHAR(MAX) is ~130× slower to stream over TDS for all
tools (a protocol characteristic, not rivet) — the mssql matrix runs on
orders.
MongoDB CDC and a folded-in CDC-churn dimension (cdc_churn.sql) are tracked for
a future revision.
Rivet v0.5.x Benchmark Report
⚠️ HISTORICAL — archived. These numbers are from v0.5.0 (2026-05-15), pre-dating the streaming read path that changed every RSS/throughput figure in the newer reports. Retained only as the pattern for config-tuning reports and as the cited evidence behind older best-practices claims. Pending a 0.18 re-measure — do not quote these figures as current.
Measured on: 2026-05-15
Binary: target/release/rivet (v0.5.0)
Host: macOS Darwin 25.4.0, Apple Silicon
Database: PostgreSQL 16 (local docker-compose)
§4.3 Compression Profiles
Dataset: bench_narrow — 500,000 rows, 5 numeric/timestamp columns, avg ~40 B/row
| Profile | Codec | Wall (s) | User (s) | RSS (MB) | Output (MB) |
|---|---|---|---|---|---|
none | uncompressed | 0.93 | 0.11 | 46.4 | 13 |
fast | Snappy | 0.92 | 0.11 | 49.5 | 10 |
balanced | Zstd-3 | 0.94 | 0.14 | 50.2 | 5 |
compact | Zstd-9 | 1.04 | 0.28 | 82.2 | 5 |
Key findings:
balanced(Zstd-3) compresses 2.6× better thannonewith identical wall time and only 4 MB more RSS. This is the recommended production default.fast(Snappy) is slightly faster thanbalancedbut produces 2× larger files. Use for large backfills where storage cost is secondary.compact(Zstd-9) offers no additional compression benefit overbalancedon numeric data, while using 64% more memory and 2× more CPU. Only use when storage/network cost dominates.- Wall time is dominated by source query and Parquet serialization, not compression. All profiles are within 12% of each other.
§4.4 Row Group Targets
Dataset: bench_wide — 100,000 rows, 10 TEXT columns, 200 chars each (~2 KB/row)
| Target | Row group strategy | Wall (s) | RSS (MB) | Output (MB) |
|---|---|---|---|---|
| 32 MB | auto | 2.26 | 75.9 | 1 |
| 64 MB | auto | 2.25 | 79.5 | 1 |
| 128 MB | auto | 2.26 | 82.7 | 1 |
| 256 MB | auto | 2.25 | 82.3 | 1 |
Key findings:
- Smaller row group targets reduce peak RSS with no wall-time penalty — latency is identical across all targets.
32 MBtarget saves ~7 MB RSS vs256 MBon bench_wide (2 KB rows). On wider tables the difference is larger — see the content_items benchmark in low-memory-runners.md where it contributes to a 5.7× RSS reduction.autostrategy chooses row count dynamically from Arrow schema widths. Users don’t need to tune a row count — they specify a memory budget and the writer adapts.- Output size is identical across targets (compression ratio is not affected by row group boundaries).
§4.5 Batch Memory Policies
Dataset: bench_wide — 100,000 rows, 10 TEXT columns, 200 chars each (~2 KB/row)
Cap: 64 MB, batch_size: 10,000 (estimated batch ~20 MB — cap does not trigger on this dataset)
| Policy | Wall (s) | RSS (MB) | Output (MB) |
|---|---|---|---|
warn (cap=64 MB) | 2.25 | 82.2 | 1 |
auto_shrink (cap=64 MB) | 2.26 | 81.1 | 1 |
| no cap (warn, 4 GB) | 2.26 | 83.7 | 1 |
Key findings:
- When batches stay under the cap,
warnandauto_shrinkadd zero measurable overhead vs no cap. The policy check is a single memory comparison per batch. - All three policies produce identical output and identical wall time, confirming no correctness regression from the cap mechanism.
- On bench_wide at
batch_size: 10,000, each batch is ~20 MB in Arrow — below the 64 MB cap. To observe RSS reduction fromauto_shrink, use wider tables or larger batch sizes.
Content_items reference (200,000 rows, avg ~3 KB/row, 12 columns including TEXT/JSONB):
| Config | batch_size | Peak RSS | Wall (s) |
|---|---|---|---|
No cap (batch_size: 25,000) | 25,000 | 878 MB | 17.2 |
Safe baseline (max_batch_memory_mb: 64) | ~2,000 | 154 MB | 16.6 |
Tight (batch_size: 500, cap 32 MB) | 500 | 111 MB | 16.3 |
The 5.7× RSS reduction holds for wide real-world tables. See low-memory-runners.md for the full methodology.
§4.6 Quality Uniqueness
Dataset: bench_hc — 200,000 rows, UUID + email columns (high cardinality)
| Config | Wall (s) | RSS (MB) | Output (MB) |
|---|---|---|---|
unique_max_entries: 50,000 (capped) | 1.54 | 41.0 | 5 |
| no cap (200,000 unique values tracked) | 1.54 | 41.8 | 5 |
Key findings:
- At 200,000 rows, uncapped uniqueness tracking adds only ~0.8 MB RSS above the capped baseline. xxHash3-64 stores u64 hashes (8 bytes), so 200K × 2 columns × 8 bytes = ~3.2 MB of hash sets — negligible against total process RSS.
- Wall time is identical: hash-based tracking is O(1) per row.
unique_max_entriesis still recommended for high-cardinality tables as a defensive cap, not because the overhead is large. Without it, a runaway uniqueness tracking on a billion-row table could grow to hundreds of MB.- The hash-based approach (xxHash3-64, typed) is a quality signal, not an exact distinct count.
Summary
| Claim | Evidence |
|---|---|
balanced compression: same speed as none, 2.6× smaller files | §4.3 ✓ |
compact adds no compression benefit over balanced on numeric data | §4.3 ✓ |
| Smaller row group targets reduce RSS with zero wall-time cost | §4.4 ✓ |
| Memory policies add zero overhead when cap doesn’t trigger | §4.5 ✓ |
auto_shrink reduces RSS 5.7× on wide real-world tables | §4.5 content_items ✓ |
| xxHash3-64 uniqueness tracking overhead is < 1 MB on 200K rows | §4.6 ✓ |
unique_max_entries cap recommended as defensive limit | §4.6 ✓ |
Mutation-testing plan — proving the tests can go RED
The coverage matrices certify that a test EXISTS for every claimed behaviour; the drift-guard certifies coverage never silently regresses. Neither can certify that a test’s assertions are ADEQUATE — the 2026-07 audit found 60+ green tests that could never fail against the exact bug they guard (stale sleeps, self-oracles, wrong artifacts). The missing third factor of trust is measured empirically: mutate the product, and the suite must go RED.
trust = coverage-exists (guard) × assertions-adequate (mutants) × runs-in-CI (audit)
Tool: cargo-mutants (>= 27). A “missed” mutant = a code change no test
notices — either a test gap, an accepted non-oracle (operator UX), or an
equivalent mutant. Every missed mutant gets exactly one of those three
verdicts; an untriaged baseline is a landfill, not a ledger.
Tiers (risk × oracle × cycle cost)
| Tier | Surface | Files | Test cycle | Cadence |
|---|---|---|---|---|
| 0 | Manifest/ledger chain | manifest.rs, pipeline/manifest_writer.rs, pipeline/manifest_reconcile.rs, pipeline/finalize.rs, pipeline/single.rs, pipeline/keyset.rs, pipeline/resume_decisions.rs, source/cdc/sink.rs | --lib (~20-30s/mutant) | pilot done; nightly |
| 1 | Value conversion (silent cell corruption) | source/{postgres,mysql,mssql}/arrow_convert.rs, source/cdc/value.rs, types/target.rs, types/decimal.rs | --lib | nightly rotation |
| 2 | State / checkpoint / integrity | state.rs, pipeline/chunked/resume_m8.rs, pipeline/validate_manifest.rs, source/value_checksum.rs, source/{postgres,mysql,mssql}/cdc.rs | --lib | nightly rotation |
| 3 | Orchestration (offline-blind — pilot proved lib tests cannot see it) | pipeline/single.rs, pipeline/keyset.rs, pipeline/chunked/exec.rs, pipeline/cdc_job.rs, pipeline/mongo_parallel.rs | live (--test live_suite -- --ignored <narrow filter>, minutes/mutant) | weekly, one module per run, devbox |
| 4 | Destination commit protocol | destination/local.rs (+ cloud via minio/fake-gcs) | --lib + live | weekly rotation |
Narrow live filters for Tier 3 (mutate X → run only its guards):
single.rs → live_resume live_crash_recovery; keyset.rs → live_keyset;
cdc_job.rs/sink.rs → the CDC suites; chunked/exec.rs → live_chunked_recovery.
Three enforcement loops
-
PR gate —
cargo mutants --in-diff(minutes). Mutates only the lines the PR changed,--lib --binscycle. A NEW missed mutant in your own diff fails the check. Cheapest and fairest: everyone pays only for their own code.Since 2026-08-21 the in-diff mutants are prioritised before they are budgeted (
.github/scripts/mutants_classify.py, wired into themutants-planjob).cargo llvm-cov --lib --binsmeasures which functions the offline suite actually EXECUTES, and each mutant lands in one of two classes:- graded — its line is inside an executed function. A test ran that code and did not notice the change: an assertion gap, and the gate’s red.
- reported — its line is inside a function measured at ZERO executions.
No offline assertion can kill it; it is a triage question
(
.cargo/mutants.tomlwith a live-oracle proof, or a unit oracle that moves the function into the graded class).
This is what makes the gate useful on a big diff: the budget guard now tests the GRADED subset, so a foundational PR that used to be graded by nothing gets its offline-reachable mutants graded. Two properties keep the split from becoming an excuse — everything the measurement does not KNOW (no report, an unmentioned file, an unparseable name) stays in the graded class, and whenever the budget stretches to it the reported class is RUN as an audit: if the offline suite catches one of them, the classification was wrong and
Mutants (coverage verdict)fails. A file some source reads as text (include_str!) always stays graded: a test that greps it kills a stub without executing it, which coverage cannot see.The graded set runs in up to eight
Mutants (shard N)jobs (about ten mutants each) (--shard k/N, dependencies reused through--copy-target);Mutants (changed lines)grades their outcomes as one run, and the P2 audit rides in that same run rather than paying a second build. -
Nightly (devbox self-hosted runner). Full
--libruns over Tier 0-2 in rotation (~500-1000 mutants/night). Result diffed against the committed baseline (docs/mutants-baseline.txt): any missed mutant NOT in the baseline fails the job. The baseline only shrinks (gap-ratchet discipline). -
Weekly (devbox). One Tier-3 module against its narrow live filter.
Why mutants survive — the degenerate-fixture rule
Survivors come from two causes, and the second is the one worth naming because the code LOOKS covered. Of 64 closed on 2026-08-02:
- 62 had no test at all —
parse_time_str_to_micros, theValue::Timearm ofRivetValue::from_mysql,pg_interval_to_iso8601,pg_type_to_rivet. Pure functions reachable only through a live export, so the--libcycle never touched them.src/source/postgres/arrow_convert.rs— 1059 lines — had no#[cfg(test)]module whatsoever. - 2 had EIGHT tests that could not SEE the mutation, because the fixture sat exactly where the mutated operators AGREE:
rescale_i128 (mssql decimals) had EIGHT unit tests and still lost both of its
scale-arithmetic mutants — every test used from_scale = 0 or equal scales, and
at zero to_scale - from_scale and to_scale + from_scale compute the same
factor. The suite could not distinguish the operators it existed to protect.
So: choose values such that no two operators produce the same result.
| component | degenerate fixture | working fixture | why |
|---|---|---|---|
h * 3600 | h = 0 | h = 2 | at 0 every operator yields 0 |
m * 60 | m = 0 or m = 1 | m = 4 | 4*60 = 240 vs 4+60 = 64 vs 4/60 = 0 |
6 - us_digits | a 6-digit fraction | 1 digit | at 6 the exponent is 0 and - == + |
months / 12 | months = 12 | months = 25 | 25/12 = 2, 25%12 = 1, 25*12 = 300 — all differ |
to_scale - from | from_scale = 0 | 1 -> 3 and 3 -> 1 | at 0 the difference equals the sum |
The same shape appears without arithmetic. A match arm deleted from a type map
drops that type to the _ fallback — a SILENT schema change — so each arm needs
its own row in a table test: remove one, exactly one row fails and names the
type. Two traps inside that:
- arms that produce the same variant.
TIMESTAMPandTIMESTAMPTZboth map toTimestampand differ only in the timezone field; asserting the variant would let the arms be swapped, losing the UTC semantics. Assert the FIELD. - arms whose value is a diagnostic. Bare
NUMERICisUnsupportedon purpose (the wire protocol carries no atttypmod), so the oracle is the REASON text — it must still name the column-override escape, or the operator is told “unsupported” with nowhere to go.
One pure function, one test
Do not write a test per mutant. A single well-chosen fixture kills a whole
function’s arithmetic, measured four times in a row on 2026-08-02:
parse_time_str_to_micros 13/13, RivetValue::from_mysql 10/10,
pg_interval_to_iso8601 11/11, pg_type_to_rivet 12/12 — zero survivors each.
Count kills by MEASURING, never by reasoning
Apply the mutant, run the test, watch it fail; only then delete the baseline line. Reading a test cannot tell you whether it bites — twice on 2026-08-02 a test that looked exhaustive did not, and the second one had been WRITTEN to close that exact mutant.
Verify “live-guarded” instead of believing it
The baseline explains its adapter entries as caught by the live suites rather
than the --lib cycle, and nothing tested that claim, because mutation runs use
--lib only. Test it per group with one representative: inverting the MySQL
boolean coercion in build_array (*v != 0 -> *v == 0) DOES fail the live
subset (live_init::init_mysql_schema_wide_discovers_seeded_table). For that
class the claim holds — as a measurement now, not an assurance.
The harness’s own thermometer (2026-08-21)
Every loop above measures the PRODUCT. Nothing measured the harness, so a guard
could rot for months with every signal a reader has still reading green — three
did (see tests/offline/nonvacuity.rs). The harness-metrics job in ci.yml now
emits one JSON per run (.github/scripts/harness_metrics.py, uploaded as the
harness-metrics artifact, one-line summary in the job log):
- mutants — in scope, excluded by
.cargo/mutants.toml, graded, and the classifier’s offline-reachable / live-only split, plus caught / missed. - guards — convention-cop guards (a
#[test]file grading a checked-in subject by NAME), how many prove that subject is non-empty, how many tests are named..._documents_...(documentation, not verification), how many files declare a blind spot in prose. - tests — DECLARED
#[test]counts for the offline suite and the lib (the job runs no cargo; it counts attributes, so the number differs from a runner’s tally by whatever iscfg-gated out).
It is a THERMOMETER: no threshold, no needs: from any job, continue-on-error
on top of if: always(). A metric with teeth becomes a number people manage
(pad the cop count; rename a test _documents_ to duck a red). An unknown count
is published as null, never 0 — “the mutation job never ran” and “nothing
was missed” must not draw the same line. tests/offline/harness_metrics_guard.rs
grades the shaping from a fixture of counts and keeps the job non-blocking.
Triage verdicts
- add-test — write the unit test that kills it (e.g. the pilot’s
set_column_checksums/set_cursor_range/part-id-max+1 finds, closed inmanifest_writer.rstests). The killing test must itself be RED-proven: apply the mutant, watch the new test fail, revert. - accept — real behaviour but not a data oracle (operator-UX stderr hints,
log lines). Excluded in
.cargo/mutants.tomlwith a reason comment. - equivalent — semantically identical mutation (e.g. the 64*1024 stream
buffer size in
compute_part_checksums: any chunking yields the same digest). Excluded with a reason.
Disk hygiene (learned the expensive way)
Each -j N run keeps N private tree copies with their own target/ — ~10 GB
each with default debuginfo, and target/incremental GROWS over hundreds of
mutants. A killed run leaks its copies (a killed tier run left a 26 GB orphan
in $TMPDIR/cargo-mutants-rivet-*.tmp). Rules for every runner:
export CARGO_PROFILE_DEV_DEBUG=0— mutants never need debuginfo; halves the build dirs and speeds the link.- Clean
$TMPDIR/cargo-mutants-rivet-*.tmpbefore AND after (nightly job step, not trust in graceful exit). mutants.out/is gitignored; the committed artifact is only the triaged baseline list.- Budget check before launch: N jobs × ~5 GB (debug=0) + headroom; refuse on low disk rather than fill it.
Pilot facts (2026-07, devbox M2 Max)
--libcycle: build 13-27s + test 3-5s per mutant; -j2 ≈ 12-18s wall each.- Orchestration files are offline-blind by construction:
replace run_keyset -> Ok(())survives the whole lib suite — only live tests guard those paths. This is WHY Tier 3 exists and why its cycle must be live. - The manifest ledger itself had 5 real gaps (checksums/cursor-range silently droppable, part-id arithmetic) — closed same-day with RED-proven unit tests.
Release Checklist
The evergreen, version-agnostic checklist that gates every Rivet tag. Treat this as operator discipline, not as a CI substitute — most items here are already enforced by automated gates (PR CI, nightly, semantic gates). The checklist names them so a release reviewer can see what was confirmed and how without grepping the workflows.
Scope of this document
| In scope | Out of scope |
|---|---|
| What must be green before tagging | One-off perf reports per release |
| What must be smoke-tested manually | Marketing copy / changelog drafting style |
| What must be updated in docs alongside the binary | cargo publish mechanics (handled by release.yml) |
Tag creation itself is automated by .github/workflows/release.yml. This
checklist is what a maintainer fills out before pushing the tag.
1. Config / schema
-
cargo test schema_drift— checked-inschemas/rivet.schema.jsonmatches the running binary. -
rivet schema config | diff - schemas/rivet.schema.json— no drift. - All sample configs in
examples/parse + validate (offline):cargo test --test examples_parse(loads everyexamples/*.yamlthroughConfig::from_yaml; no DB/network). -
tests/config_parse_errors.rs— unknown-field + did-you-mean regression suite green.
2. Local extraction
-
cargo test --release— full offline suite (~1300 tests). -
make seed-release— the 1M-rowcontent_itemsfixture the pressure test needs. The everydaymake seed-dbseeds 60k, andlive_content_load::pg_full_content_export_max_pressureFAILS (it does not skip) below 1M, so the live matrix below cannot go green without this. Same canonical seed, deterministic across engines — only the size differs. -
cargo test --release -- --ignored— full live matrix (PG + MySQL, MinIO, fake-gcs, Toxiproxy). Includes the type golden parity pair on Postgres + MySQL. -
Postgres + MySQL
e2esmoke —python3 -m dev.pytools.e2ecovers the 83-assertion end-to-end flow. -
Parquet output round-trips through
arrow-rsreader (covered bylive_parquet_roundtrip+live_type_golden). -
CSV output round-trips through
csvreader (covered byformat_golden). -
--validateand--reconcileexit zero on a clean run; non-zero on a tampered manifest (covered bylive_reconcile_repair,validate_regression). -
Resume after
kill -9mid-export keeps the prior_SUCCESSand converges on retry (covered bylive_crash_recovery,live_chunked_recovery). -
The release gate’s
harness · nextest-gradingcell is PASS — a parser that readsFAIL + LEAKas green would turn failed Rig cells green, so a gate with this cell red (or absent) is not a verdict at all.
3. Cloud smoke (manual)
Per-PR CI uses MinIO and fake-gcs containers. Real-cloud verification is operator-driven and recorded in docs/cloud-smoke-tests.md.
- S3 —
run+validate+validate --date+validate --prefix. - GCS —
run+validate+validate --date+validate --prefix. - Azure (account key) —
run+validate. - Azure (SAS token) —
run+validate; SAS-expiry preflight fires on a token < 60 min fromse=. - Failed source auth does not leak the URL password into stderr,
summary.json,summary.md, manifest, or journal. - Failed destination auth does not leak credentials into the same set of artifacts.
- Update the “Last manually verified” date in docs/cloud-smoke-tests.md.
- Update the corresponding row in docs/reliability-matrix.md § Destination coverage.
4. Security
-
cargo audit— no unpatched advisories in declared deps. - Secret-redaction tests green:
tests/config_secrets.rs,tests/validate_secrets.rs(where present). - No new code path emits raw
DATABASE_URL/RIVET_STATE_URL/ cloud keys into logs, summaries, manifest, journal, or panic backtraces. Search:rg -n 'url|password|secret_key|account_key|sas_token' src/after the diff and audit any new emitter.
5. Docs
- README quickstart matches the CLI surface (
rivet --help). - CHANGELOG updated under the new version heading.
- Cloud smoke verification date in docs/cloud-smoke-tests.md is current.
- docs/reliability-matrix.md reflects any coverage tier changes.
- docs/reference/cli.md describes any new flag or subcommand.
- If the version bumps the schema version,
schemas/latest/mirror is regenerated.
6. Backward compatibility
For non-major releases:
- Old configs without the new fields still parse and run.
- State-DB migration roundtrip green:
tests/state_compat.rs(v1 → vN). - CLI flag contract unchanged at the offline level
(
tests/cli_contract.rs).
7. Release artifacts
-
cargo build --releasesucceeds on Linux x86_64 (PR CI build job). -
release.ymlcross-build matrix green (Linux x86_64/arm64, macOS arm64/Intel). - Docker image (multi-arch via native amd64+arm64 runners) tagged.
- Homebrew tap PR opened in
panchenkoai/homebrew-rivet. - crates.io publish dry-run:
cargo publish --dry-run— automated: thepre-pushhook runscargo publish --locked --dry-runwhenever the branch bumps the crate version vsmain, so a version-bump push already exercised it (this box is the manual backstop if hooks are bypassed).
What this checklist does not enforce
The point of being explicit:
- Per-PR real-cloud CI. Too costly and noisy at the current project stage. Real S3 / GCS / Azure runs are recorded manually in docs/cloud-smoke-tests.md.
- 24-hour soak tests. Not run. Tracked in
rivet_roadmap.md§ 5.1 as P2 future work. - Release-artifact signing / SBOM. Tracked in
rivet_roadmap.md§ 5.1 as P1/P2 future work. When shipped, this checklist gains a signature-verification step and an SBOM-generation step. - Cross-platform binary smoke. Per-PR
build-releaseonly builds Linux x86_64. Release-tag builds run the full matrix; manual install verification on macOS and Linux arm64 is operator-driven.
Updating this checklist
This document is intentionally evergreen. Per-version perf evidence and
exhaustive test counts belong in the changelog or a dedicated report
(see docs/archive/benchmark_report_v0.5.0.md for the pattern). Edit this file
only when:
- A new gate becomes mandatory (add the row, link the test file).
- A previous gate is automated end-to-end (move it from the manual section into the CI section, or strike it).
- A new release artifact ships (e.g. a Snap package would add a row under § 7).
Instructional GIFs
Three short screencasts of Rivet’s core workflows, rendered from VHS tape scripts against the repository’s local Docker Compose stack.
Overview screencasts:
| GIF | Scenario | Source |
|---|---|---|
| basic.gif | Scaffold config -> doctor -> check -> run -> state (≈25 s) | basic.tape |
| plan-apply.gif | Plan/Apply: sealed artifact + credential redaction (ADR-0005 PA9) (≈20 s) | plan-apply.tape |
| reconcile-repair.gif | Chunked export + reconcile + targeted repair; committed boundary untouched per ADR-0009 RR4 (≈35 s) | reconcile-repair.tape |
Short, single-command spots (embedded next to each step of Getting Started):
| GIF | Scenario | Source |
|---|---|---|
| init-scaffold.gif | rivet init + cat orders.yaml — what scaffolding produces (≈8 s) | init-scaffold.tape |
| check-verdict.gif | rivet check verdict block: strategy, verdict, suggestion (≈7 s) | check-verdict.tape |
| inspect.gif | Post-run inspection: state show + metrics + state files + state progression (≈15 s) | inspect.tape |
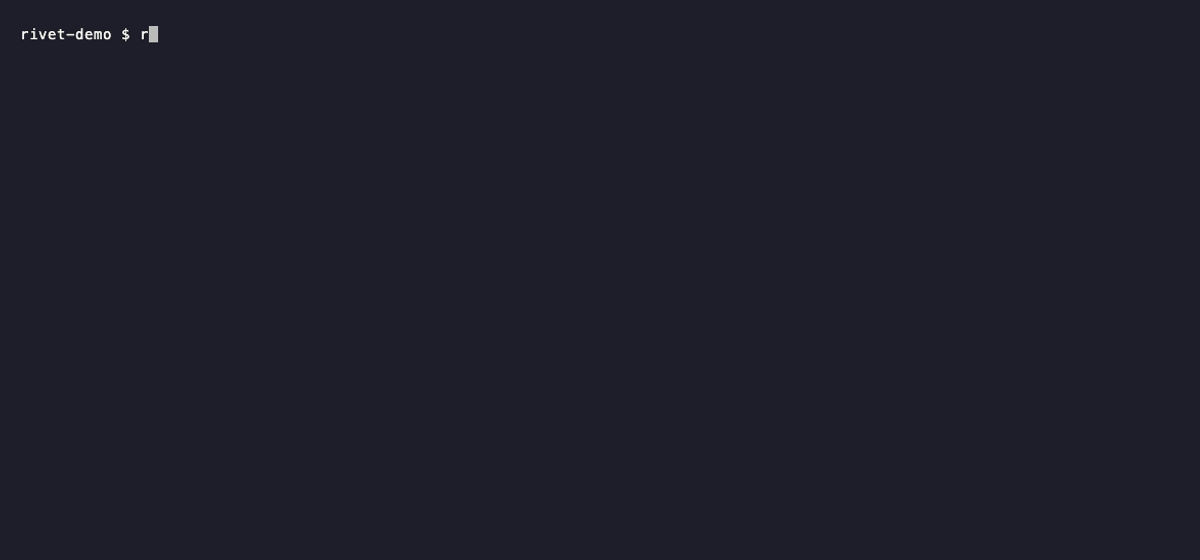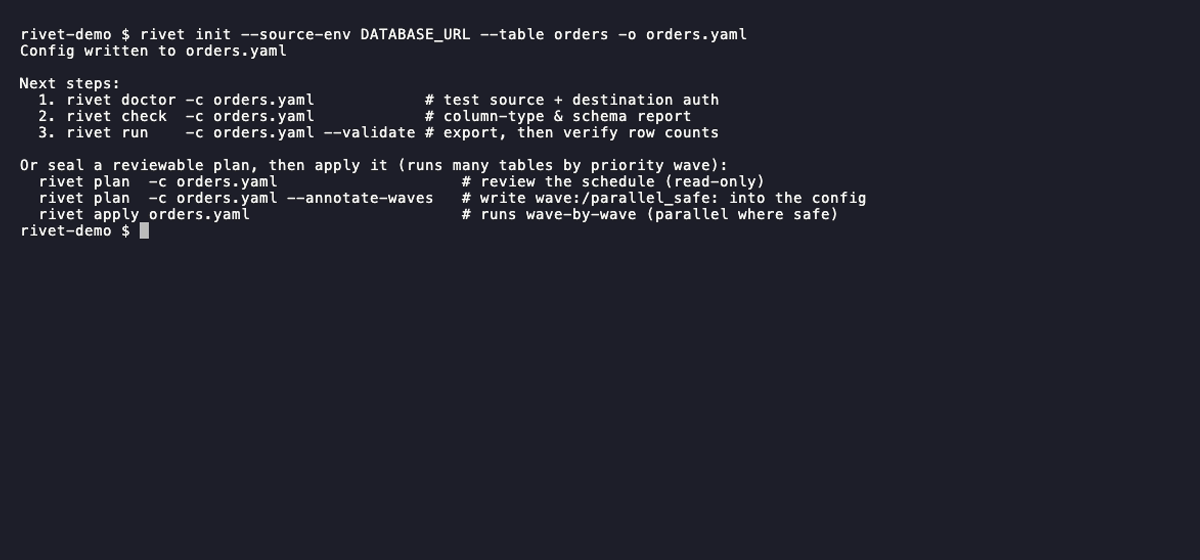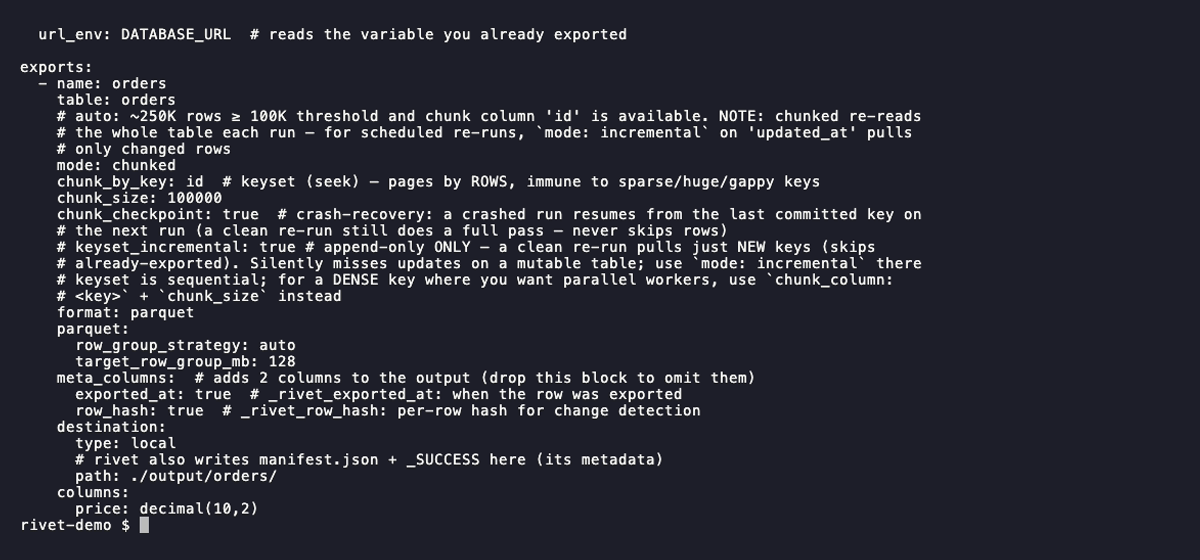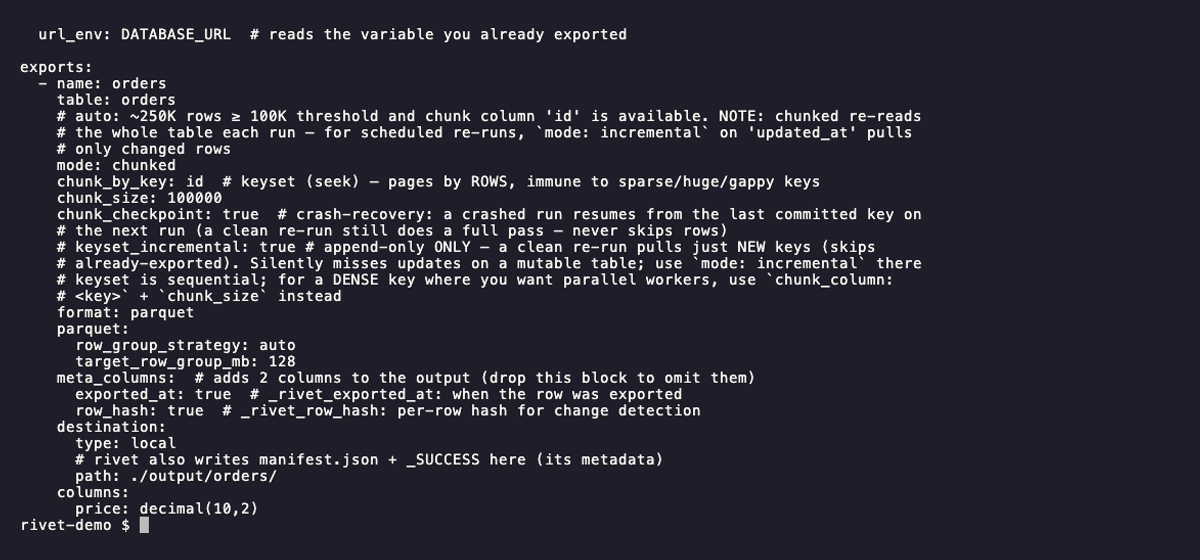
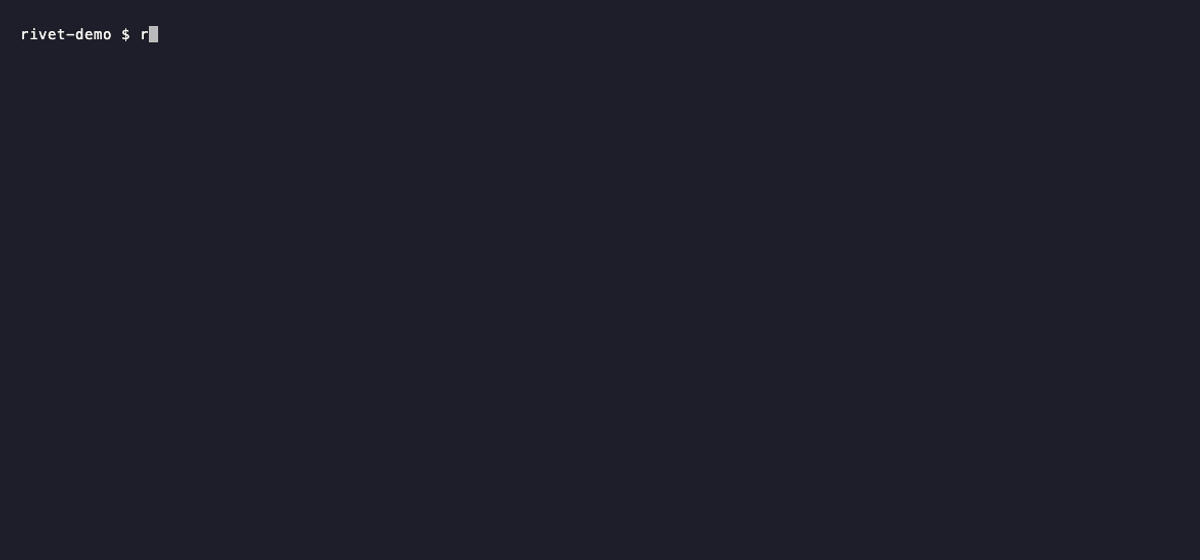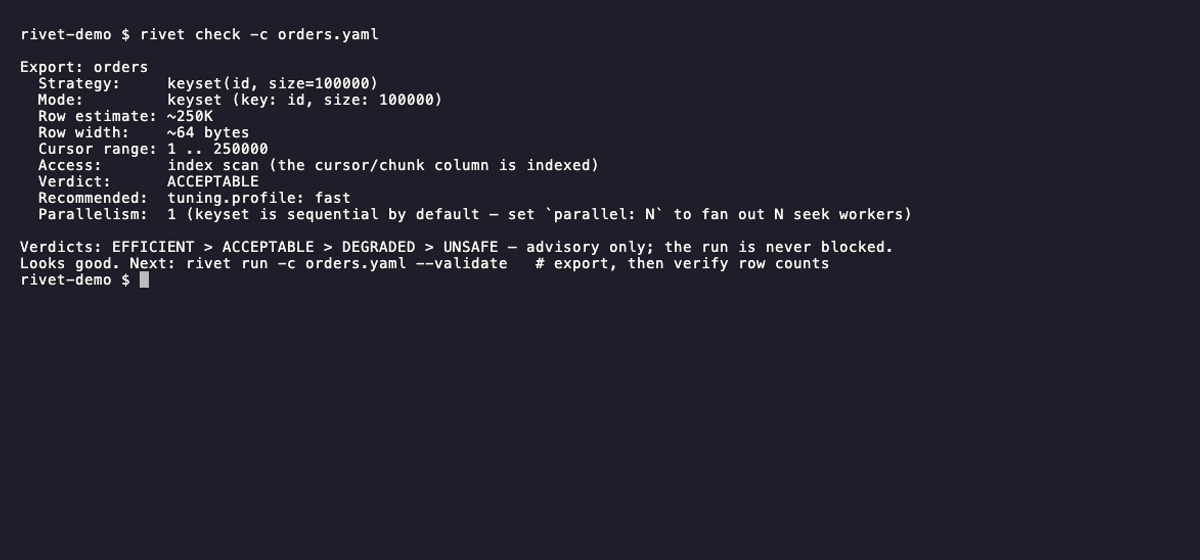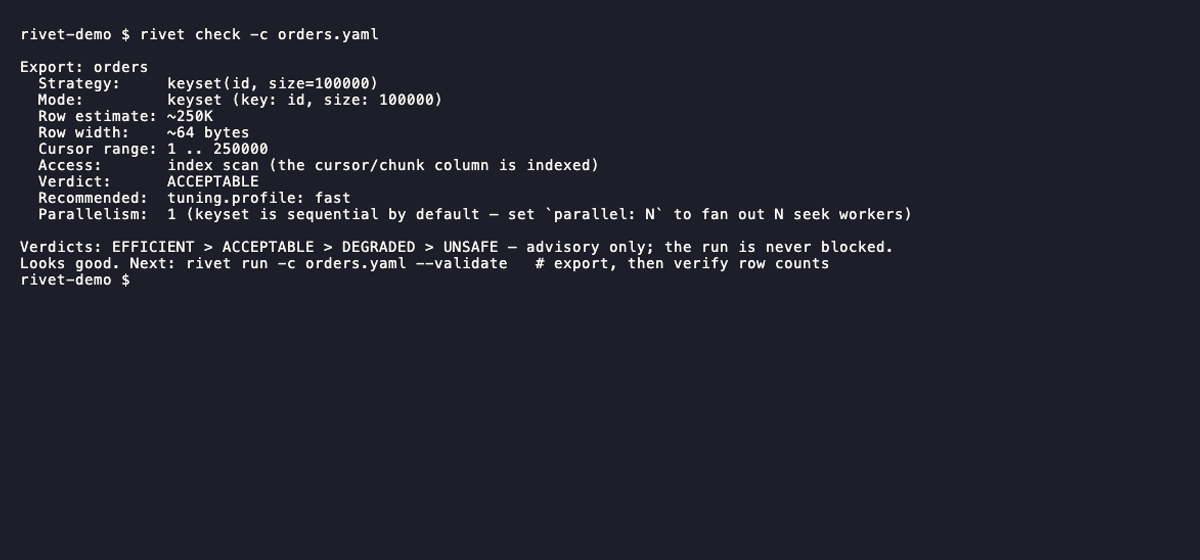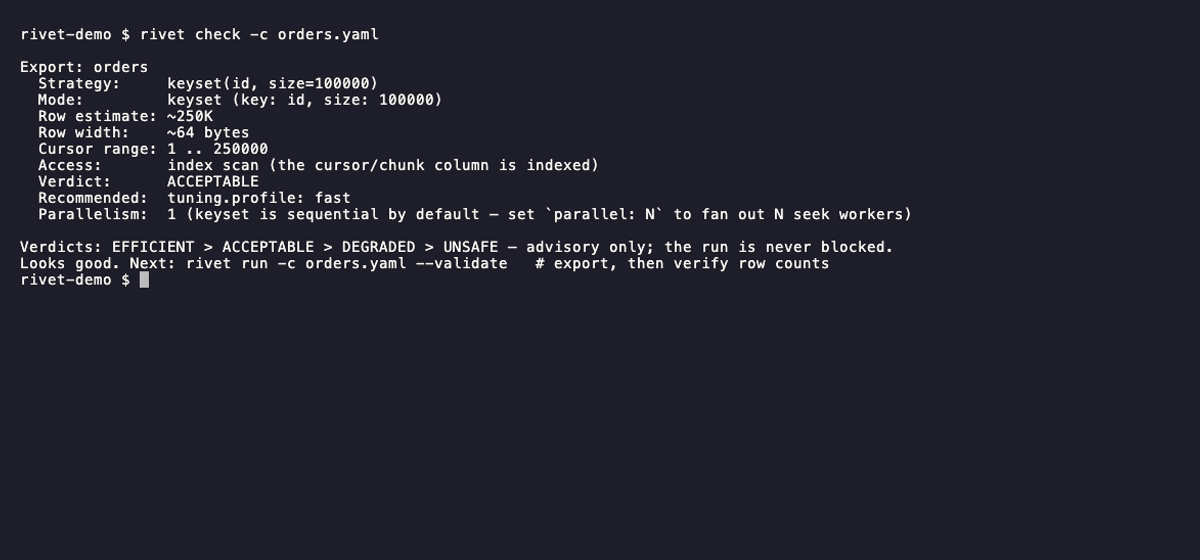
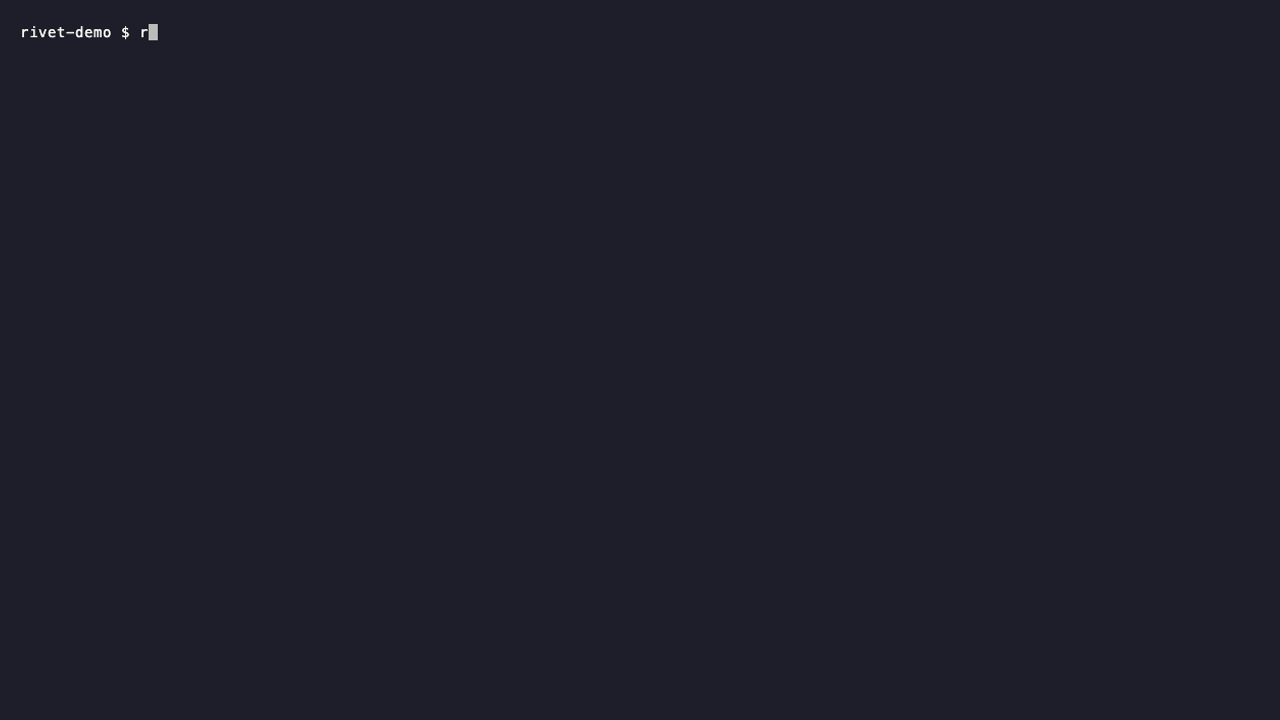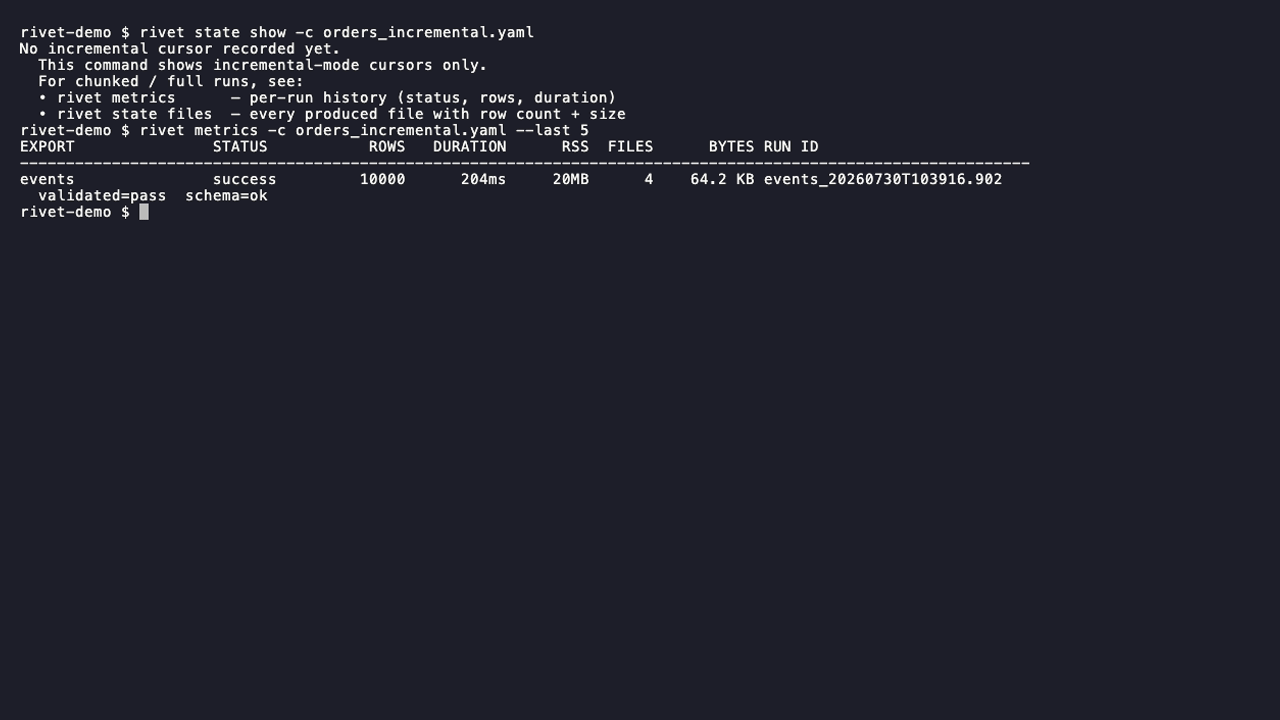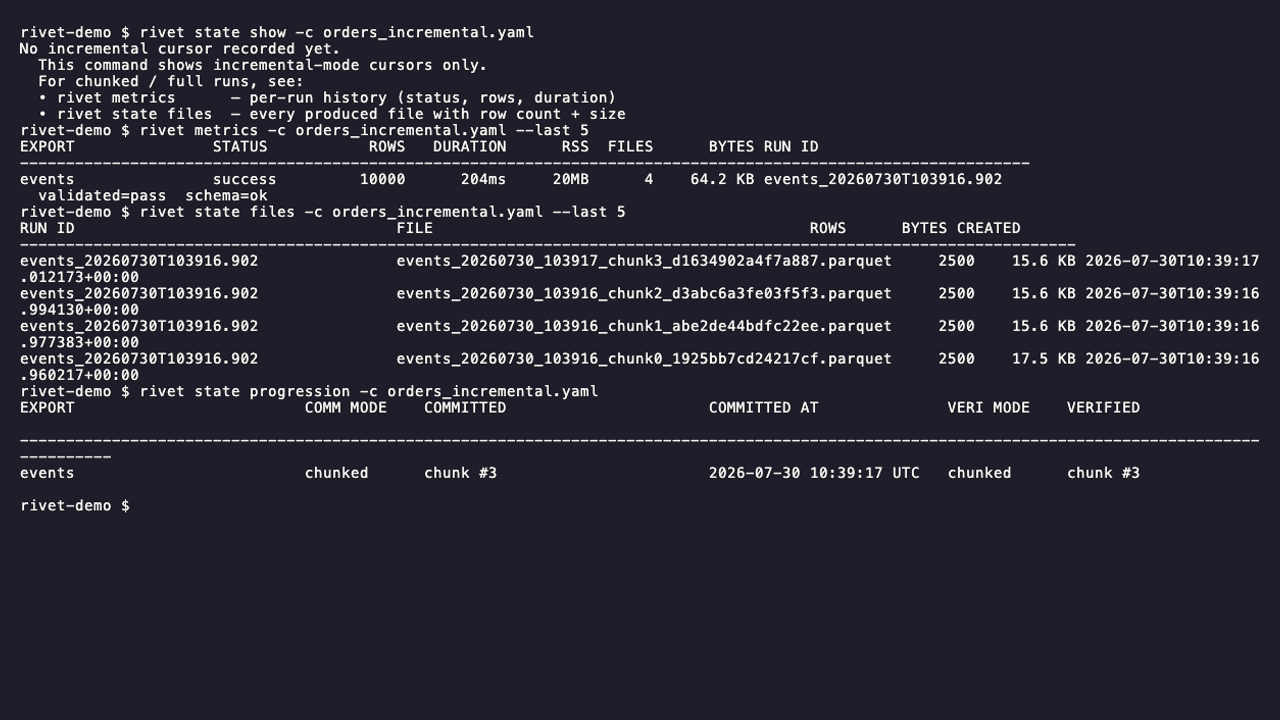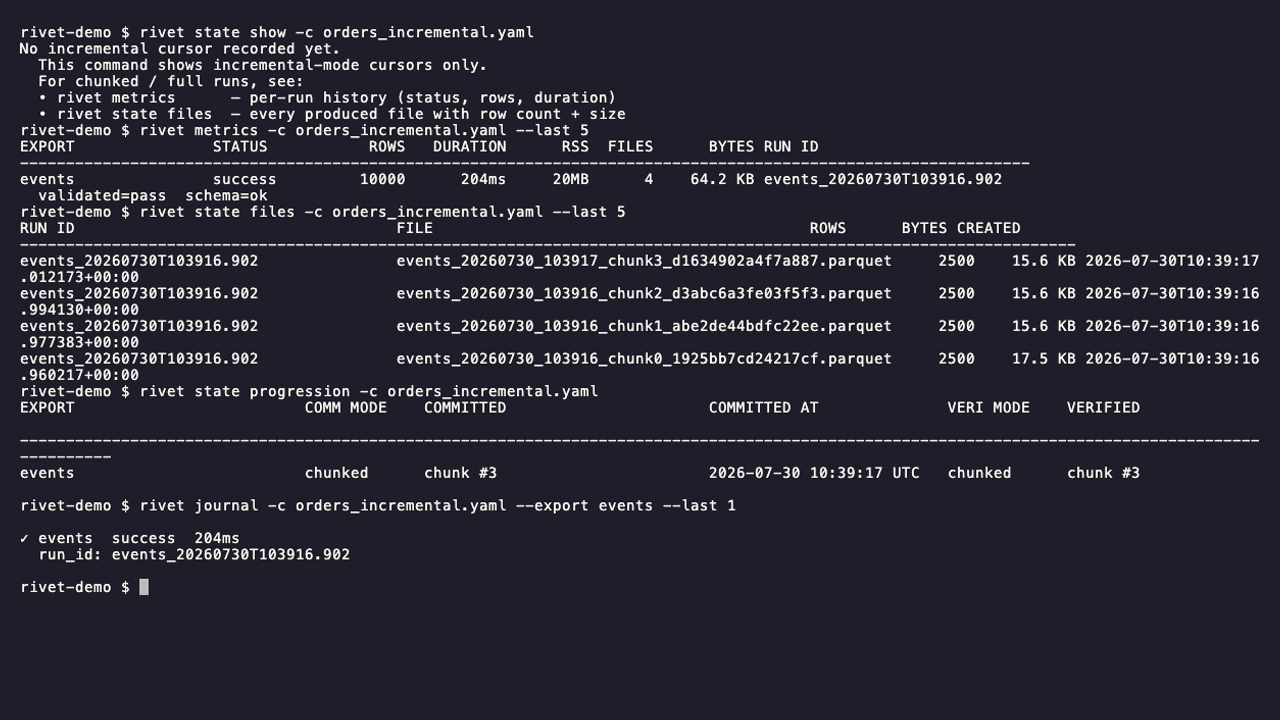
Mode / planner spots (embedded in docs/modes/, docs/reference/, docs/planning/):
| GIF | Scenario | Source |
|---|---|---|
| chunked-progress.gif | Chunked export on 50 k rows / 10 chunks with RUST_LOG=info so per-chunk progress is visible; ends with the structured summary (≈14 s) | chunked-progress.tape |
| incremental-cursor.gif | Two-run cursor progression — first run exports 10 k rows and saves cursor, second run is skipped via skip_empty: true (≈14 s) | incremental-cursor.tape |
| discover-artifact.gif | rivet init --discover + jq over the JSON artifact — ranked cursor + chunk candidates per table (≈8 s) | discover-artifact.tape |
| plan-campaign.gif | Multi-export rivet plan: Priority / Prioritize block per export + Campaign block with shared_source_heavy_conflict warning on a shared source_group (≈9 s, needs 20 M + 15 M-row fixture) | plan-campaign.tape |
| parallel-cards.gif | rivet run --parallel-export-processes over four chunked exports: one card per export with live progress bar, ETA, rows, and final metrics in place; trailing aggregate Run summary (≈30 s) | parallel-cards.tape |
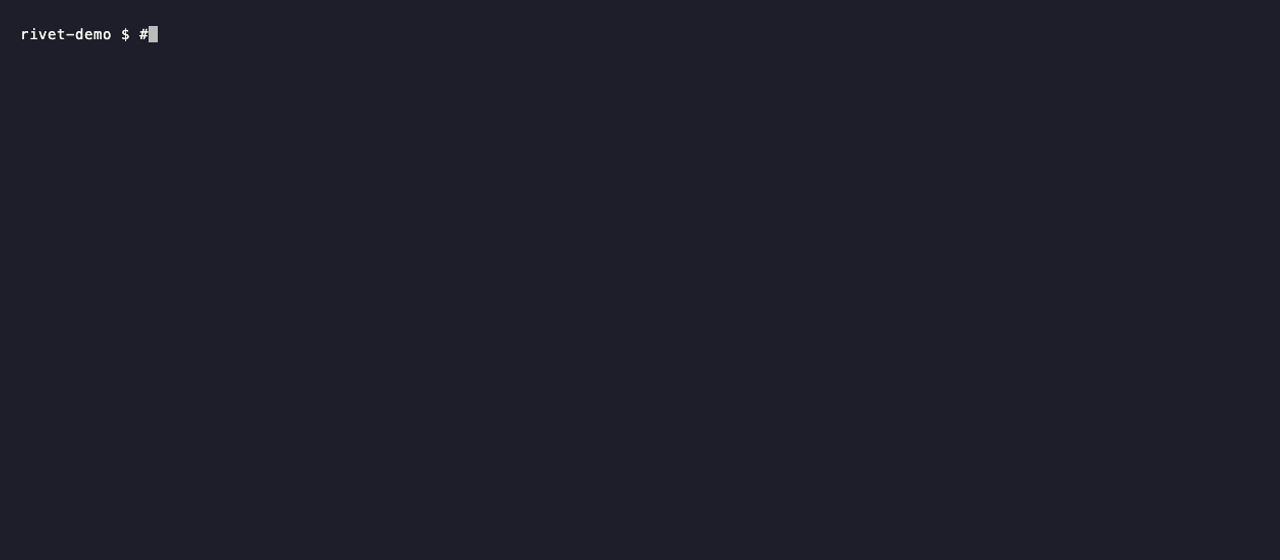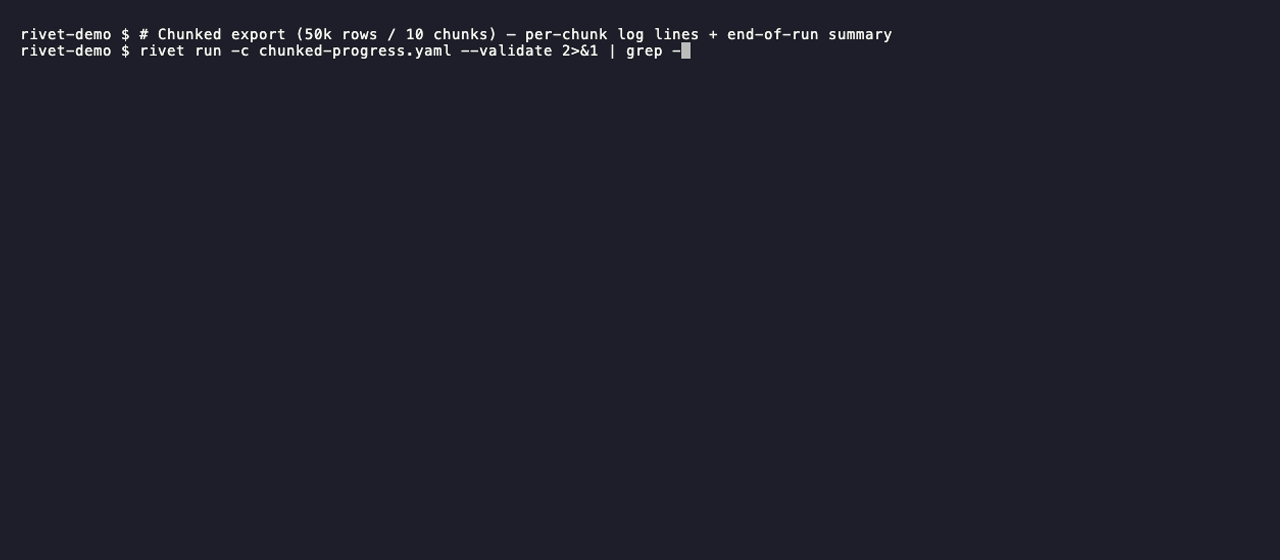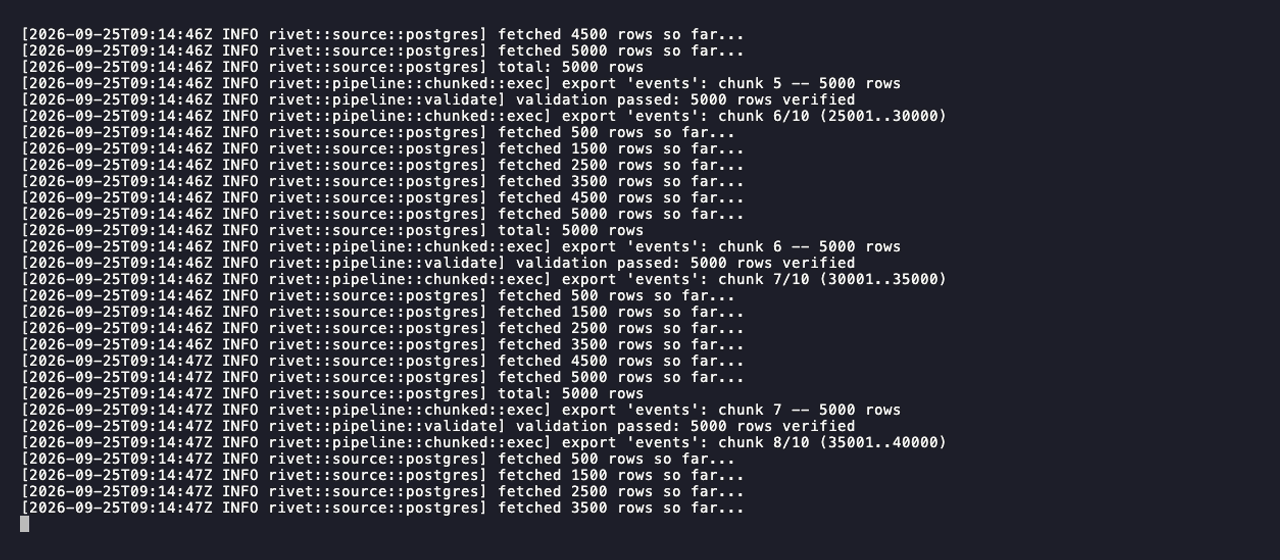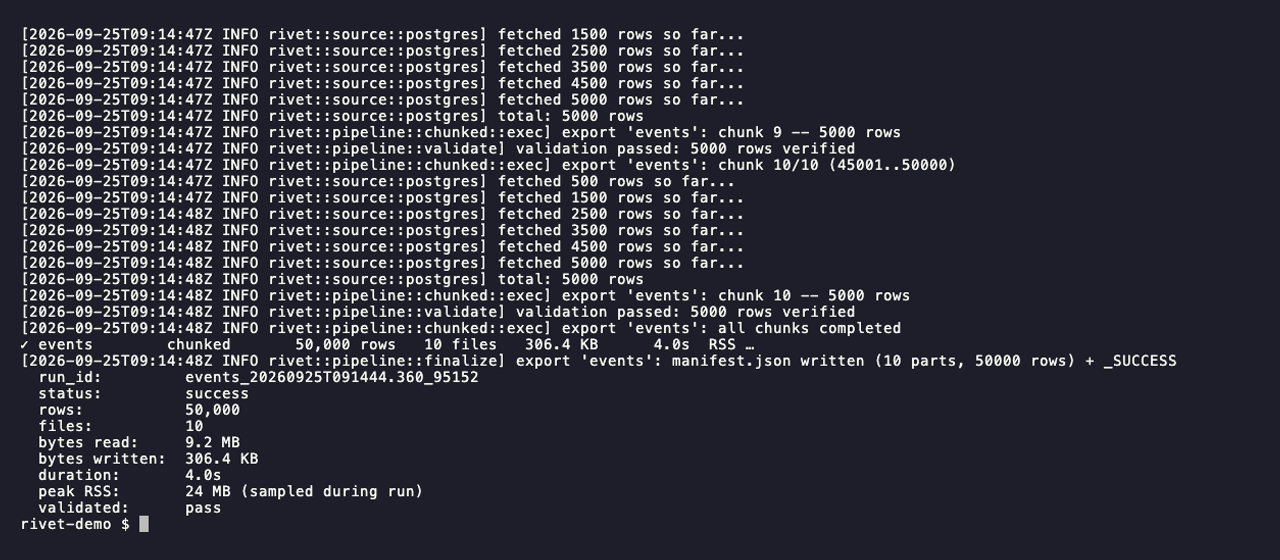
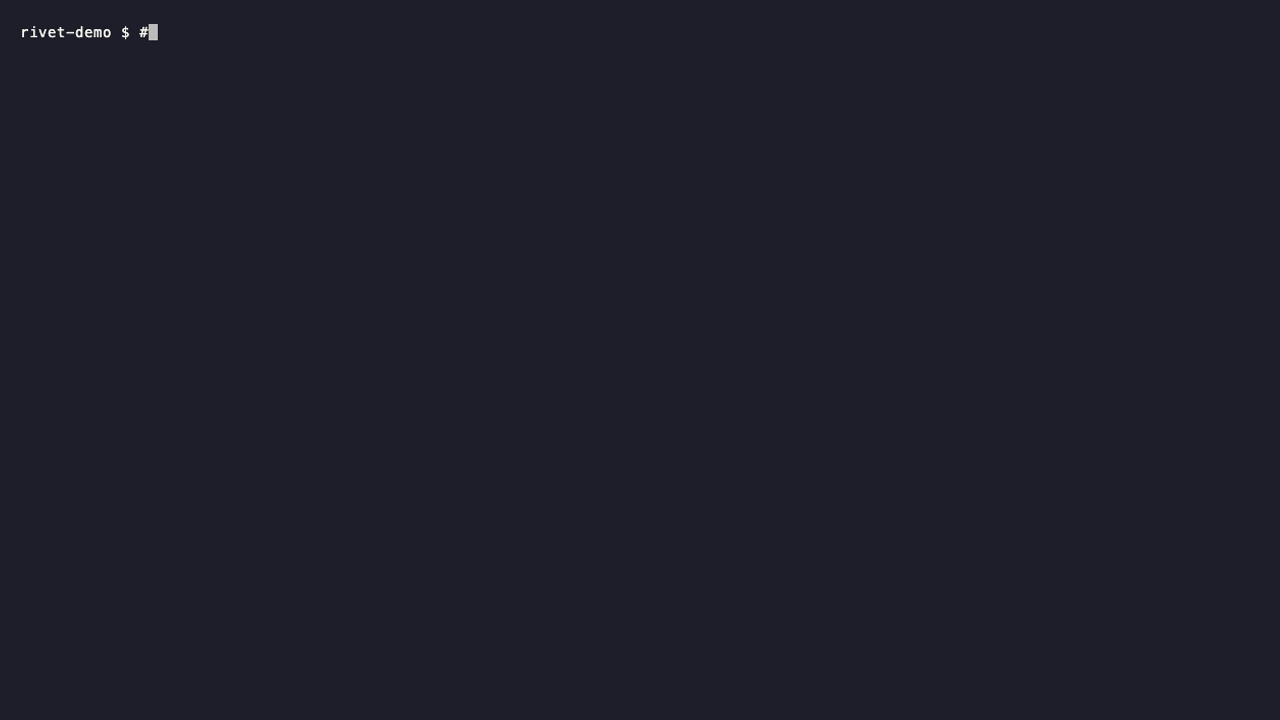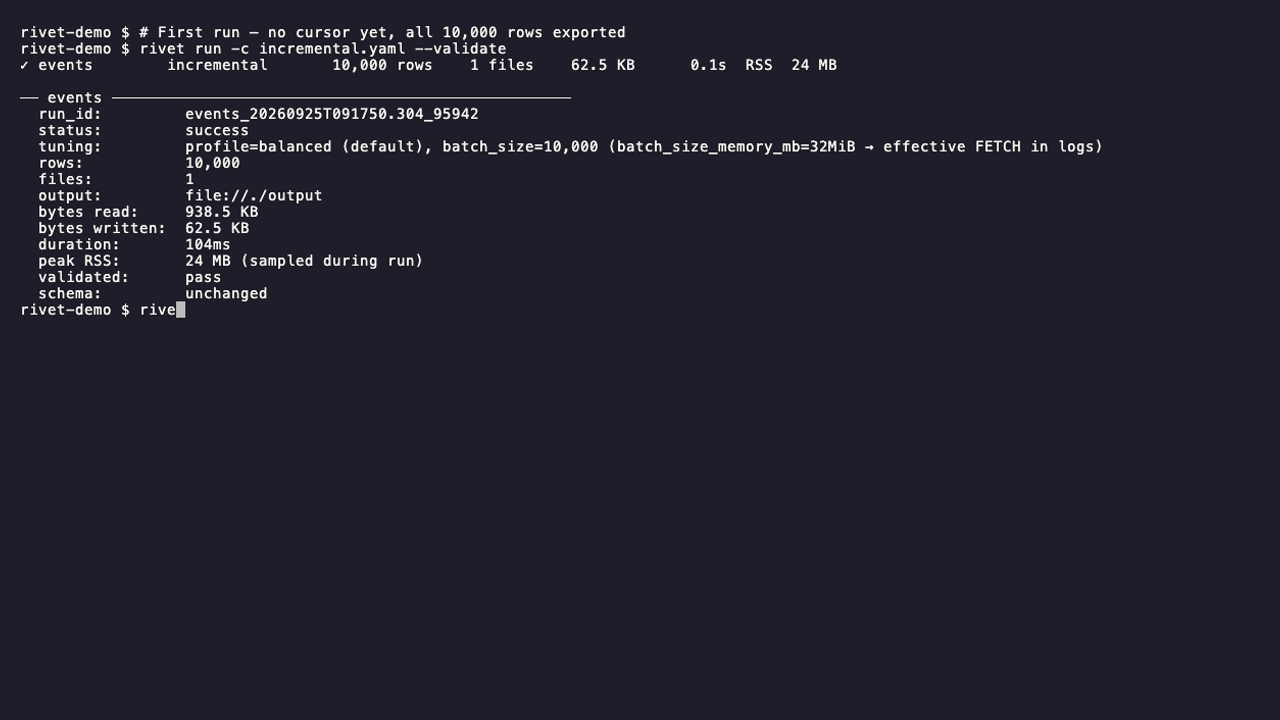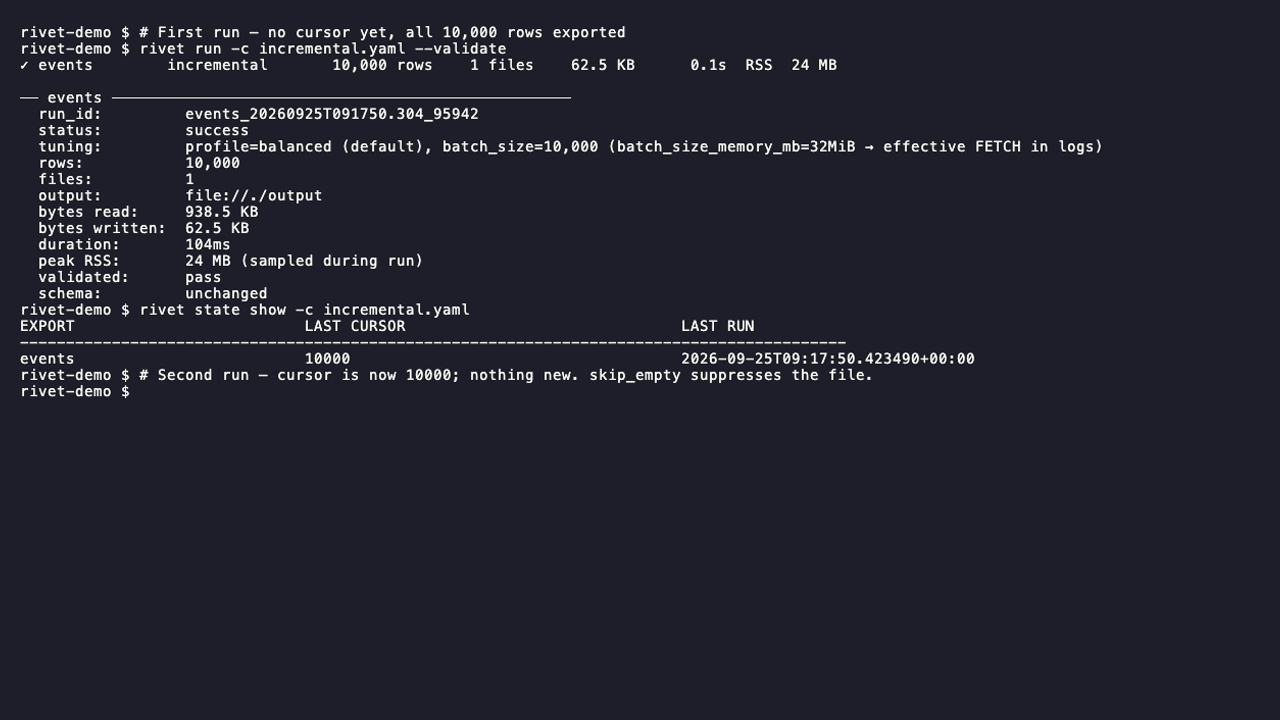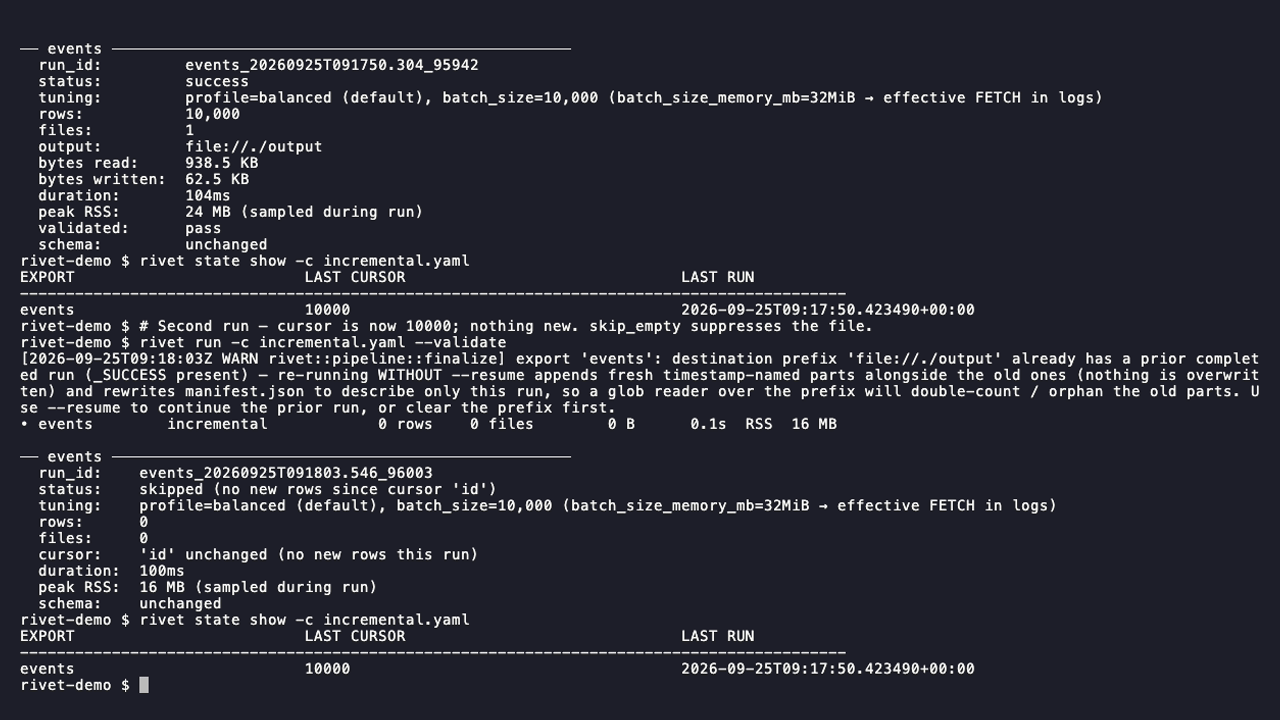
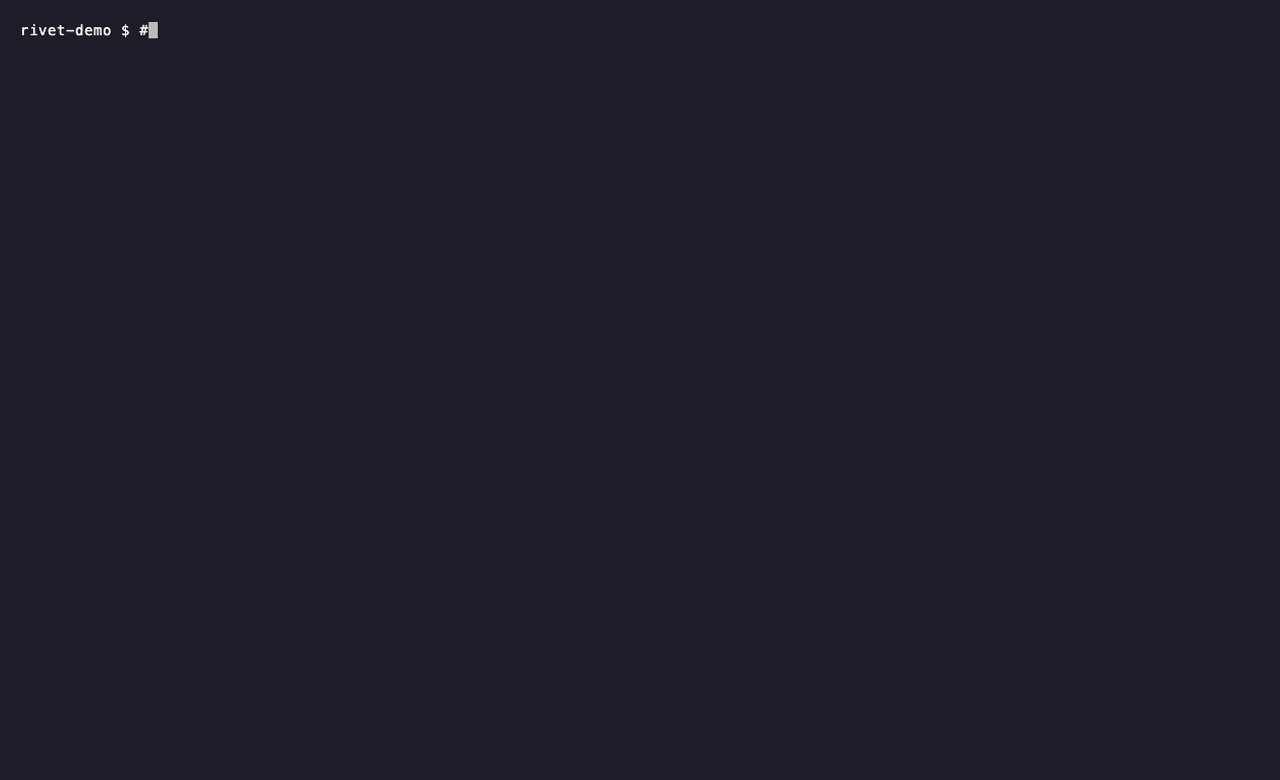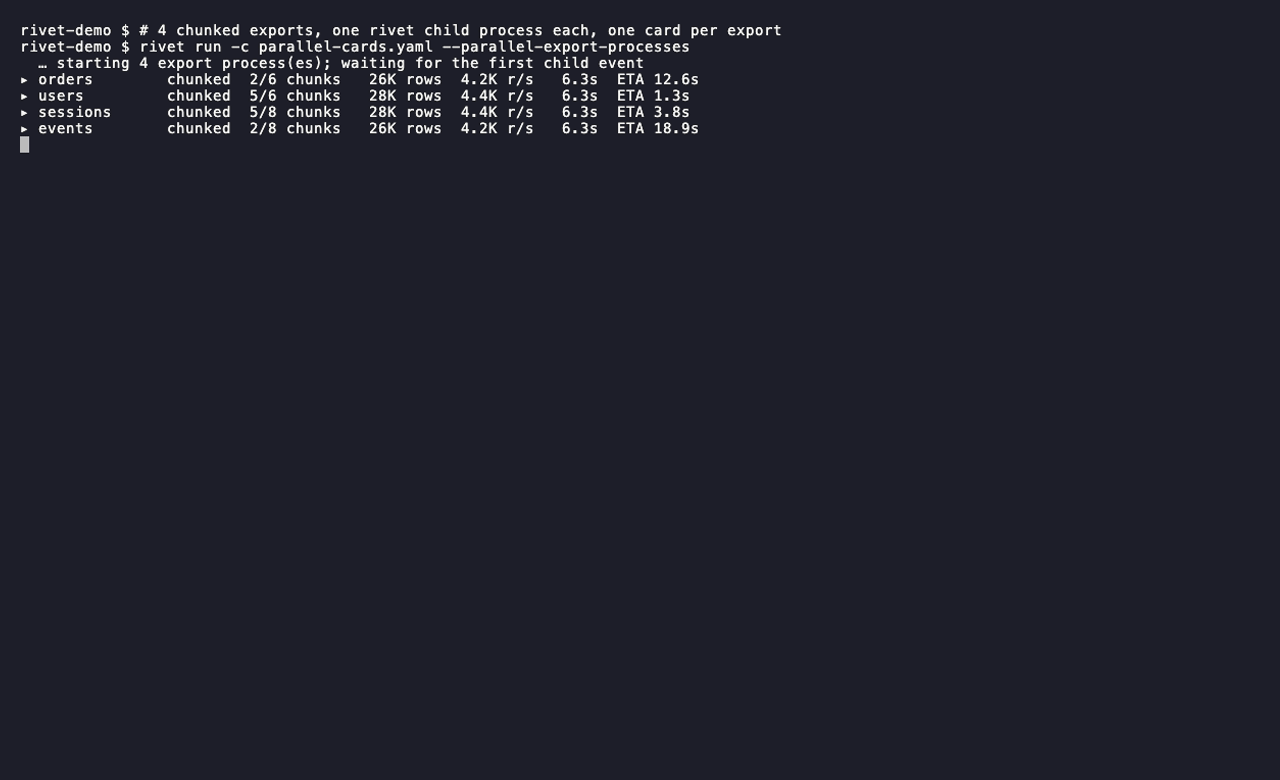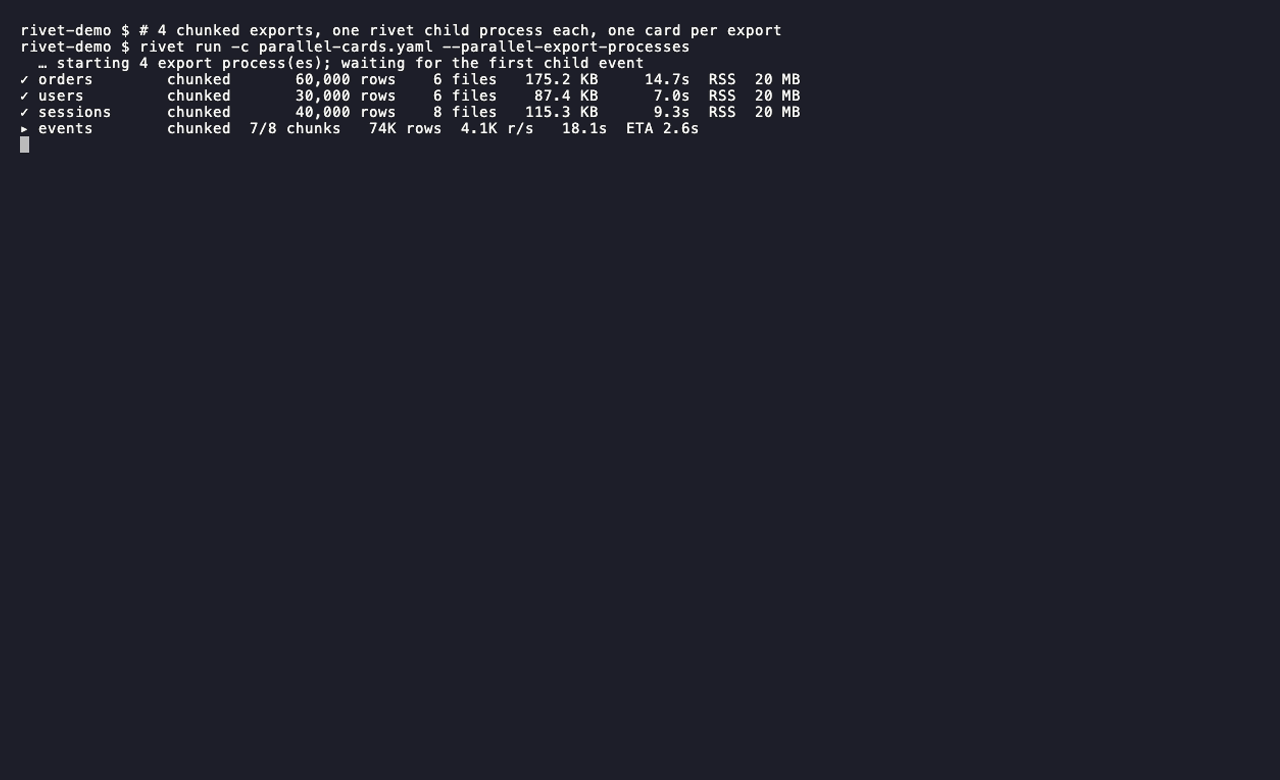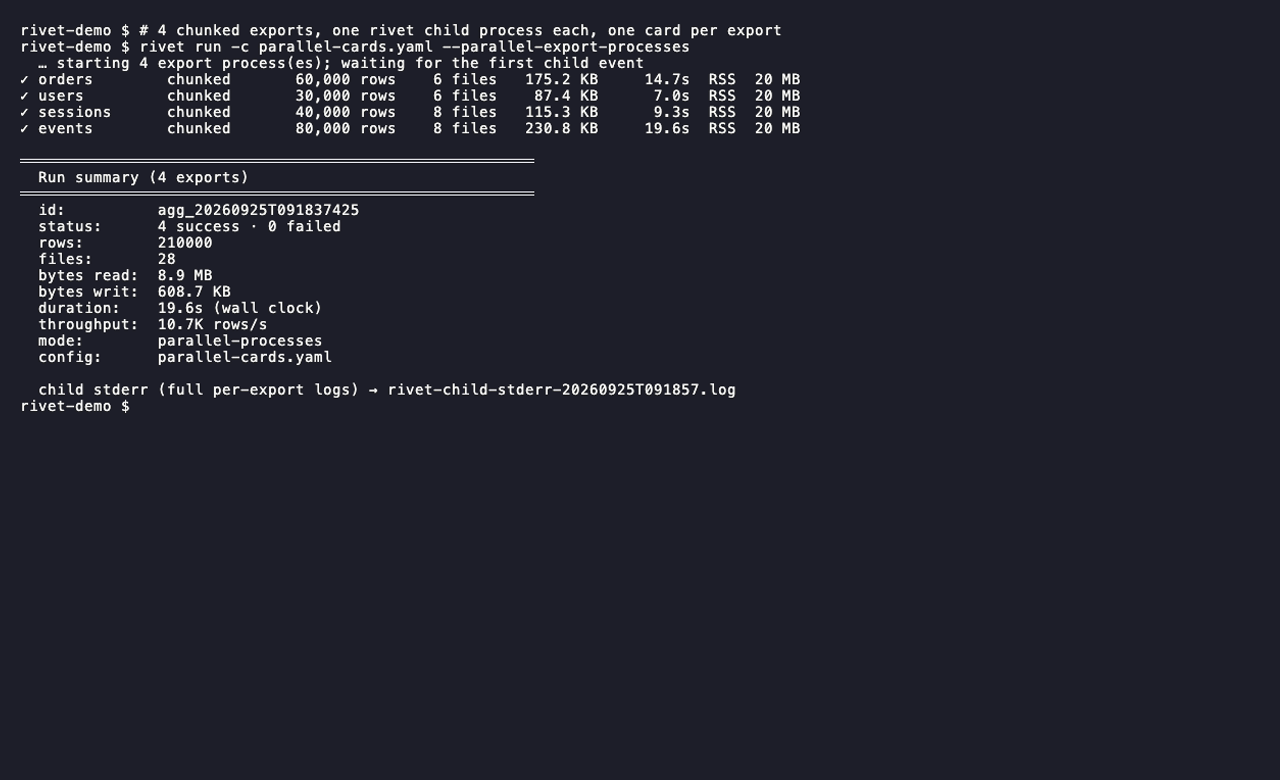
Destination-specific:
| GIF | Scenario | Source |
|---|---|---|
| doctor-gcs.gif | rivet doctor + rivet run against real Google Cloud Storage via Application Default Credentials; final gcloud storage ls confirms .rivet_doctor_probe + Parquet (≈18 s). Requires gcloud auth application-default login and write access to $GCS_DEMO_BUCKET (default rivet_data_test). | doctor-gcs.tape |
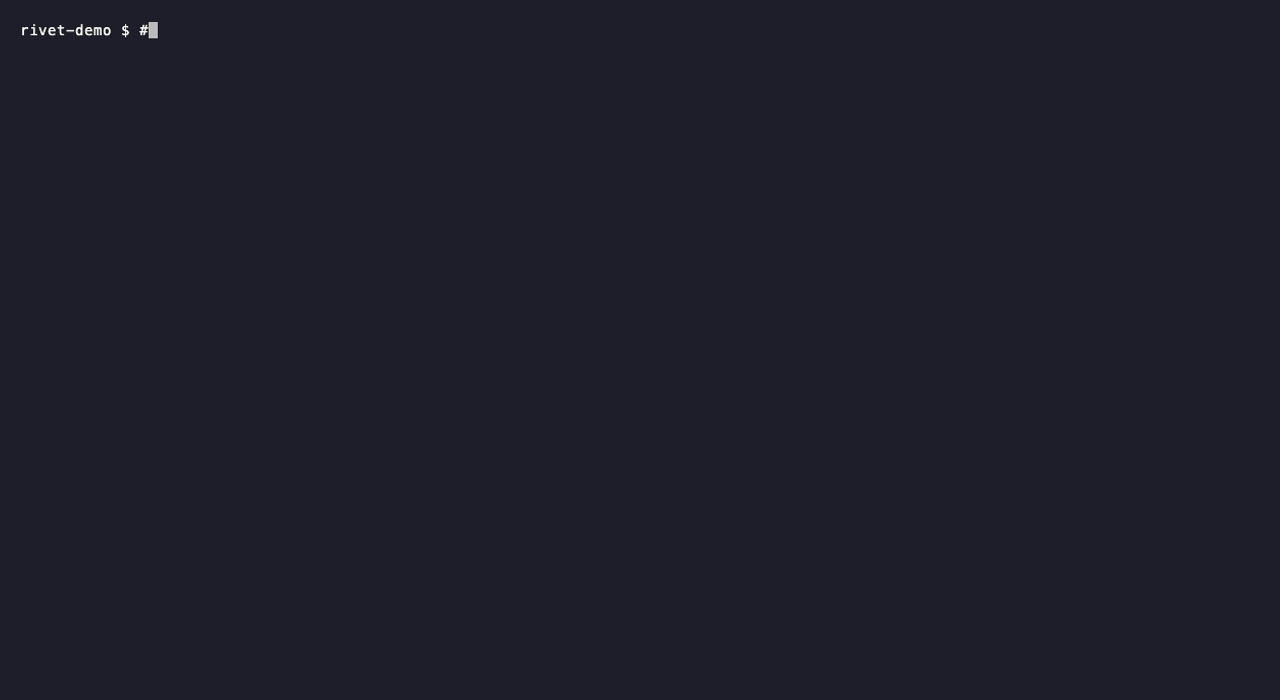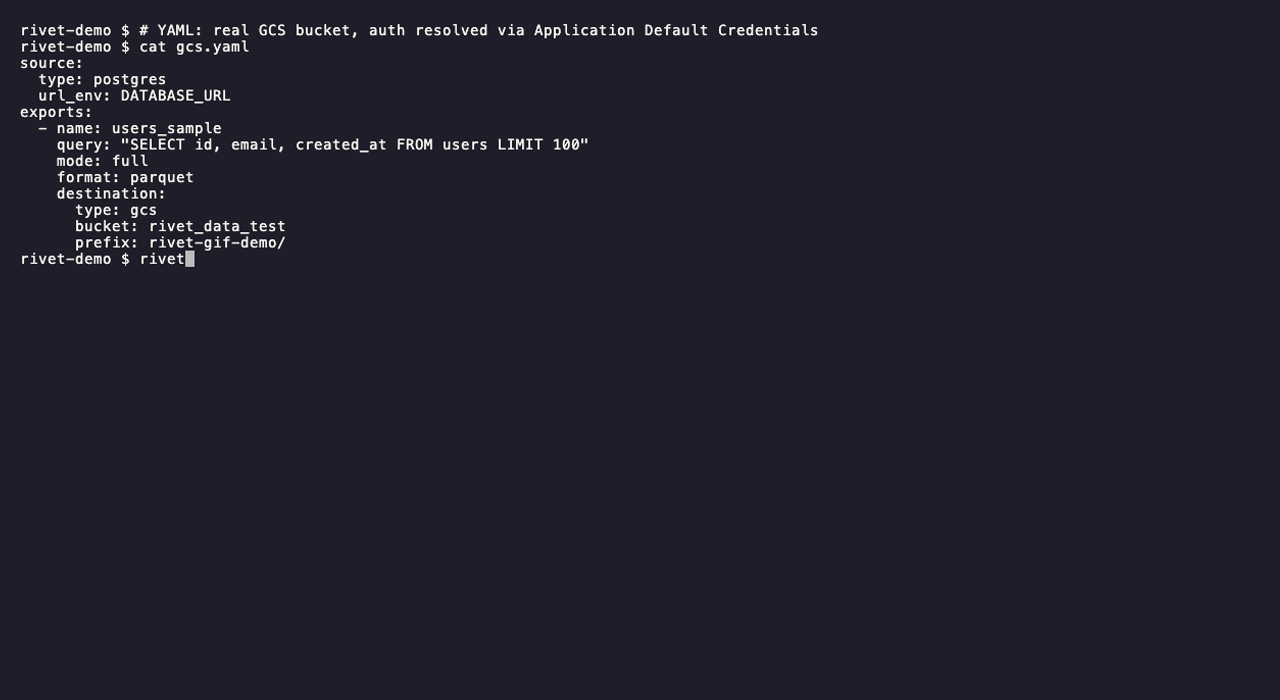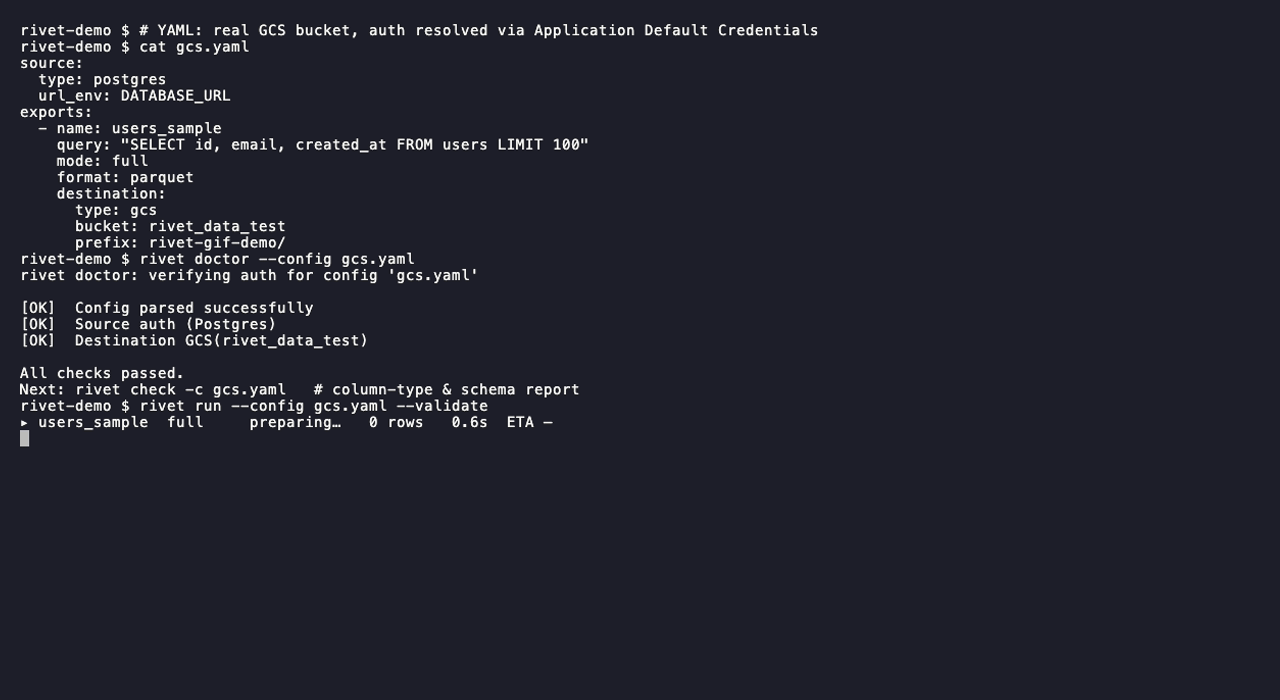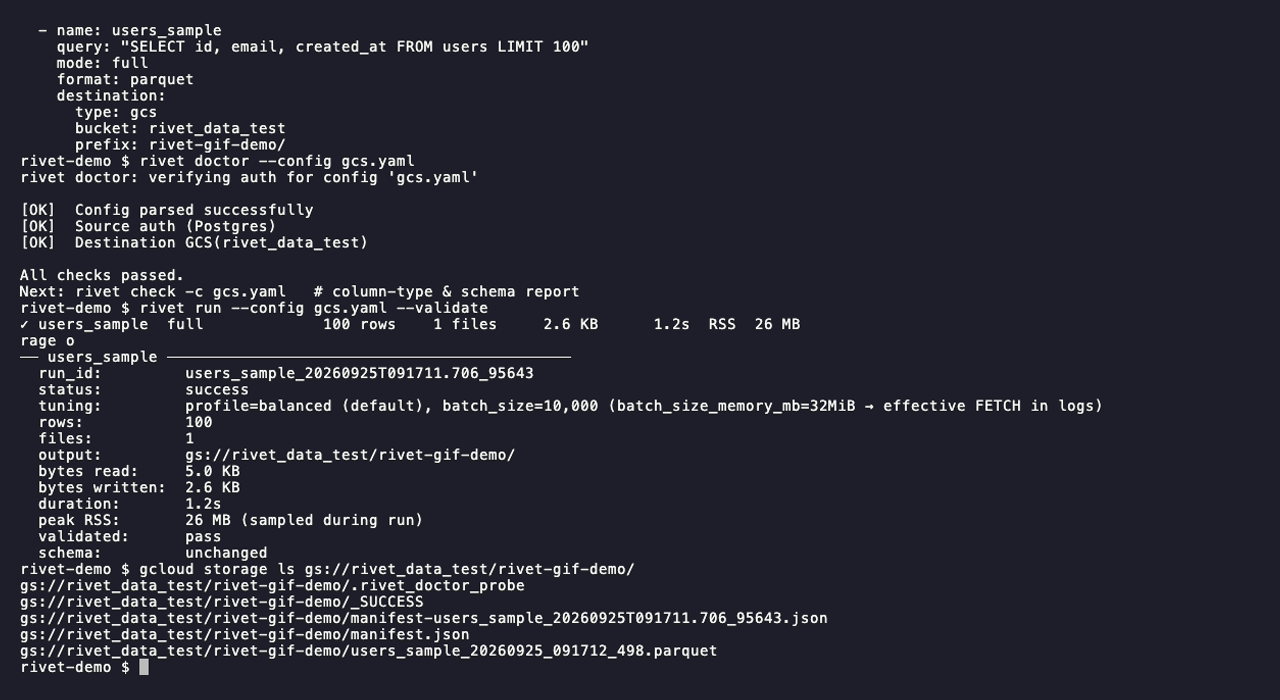
Operational warnings:
| GIF | Scenario | Source |
|---|---|---|
| pool-detect.gif | Connect-time pooler / proxy detection: direct PG (silent) → pgBouncer (transaction-mode warning) → direct MySQL (silent) → ProxySQL (MysqlProxyKind::ProxySql warning). Requires the pool docker-compose profile (docker compose --profile pool up -d pgbouncer proxysql); ≈18 s. | pool-detect.tape |
Change data capture:
| GIF | Scenario | Source |
|---|---|---|
| cdc.gif | Scaffold mode: cdc, capture MySQL binlog changes since a checkpoint into typed Parquet, read them back as typed rows (__op + columns) (≈15 s) | cdc.tape |
| cdc-parallel.gif | rivet run --parallel-exports with a full snapshot + a CDC stream of the same table, side by side — two cards, one aggregate summary (≈12 s) | cdc-parallel.tape |
| error-cdc-access.gif | A MySQL user missing the REPLICATION grant gets the exact requirement + a pointer to the grants doc, not a raw driver error (≈6 s) | error-cdc-access.tape |
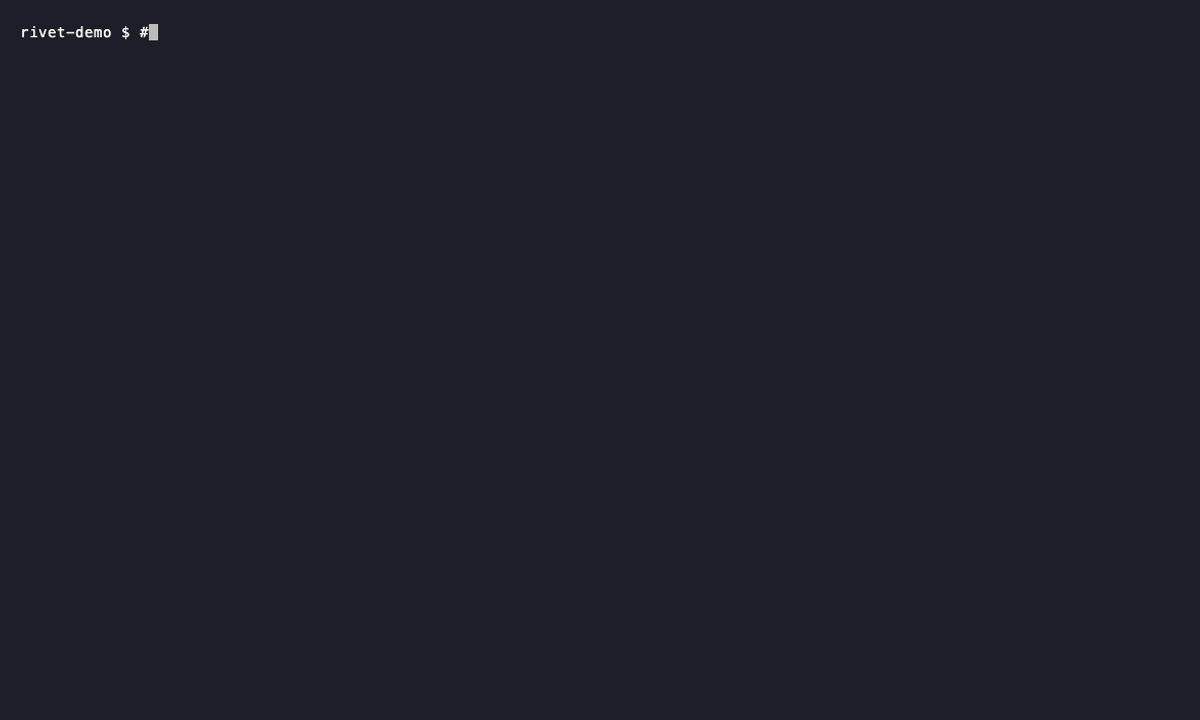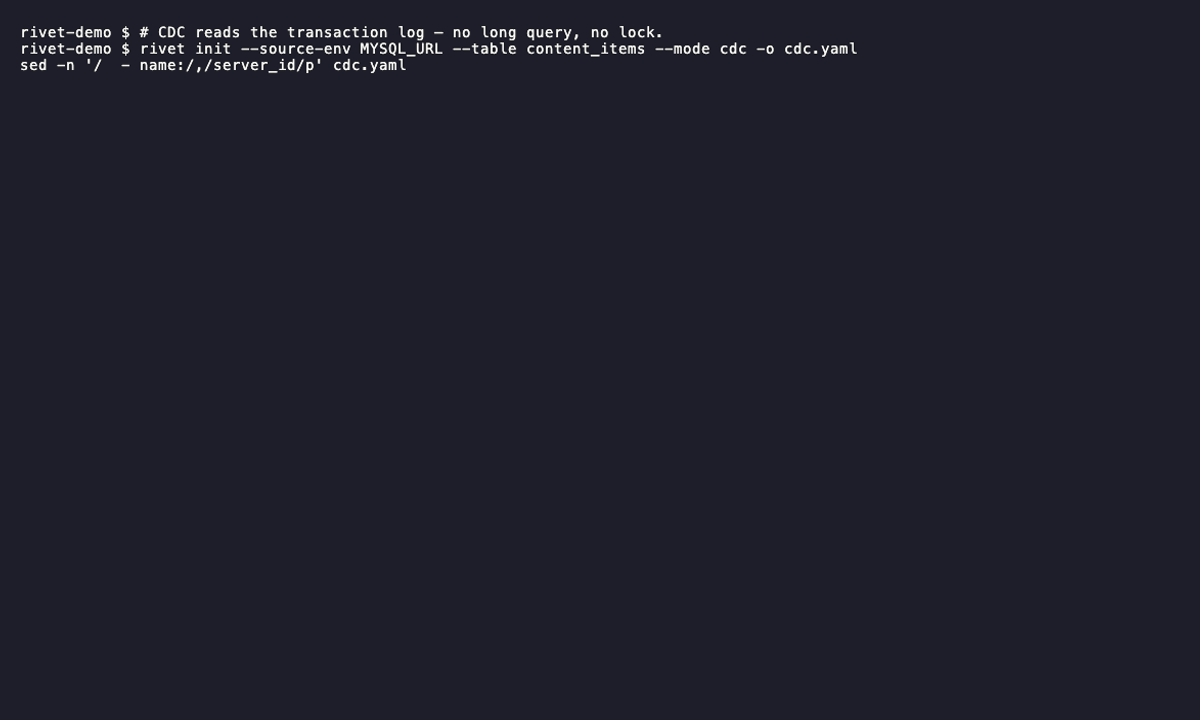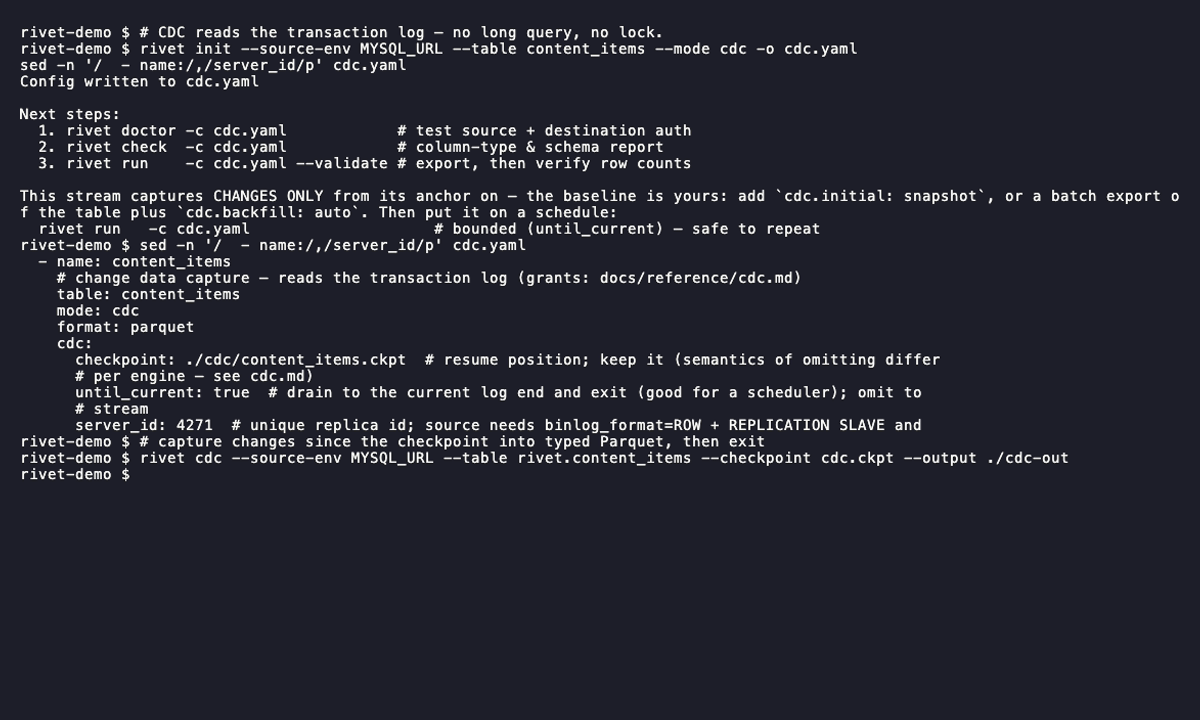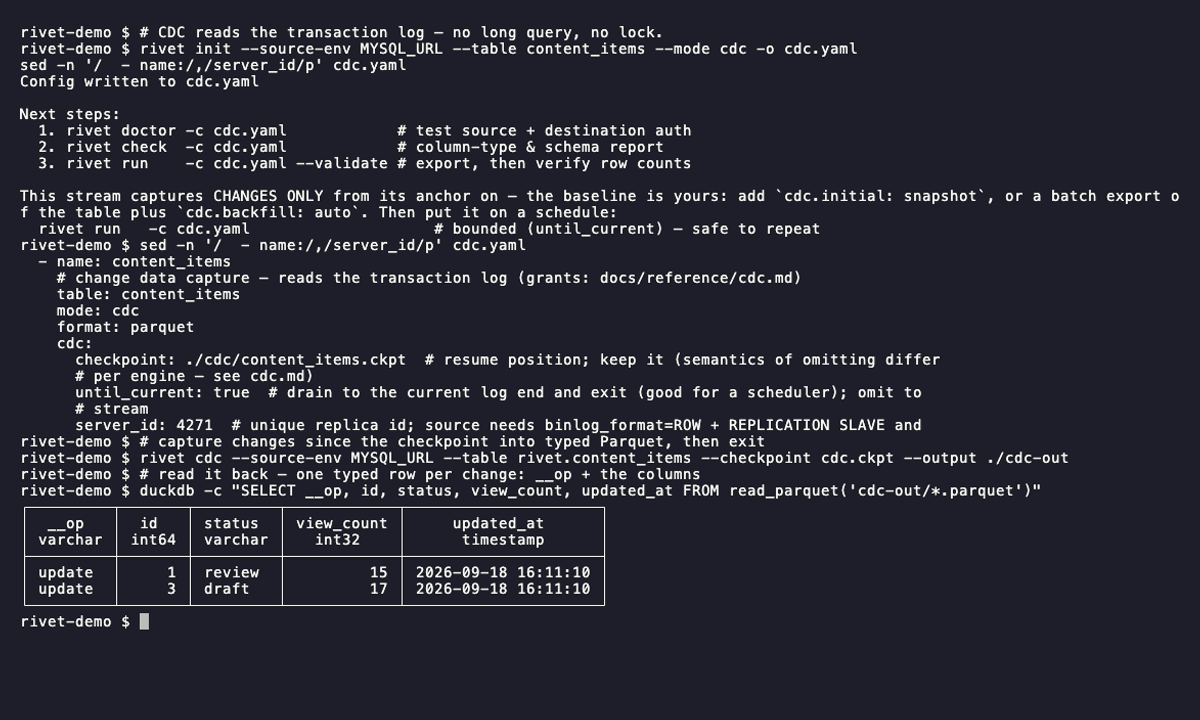
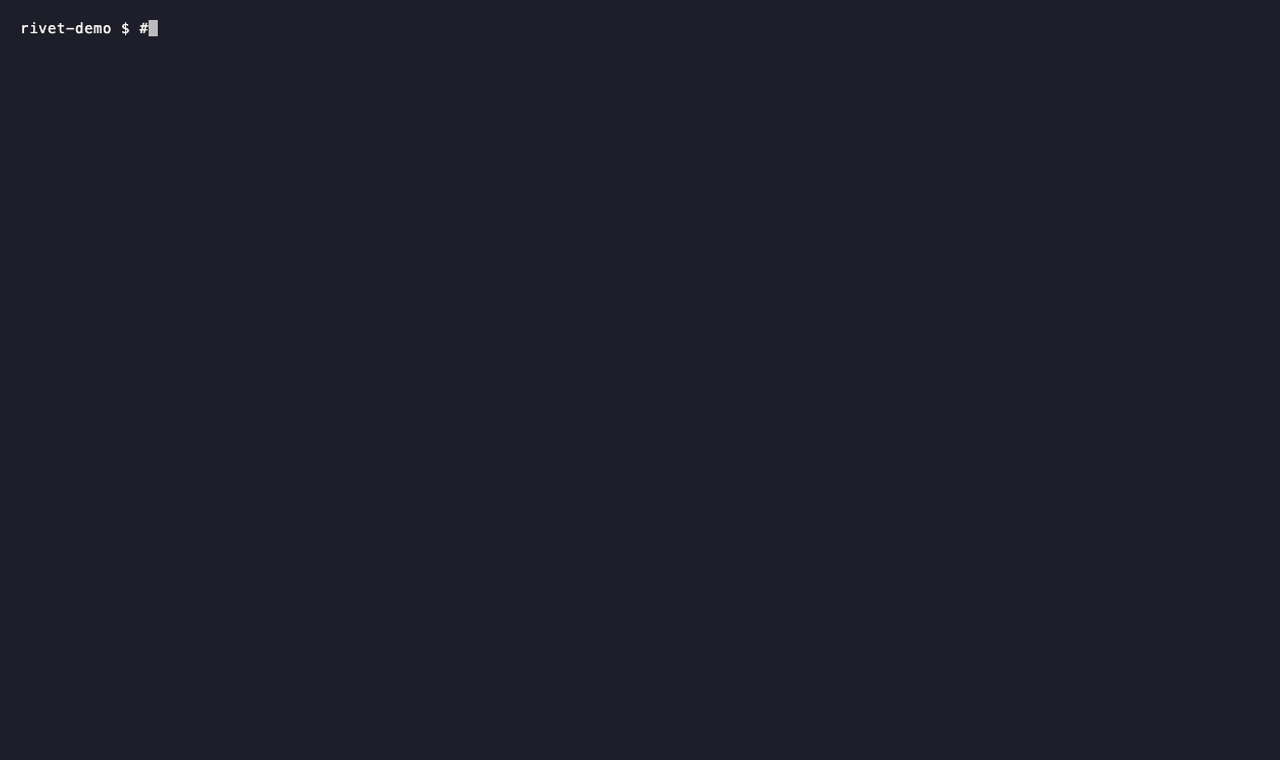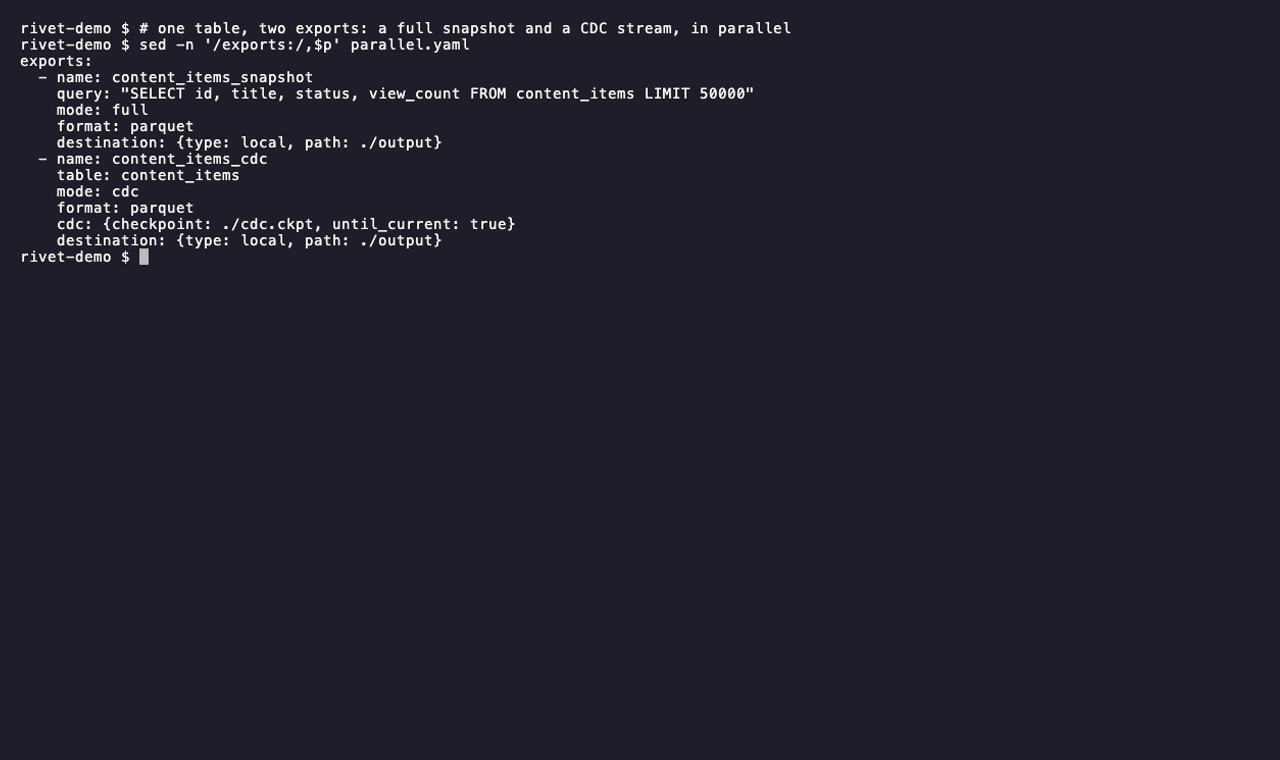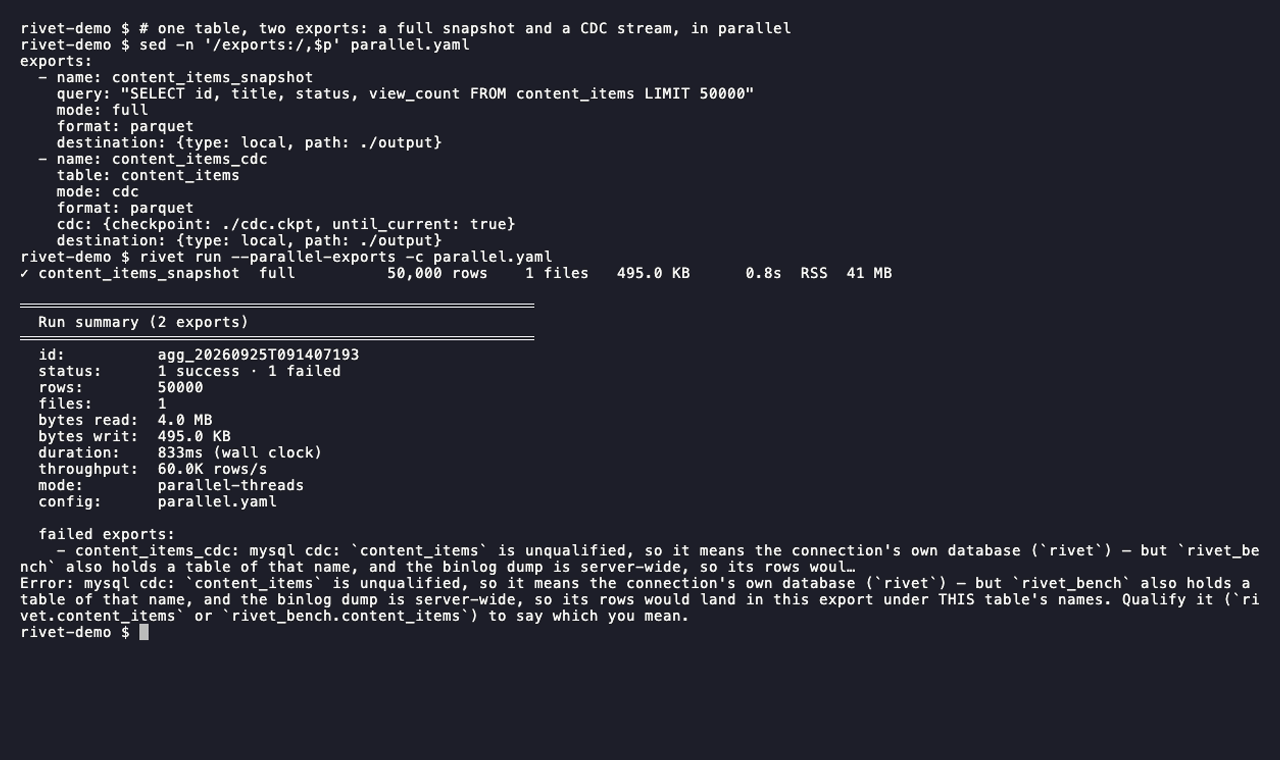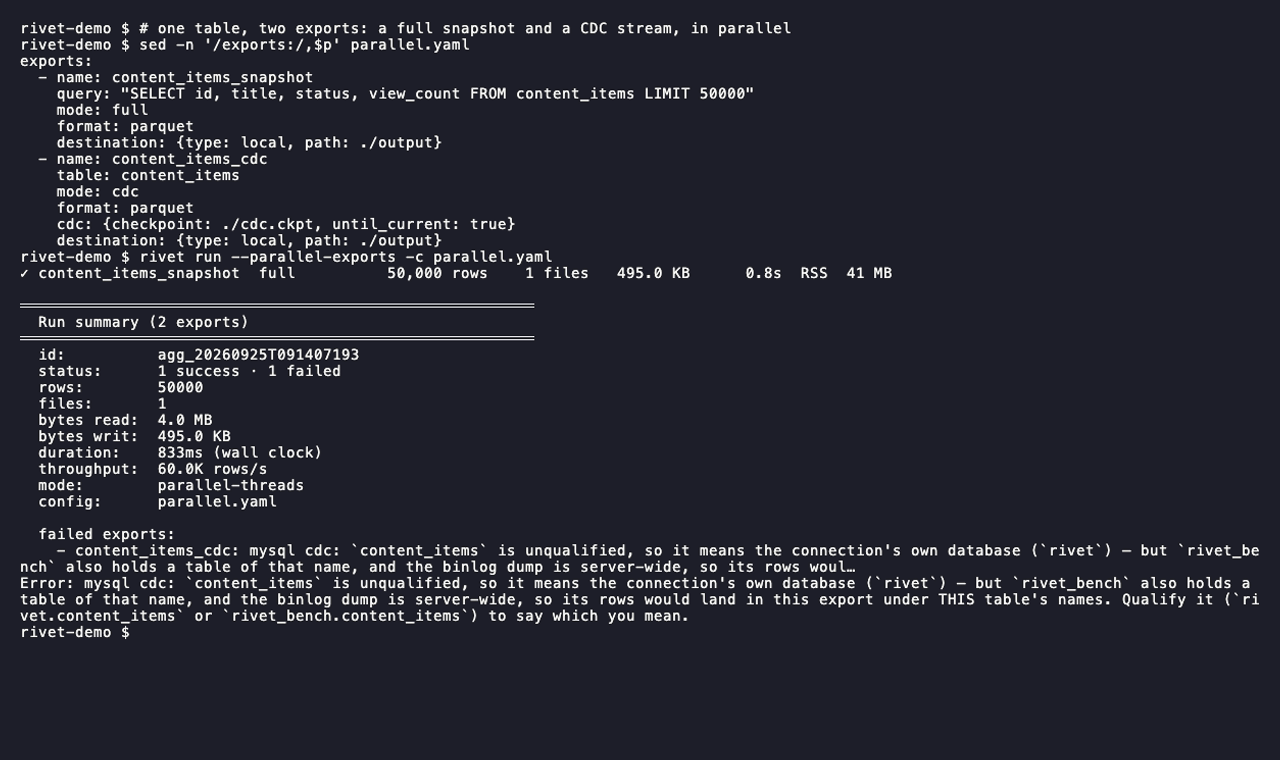
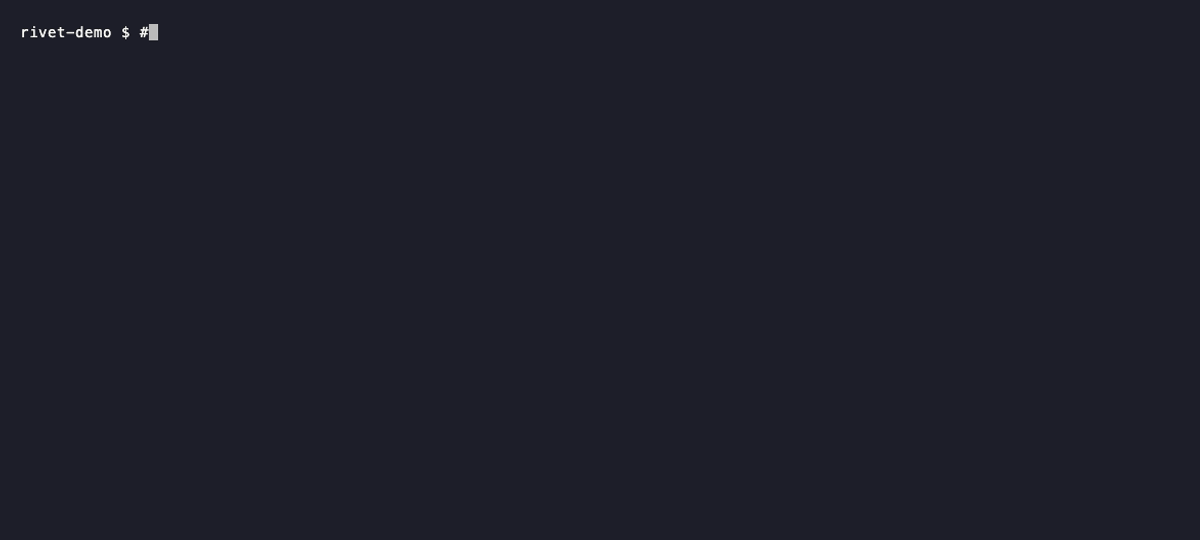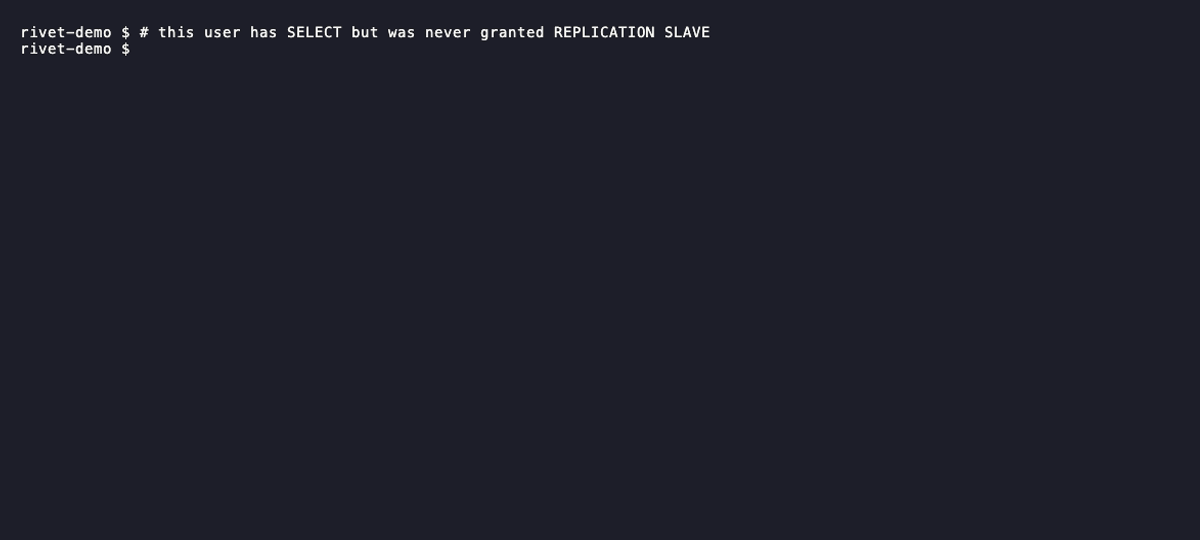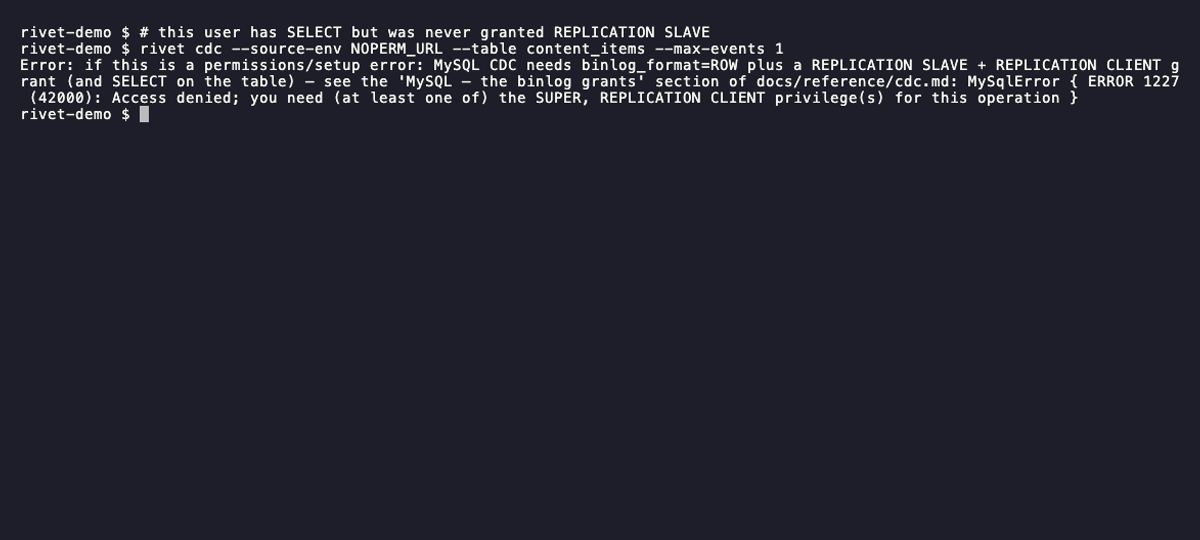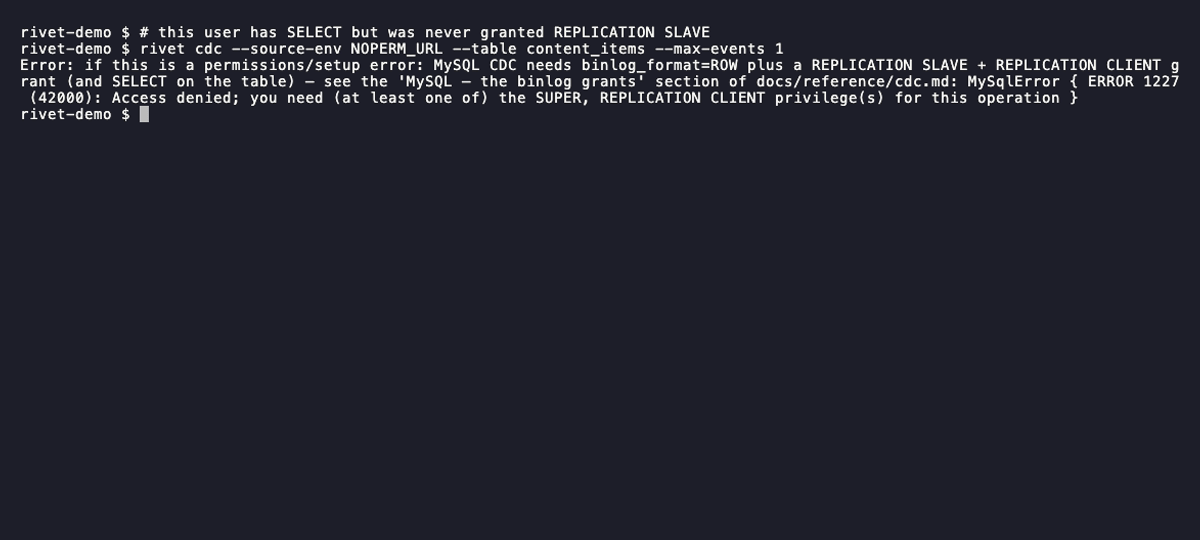
They are linked from the user-facing guides (see “Where they appear” below)
and are intentionally terminal-only: no narration, no cursor movement, no UI
chrome. They show exactly what rivet prints.
Regenerating
Prereqs (one-off):
brew install vhs # pulls ttyd + ffmpeg as dependencies
docker compose up -d postgres mysql
cargo build --release --bin rivet --bin seed
cargo run --release --bin seed -- --target postgres # ~500 rows in public.orders
Render all three:
python3 -m dev.pytools.render_gifs
Or just one:
python3 -m dev.pytools.render_gifs basic
python3 -m dev.pytools.render_gifs plan-apply
python3 -m dev.pytools.render_gifs reconcile-repair
python3 -m dev.pytools.render_gifs init-scaffold
python3 -m dev.pytools.render_gifs check-verdict
python3 -m dev.pytools.render_gifs inspect
python3 -m dev.pytools.render_gifs chunked-progress
python3 -m dev.pytools.render_gifs incremental-cursor
python3 -m dev.pytools.render_gifs discover-artifact
python3 -m dev.pytools.render_gifs plan-campaign # creates ~35 M rows in rivet_gif.*
python3 -m dev.pytools.render_gifs parallel-cards # 4 chunked exports, parent-side cards UI
python3 -m dev.pytools.render_gifs pool-detect # connect-time pooler/proxy warnings; see below
python3 -m dev.pytools.render_gifs doctor-gcs # real GCS via ADC; see below
The default invocation (no args) renders the eleven “always
reproducible” scenarios against Docker Compose (setup per scenario is
ephemeral — tables live under a dedicated rivet_gif schema that is
dropped on teardown). Two scenarios are opt-in:
pool-detectneeds thepooldocker-compose profile up so pgBouncer (6432) and ProxySQL (6033) are reachable:docker compose --profile pool up -d pgbouncer proxysql.doctor-gcsneedsgcloud auth application-default loginand a writable bucket.
plan-campaign takes ~60 s because it seeds 35 M narrow rows so the
cost-class classifier triggers shared_source_heavy_conflict.
The renderer creates an ephemeral /tmp/rivet-gif-<name> workdir, seeds any
fixture the scenario needs (the reconcile-repair tape uses a dedicated
10,000-row rivet_gif.events schema that is dropped on exit), invokes
vhs, and moves the rendered .gif next to the tape.
Environment the tapes assume
Each tape inherits DATABASE_URL, RIVET_BIN_DIR, and PSQL_BIN from
the renderer. The first Hide block prepends them to PATH and sets a
clean PS1='rivet-demo $ ' prompt, so the rendered terminal is
deterministic regardless of the user’s shell rc.
Conventions
- Relative
Outputpaths only. VHS rejects absolute paths. - No multi-line
Typeheredocs. VHS parses every newline as a tape command. Fixture YAMLs are written to the workdir by the renderer beforevhsruns (seefixture_chunked_setup). - Theme: Dracula, 14 pt; 1200 x 720 for
basic/plan-applyand 1280 x 780 forreconcile-repair(wider table output). - Typing speed: 30–35 ms/char. Fast enough to keep GIFs short; slow enough to read command lines.
Where they appear
- README.md — top-level table of contents.
- docs/README.md — “Start here” section.
- docs/getting-started.md (current 4-step layout):
basic.gifin §3 “Preflight & run”.check-verdict.gifin §3 (right after therivet checkblock).inspect.gifin §4 “Inspect & iterate”.
- docs/reference/cli.md —
plan-apply.gifnext torivet plan,reconcile-repair.gifnext torivet reconcile,parallel-cards.gifnext torivet run --parallel-export-processes. - docs/destinations/gcs.md —
doctor-gcs.gifin the “Verify” section. - docs/modes/chunked.md —
chunked-progress.gifin “Progress bar (chunked exports)”. - docs/modes/incremental.md —
incremental-cursor.gifin “What happens”. - docs/reference/init.md —
init-scaffold.gifin “Single table”;discover-artifact.gifin “Discovery artifact”. - docs/reference/prioritization.md —
plan-campaign.gifin “Viewing the output”. - docs/pilot/pilot-walkthrough.md —
init-scaffold.gif(Step 1),plan-apply.gif(Step 3),inspect.gif(Step 5),reconcile-repair.gif(Steps 6–8). - docs/pilot/demo-quickstart.md —
plan-apply.gif(Step 3),reconcile-repair.gif(Step 4). - docs/pilot/production-checklist.md —
pool-detect.gifin “Connection poolers and proxies”.
If you update a tape, re-render, and commit both the .tape and the
.gif together. The tape is the source; the GIF is the build artifact.
ADR-0001: State Update Invariants
Status: Accepted
Date: 2026-04
Context: Rivet supports retries, resumable chunked exports, incremental cursors, file manifests, and metrics history. As the number of state transitions grows, the ordering rules between them must be explicit so recovery behavior is predictable after any failure.
Problem
The pipeline writes to several independent state stores during a single export run:
- Cursor store — tracks the last extracted value for incremental exports
- File manifest — records the name, size, and row count of every produced file
- Chunk checkpoint — tracks individual chunk task lifecycle for resumable chunked exports
- Run metrics — records the final outcome, duration, and resource usage of each run
If these stores are updated in the wrong order — or if failures leave them in inconsistent states — recovery becomes ambiguous. Specifically:
- Should the next run re-extract rows already written to S3?
- Is a file in S3 tracked in the manifest?
- Is a chunk that crashed mid-export safe to resume?
Invariants
I1 — Finalize Before Write (FBW)
The temp file writer must be finalized before the file is transferred to the destination.
Rationale: A Parquet file without its footer, or a CSV without its last chunk, is corrupt. The destination always receives a complete file.
Current implementation: w.finish() is called before the dest.write() loop in pipeline/single.rs:run_single_export.
Failure mode if violated: Destination receives a truncated file; downstream consumers produce read errors.
I2 — Write Before Manifest (WBM)
The manifest entry (
record_file) is written only after the destination write succeeds. A failed write produces no manifest entry.
Rationale: The manifest represents files that are durably available at the destination. An entry for a file that was never written is a phantom record.
Current implementation: the manifest entry is recorded immediately after dest.write(...) returns Ok, via the shared pipeline/commit.rs:record_part seam (which calls st.record_file). record_part is invoked from run_single_export and every chunked runner, so the after-write ordering lives in one place rather than copied per runner.
Recovery behavior: If the process is killed between dest.write and record_file, the file exists at the destination but is absent from the manifest. This is safe — the file is not lost, only untracked. The manifest can be reconstructed.
I3 — Write Before Cursor (WBC)
The cursor advances only after all destination writes for the current batch succeed. On any write failure, the cursor stays at the prior position.
Rationale: If the cursor were advanced before the write, a subsequent run would skip rows that were never durably written. Keeping the cursor behind ensures at-least-once extraction semantics.
Current implementation: the cursor advance runs after the file-writing loop, via the shared pipeline/run_store.rs:RunStore seam (ADR-0018) called from run_single_export. If any dest.write returns Err, execution exits via ? before reaching the cursor update.
Consequence: On retry after a write failure, the same rows are re-extracted and re-written. Consumers of the destination must tolerate duplicate files.
I4 — Metric After Verdict (MAV)
The run metric is recorded after the final run outcome is determined — never during execution.
Rationale: A metric recorded before all artifacts are committed will show a misleading status. The status field in export_metrics always reflects the terminal state of the run.
Current implementation: state.record_metric_full(...) is called near the end of pipeline/job.rs:run_export_job (and run_export_job_with_chunk_source for apply), after the quality gate has resolved the result and the status field is set to "success" or "failed".
I5 — Chunk Task Acyclicity (CTA)
Chunk task state transitions are strictly forward:
pending → running → {completed | failed}. Acompletedtask is never re-claimed. Afailedtask can return torunningonly whileattempts < max_chunk_attempts.
Rationale: Resuming a completed chunk would produce duplicate output. Retrying beyond the configured limit would loop indefinitely on permanent errors.
Current implementation: The claim_next_chunk_task SQL query selects only rows where status = 'pending' OR (status = 'failed' AND attempts < max_chunk_attempts). Completed tasks are permanently excluded.
Recovery behavior: On resume after a crash, tasks left in running state are reset to pending via reset_stale_running_chunk_tasks before new claims are issued.
I6 — Finalize After All Complete (FAC)
finalize_chunk_run_completedmust only be called after all chunk tasks are incompletedstate. The pipeline enforces this by checkingcount_chunk_tasks_not_completed == 0before finalizing, and bailing with an error otherwise.
Rationale: A chunk run finalized with incomplete tasks cannot be reliably resumed. The final state would show completed while some data windows were never exported.
Current implementation: pipeline/chunked/sequential_checkpoint.rs:run_chunked_sequential_checkpoint checks count_chunk_tasks_not_completed and calls anyhow::bail! if any tasks remain. finalize_chunk_run_completed is only reached if that check passes.
I7 — Manifest Failure Is Non-Fatal (MFN)
Manifest write failures do not abort the export. Files already at the destination are not affected. The manifest can be reconstructed by querying the destination.
Rationale: The manifest is an observability aid, not a write gate. Aborting an otherwise successful export because a SQLite INSERT failed would be disproportionate.
Current implementation: All st.record_file(...) call sites use if let Err(e) = st.record_file(...) { log::warn!(...) }. The error is logged at WARN level so operators can observe manifest drift without causing the run to fail.
I8 — Finalize Order: Manifest → Verification → Report (FOR)
The end-of-run finalization hooks run in a fixed order:
- Manifest write —
pipeline::finalize::finalize_manifestwritesmanifest.jsonand (forsuccessruns)_SUCCESSto the destination. M1/M2/M7 from ADR-0012 ride on this step.- Manifest-aware validate — when
--validateis set,pipeline::finalize::finalize_validate_manifestverifies the just-written manifest against the destination listing (M5). Populatessummary.manifest_verification.- Run report —
pipeline::finalize::finalize_run_reportwrites.rivet/runs/<run_id>/{summary.md,summary.json}. The report includes the manifest-verification verdict only because step 2 ran first.- Notification —
notify::maybe_sendfires last so the Slack/webhook payload reflects the most complete summary.
Rationale: Reordering breaks the trust contract. If the report writes before the manifest is verified, downstream consumers (Airflow sensors, PR comments) read a verdict-less report. If the verification runs before the manifest is written, it has nothing to verify and falls back to the M6 legacy_run path on every clean run. If notification fires before the verification populates the summary, the message claims “validation passed” when in fact it ran on a stale snapshot.
Failure mode if violated: silent loss of the verdict in observability
artifacts. The exit code stays correct (the per-file row check has
already set summary.validated), but the verdict an operator opens the
report for is missing or stale.
Current implementation: pipeline::job::run_export_job and
run_export_job_with_chunk_source call the finalize hooks in this order
explicitly. The hooks themselves live in pipeline::finalize so the
order is visible in one place. Each step is best-effort and non-fatal
per I7, but the order itself is enforced by the call sites.
Recovery behaviour: any single step failing is logged at WARN and
the next step still runs. A failure at step 1 means step 2 will see a
manifest from the prior run (or none, triggering M6); step 3’s report
labels it accordingly. A failure at step 2 leaves
summary.manifest_verification = None, which the JSON serializer omits
(skip_serializing_if = Option::is_none), preserving 0.6.x report shape.
Failure Point Map
| Failure point | Cursor | Manifest | Metric | Recovery |
|---|---|---|---|---|
| Kill during extraction | not advanced | no entry | no entry | re-extract from last cursor |
| Kill after write, before manifest | not advanced | no entry | no entry | re-extract; duplicate file at destination |
| Kill after manifest, before cursor | not advanced | entry exists | no entry | re-extract; duplicate file + manifest entry |
| Kill after cursor update | advanced | entry exists | no entry | metric missing; next run starts from new cursor |
| Clean failure (Err return) | not advanced | no entry | failed status | normal retry |
| Clean success | advanced | entry exists | success status | — |
Test Coverage
Each invariant is covered by at least one automated test. tests/invariants.rs covers I1–I7 structural contracts. tests/journal_invariants.rs covers the RunJournal event-ordering contracts (plan snapshot recorded first, RunCompleted recorded last, chunk lifecycle ordering). tests/recovery.rs covers chunk checkpoint resume semantics (I5/I6). I8 (finalize order) is exercised by tests/offline/trust_artifacts_integration.rs §23 (ValidationOutcome wire contract): the run report’s validation.manifest sub-object is populated only when the verification step ran between the manifest write and the report write — the order test passes by virtue of the verdict appearing in the JSON. All test suites are run as semantic release gates in CI before any binary is produced.
Amendment 2026-09-26: the cursor and the manifest moved to the dispatcher
I3. The cursor now advances in the dispatcher (pipeline::job::execute_resolved_plan →
single::commit_incremental_cursor → RunStore), only after finalize_manifest has
written the destination manifest, and never when that write failed. A cursor-write failure
after the manifest is logged and does not fail the run: the next run re-exports from the
prior cursor (at-least-once).
I4. run_export_job and run_export_job_with_chunk_source both funnel into
execute_resolved_plan, which is now the one call site of the finalize steps.
I8. Step 1 is no longer non-fatal. A manifest that cannot be written fails the run: the
status becomes failed, the run-status ledger row is re-closed, the cursor is not advanced,
and the exit is non-zero (it outranks a reconcile verdict). The later steps remain
best-effort. The order is manifest → cursor → validate → metrics → report → notification.
ADR-0002: CLI Product vs Library
Status: Accepted
Date: 2026-04
Context: Rivet ships as a single crate (rivet-cli on crates.io) that produces both a library target (rivet) and a binary target (rivet). The default Rust project layout creates accidental public API surface — any module marked pub in lib.rs is reachable by external consumers. This ADR decides intentional product boundaries.
Decision
Rivet is a CLI-first product. The library crate (rivet) is not a stable public API.
Rivet’s primary deliverable is the rivet binary: end users invoke it from the command line to export data from PostgreSQL/MySQL databases to Parquet/CSV files. No embedding contract, no programmatic API stability guarantee, no semver guarantee on internal types.
The library target exists solely to enable Rust’s integration test harness (tests/*.rs must link against a library crate). It is an implementation artifact, not a product surface.
Rationale
Why CLI-first, not library
- Use case fit: The tool solves a concrete operational task (export data). Embedding it in other Rust programs is not a stated use case and adds maintenance overhead (API stability, semver discipline, docs).
- Crate name signals intent: The crate is published as
rivet-cli, notrivet. The-clisuffix is the standard Rust convention for CLI tools that are not intended as embeddable libraries. - Binary is the integration point: All known consumers use the binary — via shell scripts, Docker images, CI pipelines. No known Rust consumer imports the library crate.
- Internal types are not API-stable:
ResolvedRunPlan,ExtractionStrategy,StateStore,SourceTuningand similar types evolve to serve the pipeline’s execution model. Treating them as public API would force design compromises on internal evolution.
Why the library crate still exists
Rust’s integration tests (tests/ directory) must link against a library target. There is no way to run integration tests against a binary-only crate. The library crate is the Rust mechanism that grants tests/*.rs access to internal implementations.
Module Visibility Rules
Reflects src/lib.rs as of v0.8.0. pub modules are reachable cross-crate
only so tests/*.rs (and the in-crate MCP surface) can link them — none
carry a stability guarantee (see Consequences #1). pub here means “the test
harness needs it”, not “public API”.
| Module | lib.rs visibility | Reason |
|---|---|---|
config | pub | Integration tests import config types (Config, ExportMode, …) |
error | pub | Result alias surfaced for the test harness |
format | pub | Integration tests validate format output (CsvFormat, ParquetFormat, …) |
journal | pub | RunJournal event log — trust-contract type asserted in tests |
manifest | pub | RunManifest wire schema (ADR-0012) — asserted in trust-artifact tests |
pipeline | pub | Integration tests call pipeline functions (generate_chunks, classify_error, …) |
preflight | pub | Integration tests exercise diagnostics / type-report |
resource | pub | Integration tests verify memory utilities (get_rss_mb, check_memory, …) |
source | pub | Live integration tests construct ExportRequest / introspection directly |
state | pub | Integration tests verify state invariants (StateStore, SchemaColumn) |
tuning | pub | Governor / adaptive tuning tests link it (ADR-0019) |
types | pub | Type-roundtrip tests assert RivetType / fidelity mappings (ADR-0014) |
mcp | pub | Rivet’s read-only DB-introspection MCP server (run_stdio) — public so the rivet-mcp binary in src/bin/rivet-mcp.rs can link it |
cli | pub | The rivet binary’s entry point (run_binary) — public so src/main.rs can link it, like mcp |
redact | pub | Cross-cutting credential-redaction helper, asserted in tests |
destination_for_tests | pub | Thin test-only shim over the pub(crate) destination module |
destination | pub(crate) | Internal write backends — exercised via destination_for_tests |
enrich | pub(crate) | Internal pipeline module |
notify | pub(crate) | Internal notification module |
plan | pub(crate) | Internal execution contract — consumed by pipeline, not by tests |
quality | pub(crate) | Internal quality gate |
sql | pub(crate) | SQL identifier quoting (quote_ident) — internal utility, not a product surface |
test_hook | pub(crate) | Internal fault-injection points for tests |
Consequences
- No stability guarantee: Consumers who depend on internal modules (any non-
pubmodule above, or sub-items ofpubmodules not explicitly documented) accept breakage at any patch release. - Docs reflect intent:
cargo docwill not generate docs forpub(crate)modules, reducing confusion about the intended API surface. - Binary compilation path:
src/main.rsdeclares all modules privately viamod— it never uses the library crate. The two targets are independent compilation units that happen to share source files.- Amended 2026-09-27:
src/main.rsnow callsrivet::cli::run_binary()and declares no modules. Two compilation units compiled every module twice and ran each unit test twice (3,196 lib + 3,379 bin tests from the same sources). Every CI job and every mutation build paid that twice. The CLI-first decision above is unchanged:cliispubonly so the binary links it, asmcpis forrivet-mcp.
- Amended 2026-09-27:
- Future library path: If Rivet ever offers a stable embedding API, a separate
rivet-enginecrate should be extracted with its own semver-tracked surface, rather than promoting internal types topub.- Amended by ADR-0026: a minimal first-party extension seam (the
types/types::targetresolution items) is now stability-tracked in-crate for the privaterivet-procompanion. The fullrivet-engineextraction is deferred until a non-first-party external consumer appears.
- Amended by ADR-0026: a minimal first-party extension seam (the
Alternatives Considered
Make everything pub(crate), move tests inline
Moving tests/*.rs into the library as #[cfg(test)] mod tests would allow all modules to be pub(crate). This was rejected because:
- Integration tests (especially chunk/state invariants) benefit from the clean external-crate perspective
tests/layout is idiomatic and easier to locate
Extract a rivet-engine crate now
Premature. No known consumers exist. The extraction cost (separate crate, two Cargo.toml files, re-exports) is not justified until there is a concrete embedding use case.
ADR-0003: Layer Classification
Status: Accepted
Date: 2026-04
Context: Rivet’s pipeline has grown to include preflight analysis, execution orchestration, state management, and observability. Without explicit layer assignments, modules accumulate mixed responsibilities — execution code makes semantic decisions, and observability code owns runtime logic.
Decision
Rivet’s modules are classified into four layers. Each module belongs to exactly one layer. The coordinator (pipeline/mod.rs) is the only module permitted to bridge layers — it is the seam between planning, execution, and persistence.
Layer Definitions
L1 — Planning (Decision)
Responsible for: deriving what a run means before it starts. No I/O, no DB connections, no state reads.
| Module | Responsibility |
|---|---|
config/ | Raw YAML model — user-facing config shapes |
plan/mod.rs | ResolvedRunPlan, ExtractionStrategy with behavioral contracts |
plan/validate.rs | Compatibility validation — produces Diagnostic list, no side effects |
tuning/ | Tuning profiles and parameter resolution |
preflight/ | Pre-run source analysis (reads DB metadata, emits diagnostics) |
Rule: Planning modules must not write state, open data connections, or modify files.
L2 — Execution
Responsible for: running the resolved plan. Reads source data, writes destination files. May write post-execution state (invariant-ordered, see ADR-0001).
| Module | Responsibility |
|---|---|
pipeline/single.rs | Single-query export (Snapshot, Incremental, TimeWindow) |
pipeline/chunked/ | Chunked export: sequential, parallel-simple, parallel-checkpoint (exec.rs, sequential_checkpoint.rs, parallel_checkpoint.rs, resume_m8.rs, …) |
pipeline/sink/ | Local temp-file write path; inline quality checks (mod.rs, cursor.rs, pipelined.rs) |
pipeline/retry.rs | Error classification for retry decisions |
pipeline/validate.rs | Post-write row-count verification |
source/ | DB connection and Arrow batch extraction |
destination/ | Write to local, S3, GCS, stdout |
format/ | Parquet/CSV serialization |
quality/ | Quality check evaluation (invoked from sink) |
enrich/ | Meta-column injection into Arrow batches |
Rule: Execution modules receive a ResolvedRunPlan and execute it. They must not re-derive semantic decisions. Post-execution state writes (cursor, manifest, schema) are permitted only after the execution succeeds and only in the order mandated by ADR-0001.
L3 — Persistence
Responsible for: durable state across runs. No execution logic.
| Module | Responsibility |
|---|---|
state/mod.rs | StateStore entry point |
state/migrations.rs | Schema version + SQLite/PostgreSQL migration ladders and runners |
state/cursor.rs | Incremental cursor positions (export_state) |
state/checkpoint.rs | Chunk run/task lifecycle (chunk_run, chunk_task) |
state/metrics.rs | Run outcome history (export_metrics) |
state/file_log.rs | Per-export file ledger (file_log; renamed from file_manifest in schema v8) |
state/schema.rs | Schema snapshot history (export_schema) |
Rule: Persistence modules must not contain execution logic or make semantic decisions about when to write.
L4 — Observability
Responsible for: surfacing what happened without affecting execution or state.
| Module | Responsibility |
|---|---|
pipeline/summary.rs | RunSummary — data accumulator for run metrics, printed at end-of-run |
journal.rs (top-level) | RunJournal — typed event log answering the four DoD observability questions |
pipeline/progress.rs | Terminal progress bar for chunked exports |
pipeline/cli.rs | CLI display of state, metrics, files, chunk checkpoints |
notify/ | Slack notifications triggered by run outcome |
resource/ | RSS memory measurement |
Rule: Observability modules must not write state, make execution decisions, or alter the pipeline path.
Coordinator (crosses layers by design)
| Module | Responsibility |
|---|---|
pipeline/mod.rs | Reads config → builds plan → dispatches execution → records metric → notifies |
pipeline/job.rs | Per-export coordinator: builds plan → dispatches single/chunked → finalizes manifest/report/notification |
pipeline/{validate_cmd,reconcile_cmd,repair_cmd}.rs | Standalone subcommand drivers — re-run a single check (manifest verify / source COUNT / repair) against an existing destination, no extraction. Do not bridge layers as freely as pipeline/mod.rs; each is a thin Coordinator-shaped driver for one ADR-0012 concern. |
pipeline/mod.rs is the only module permitted to touch all three layers. It must remain thin: its role is orchestration, not logic ownership.
RunOptions<'a> is defined in pipeline/run.rs (the extracted rivet run orchestrator — pipeline/mod.rs is a thin facade that re-exports it as pipeline::RunOptions / pipeline::run) and passed through the execution stack. It bundles the per-run CLI flags (validate, reconcile, resume, force, params) as a named struct, replacing a sequence of positional bool arguments that were invisible at call sites and prone to transposition bugs. The coordinator constructs RunOptions once from the public run() signature, then passes it to run_export_job and (via individual fields) to run_exports_as_child_processes.
Trust contract types (no layer — shared schema)
A small set of modules holds wire-format types that cross every layer boundary without making decisions of their own. They are not classified under L1–L4 because they are pure data carriers + pure functions.
| Module | Responsibility |
|---|---|
manifest.rs (top-level) | RunManifest / ManifestPart / ManifestStatus wire schema; validate_self_consistency, success_marker_body, parse_success_marker pure helpers |
pipeline/resume_decisions.rs | Pure M8 decision matrix (ResumePlan, ResumeDecision); no I/O — fits L1 Planning by classification but is grouped here because its contract is the decision schema |
destination::ObjectMeta | Read-side metadata the Observability layer (validate_manifest) and Planning layer (resume_decisions) both consume |
Rule: trust-contract modules must not depend on L2/L3/L4 modules. They are leaves of the dependency graph; everything else may import them.
Known Mixing (Accepted)
pipeline/single.rs — execution + bounded persistence writes
run_single_export writes three state artifacts after a successful write:
- File manifest entry (
record_file) — I2 - Cursor advance (
update) — I3 - Schema snapshot (
store_schema/detect_schema_change) — observability
These writes are post-execution, invariant-ordered, and have no effect on the execution path. This mixing is accepted as a bounded exception documented by ADR-0001.
Future: If the execution/persistence boundary is ever hardened further, run_single_export could return a SingleRunResult struct carrying the data to be persisted, and the coordinator would handle the writes. This is deferred — the current mixing is contained and tested.
Consequences
- Each module’s
//! **Layer: …**comment at the top declares its classification. - New modules must declare their layer.
- Code reviews should flag layer violations: planning code making runtime decisions, execution code re-reading raw config, persistence code containing branching logic.
ExtractionStrategybehavioral methods (needs_cursor_state,is_resumable,requires_parallel_execution,resolve_query) keep layer-specific decisions in the planning layer rather than in pipeline dispatch code.
ADR-0004: Destination Write Contracts
Status: Accepted
Date: 2026-04
Context: Rivet writes exported data to four backends — local filesystem, S3, GCS, and stdout. Their failure modes, commit boundaries, and write guarantees differ. The planning and recovery layers must be able to reason about these differences without inspecting backend internals.
Problem
State and manifest writes (ADR-0001 invariants I2–I4) must happen only after the destination write is durably committed. But “committed” means different things for different backends:
- Local writes stage into a dot-prefixed temp file in the target directory and commit with an atomic same-filesystem
rename(OPT-6), so a failure leaves nothing at the final path — retry-safe, no partial-write risk. - S3 and GCS object writes are not committed until the writer handle is closed (
dst.close()); a mid-upload failure leaves nothing at the destination. - stdout streams data immediately with no atomic commit point; a retry produces duplicate or corrupt output.
Without an explicit contract, the pipeline has no safe way to determine: when is it safe to advance the cursor? when is it safe to record a manifest entry? is a failed write safe to retry automatically?
Decision
Introduce two types in src/destination/mod.rs:
WriteCommitProtocol— when a write becomes durably committed and visible to readers.DestinationCapabilities— the full set of operational guarantees for a backend.
Add a capabilities() method to the Destination trait so each backend declares its own contract. The pipeline can inspect capabilities without downcasting.
Per-Backend Capability Table
| Backend | commit_protocol | idempotent_overwrite | retry_safe | partial_write_risk |
|---|---|---|---|---|
LocalDestination | Atomic | true | true | false |
S3Destination | FinalizeOnClose | true | true | false |
GcsDestination | FinalizeOnClose | true | true | false |
AzureDestination | FinalizeOnClose | true | true | false |
StdoutDestination | Streaming | false | false | true |
S3Destination / GcsDestination / AzureDestination are all type aliases for
CloudDestination<B> (src/destination/{s3,gcs,azure}.rs); they share one
capabilities() body in cloud.rs, so the three cloud rows are identical by
construction, not by coincidence.
WriteCommitProtocol semantics
write() returns Ok(WriteOutcome) (not Ok(())): on success the file is
present per the commit protocol below, and the outcome carries the store’s own
content checksum when the upload reported one (GCS/Azure single Put Blob MD5,
S3 single PutObject ETag), which the commit path compares to the locally
computed MD5 for a fail-fast, no-download transit-integrity check. None for
backends/paths that report none (local FS, streamed multipart).
Atomic: a successfulwrite()means the full file is present at the destination. The only Atomic backend (LocalDestination) stages into a temp file and commits via atomic same-filesystem rename, so a failure leaves nothing at the final path (partial_write_risk = false,retry_safe = true); an Atomic backend that could leave a partial artifact would declarepartial_write_risk = true, in which case the caller would need to clean up before retrying.FinalizeOnClose: The object is committed only when the internal writer handle is closed. A mid-upload failure leaves nothing at the destination — the object is never partially visible to readers.retry_safe = truebecause a failed upload can be retried from scratch with no cleanup needed.Streaming: Data is written to an unbuffered output with no atomic commit boundary. Partial output may be observable beforewrite()returns. Retrying after failure produces duplicate or corrupt output. There is no safe commit moment.
Alignment with ADR-0001 Invariants I2–I4
ADR-0001 requires that state writes (manifest, cursor, schema) happen only after the destination write succeeds. This ADR makes the commit boundary explicit:
- I2 (Write Before Manifest):
record_fileis called afterdest.write()returnsOk(()). ForAtomicandFinalizeOnClosebackends, this is the commit boundary. - I3 (Write Before Cursor):
st.update()is called after the file-writing loop. ForAtomicandFinalizeOnClosebackends, all files are committed before the cursor advances. - I4 (Metric After Verdict): Unchanged — metrics are recorded at the terminal state of the run.
The ordering is made explicit in the source at the shared commit seam: pipeline/commit.rs::{write_part_file, record_part} (which every runner, including pipeline/single.rs:run_single_export at its record_part call, goes through) documents that state writes happen only after destination.write() returns Ok.
Runtime Capability Inspection
pipeline/single.rs:run_single_export inspects dest.capabilities() at runtime and logs the commit protocol for every run:
export 'orders': destination commit_protocol=Atomic idempotent=true retry_safe=true partial_risk=false
When a destination that is not retry-safe (retry_safe = false) is configured with automatic retries (max_retries > 0), a WARN is emitted once per export at capability-logging time, before any retry occurs:
export 'orders': stdout destination is not retry-safe (max_retries=2); partial artifacts may exist at destination on failure — manual cleanup may be needed
This surfaces retry-safety mismatches without blocking the run. With current backends this can fire only for stdout (Streaming); local, S3, GCS and Azure all declare retry_safe: true.
Known Gap: stdout state writes
StdoutDestination has commit_protocol: Streaming. There is no safe moment to advance state after a streaming write — any output may have been partially consumed by the reader before write() returns.
Current behavior: The pipeline does not special-case stdout for state writes. If stdout is used as a destination, cursor and manifest writes proceed as normal after write() returns. This is safe only because stdout is used exclusively in development/piping scenarios where state persistence is not meaningful. The plan validation layer rejects stdout + chunked and stdout + max_file_size combinations via Rejected diagnostics before execution starts.
If stdout is ever used in a production pipeline with cursor or manifest state, this gap must be addressed. The fix is for the pipeline to inspect capabilities().commit_protocol and skip or warn on state writes when Streaming.
Consequences
- Each backend’s operational contract is now machine-readable and located with the implementation.
- The planning and recovery layers can inspect
capabilities()without coupling to backend types. - The stdout gap is documented rather than hidden; future callers are warned.
- No breaking changes —
capabilities()is a new trait method with a defined contract.
ADR-0005: Plan/Apply Contracts
Status: Accepted
Date: 2026-04
Context: Rivet implements a Terraform-style plan/apply workflow for data extracts. rivet plan generates a sealed PlanArtifact that captures the full execution intent at a point in time. rivet apply consumes the artifact and executes it. Because plan time and apply time are separated, the contracts between them must be explicit to ensure predictable, auditable execution.
Problem
Separating planning from execution introduces a temporal gap between analysis and action:
- Data in the source may change between plan and apply.
- The cursor may advance (another incremental run completed).
- The config file may be edited.
- The artifact may be arbitrarily old.
Without explicit contracts, rivet apply cannot reason about whether the artifact is still valid to execute, and operators cannot reason about what guarantees the system provides.
Contracts
PA1 — Artifact Is the Communication Channel (ACC)
A
PlanArtifactis the sole input torivet apply. Apply does not re-read the config file, re-run preflight queries, or re-compute chunk boundaries. Everything needed for execution is embedded in the artifact.
Rationale: Decoupling apply from config re-parsing enables apply to work from a sealed, auditable snapshot. The artifact can be stored as a CI artifact, committed to a PR, or reviewed before execution.
Consequence: Any change to config, queries, or chunk boundaries after rivet plan requires regenerating the artifact with a new rivet plan invocation. Applying a stale artifact against a changed config is detected by staleness checks (PA3) and fingerprint logging (PA6), not by a config re-parse.
PA2 — Artifact Immutability (AI)
A
PlanArtifactfile must not be modified after it is written byrivet plan.rivet applytreats the artifact as a sealed, read-only input.
Rationale: The artifact’s plan_id and created_at field are set at plan time. Any post-generation modification breaks the audit trail and the staleness check. The artifact is a point-in-time snapshot, not a mutable config.
Current implementation: PlanArtifact is deserialized from the file at apply time. No write-back or in-place mutation occurs. The file on disk is never opened for writing by apply_cmd. [Update: immutability is now machine-enforced, not just an operator convention — see PA10.]
PA3 — Staleness Boundary (SB)
rivet applyenforces a maximum age between plan time and apply time:
- Age < 1 hour: apply proceeds silently.
- 1 hour ≤ age < 24 hours: apply emits a
WARNlog and proceeds.- Age ≥ 24 hours: apply rejects the artifact with an error unless
--forceis passed.
Rationale: The value of a pre-computed plan degrades as the source drifts. An artifact that is hours old may describe chunk boundaries that are no longer representative of the current data distribution. The hard error threshold prevents accidentally applying a week-old plan that was forgotten in a directory.
Current implementation: PlanArtifact::staleness(warn_after, error_after) computes the age from created_at to Utc::now(). apply_cmd::run_apply_command calls this and either warns, bails, or proceeds. The expires_at field in the artifact JSON provides the deadline in a human-readable form.
Test coverage: test staleness_fresh, test staleness_expired_artifact in plan/artifact.rs.
PA4 — Cursor Snapshot Integrity (CSI)
For
Incrementalexports,rivet applyverifies that the cursor value inStateStoreat apply time equals the cursor value captured inComputedPlanData.cursor_snapshotat plan time. If they differ, apply rejects the artifact.
Rationale: If another rivet run completed between plan and apply, the cursor has advanced. Applying the artifact would re-extract rows that were already exported and written to the destination, producing duplicate output. The cursor snapshot check makes this divergence explicit rather than silently producing duplicates.
Failure mode: If cursor drift is detected and --force is not passed, apply exits with:
plan 'orders': cursor has drifted since plan was generated
(plan snapshot: "2026-04-14T09:00:00Z", current: "2026-04-14T11:00:00Z")
Regenerate with `rivet plan` or pass --force to skip this check.
Scope: This check applies only to Incremental exports (where cursor_snapshot is non-None). Snapshot, TimeWindow, and Chunked exports have no cursor and are not subject to this check. Chunked exports instead have partition-level progression tracked by ADR-0008 (committed) and ADR-0009 (verified).
Cursor policy: How the snapshot string is produced (single column vs COALESCE progression) is defined in ADR-0007; PA4 compares opaque strings regardless of mode.
Current implementation: apply_cmd::run_apply_command calls PlanArtifact::cursor_matches(current). cursor_matches returns true when cursor_snapshot is None (all non-incremental strategies).
Test coverage: test cursor_matches_none_snapshot, test cursor_matches_incremental in plan/artifact.rs.
PA5 — Chunk Range Monotonicity (CRM)
Chunk ranges stored in
ComputedPlanData.chunk_rangesmust satisfy:
- Each range
(start, end)satisfiesstart ≤ end.- Consecutive ranges
(s1, e1)and(s2, e2)satisfys2 = e1 + 1(no gaps, no overlaps).An empty
chunk_rangesis valid for non-Chunked strategies.
Rationale: These invariants mirror generate_chunks output guarantees (see math.rs). At apply time, ranges are replayed as ChunkSource::Precomputed and passed directly to build_chunk_query_sql without re-validation. A non-monotonic or overlapping range would produce incorrect WHERE predicates.
Current implementation: detect_and_generate_chunks produces ranges via generate_chunks which guarantees monotonicity by construction. The artifact round-trips ranges through JSON without mutation.
Future: An explicit PlanArtifact::validate_chunk_ranges() method that enforces this invariant before execution is a candidate for a future hardening pass.
PA6 — Fingerprint Stability (FS)
For Chunked exports, the
plan_fingerprintfield is computed at plan time from(base_query, chunk_column, chunk_size, chunk_count, dense, by_days)viachunk_plan_fingerprint. This fingerprint is embedded in the artifact and displayed inrivet plan’s summary output.
Rationale: If the config changes between plan and apply (query rewritten, chunk_size changed), the fingerprint computed from the new config would differ from the artifact’s fingerprint. This mismatch is an operator signal that the artifact may no longer represent the intended extraction, even if apply can technically proceed.
Current behavior: The fingerprint is displayed only at plan time (PlanArtifact::print_summary); nothing at apply time reads, logs, or enforces it. The operator is responsible for regenerating the plan when the config changes.
Alignment with ADR-0001 I5: The chunk checkpoint system (chunk_run.plan_hash) enforces fingerprint matching at resume time. The plan artifact fingerprint is a complementary audit signal, not a resume gate.
PA7 — State Writes Unchanged (SWU)
rivet applyuses the same state persistence paths asrivet run. File manifest, cursor updates, and run metrics are written viaStateStoreusing the same invariants defined in ADR-0001.
Rationale: The artifact replaces chunk boundary detection only. It does not change the semantics of state persistence. All ADR-0001 invariants (I1–I7) apply unchanged to an apply run.
Consequence: The StateStore file (.rivet_state.db) used by apply is resolved primarily from the directory of the artifact’s recorded config_path when that directory exists (F13, 0.7.5 audit — this keeps apply consistent with rivet run’s state location). Only if the config directory is gone, or the artifact predates 0.7.5 and recorded no config path, does apply fall back to the plan file’s own directory, emitting a WARN about the divergence.
PA8 — Diagnostics Are Advisory (DAA)
Preflight diagnostics embedded in
PlanDiagnostics—verdict,warnings,recommended_profile— are advisory metadata captured at plan time. They do not gate execution at apply time. A plan withverdict: "Unsafe"can be applied; the verdict is preserved for auditability.
Rationale: The decision to apply a plan is the operator’s. A degraded verdict is information, not a veto. Vetoing at apply time would be surprising because the operator already reviewed the plan before deciding to apply.
Contrast with plan validation: validate_plan(&plan) (ADR-0003) is re-run at apply time with Rejected diagnostics as hard gates. Plan validation checks structural constraints (e.g., stdout + chunked). Preflight diagnostics check operational health (e.g., missing index). Only the former is enforced at apply time.
PA9 — Artifact Credential Redaction (ACR)
A
PlanArtifactmust not contain plaintext credentials. Before the resolved plan is embedded,PlanArtifact::newrunsSourceConfig::redact_for_artifact:
password→ always stripped (set toNone).urlwithscheme://user[:password]@…→ userinfo replaced withREDACTED(host/port/path preserved).url_env,url_file,password_env— preserved. They are references (env var names, file paths) that apply needs to re-resolve credentials at runtime; not secrets themselves.host,port,user,database— preserved (infrastructure metadata, not credentials).
Rationale: Plan artifacts are designed to be stored, committed to PRs, or shared for review (PA1, PA2). Historic config patterns with inline password: or credentials-in-URL would leak into every artifact. Silently stripping plaintext (rather than failing loudly) keeps the plan/apply workflow operational while making artifacts safe-by-default.
Operator contract: When redaction runs, Rivet logs a WARN: plan '<name>': plaintext credentials stripped from artifact — apply time must have equivalent env/file-based auth available. Operators must ensure url_env / password_env / url_file equivalents are set in the apply environment. For existing YAML configs with plaintext password, migrate to password_env before relying on plan/apply.
Scope of protection: PA9 covers only the source-side credentials embedded in ResolvedRunPlan.source. Destination secrets are already ADR-0004-compliant (S3/GCS use env/file references via access_key_env, secret_key_env, credentials_file; no plaintext equivalents exist in the destination schema).
Current implementation: SourceConfig::redact_for_artifact in src/config/source.rs; called from PlanArtifact::new in src/plan/artifact.rs. URL parsing uses a path-aware @ scan so @ in a query string or path does not trigger false redaction.
Test coverage: redact_plaintext_password_stripped, redact_password_embedded_in_url, redact_url_without_userinfo_is_unchanged, redact_env_references_are_preserved, redact_does_not_confuse_at_in_path in src/config/tests/secops.rs; artifact_strips_plaintext_password_from_source, artifact_strips_credentials_from_url in src/plan/artifact.rs.
PA10 — Artifact Tamper-Evidence (ATE)
Before running any query,
rivet applycallsPlanArtifact::verify_integrity()and rejects an artifact whoseresolved_planwas edited after planning. Unlike staleness (PA3) and cursor drift (PA4), this gate is not bypassable by--force— a hand-edited execution contract is never something the operator can opt into; the only correct recovery is to re-runrivet plan.
Rationale: PA2 declares the artifact a sealed, read-only input; PA10 is its machine enforcement. Without it, a post-plan edit would execute silently with a plan_id/created_at audit trail that no longer describes what ran.
Current implementation: PlanArtifact::verify_integrity in src/plan/artifact.rs (integrity checksum over the resolved plan), called from apply_cmd::run_apply_command before any state or source access (finding #16).
Contract Summary Table
| ID | Name | Enforced? | On Violation |
|---|---|---|---|
| PA1 | Artifact Is the Communication Channel | yes | apply cannot run without an artifact |
| PA2 | Artifact Immutability | yes (integrity checksum, PA10) | bail! — not --force-bypassable |
| PA3 | Staleness Boundary | yes (hard at 24 h) | bail! unless --force |
| PA4 | Cursor Snapshot Integrity | yes (Incremental only) | bail! — regenerate plan |
| PA5 | Chunk Range Monotonicity | by construction | no explicit runtime gate |
| PA6 | Fingerprint Stability | advisory (plan-time display only) | operator responsibility |
| PA7 | State Writes Unchanged | yes (ADR-0001) | same failure modes as rivet run |
| PA8 | Diagnostics Are Advisory | explicit non-enforcement | verdict visible in artifact; no gate |
| PA9 | Artifact Credential Redaction | yes (on PlanArtifact::new) | plaintext password/URL userinfo silently stripped; WARN logged |
| PA10 | Artifact Tamper-Evidence | yes (verify_integrity before any query) | bail! — not --force-bypassable |
Interaction with Existing ADRs
| ADR | Interaction |
|---|---|
| ADR-0001 (State Update Invariants) | PA7 — state write ordering (I1–I7) applies unchanged to apply runs |
| ADR-0003 (Layer Classification) | plan_cmd.rs and apply_cmd.rs are coordinator-layer modules; they bridge plan, execution, and persistence exactly like pipeline/mod.rs:run_export_job |
| ADR-0004 (Destination Write Contracts) | PA7 — destination commit protocols apply unchanged; apply does not change write semantics |
Failure Point Map
| Scenario | PA3 | PA4 | State after |
|---|---|---|---|
| Plan generated, applied < 1h later | Fresh | Matches (if no other run) | Normal success |
| Plan generated, applied 2h later | Warn | Matches (if no other run) | Normal success with warning logged |
| Plan generated, other incremental run completed, apply attempted | Fresh | Drift detected → bail | No state written (apply never ran) |
| Plan generated, applied 25h later | Error | not checked | bail (unless –force) |
| Plan generated, applied with –force after 25h | Warn override | Checked | Proceeds; operator takes responsibility |
Test Coverage
plan/artifact.rs tests: round_trip_json, round_trip_chunked, staleness_fresh, staleness_expired_artifact, cursor_matches_none_snapshot, cursor_matches_incremental.
PA5 structural coverage is provided by pipeline/chunked/math.rs tests (test_generate_chunks, test_generate_chunks_exact, test_generate_chunks_empty).
Amendment 2026-09-26: PA1 holds for a plan artifact only
rivet apply <config.yaml> is a second, artifact-free mode: it loads the config and runs
every export live, wave by wave (or as a --pool N pool), so PA1–PA6 and PA10 do not apply
to it. A JSON plan artifact still takes the sealed path — integrity, staleness and
precomputed chunks — and --pool is refused for one.
ADR-0006: Source-Aware Extraction Prioritization
- Status: Accepted
- Date: 2026-04-15 (proposed) · 2026-04-18 (accepted after Epics A/B/C/D/E/I landed)
- Owners: Rivet maintainers
Context
Rivet already supports:
- extract-only workflows
- preflight diagnostics
- plan/apply
- snapshot / incremental / chunked / time-window execution
- state, metrics, manifest, and operational visibility
In real production environments, operators often face a different problem:
not only how to extract, but what to extract first, what to delay, what to isolate, and what should not run together on the same source host or replica.
This matters when:
- many exports share one source replica
- tables differ greatly in size
- cursor quality varies by table
- some tables are weak-cursor or reconcile-prone
- extraction windows are limited
- source pressure matters more than raw throughput
Decision
Rivet will introduce an advisory prioritization layer inside the planning subsystem.
This layer will:
- consume metadata and planning signals
- classify exports by cost/risk/freshness value
- emit explainable recommendations
- optionally consider shared source groups
- recommend ordering and execution waves for multi-export campaigns
This feature is:
- advisory
- planning-time
- explainable
It is not:
- a scheduler
- a queue manager
- an orchestration engine
- a runtime reordering mechanism
Why
This comes directly from real production pain:
- 100+ tables
- shared replicas
- weak or inconsistent cursors
- sparse huge tables
- mixed strategies
- limited windows
- manual prioritization outside the product
Rivet already has many useful signals:
- row estimates
- chunking information
- warnings
- profile recommendations
- sparse-range diagnostics
- plan artifacts
But they are not yet combined into a clear recommendation layer.
Principles
1. Advisory, not authoritative
Recommendations guide users and external orchestrators. They do not silently control execution in v1.
2. Explainability first
Every recommendation must include structured reasons.
3. Metadata is signal, not truth
Metadata can be used for:
- discovery
- hints
- ranking
- risk classification
- freshness signals
Metadata must not alone be used for:
- committed export progression
- correctness proof
- reconcile success
- exact incremental truth
4. Planning-layer ownership
This feature belongs first to:
plan/preflight/planCLI output
It should not start inside runtime scheduling or execution control.
5. Graceful degradation
Weak metadata must result in weaker recommendations and explicit caveats.
Definitions
Metadata
Information about tables/exports that is not the exported data itself. Examples:
- table size
- estimated row count
- candidate cursor fields
- source freshness hint
- source group
Export recommendation
An explainable recommendation for one export.
Campaign recommendation
A recommendation for a set of exports, including:
- ordering
- waves
- source-group warnings
- isolation hints
Source group
A logical grouping for exports that share one source host, replica, or capacity boundary.
Scope
In scope for v1
- per-export scoring and classification
- recommendation reasons
- wave recommendation
- optional source-group hints
- campaign-level advisory output
- integration into
plan
Out of scope for v1
- automatic scheduling
- queue daemon
- internal job runner
- dynamic runtime balancing
- historical learning
- execution-time throttling control
Recommendation model
Per-export output
Each export may receive:
priority_scorepriority_classcost_classrisk_classrecommended_wavereasons[]- optional
isolate_on_source
Campaign output
For a group of exports:
- ordered exports
- grouped waves
- source-group warnings
- heavy export isolation hints
- advisory concurrency hints
Inputs
Metadata inputs
Expected signals may include:
- estimated table size
- estimated row count
- min/max numeric range
- sparse-range suspicion
- cursor candidates
- cursor quality
- suggested strategy
- source freshness hint
- reconcile-required flag
- source group
Historical inputs
Deferred:
- previous runtime duration
- retry count
- failure rate
- observed throughput
Metadata policy
Allowed uses
Metadata may be used to:
- suggest strategies
- rank exports
- infer cost/risk
- generate warnings
- bootstrap export registry
Forbidden uses
Metadata must not alone:
- advance committed export boundaries
- define correctness of continuation
- define reconcile success
- prove source-target consistency
Cursor policy interaction
This feature depends on cursor semantics and requires a stable cursor quality classification such as:
- strong monotonic cursor
- weak time cursor
- weak multi-candidate cursor
- fallback-only cursor
- no usable cursor
This ADR does not fully define cursor policy design, but prioritization must consume its outputs.
Source group interaction
Exports may optionally belong to a source_group.
This allows recommendations such as:
- do not run these together
- isolate this export
- only one heavy export at a time on this group
These are advisory only in v1.
Scoring approach
Initial approach
Use a deterministic rule-based scoring model.
Requirement
Recommendations must never be score-only. They must always include:
- class
- score or rank
- reasons
- warnings where relevant
Architecture fit
Reuse current modules
src/plan/— recommendation models and campaign logicsrc/preflight/— advisory inputssrc/pipeline/— CLI renderingsrc/config/— optional future metadata fields
Likely new modules
src/plan/recommend.rssrc/plan/campaign.rs
Modules mostly untouched in v1
- destinations
- file writing
- retry logic
- apply contracts
- runtime scheduling internals
Rollout
Phase 0
- define schemas
- define scoring dimensions
- define reason taxonomy
- define source-group model
Phase 1
- per-export recommendation MVP
- plan output integration
Phase 2
- source-group hints
- isolation suggestions
Phase 3
- campaign view
- wave grouping
Phase 4
- pilot validation and tuning
Phase 5
- historical refinement — landed as Epic I (ADR-0008 interaction, bounded contribution from
export_metrics; seeplan::history::HistorySnapshot)
Risks
Product sprawl
This may drift toward orchestration.
Mitigation:
- advisory only
- no runtime scheduling
- no internal queue
Weak metadata quality
Recommendations may be misleading.
Mitigation:
- explicit reasons
- confidence-aware output
- clear warnings
Beginner overload
Not all users need campaign planning.
Mitigation:
- expose primarily through
plan - keep first-run path simple
Alternatives considered
Do nothing
Rejected because users already solve this manually outside the product.
Build a scheduler
Rejected because it expands product scope too far.
Push all logic to external orchestrators
Rejected because Rivet has richer planning context than generic orchestrators.
Consequences
Positive
- stronger differentiation
- better operator experience
- stronger source-safety story
- strong pilot/demo value
Negative
- more planning complexity
- more heuristics to maintain
- future temptation to over-automate
Summary
Rivet will add Source-Aware Extraction Prioritization as an explainable planning feature.
It will:
- reuse current planning and preflight layers
- classify and rank exports
- recommend execution waves
- emit source-aware warnings
It will not become a scheduler in v1.
Amendment 2026-09-26: rivet now executes orderings
The recommendation layer in plan stays advisory, but rivet apply <config.yaml> now
executes orderings: it runs wave: tiers with barriers, and --pool N is a bounded
work-stealing scheduler that orders exports by predicted duration (longest first, from run
history) and serializes exports that are not parallel_safe. Tiers are not honoured in pool
mode. rivet is still not a daemon, a queue service or a cron.
ADR-0007: Cursor Policy Contracts (Incremental)
- Status: Accepted
- Date: 2026-04-15
- Context: Epic D introduces an explicit incremental cursor policy: primary column, optional fallback, and progression mode. Execution, plan artifacts, preflight, and apply must agree on what “cursor” means so operators can reason about ordering, state, and safety (see also ADR-0005 PA4).
Definitions
| Term | Meaning |
|---|---|
| Primary column | User-configured cursor_column — main monotonic progression key. |
| Fallback column | Optional cursor_fallback_column — only used when incremental_cursor_mode: coalesce. |
SingleColumn mode | Predicate and ordering use the primary column only; fallback must not be set. |
Coalesce mode | Predicate and ordering use COALESCE(primary, fallback); one scalar cursor string is stored in state (max coalesced value from the last batch via a synthetic result column). |
| Synthetic cursor column | Reserved alias _rivet_coalesced_cursor appended to every Coalesce query; stripped before Parquet/CSV write. |
Contract matrix
| ID | Name | Statement | Enforced by |
|---|---|---|---|
| CC1 | Config consistency | cursor_fallback_column is valid iff incremental_cursor_mode: coalesce; coalesce requires a fallback. | Config::validate |
| CC2 | Plan embeds policy | For incremental exports ResolvedRunPlan.strategy = Incremental(IncrementalCursorPlan { primary_column, fallback_column, mode }) and is serialized in PlanArtifact.resolved_plan. | build_plan, serde |
| CC3 | Apply uses artifact only | rivet apply does not re-read cursor policy from YAML; it uses the embedded IncrementalCursorPlan (same channel as ADR-0005 PA1). | apply_cmd + artifact |
| CC4 | Single-column state key | SingleColumn stored cursor equals the primary column’s last row value. | ExtractionStrategy::cursor_extract_column, single.rs |
| CC5 | Coalesce state key | Coalesce stored cursor equals the last row’s _rivet_coalesced_cursor; that column is stripped before Parquet/CSV write. | ExportSink::strip_internal_column, extract_last_cursor_value via cursor_extract_column |
| CC6 | Incremental SQL shape | Incremental queries are single-level and end with ORDER BY so the final Arrow batch carries the maximum progression value. See table below. | source::query::build_incremental_query |
| CC7 | Preflight alignment | EXPLAIN and MIN/MAX range probes use the same key expression as execution. | preflight/cursor_expr::incremental_key_expr |
| CC8 | PA4 unchanged | Cursor snapshot integrity (ADR-0005 PA4) still compares one opaque string in StateStore to cursor_snapshot; the semantics of that string are mode-dependent but the check is unchanged. | PlanArtifact::cursor_matches |
| CC9 | Identifier quoting | Both primary and fallback columns, and the synthetic cursor alias, are quoted via sql::quote_ident ("…" for Postgres, `…` for MySQL). | source::query::build_incremental_query |
| CC10 | Cursor value escaping | Cursor values are injected per engine: MySQL binds the value as a ? parameter (no in-SQL literal); Postgres embeds an E'…' literal with backslash-escaped ' and \ (escape_pg_literal); SQL Server embeds an N'…' literal with single quotes doubled (escape_mssql_literal). | source::query::cursor_rhs |
SQL shape (CC6)
SingleColumn
Subsequent run:
SELECT * FROM (<base>) AS _rivet
WHERE <P> > '<cursor>'
ORDER BY <P>
First run (no stored cursor) omits the WHERE.
Coalesce
Single-level wrapper — the outer ORDER BY is what guarantees the last Arrow batch holds the maximum COALESCE value:
SELECT _rivet.*, COALESCE(_rivet.<P>, _rivet.<F>) AS "_rivet_coalesced_cursor"
FROM (<base>) AS _rivet
WHERE COALESCE(_rivet.<P>, _rivet.<F>) > '<cursor>'
ORDER BY COALESCE(_rivet.<P>, _rivet.<F>), _rivet.<P>, _rivet.<F>
First run omits WHERE. <P> and <F> are quote_ident-quoted; the '<cursor>' literal shown in both shapes is illustrative — the real right-hand side is engine-specific per CC10 (a ? bind parameter on MySQL, an E'…' literal on Postgres, an N'…' literal on SQL Server).
An earlier two-level shape (SELECT _i.* FROM (ORDER BY ...) plus an outer projection) was rejected because SQL does not preserve inner ordering through an outer SELECT: the last batch could miss the max coalesced value and stored cursor could go backwards.
Prioritization interaction
CursorQuality in planning consumes resolved IncrementalCursorPlan.mode (plan/inputs.rs): Coalesce maps to weaker tiers than a fully indexed single column even when both preflight hints (index usage, observed range) are positive, reflecting the higher uncertainty of multi-column progression.
Out of scope (v1)
- Lexicographic pair cursors
(a, b)with two stored values - Runtime
NULL-aware progression withoutCOALESCEin SQL - Changing the SQLite state schema beyond a single
last_cursor_valuetext field - More than one fallback column
Summary
Incremental exports now have an explicit cursor policy in config and a resolved IncrementalCursorPlan in the execution plan. Coalesce uses one stored cursor string, a single-level SQL wrapper with an outer ORDER BY, and a synthetic column that is stripped before write — preserving ADR-0005 apply semantics and keeping destinations clean.
ADR-0008: Export Progression Boundaries (Committed / Verified)
- Status: Accepted
- Date: 2026-04-18
- Context: Epic G separates three distinct boundaries an operator may ask about: what was observed in the source, what was committed to the destination, and what was verified against the source after the fact. Earlier versions of Rivet conflated the first two under a single
export_state.last_cursor_value. Epic F added reconcile reports but no persistent “verified” marker.
Boundaries
| Boundary | Meaning | Source of truth |
|---|---|---|
| Observed | Seen in source during preflight / plan (row estimates, chunk min/max) | ComputedPlanData in PlanArtifact, ExportDiagnostic |
| Committed | Successfully exported to the destination (file durably written, manifest recorded) | export_progression.last_committed_* |
| Verified | Committed and reconciled — per-partition source/export counts all matched | export_progression.last_verified_* |
Observed is ephemeral (rebuilt each rivet plan); committed and verified are persistent.
Contract matrix
| ID | Name | Statement | Enforced by |
|---|---|---|---|
| PG1 | Cursor table unchanged | export_state.last_cursor_value remains the single execution cursor used by the WHERE cursor > ? predicate and by ADR-0005 PA4 (apply-time drift check). Epic G does not rename or repurpose it. | state::cursor, apply_cmd |
| PG2 | Committed after destination write | Committed boundary is written after the existing state writes (manifest, cursor, schema) complete — never before. Failure of the progression update is logged and does not fail the pipeline. | single.rs, chunked::record_chunked_commit |
| PG3 | Committed monotonicity (incremental) | When an incremental commit arrives with a cursor value that does not advance past the stored committed cursor — compared numerically (i128, then f64) when both sides parse as numbers, byte-wise string order otherwise (correct for RFC3339 / YYYY-MM-DD / UUIDv7) — the stored row is kept. Guards against accidental regressions from a stale worker or manual state edit. | record_committed_incremental via the Rust guard cursor_advances (src/state/progression.rs), not SQL |
| PG4 | Committed per strategy | The committed row stores either last_committed_cursor (incremental) or last_committed_chunk_index (chunked), with last_committed_strategy as the discriminant. Switching modes replaces the row rather than mixing fields. | record_committed_incremental, record_committed_chunked |
| PG5 | Verified ⇒ all partitions match | Verified is recorded only when summary.mismatches == 0 && summary.unknown == 0 in a ReconcileReport. A partially-verified run does not advance last_verified_*. | reconcile_cmd::reconcile_chunked |
| PG6 | Verified ≤ Committed | Verified is derived from the reconcile of a specific run_id, which can only advance after that run’s commit. Reconcile refuses to run when chunk_run is missing (Epic F CC). | reconcile_cmd, by construction |
| PG7 | Advisory only | Progression fields are observational. They do not gate rivet run, rivet apply, or rivet reconcile. Consumers: rivet state progression, external monitoring. | No execution paths consult export_progression |
| PG8 | Progression survives schema changes | export_progression is keyed by export_name; column additions to the schema or changes to query SQL do not clear it. Operators drop progression explicitly via a state reset (future rivet state reset-progression). | DB key design |
Schema (v4 migration)
CREATE TABLE export_progression (
export_name TEXT PRIMARY KEY,
last_committed_strategy TEXT,
last_committed_cursor TEXT,
last_committed_chunk_index INTEGER,
last_committed_run_id TEXT,
last_committed_at TEXT,
last_verified_strategy TEXT,
last_verified_cursor TEXT,
last_verified_chunk_index INTEGER,
last_verified_run_id TEXT,
last_verified_at TEXT
);
Migration is additive (no drops, no data movement); pre-existing state DBs upgrade transparently via the existing versioned migration runner.
Write points (v1)
| Strategy | Committed | Verified |
|---|---|---|
Incremental (single.rs) | After state.update(cursor) succeeds, record_committed_incremental with summary.run_id | — (no partition model; reconcile is whole-export) |
Chunked, chunk_checkpoint: true (sequential and parallel) | After finalize_chunk_run_completed, record_committed_chunked with max(chunk_index) WHERE status='completed' | rivet reconcile writes record_verified_chunked when the report has zero mismatches and zero unknowns |
| Chunked, no checkpoint | — in v1 | — in v1 |
| Snapshot / TimeWindow | — in v1 | — in v1 |
Chunked without checkpoint has no per-partition state to key progression on; adding it requires Epic F-style partition tracking (future work).
Out of scope (v1)
- Partition-level committed boundary for non-checkpoint chunked runs.
- Snapshot / TimeWindow progression (no natural partitions).
- Programmatic monotonicity check for chunked commits across reruns (tracked by
run_id; new runs overwrite). rivet state reset-progressionsubcommand (workaround:sqlite3 .rivet_state.db 'DELETE FROM export_progression WHERE export_name = …').
Observability
rivet state progression [--export <name>] prints a table with columns:
EXPORT COMM MODE COMMITTED COMMITTED AT VERI MODE VERIFIED
orders chunked chunk #41 2026-04-18 12:20:15 UTC chunked chunk #41
events incremental 2026-04-17T23:59:59Z 2026-04-18 00:02:11 UTC - -
JSON output for monitoring integrations is tracked as a follow-up; current consumers can parse the table or read the SQLite directly.
Relation to other ADRs
- ADR-0001 (state invariants) — progression writes happen after the existing ordered state writes, preserving I1–I4.
- ADR-0005 (plan/apply) — PA4 cursor-drift check still uses
export_state.last_cursor_value, not the progression table. - ADR-0006 (prioritization) — progression is a future input to Epic I (historical refinement), not used in v1 scoring.
- ADR-0007 (cursor policy) — the single
cursorstring stored in the committed boundary carries the same semantics as the execution cursor; forcoalescemode it isCOALESCE(primary, fallback).
Amendment 2026-09-26: progression is cleared by the existing reset commands
rivet state reset -e <export> deletes the cursor and the export_progression row together,
and rivet state reset-chunks -e <export> also deletes the progression row. No separate
reset-progression command exists or is planned.
ADR-0009: Reconcile and Targeted Repair Contracts
- Status: Accepted
- Date: 2026-04-18
- Context: Epic F introduces partition-level reconciliation (
rivet reconcile), Epic H introduces targeted repair (rivet repair). Both operate on completed chunked runs, produce structured reports, and interact with the progression table (ADR-0008) and the plan/apply channel (ADR-0005). The contracts below make the workflow auditable and composable with external tooling.
Scope
| Command | Input | Output | Side effects |
|---|---|---|---|
rivet reconcile -c -e | Latest chunk_run + committed files (manifest) | ReconcileReport (pretty or JSON) | May advance last_verified_* (ADR-0008 PG5) |
rivet repair -c -e [--report …] [--execute] | ReconcileReport (from --report <file>, or built fresh in-process against the latest chunk run when --report is omitted) | RepairPlan (without --execute) or RepairReport (with --execute) | With --execute: new output files; manifest entries (the repaired chunk’s originals marked superseded); no cursor/commit changes |
Contract matrix
| ID | Name | Statement | Enforced by |
|---|---|---|---|
| RC1 | Reconcile requires a committed chunk run | rivet reconcile bails when no chunk_run exists for the export. Operator must run the chunked export with chunk_checkpoint: true first. | reconcile_chunked_inner — get_latest_chunk_run |
| RC2 | Partition SQL parity with extraction | The per-partition source COUNT(*) is built from the exact same build_chunk_query_sql shape used during extraction — same WHERE, same dense/range/by-days branch, same identifier quoting. | reconcile_chunked_tasks |
| RC3 | Per-partition classification | Each chunk_task is classified as match (counts equal), mismatch (both counts known and differ), or unknown (either count missing). Unknown is always a repair candidate. | PartitionResult::classify |
| RC4 | Reconcile scope v1 | Only chunked exports. time_window bails with a clear “use chunk_by_days” message; snapshot / incremental receive “use rivet run --reconcile”. | reconcile_cmd::run_reconcile_command |
| RC5 | Report shape stability | ReconcileReport JSON fields (export_name, run_id, strategy, partitions[], summary) form a stable schema; new fields are additive only. | plan::reconcile, serde defaults |
| RC6 | Verified advances only on full match | Verified boundary (ADR-0008 PG5) is written iff summary.mismatches == 0 && summary.unknown == 0. | reconcile_cmd::reconcile_chunked |
| RR1 | Repair derives only from reconcile | RepairPlan::from_reconcile is the single path that produces repair actions — no direct config paths, no operator-typed ranges. | plan::repair::RepairPlan::from_reconcile |
| RR2 | Plan before execute | Without --execute, rivet repair prints the plan and exits; no destination files are written and nothing is re-exported. When --report is omitted it first builds a fresh reconcile in-process, issuing one read-only SELECT COUNT(*) per partition against the source (and, on a fully-clean result, advancing the verified boundary per RC6); only the --report <file> path is source-query-free. | repair_cmd::run_repair_command |
| RR3 | Repair SQL parity | Repair chunk queries use the same build_chunk_query_sql as extraction and reconcile — repair is apples-to-apples with the original run. | run_chunked_sequential(ChunkSource::Precomputed) |
| RR4 | Committed boundary not moved by repair | Repair re-exports chunks already covered by committed progression; last_committed_* is not re-stamped by repair. Operator advances verified by running rivet reconcile afterwards. | repair_cmd::execute_repair (no record_committed_* call) |
| RR5 | Destination files are additive | Repair writes new files alongside originals using <export>_<ts>_chunk<idx>_<nonce>.<ext> naming; the 64-bit <nonce> makes the name collision-proof so a re-export of the same chunk never overwrites the original even when it lands in the same wall-clock second (the second-granularity <ts> alone would collide). Rivet does not delete or overwrite prior files. The manifest declares the replacement (amended 2026-09-26): the chunk’s previously committed part(s) are re-marked superseded, so row_count, part_count, column_checksums (the superseded parts’ contribution is re-read and subtracted), validate, and rivet load all see each row once. The superseded files stay on disk until opt-in load.gc_orphans collects them (never while a run is active on the prefix). When an original cannot be mapped to its chunk without guessing (a manifest from another run, a part name with no chunk index, a repair part the rename could not relabel), that chunk stays additive and repair warns. A warehouse that already loaded the old part without a primary key keeps those rows. | chunked::chunk_part_filename, repair_cmd::superseded_parts |
| RR6 | Unparseable identifiers are skipped | Partitions whose identifier does not match "chunk N [start..end]" with parseable i64 bounds are recorded in skipped[] — never silently dropped, never executed. | RepairAction::from_identifier, execute_repair |
| RR7 | Strategy scope v1 | Repair requires mode: chunked. Other modes bail with a clear error (same policy as reconcile scope). | repair_cmd::run_repair_command |
| RR8 | Report shape stability | RepairPlan / RepairReport JSON is a stable additive schema (same policy as RC5). | plan::repair, serde defaults |
Interaction with other ADRs
| ADR | Interaction |
|---|---|
| ADR-0001 (state invariants) | Reconcile does not write to state beyond progression (ADR-0008). Repair runs run_chunked_sequential which honors I1–I4 for the files it produces. |
| ADR-0005 (plan/apply) | A reconcile or repair-report JSON is a peer of PlanArtifact: sealed, reviewable, auditable. No staleness check — reports are snapshots, not execution gates. |
| ADR-0006 (prioritization) | Reconcile outcomes are not (yet) fed into prioritization; Epic I uses export_metrics, not reconcile reports. |
| ADR-0007 (cursor policy) | Reconcile is chunked-only in v1 and does not touch incremental cursors. Coalesce mode is unaffected. |
| ADR-0008 (progression) | RC6 is the sole writer of last_verified_*; RR4 documents that repair leaves last_committed_* untouched. |
Failure map
| Scenario | Reconcile behavior | Repair behavior |
|---|---|---|
No chunk_run for export | Bails (RC1) | Bails (RC1 via fresh reconcile) or error loading report |
| Non-chunked export | Bails (RC4) | Bails (RR7) |
| Source unreachable | Bails at first query_scalar | Bails at source::create_source before any chunk runs |
| Partition count mismatch | Partition marked mismatch; verified not advanced (PG5) | Repair action generated; user decides to --execute |
| Chunk task never completed | Partition marked unknown; verified not advanced | Repair action generated |
| Unparseable chunk keys | Partition marked unknown (source count not attempted) | Skipped with note (RR6) |
Workflow example
# 1. Run chunked export with checkpoint
rivet run -c cfg.yaml
# 2. Reconcile — advances `last_verified_*` if all match
rivet reconcile -c cfg.yaml -e orders --format json -o reconcile.json
# 3. Repair plan (dry-run)
rivet repair -c cfg.yaml -e orders --report reconcile.json
# 4. Execute repair
rivet repair -c cfg.yaml -e orders --report reconcile.json --execute
# 5. Reconcile again to advance `last_verified_*`
rivet reconcile -c cfg.yaml -e orders
Out of scope (v1)
time_windowandincrementalper-partition reconcile.- Automatic repair execution (always opt-in via
--execute). - Repair that rewrites or deletes prior destination files (superseded files are only collected by opt-in
gc_orphans). - Hash-based partition verification (current v1 is
COUNT(*)only). - Repair advancing
last_committed_*(documented non-goal: commit = first successful extraction; repair is corrective, not commitment).
Test coverage
plan::reconcile::tests— classification, summary, round-trip JSON.plan::repair::tests— identifier parsing, action derivation, summary counts.pipeline::reconcile_cmd::tests— stubbed source closure exercises the fullreconcile_chunked_taskspath without a DB.pipeline::repair_cmd::tests— smoke test for the reconcile → plan derivation path.
ADR-0010: Two Parallel Execution Engines
Status: Accepted Date: 2026-05 Context: The architectural audit (2026-05) flagged that rivet runs two distinct parallel execution engines for what looks at first glance like the same job. This ADR documents why they coexist, what each is for, and the conditions under which we would unify them.
Decision
Keep two engines. Do not unify in v0.5.x.
| Engine | File | Use case | Parallel unit |
|---|---|---|---|
| In-process scoped threads | src/pipeline/chunked/exec.rs | Chunked export of a single table — split the row range into N chunks, run them concurrently against the same source DB. | std::thread::scope + per-thread Source connection |
| Subprocess fan-out | src/pipeline/parallel_children.rs | --parallel-export-processes — run many independent exports (different tables, different configs) concurrently as separate rivet child processes communicating via IPC. | std::process::Command + a JSON event stream |
Rationale
The two engines exist because they answer different questions:
-
In-process threads are the right tool when:
- Workers share one Arrow / parquet / OpenDAL runtime in process memory.
- Workers cooperate (semaphore, shared
Destination, shared progress bar). - Crash isolation is not a requirement — one panicking worker can take the whole process down because they share an export plan.
-
Subprocesses are the right tool when:
- Each export has its own config, plan, state, and OpenDAL runtime — sharing them would mean a much larger refactor of
Destination,StateStore, etc., for cross-export use. - Crash isolation matters: a failing export must not abort the others. A child process death is observable via exit code; a thread panic poisoning shared state is not.
- Memory pressure is per-process: a child that explodes its RSS hits the OOM killer alone.
- Each export has its own config, plan, state, and OpenDAL runtime — sharing them would mean a much larger refactor of
Unifying these into one engine would mean either:
- Pushing chunked exports into subprocesses → much higher overhead per chunk (cold connection, runtime spin-up, IPC for every progress event), losing the in-process semaphore and shared destination.
- Pushing multi-export concurrency into threads → losing per-export crash isolation and OpenDAL-runtime separation.
Neither trade is worth the refactor at v0.5.x scale. [Update: the sharing claim below held only for the in-process engine — it uses resource::Semaphore (kernel-parking, no busy-wait) and RetryClass (typed error classification); the subprocess fan-out engine uses neither, classifying child failures from exit codes over the IPC seam.]
What this ADR is not deciding
This ADR is not “we’ll never unify”. It is “we accept the duplication for now, and revisit when”:
- A third parallelism need arises (e.g. async source streaming) — duplication grows from N=2 to N=3 and the cost of keeping them in sync exceeds the cost of consolidation.
- The
Sourcetrait becomesSend + Sync(see ADR-0011). A shareableSourcewould unlock collapsing chunked workers to share one connection, which changes the in-process trade-offs. - A user-facing requirement forces a single execution model (e.g. cross-export coordination during chunked exports — currently impossible because subprocesses cannot observe each other’s chunk state).
Consequences
Cost
- Two retry loops, two progress UIs, two error-aggregation paths.
- New cross-cutting features (graceful shutdown, distributed tracing) must be implemented in both.
Benefit
- Each engine is small and focused; debugging chunked behaviour does not require understanding IPC, and vice versa.
- Subprocess engine inherits OS-level isolation for free.
- Different parallel semantics are not papered over with a
mode: enum.
Considered Alternatives
-
One engine via subprocesses only. Rejected: chunked exports of millions of rows on
--parallel 16would pay 16× cold connection latency at startup, and inter-chunk progress would be IPC traffic instead of a shared atomic. -
One engine via threads only. Rejected: a panic in one of N exports running multiple plans simultaneously would crash the whole
rivetprocess. The operator currently relies on the child-isolation property for long multi-export runs. -
Async/tokio for both. Rejected: rivet keeps its execution model sync. [Update:
tokiohas since become a direct dependency (rt-multi-thread/net/time) — the MongoDB and MSSQL drivers are async internally, bridged to the syncSourcetrait via a per-source runtime +block_on(ADR-0011); the pipeline itself remains sync.] Migrating Source to async I/O is a strictly larger refactor than this ADR is willing to scope. Decision deferred until the Source trait redesign in ADR-0011 lands.
When to revisit
Open a follow-up ADR if any of the following holds:
- The audit graph (
code-review-graph) shows new flows that cross the two engines — currentlypipeline-chunk(461 nodes) is one community, parallel-children lives insrc-batch. - A bug is reported that is impossible to express in one engine and trivial in the other — that asymmetry signals the abstraction is mis-cut.
- Multi-export with chunking (i.e. cross-product parallelism) becomes a real use case.
ADR-0011: Source: Send (not Sync)
Status: Accepted
Date: 2026-05
Context: The architectural audit (2026-05) noted that Source is Send but not Sync, which forces every parallel chunk worker to open its own DB connection. With --parallel 16 on a long export this means 16 backend processes on the source database. The audit asked whether making Source: Send + Sync (via interior mutability, the pattern StateStore already uses) would be a net improvement.
Decision
Keep Source: Send only. Do not introduce Sync in v0.5.x.
#![allow(unused)]
fn main() {
// src/source/mod.rs
pub trait Source: Send {
fn export(&mut self, request: &ExportRequest<'_>, sink: &mut dyn BatchSink) -> Result<()>;
fn query_scalar(&mut self, sql: &str) -> Result<Option<String>>;
fn type_mappings(...) -> Result<Vec<TypeMapping>>;
}
}Every method takes &mut self. A worker that needs a Source must own it; sharing &Source between threads is not supported.
Rationale
Why Sync would be tempting
StateStore already uses interior mutability (RefCell wrapping postgres::Client) so its methods take &self. Applying the same pattern to Source would let the chunked engine in pipeline/chunked/exec.rs share one connection across N worker threads. On paper that means:
- 1× DB backend instead of N — large win against a
max_connections=200Postgres. - No
lean_pool_opts()workaround in MySQL (themin=10bug we fixed in f6ba79f). - Faster startup — no per-worker
Client::connect.
Why it is the wrong trade-off today
-
Serialized I/O kills the point of parallelism. A single
postgres::Client(ormysql::PooledConn) is fundamentally not concurrent: eachclient.query()exchanges Postgres wire-protocol packets in lock-step. Wrapping it inMutex<Client>orRefCell<Client>means workers contend on the mutex and the parallel design degrades into batched-sequential. We measured a 1.7× slowdown on a 4-thread chunked export ofcontent_items(200K rows) when prototyped against aMutex<Client>. -
pipeline/chunked/exec.rsalready amortizes connection cost. Workers open their connection once and reuse it for the entire chunk’s lifetime. Per-chunk cost is dominated by the SQL execution, not the connect handshake. -
Backend explosion is a non-problem in practice. A user running
--parallel 16is explicitly opting into 16 concurrent backends. The exporter has guardrails:lean_pool_opts()keeps the MySQL pool atmin=1, ADR-0010 keeps each child process to oneSource, and pooler detection (detect_pg_transaction_pooler) warns when a pgBouncer is multiplexing. Operators who want fewer backends can run with lower--parallel. -
The
Syncrefactor blocks on multiple deps the audit flagged separately.- The
postgres::ClientAPI is&mut-only; making itSyncrequires eitherMutex(slow, see #1) or an async client (a much larger surface change). mysql::PooledConnhas the same problem.- The Source trait’s three methods all mutate session state (timeouts, cursors, prepared statements). Interior mutability without serialization would be unsafe by design, not just slow.
- The
-
The
Sendbound is exactly what we need. Workers move theirSourceintothread::scope. The trait already supports the parallelism model we actually run; the missing capability (one shared connection) is not a capability we want.
Consequences
Cost
- N-worker chunked exports open N connections. Documented in the
--parallelflag help and in pgBouncer guidance. - No “single-conn parallel” mode. Users who want one backend run sequentially (
--parallel 1).
Benefit
- Source trait stays simple —
&mut selfeverywhere, noMutex, noRefCell, noArc<dyn Source>to reason about. - Each worker has independent failure semantics — a panic in one connection cannot poison another worker’s mid-statement state.
- Easy to add new backends:
impl Source for NewDBrequires only&mut selfmethods, the natural shape for any blocking DB driver.
Considered Alternatives
A. Sync via Mutex<Client> inside the impl
Prototyped. Result: workers serialise on the mutex, making --parallel N no better than --parallel 1. Rejected.
B. Sync via async (tokio + tokio-postgres)
Requires rewriting Source as async. Knock-on changes:
BatchSink::on_batchbecomes async, propagating throughpipeline/sink.rsandformat/parquet.rs(which is sync today).chunked/exec.rsswitches fromthread::scopetotokio::join!/JoinSet.Destination::writeis already sync (OpenDAL blocking layer); making it async would unwind the layered design.
Estimated effort: weeks. Estimated value over current model: marginal — chunked workers already saturate the source DB’s network and CPU; adding async coordination on top does not help.
Rejected for v0.5.x. Revisit if a future requirement (e.g. async incremental tailing, CDC-like consumption) needs async I/O for an unrelated reason.
C. Lazy Source creation inside workers (current behaviour)
This is what we do. Each chunked worker calls source::create_source(&plan.source) inside thread::scope and owns its connection for the chunk’s duration. StateRef::Postgres(url) propagates the connection string into workers without requiring shared state.
When to revisit
Open a follow-up ADR if:
- A blocking SQL driver appears that is genuinely
Syncwithout internal serialization (none currently exists for Postgres or MySQL). - The whole pipeline migrates to async (would also affect ADR-0010).
- Profiling shows connect handshakes dominating end-to-end latency on a real workload — currently far from the case (200K-row content_items chunked export: connect <50ms, query+stream 8s).
ADR-0012: Cloud Manifest Contract
Status: Accepted Date: 2026-05-21 (accepted; M1–M9 landed, incl. M8 chunked-resume executor and M9 best-effort quarantine move — see test-coverage table) Context: Rivet 0.7.0 introduces a public JSON manifest as the trust contract for cloud-output runs (local / S3 / GCS). The manifest is the operator-visible record of what was written, and the input to resume, validation, and reconciliation. Its invariants must be locked before the writer, the resume logic, and the verification extensions are coded — otherwise we will rewrite them.
This ADR defines those invariants. The shipping target is Rivet 0.7.0. Schema v8 has already reclaimed the manifest name by renaming the internal SQLite ledger to file_log (ADR refs: see CHANGELOG 0.6.1).
Goals
- Resume-aware cloud output: a re-run can decide, per part, whether to skip, rewrite, or quarantine.
- Trust verdict:
--validateand--reconcilecan give an unambiguous pass/fail by inspecting only the manifest and the destination (no local state required). - Legacy compatibility: pre-0.7.0 runs work as-is, with no migration of in-flight state. See M6.
- Backend portability: identical semantics on local FS, S3-compatible, and GCS.
Non-goals
- Cross-engine column-level encryption metadata (a separate ADR if/when encryption ships).
- Schema evolution between successive runs of the same export (out of scope — schema_changed/fingerprint live in the run report, not in the manifest contract).
- A new
rivet verifysubcommand — explicitly rejected. The verdict is surfaced via the existing--validate/--reconcile/--reportflags.
Artifacts
For every export run targeting a cloud or local-file destination, Rivet writes:
<destination_uri>/<export_layout>/
part-000001.<format>
part-000002.<format>
...
manifest.json
manifest-<run_id>.json # immutable per-run copy of the manifest
_SUCCESS # only if the run completed cleanly
<export_layout> is the destination-config-provided layout, typically <schema>.<table>/ and optionally namespaced by run_id. Layout policy is destination-config concern, not part of this ADR.
manifest.json is the authoritative record of the run for this export. Its schema is versioned (see “Versioning”) and stable across patch releases.
Every manifest write also leaves an immutable run-unique copy manifest-<sanitized-run_id>.json beside the canonical last-writer-wins manifest.json (src/manifest.rs::run_unique_manifest_name), so repeated runs into one prefix do not clobber prior runs’ records. The copies are Rivet-internal sidecars: resume, validate, and reconcile keep reading the canonical name, and the untracked-object scans exempt any manifest-*.json name (is_run_unique_manifest_name).
_SUCCESS is a single-line marker carrying the manifest fingerprint (xxh3:<16-hex>, src/manifest.rs::success_marker_body; see M2). Its only meaning is “the manifest at this prefix represents a fully-committed run”. Its existence implies the manifest exists, and every part the manifest references also exists at the recorded byte length.
Invariants
These extend ADR-0001 (I1–I7) into the cloud-destination plane.
M1 — Parts Before Manifest (PBM)
The manifest is written only after every part it references has been committed to the destination.
Rationale: A manifest pointing at a part that was never uploaded is a phantom record — worse than no manifest, because resume logic would skip work that wasn’t actually done.
Failure mode if violated: resume skips real work; --validate falsely reports completeness.
Recovery: a process killed between part-upload and manifest-write leaves the destination without a manifest. Resume detects “parts present, manifest absent” and re-derives the run state by listing parts (see M6 / M8).
M2 — Manifest Before SUCCESS (MBS)
_SUCCESSis written only after the manifest has been written and is readable at its destination URI.
Rationale: _SUCCESS is the single observable signal an external orchestrator (Airflow, Dagster, CI) can poll to decide “data is ready”. If _SUCCESS could appear before the manifest, downstream consumers reading the manifest would race.
Recovery: a process killed between manifest-write and _SUCCESS-write leaves the prefix with a manifest but no _SUCCESS. Resume treats this as “candidate complete; re-verify before finalizing”. Re-verification reads the manifest, checks each part, and writes _SUCCESS only if all checks pass.
_SUCCESS body: a single line xxh3:<16-hex>\n carrying the manifest’s content fingerprint (xxh3_64 over the exact bytes of manifest.json). This lets a polling consumer detect manifest changes (rerun, resume, repair) with a cheap GET _SUCCESS instead of re-reading the full manifest. The Hadoop empty-marker convention is not followed — Rivet does not target the Hadoop ecosystem and the fingerprint pays for itself the first time an Airflow sensor needs to distinguish “same successful run” from “new successful run at the same prefix”.
M3 — Part Identity Triple (PIT)
Every part referenced by the manifest is uniquely identified by
(path, size_bytes, content_fingerprint).
The triple is recorded for each part. On resume, a part is considered the same as the manifested part if and only if all three components match. A part whose path matches but whose size or fingerprint differs is treated as corrupt or stale and quarantined (M9).
content_fingerprint is xxh3_64 over the part body, formatted "xxh3:<16-hex>". xxh3 was chosen because (a) the codebase already depends on xxhash-rust, (b) it streams at ~2 GB/s so the per-part cost is negligible against destination upload latency, and (c) the manifest is a trust contract for integrity, not for security — cryptographic hashes (sha256, blake3) are explicitly out of scope. The encryption / tamper-evidence track is deferred to a separate ADR if and when needed; until then, the xxh3: prefix in the on-wire format reserves the syntactic slot so a future cryptographic hasher can coexist without a schema break.
For 0.7.0, fingerprint is mandatory for new manifests. Pre-0.7.0 runs have no fingerprint and fall under M6.
M4 — Manifest Is Append-Only Per Run
A given
run_idproduces exactly one manifest. The manifest is never amended in place — a resumed run that completes additional parts writes a fresh manifest atomically (write-then-rename on local; atomic PUT on S3/GCS).
Rationale: partially-written manifests must be impossible to observe. Object stores give per-object atomicity for PUT/upload; local FS gets the same via write-temp-then-rename.
Resume across multiple interruptions does not produce multiple manifests for the same run — the latest write supersedes.
[Update: each manifest write now also leaves an immutable run-unique copy manifest-<run_id>.json (see Artifacts), so one run_id yields the canonical manifest.json plus one sidecar copy at the prefix. The canonical manifest is still never amended in place — the copy exists so repeated runs into one prefix keep every run’s record.]
M5 — SUCCESS Implies Verifiability
If
_SUCCESSexists, then for every part listed in the manifest, the part is present at the destination at the recorded byte length.
This is the contract --validate checks on the metadata-only path: it lists the prefix, reads the manifest, and verifies M5 part-by-part. The listing also carries each object’s content MD5 (GCS md5Hash, S3/Azure single-PUT ETag), so --validate confirms content, not just size, with no download — the original “re-download to re-fingerprint” idea (--validate --deep) was rejected as wasteful. A part whose store gives no checksum (streamed multipart, local FS) verifies size-only; exports[].verify: content makes that a failure.
--reconcile adds: row counts in the manifest sum to the source COUNT(*) for the export’s row range.
M6 — Legacy Output Is Labeled, Not Migrated
Runs that completed before 0.7.0 (no manifest at the destination prefix) are not migrated. Operations on legacy prefixes succeed with reduced guarantees and must emit an explicit
legacy_run: truelabel in operator-facing output.
Per the project decision taken at 0.7.0 planning (pre-0.7.0 runs keep the old behavior; the manifest applies only to new runs; every reduced check is explicitly labeled legacy_run, never silent):
--resumeon a legacy prefix uses the pre-0.7.0 file-log-based logic; no manifest-aware skip.--validateon a legacy prefix falls back to local-file row-count checks; manifest/M5 checks are skipped and reported as such.--reconcileon a legacy prefix uses source-COUNT vs file-log only; the “manifest part-count match” line is omitted.
Silent fallback is forbidden. Every reduced check must say so in the report.
M7 — Manifest Atomicity
The manifest write is observable atomically: a reader either sees the previous state (manifest absent, or older manifest from a prior superseded run) or the new complete manifest. A partially-written manifest is unreachable to readers.
Local FS: write manifest.json.tmp then rename to manifest.json (POSIX rename(2) is atomic on the same filesystem).
S3 / GCS: write manifest.json as a single PUT / upload. Object stores guarantee write-completes-or-fails-with-no-trace.
Multipart uploads MUST NOT be used for the manifest itself — only the data parts. The manifest stays small enough (KB to single MB) that single-PUT suffices and side-steps the multipart abort/cleanup story.
M8 — Resume Decisions Are Deterministic
Given the same destination prefix and the same source/cursor state,
--resumemakes identical decisions on every run.
Decision matrix per part name:
| Manifest entry | Object present | Size matches | Fingerprint matches | Decision |
|---|---|---|---|---|
| yes | yes | yes | yes | skip (committed) |
| yes | yes | yes | no | quarantine (M9) |
| yes | yes | no | — | quarantine (M9) |
| yes | no | — | — | rewrite (lost) |
| no | yes | — | — | quarantine (M9) — untracked artifact |
| no | no | — | — | new — write |
_SUCCESS present + no --force → refuse to start (operator must opt in to overwrite a successful run).
The “no manifest entry / object present” row does not apply to the run-unique manifest copies (manifest-*.json, see Artifacts): both the reconcile and validate untracked-object scans exempt them via is_run_unique_manifest_name, so prior runs’ sidecar copies are never quarantined as untracked artifacts.
M9 — Untracked / Corrupt Parts Are Quarantined Best-Effort, Never Deleted
When resume finds an unknown or fingerprint-mismatch part, Rivet attempts to move it to a quarantine prefix and emits a warning. The move is best-effort: if it fails, the run still proceeds, the warning escalates, and the object stays where it was. Rivet never deletes unknown objects.
Quarantine layout: <prefix>/_quarantine/<run_id>/<original-name>.
Rationale — defensive: the unknown part may be the operator’s own intentional artifact, or evidence of a bug. Either way, Rivet preserves it and shifts the cost of cleanup to the operator.
Rationale — best-effort: on S3 / GCS the move decomposes into copy + delete, two non-atomic operations. A partial failure (copy succeeds, delete fails; or copy fails outright on a permissions issue) must not abort an otherwise-recoverable run. The reported warning carries enough detail (source path, destination quarantine path, failure reason) for the operator to finish the move manually. If the move never happens, the untracked part remains in place and re-trips M9 on the next resume — that is acceptable; an unmovable artifact is not a correctness problem, just a clutter problem.
Local FS gets the same best-effort behaviour: rename(2) is atomic but can still fail (different mount point, permissions, file-in-use on Windows). The semantics are uniform across backends — never bail on a quarantine failure.
Manifest schema (v1)
Field additions are backwards-compatible (consumers ignore unknowns). Field removals or type changes require a manifest_version bump.
{
"manifest_version": 1,
"run_id": "orders_20260521T120000.000",
"export_name": "public.orders",
"started_at": "2026-05-21T12:00:00.000Z",
"finished_at": "2026-05-21T12:14:33.412Z",
"status": "success",
"source": {
"engine": "postgres",
"schema": "public",
"table": "orders"
},
"destination": {
"kind": "gcs",
"uri": "gs://rivet-exports/public.orders/run_20260521T120000/"
},
"format": "parquet",
"compression": "zstd",
"schema_fingerprint": "xxh3:7f3a91be...",
"row_count": 2001291,
"part_count": 41,
"parts": [
{
"part_id": 1,
"path": "part-000001.parquet",
"rows": 50000,
"size_bytes": 123456789,
"content_fingerprint": "xxh3:8a44e2c1...",
"status": "committed"
}
]
}
path is relative to the destination prefix so the manifest is portable across copies of the same dataset.
source.schema / source.table capture the logical name; the resolved SQL is not embedded — the manifest is about the output, not the extraction strategy. The run report (.rivet/runs/<run_id>/summary.json) carries the plan-side details.
schema_fingerprint is xxh3_64 over a canonical serialization of [{name, type}] from the existing state::SchemaColumn array. The fingerprint format prefix (xxh3:) is reserved so future fingerprint algorithms can coexist.
status per part: committed (in this manifest) or quarantined (the part listed in a prior superseded manifest that resume found corrupted; retained for audit).
What this does NOT define
- Per-column encryption metadata.
- Per-row provenance / lineage fingerprints.
- Cross-run incremental cursor state (lives in
export_state, surfaced byrivet state/rivet metrics). - Quotas, retention, or bucket policy.
These are intentionally outside the manifest. A manifest that tries to be a catalog will lose its trust-verdict role.
Decisions locked at ADR review
These items were open in the first draft of this ADR; they are now decided.
_SUCCESSbody — decided: carries the manifest fingerprint. See M2. A polling orchestrator can detect manifest changes between two successful runs (a rerun, a resume that completed, a repair) by reading the_SUCCESSbody alone, without re-fetching the manifest. The Hadoop empty-marker convention is rejected — Rivet does not target the Hadoop ecosystem.- Run-id segmentation in the destination prefix — decided: no automatic segmentation. Rivet writes parts, manifest, and
_SUCCESSdirectly under the operator-configured destination prefix. Two successive runs against the same prefix produce one observable dataset whose manifest reflects the latest run; the prior run’s parts are reused (M8 skip), rewritten, or quarantined (M9) as the matrix dictates. Operators who want time-segregated historical runs include{run_id}(or{date}) in their destination URI themselves — that policy lives in the destination config, not in the manifest contract. Resume across overwrite is handled by the_SUCCESSgate plus--force(M8). - Cryptographic / encryption-aware fingerprinting — decided: out of scope for 0.7.0. See M3. The
xxh3:prefix reserves the slot.
Open questions deferred to implementation
- Quarantine TTL: Rivet does not delete quarantined objects. Operators may want a cleanup helper (
rivet state remote --gc) — out of scope for 0.7.0.
Test coverage plan
| Invariant | Status (2026-05-21) | Test |
|---|---|---|
| M1 | ✅ writer side covered | manifest writer commits parts before manifest (pipeline::manifest_writer); kill-mid-write integration test deferred to Phase C-γ |
| M2 | ✅ writer side covered | _SUCCESS written iff status==Success; body = xxh3(manifest.json bytes); covered by success_marker_* tests + tests/offline/trust_artifacts_integration.rs §4 (compiled into the offline suite via tests/offline_suite.rs) |
| M3 | ✅ write side + no-download content verify | per-part content_fingerprint (xxh3) and content_md5 recorded at write in one pass; --validate confirms content by comparing content_md5 to the store’s listing checksum (no download); resume still trusts size for skip decisions (quarantine on size drift) — covered by pipeline::resume_decisions::tests and pipeline::manifest_reconcile::tests |
| M4 | ✅ | tests/offline/trust_artifacts_integration.rs §6 — writing_manifest_twice_replaces_the_previous_artifact |
| M5 | ✅ | pipeline::validate_manifest + tests/offline/trust_artifacts_integration.rs §22 (manifest read, part presence, size match) |
| M6 | ✅ | legacy_run: true label surfaced by verify_at_destination when no manifest present; covered in validate_manifest unit + integration tests |
| M7 | ✅ writer relies on Destination::write atomicity | local: fs::copy; S3/GCS: single PUT (opendal); covered by destination capability tests |
| M8 | ✅ gate + matrix + chunked-resume executor wired | --resume against _SUCCESS refuses without --force (covered §26); pure matrix tested per row in pipeline::resume_decisions::tests and end-to-end against real Destination listing in §27; executor apply_m8_resume_decisions runs as the resume preamble in both chunked runners (pipeline/chunked/resume_m8.rs, called from sequential_checkpoint + parallel_checkpoint) |
| M9 | ✅ best-effort quarantine move wired | quarantine_move → Destination::move for divergent manifest parts (size/fingerprint) and untracked surplus objects; never fatal, never deletes on partial failure; counted on M8ResumeStats.{quarantined_moved, quarantine_move_failures} (pipeline/chunked/resume_m8.rs) |
Each invariant lands with at least one unit test (local FS, fast) and one integration test (S3-compat via MinIO or GCS-compat; nightly).
Amendment 2026-08-27: the CDC cursor belongs in this contract, fenced (M10, proposed)
M1–M9 govern what a run records ABOUT its data in the destination. The CDC
cursor — the position a next run resumes from — is not in that record. It is a
JSON file on the local filesystem (src/source/cdc/mod.rs:98-139: temp file,
fsync, rename; a corrupt or truncated file is refused rather than silently
re-anchored). There is no fence and no owner on it.
That split has two silent failures, and neither is a bug in the code above:
- The two live in different durability domains. The data lands in object storage; the cursor lands on a container’s disk. A run in a fresh container finds no cursor and re-anchors — the “enable CDC during a quiet period” shape the process rules already records for MySQL, one layer up from the engine.
- Nothing arbitrates two writers. PostgreSQL refuses a second consumer of a
replication slot, so that engine is protected by the server. MySQL, MongoDB
and SQL Server are not: two processes on one checkpoint path both advance it
and both report success.
has_active_run_on_prefixanswers a different question (orphan GC) and is not an owner check.
Proposed M10 — Cursor With The Data, Fenced. The durable CDC cursor is recorded in the destination, in the same write path as the manifest, and carries a monotonic generation plus the owning run id. A run re-reads that fence immediately before every advance and refuses (or invalidates its own generation) when it no longer owns it. The local file is demoted to a cache: it may make a resume faster, it may never be the sole source of truth. The durability ORDER is unchanged (flush → record → ack, per M1/M2 and ADR-0017); what changes is where the record lives and that it is fenced.
Primary prior art. The fencing token — a monotonically increasing generation
the resource itself checks on every write, so a stalled or superseded owner
cannot resume — is Kleppmann, Designing Data-Intensive Applications, ch. 8
(“The Truth Is Defined by the Majority” → fencing tokens). rivet already applies
the shape once, in gc_orphans, where a superseded running row loses to a
newer run by started_at rather than to a clock; M10 is the same discipline
applied to the cursor.
RED-proof before this leaves Proposed. Two runs of one export against one destination, overlapping in time: the second is refused or invalidates the first’s generation, and the union of delivered rows equals the source. The mutant is the fence read removed from the advance path — that test must go RED. Plus the ephemeral half: delete the local cursor file between two runs and assert the second resumes rather than re-anchors, which is RED today.
Sequencing note: M10 touches the manifest write path, the state store, and every engine’s ack path. It is the largest of the four CDC amendments dated 2026-08-27 (the others are in ADR-0023 and ADR-0025) and the one most likely to need its own ADR before code.
Amendment 2026-09-26: what M1, M2 and M8 do today
M1. Recovery without a destination manifest rebuilds the committed parts from the state
DB (completed chunk tasks, file_log) and uses the destination listing only to confirm they
are present: a missing part’s chunk is reset and re-exported in the same run (keyset refuses
instead). Listed parts the state DB does not name are not adopted. When the listing fails,
the parts are declared from the state DB with a warning.
M2. Resume-time re-verification is not implemented for the chunked runners. They mark the
chunk run completed before the dispatcher writes the manifest, so a crash between the
manifest and _SUCCESS makes --resume plan afresh and re-export. --pool --split repairs a
missing marker only when the completed units’ windows tile. The writer-side order (manifest
before _SUCCESS) holds.
M8. The per-part decision matrix (apply_m8_resume_decisions) runs only in the two
chunked-checkpoint runners, and only against a manifest carrying this run’s run_id. Single,
plain chunked, keyset and mongo_parallel have no per-part matrix.
ADR-0013: Trust Flag Contract
Status: Proposed
Date: 2026-05-21
Context: ADR-0012 introduced cloud manifest invariants (M1–M9). Implementing
M5 (manifest-aware verification), M6 (legacy fallback), M8 (resume decision
matrix), M9 (quarantine), and the future encryption-aware verify path could
each plausibly grow its own CLI flag (--validate-manifest, --validate-deep,
--verify, --decrypt, --check-success, …). Without an explicit contract
the surface area drifts; six months from now operators face a flag soup that
contradicts the project’s existing “predictable, minimal CLI” stance.
This ADR locks the trust-flag surface for rivet run at exactly three flags
(--validate, --reconcile, --resume) and the safety-override flag
--force, and pins the rule that ADR-0012 work and beyond extends semantics,
never adds new flags.
Goals
- Operators have one mental model for “how do I ask Rivet to prove the run was correct?” — and that model fits in a handful of words.
- New trust invariants (M5–M9 today, encryption later) are absorbed under the existing flags transparently, with the operator’s existing CI / Airflow wiring continuing to work unchanged.
- The cheapest useful check is reachable without a source query
(
--validate); the full audit is reachable with one flag (--reconcile). - Deprecation pressure on the CLI shape is explicit, not accidental.
Non-goals
- A unified
rivet verifysubcommand. Rejected — the verdict is surfaced via the existing run report (.rivet/runs/<run_id>/summary.{md,json}) and the existing flags. See ADR-0012 §“Non-goals” item 3. - Per-invariant flags (
--check-m5,--validate-manifest, etc.). Same rejection: the operator should not have to know which ADR-0012 letter their check maps to. - Renaming
--validateto--check. See “Naming” below.
The contract
rivet run exposes three mutually composable trust flags and one
safety-override flag:
| Flag | What it asks | Source query? | Implies |
|---|---|---|---|
--validate | “Is the output internally consistent?” | No | — |
--reconcile | “Does the output match the source right now?” | Yes | --validate |
--resume | “Pick up where the prior run left off.” | Sometimes | — |
--force | “Override a refusal that would otherwise abort the run.” | — | — |
Trust flags are composable: --validate --reconcile is the same as just
--reconcile; --resume --reconcile runs resume and then reconciles.
--force is a category apart — it overrides safety gates, not check
semantics. Calling it a trust flag would be a misnomer; it’s the inverse.
Semantics that grow under each flag
ADR-0012 invariants land under existing flags as follows. The flag itself does not change between versions — only what it does internally.
--validate
| Version | Behaviour |
|---|---|
| 0.6.x (current) | Per-file row count check (parquet rows / CSV lines minus header) |
| 0.7.0 | Above, plus ADR-0012 M5: read manifest.json from the destination, verify every listed part exists at the recorded size_bytes, verify _SUCCESS body matches the manifest fingerprint. |
| 0.7.0 (M6) | When the destination prefix has no manifest (legacy run), the new checks degrade to the 0.6.x file-row check and the report carries legacy_run: true so the reduction is explicit, not silent. |
| 0.7.x (shipped) | --validate also confirms each part’s content via the MD5 the store surfaces in its listing (GCS md5Hash, S3/Azure single-PUT) — no download. The earlier “--validate --deep re-fingerprints every part” projection was rejected (re-downloading a whole dataset to recompute a hash we already verified pre-upload is wasteful and partial). Verification depth is instead a per-export config — verify: size (default) / verify: content (content MD5 required; size-only parts fail) — not a CLI flag, which keeps the no-new-trust-flag contract. |
| 0.7.2+ (encryption track) | When parts are encrypted, metadata-only verify (no key needed) is the default; --validate --identity ./key.txt adds the decrypting verify. |
The flag stays --validate. No --validate-manifest, no --check-success,
no --verify-output.
--reconcile
| Version | Behaviour |
|---|---|
| 0.6.x (current) | SELECT COUNT(*) FROM (<base_query>) and compare to exported rows. |
| 0.7.0 | Above, plus the full --validate chain (M5/M6 included). In effect, --reconcile becomes “everything --validate does + source comparison”. No new flag is needed for “full audit” — --reconcile already is that. |
| 0.7.x (future) | Source schema fingerprint compared to manifest’s schema_fingerprint so silent type drift surfaces in the verdict. |
The implication direction is fixed: --reconcile implies --validate,
never the other way around. Operators who only want the cheap check use
--validate; operators who want the full audit use --reconcile and
get everything for free.
--resume
| Version | Behaviour |
|---|---|
| 0.6.x (current) | Reuse chunk_checkpoint rows in the local state DB to skip already-completed chunks; no destination-side awareness. |
| 0.7.0 | Above, plus ADR-0012 M8: read the manifest at the destination, apply the decision matrix per part (skip / rewrite / lost / quarantine), refuse to start when _SUCCESS is present unless --force is given. |
| 0.7.0 (M9) | Untracked / fingerprint-mismatch parts are moved to _quarantine/<run_id>/<original-name> best-effort during resume. This is automatic, not a flag. |
Quarantine (M9) is intentionally not a flag. An operator who said “resume” already accepted that the destination would be touched; refusing to move a corrupt artifact in that mode would be worse than a best-effort relocation with an audit warning.
--force
A safety-override, not a check.
| Version | Use |
|---|---|
| 0.7.0 | --resume --force: proceed even when _SUCCESS is present (M8 gate). Without it, resume against a complete run refuses and exits non-zero so an operator can’t accidentally re-export over a verified dataset. |
--force is scoped to the specific safety gate it overrides. Future gates
(if they appear) reuse the same flag rather than adding --force-resume,
--force-overwrite, etc.
Naming
Why keep --validate rather than the conceptually cleaner --check:
- The word is already in the codebase (
pipeline::validate,validate_output,RunReport.validation). Renaming it now ripples into Airflow operator code and CI scripts that grep for--validate. The cost outweighs the gain. - The roadmap (
rivet_roadmap_0_6_1_to_0_8_0_encryption.md) reservedcheckfor the pre-run preflight subcommand. Mixing pre-run and post-run checks under one word would re-introduce exactly the ambiguity this ADR is trying to prevent. --validateis the same word every other widely-used data tool spells (dbt, Airflow, Great Expectations). Operators don’t have to learn a Rivet-specific dialect.
What this rules out
These are explicitly not going to ship, in 0.7.0 or later, unless this ADR is superseded:
rivet verifysubcommand as a higher-level umbrella that subsumes validate + reconcile + manifest + schema under one new noun. See the carveout below for the narrower allowance.--verify,--audit,--check-output,--fullflags onrivet run.- Per-invariant flags (
--check-m5,--validate-manifest,--require-success). - Behaviour where
--validatetriggers a source query. - Behaviour where
--reconciledoes not imply--validate. - Silent fallback when manifest is missing — see M6: the report must say
legacy_run: trueso the operator knows the surface they’re looking at.
If a use case appears that these rule out, the right move is to reopen this ADR and amend it, not to slip a new flag in under the radar.
Subcommand carveouts (amendment 2026-05-21)
The contract above pins the flag surface of rivet run. It does not
forbid subcommands whose only job is to re-drive existing flag semantics
standalone, without introducing new trust nouns. Two examples:
rivet reconcile -c <config> -e <export>— already exists; partition-level reconciliation for chunked exports previously run withchunk_checkpoint: true(re-runs per-chunkCOUNT(*)against stored chunk counts). For snapshot/incremental/keyset it bails and directs the operator torivet run --reconcile, the whole-export COUNT(*)-vs-exported-rows audit (reconcile_source_countinsrc/pipeline/job.rs). The subcommand itself (src/pipeline/reconcile_cmd.rs) is a sibling partition-level check, not a standalone driver of the--reconcileflag semantics.rivet validate [--export <name>]— added 2026-05-21; standalone driver for the M5/M6 semantics thatrivet run --validateperforms at end-of-run. Runs the samepipeline::validate_manifest::verify_at_destinationcode path against an existing destination prefix, no source query, no extraction, no state writes.
Allowed subcommand patterns:
- The subcommand’s verdict must be expressible by an existing flag.
rivet validateproduces the sameManifestVerificationshape thatvalidation.manifestcarries insummary.json; an Airflow consumer reads it identically from either source. - The subcommand must not introduce a new trust noun in the
operator-facing language. “Validate” maps to
--validate; “reconcile” maps to--reconcile. Arivet verifysubcommand was rejected above precisely because “verify” is not an existing flag. - The subcommand must not depend on having run an extraction. These are between-run inspection tools, not retroactive run mutators.
Rationale: between-run polling (Airflow sensors, CI gating, operator
triage) is a real workflow that the existing --validate flag cannot
serve — it only fires at end-of-run. Refusing to ship a standalone
driver would force operators to either re-run the entire export to
re-verify, or to reimplement M5 in shell against the manifest schema.
Both are worse than a thin subcommand.
Acceptance criteria
rivet run --helplists exactly the flags above for trust/resume/safety.--reconcileproduces a verdict that subsumes everything--validateproduces (i.e. an operator running--reconcilenever needs to also pass--validateto get the full picture).- Run report renders a single “Verdicts” section that names the strongest check the operator asked for, not a column per ADR letter.
- Adding M5, M6, M8, M9 to the codebase causes zero changes to
rivet run’sclapderive struct beyond--force(the safety override). - Subcommand carveouts (see amendment below) are limited to standalone
drivers that re-run an existing flag’s semantics.
rivet validateis the first such carveout; future carveouts must clear the same bar.
Status (2026-05-21)
--validateextended with M5/M6 semantics: ✅feat(0.7.0): manifest-aware --validate (1ef2fbb)- Standalone
rivet validatesubcommand: ✅feat(0.7.0): rivet validate subcommand (20b849a) --forcesafety override +_SUCCESSgate: ✅feat(0.7.0): _SUCCESS gate + pure resume decision matrix (9b510c7)- M8 chunked-resume executor wiring (no new flag): ⚠️ Phase C-γ
- M9 quarantine on resume (no new flag): ⚠️ Phase C-δ
- Integration anchor test (
§24intrust_artifacts_integration) pins therivet runflag set; refuses any flag outside the contract. --reconcileimplies--validate: ✅ enforced at plan build (plan.validate = validate || reconcileinplan/build.rs). Previously the two flags were gated independently downstream, sorun --reconcileran only the source-count check and skipped the M5/M6 manifest verdict — a drift from the acceptance criterion above. Pinned byrun_reconcile_implies_validate_produces_manifest_verdict(a reconcile-only run must produce thevalidated:verdict; a plain run must not).
Open items
-
How
--reconcilereports its three sub-checks (file rows, manifest M5, source COUNT) is a render decision, not a CLI surface decision. The suggestion is one block insummary.md:## Verdicts - Validation: PASSED (manifest M5 + 13 parts verified) - Reconciliation: MATCHED (2,500 rows source ↔ 2,500 rows in manifest) - Schema: unchanged (xxh3:cad2…)Bikeshed-friendly; not part of this ADR’s contract.
-
Verification depth turned out not to be a
--validatemodifier at all: it’s the per-exportverify: size | contentconfig (shipped 0.7.x). The--validate --deepre-download idea was rejected — content is verified pre-upload and via the free listing MD5, never by pulling bytes back. The encryption-aware--validate --identity ...modifier remains a future decision. Either way the contract holds: no new top-level trust flag.
References
- ADR-0012: Cloud Manifest Contract — defines M1–M9.
rivet_roadmap_0_6_1_to_0_8_0_encryption.md— release scoping.pipeline::report::RunReport.validation/.reconciliation— the on-wire shape these flags drive.
ADR-0014: Target Type Materialization
Status: Proposed
Date: 2026-05-26
Context: Rivet v0.7.8 ships a canonical type pipeline (SourceColumn → RivetType → Arrow/Parquet/CSV) with Parquet field metadata (rivet.native_type, rivet.logical_type, rivet.fidelity). Operators load files into DuckDB, BigQuery, Snowflake, and ClickHouse. Autoload from Parquet infers physical types only (e.g. JSON columns appear as STRING / VARCHAR), while warehouses expose native semi-structured and exact numeric types (BigQuery JSON, Snowflake semi-structured types, ClickHouse types, DuckDB types).
Epic 14 already has ExportTarget::BigQuery and rivet check --type-report --target bigquery mapping Arrow physical types to expected warehouse types (src/types/target.rs). DuckDB is the most common first consumer of Rivet Parquet in benchmarks and ad-hoc analytics but is not yet a first-class ExportTarget. This ADR defines how Rivet separates interchange (files) from materialization (target-native types at load time) without breaking the v0.7.8 Parquet contract.
Related: type-mapping.md, Epic 14 in rivet_roadmap.md, ADR-0012 (manifest/schema fingerprint).
Goals
- One canonical semantic layer (
RivetType+ fidelity + metadata) for all sources (PostgreSQL, MySQL, …). - Predictable file interchange: Parquet/CSV values preserved; no silent float fallback for decimals.
- Target-aware guidance: per-column native type, warnings, and optional load SQL for each supported engine.
- DuckDB as a reference target (strong Parquet interop,
JSON/UUID/UBIGINT) before cloud warehouses. - Extensibility for future direct warehouse load (Epic 14) reusing the same resolver — not a second type system.
Non-goals
- Replacing Parquet with N target-specific file formats in v0.8 (one interchange artifact remains default).
- Automatic type coercion inside Rivet’s Parquet writer per target (physical Arrow types stay target-neutral).
- PostGIS / nested arrays / full PostgreSQL exotic types (tracked separately in the type matrix roadmap).
- A new top-level
rivet verifysubcommand (ADR-0013: extend--validate/ type-report semantics instead). - Teaching DuckDB/BigQuery to read
rivet.*metadata keys without operator or generated DDL (not a standard interchange contract). - Databricks as an
ExportTargetor materialization matrix column (deferred; Delta/VARIANT overlap with Snowflake/CH patterns — revisit when there is operator demand).
Problem
Three layers are often conflated:
| Layer | Question | Failure mode |
|---|---|---|
| Semantic | What did the source column mean? | Lost when everything becomes Utf8 |
| Interchange | What is in the Parquet/CSV file? | Correct bytes, wrong inferred type at load |
| Materialization | What type should the target table use? | JSON/VARIANT never created; queries need casts |
Rivet today solves semantic + interchange well (e.g. jsonb → Utf8 + rivet.logical_type=json, fidelity=logical_string). schema_fingerprint in the manifest hashes Arrow Debug types only — it does not include rivet.* metadata (schema_fingerprint design). Downstream engines that read Parquet schema alone therefore cannot recover JSON vs plain text.
Industry tools split the same problem differently:
- Sling: generic types (
json,decimal, …) + per-DBnative_type_map/general_type_map(templates);column_typingandcolumns:overrides at DDL/load time. - Airbyte: JSON Schema +
airbyte_type; destinations v2 materialize typed tables (e.g. BigQueryJSONfor objects, not onlySTRING).
Rivet needs an explicit materialization stage analogous to Sling’s target DDL + Airbyte’s destination typing, while keeping file-first extraction.
Decision
Adopt a five-layer type pipeline. Layers L0–L3 are implemented in v0.7.8; L4–L5 are specified here and rolled out incrementally.
L0 source_native ("jsonb", "numeric(18,2)")
↓
L1 RivetType (Json, Decimal { p, s }, …)
↓
L2 PhysicalType (Arrow DataType → Parquet/CSV)
↓
L3 TypeManifest (rivet.* field metadata + TypeFidelity)
↓
L4 TargetColumnSpec (per ExportTarget: sql_type, autoload_type, status)
↓
L5 Materialization (DDL, load schema, cast SQL — operator or future loader)
Invariants
T1 — Single semantic source. Only RivetType (via TypeMapping / build_arrow_field) may drive L2–L3. Source drivers must not set ad-hoc Arrow types for domain columns.
T2 — Interchange is target-neutral. Parquet physical types are chosen for cross-engine fidelity (e.g. Decimal128, Timestamp with timezone). Target-specific types (BigQuery JSON, Snowflake VARIANT) appear in L4–L5, not by changing L2 per export unless a separate target profile is explicitly enabled (future, opt-in).
T3 — Metadata is provenance, not autoload. Keys rivet.native_type, rivet.logical_type, rivet.fidelity (src/types/mapping.rs) document intent for tooling and CI. Generic Parquet readers may ignore them.
T4 — Plain strings stay plain. Columns mapped to RivetType::String / Text must not carry rivet.logical_type (tests enforce this). Semantic JSON/UUID/enum must use the corresponding RivetType variants.
T5 — Materialization is explicit. Achieving target-native types requires TargetColumnSpec + L5 (cast or load schema). Autoload from Parquet alone is a compatibility class, not the native class, when rivet.logical_type is set.
T6 — Fidelity gates policy. TypeFidelity::Lossy / Unsupported behavior remains governed by TypePolicy and --strict on type-report; target resolver must not upgrade fidelity.
Physical interchange (L2–L3) — current contract
Documented in type-mapping.md. Summary:
| Source (examples) | Rivet | Parquet (Arrow) | Parquet metadata |
|---|---|---|---|
json / jsonb | Json | Utf8 | logical_type=json, fidelity=logical_string |
uuid | Uuid | FixedSizeBinary(16) | arrow.uuid ext → native LogicalType::Uuid, fidelity=exact |
numeric(p,s) | Decimal | Decimal128/256 | fidelity=exact |
timestamptz | Timestamp + UTC | Timestamp(µs, UTC) | fidelity=exact |
PG enum | Enum | Utf8 | logical_type=enum |
CSV rejects list (and other non-serializable) columns loudly at writer creation, naming the column — the export fails with CSV cannot serialize column … rather than omitting the column (and rivet check --type-report surfaces the same violation); metadata is Parquet-only.
Target materialization (L4–L5)
ExportTarget
Extend the enum in src/types/target.rs (order reflects recommended implementation priority):
| Target | CLI alias | Role |
|---|---|---|
DuckDb | duckdb | Reference consumer of Parquet; local analytics/staging |
BigQuery | bigquery, bq | ✅ partial (bq_compat) |
Snowflake | snowflake | Cloud warehouse |
ClickHouse | clickhouse, ch | Columnar OLAP |
TargetColumnSpec (new struct)
Per column, per target:
#![allow(unused)]
fn main() {
pub struct TargetColumnSpec {
pub target_type: String, // e.g. "JSON", "VARCHAR", "UBIGINT"
pub autoload_type: String, // type inferred by read_parquet / BQ autodetect
pub status: TargetStatus, // ok | warn | fail (existing)
pub note: Option<String>,
pub cast_sql: Option<String>, // e.g. "attrs::JSON" (DuckDB), "PARSE_JSON(attrs)" (BQ)
}
}Resolver inputs: RivetType, Option<DataType> (Arrow), field metadata, ExportTarget, optional TypePolicy / column overrides.
Resolver must consider rivet.logical_type when physical type is Utf8 / LargeUtf8.
RivetType → target native (normative matrix)
Autoload = type a typical Parquet reader assigns without casts. Native = recommended table type for semantic fidelity.
| RivetType | DuckDB native | DuckDB autoload | BigQuery native | BQ autoload | Snowflake native | ClickHouse native |
|---|---|---|---|---|---|---|
Json | JSON | JSON | JSON | BYTES ⚠ | VARIANT | JSON† |
Uuid | UUID | UUID | STRING | BYTES ⚠ | TEXT | UUID |
Enum | VARCHAR | VARCHAR | STRING | STRING | STRING | String |
Decimal(p,s) | DECIMAL(p,s)‡ | DECIMAL(p,s)‡ | NUMERIC/BIGNUMERIC‡ | same | NUMBER(p,s)‡ | Decimal(p,s) |
UInt64 | UBIGINT | UBIGINT | NUMERIC | INT64 ⚠ | NUMBER | UInt64 |
Timestamp + TZ | TIMESTAMPTZ | TIMESTAMPTZ | TIMESTAMP | TIMESTAMP | TIMESTAMP_TZ | DateTime64 |
Timestamp naive | TIMESTAMP | TIMESTAMP | DATETIME | TIMESTAMP ⚠ | TIMESTAMP_NTZ | DateTime64 |
Interval | INTERVAL § | INTERVAL § | STRING | STRING | TEXT | String |
List { … } | LIST(T) | LIST(T) | ARRAY<…> | REPEATED … | ARRAY | Array(T) |
Binary | BLOB | BLOB | BYTES | BYTES | BINARY | String/binary |
† ClickHouse: use JSON when querying inside fields; opaque blob → String (JSON type).
‡ Per-warehouse decimal ceilings: DuckDB and Snowflake cap at precision ≤ 38 — past 38, DuckDB autoloads as DOUBLE (lossy past 2^53, no recovering cast — narrow the source precision) and Snowflake FAILS the column (NUMBER above precision 38 is not a valid type). BigQuery instead escalates NUMERIC (≤ (29,9)) → BIGNUMERIC (≤ (76,38) with at most 38 integer digits, p - s ≤ 38 — its range is about ±5.79e38), failing past either (bigquery::decimal in src/types/target.rs, covered by the bq_decimal_* tests).
⚠ Autoload diverges from native, cast_sql only where lossless: BQ Json autoloads as BYTES — recover native JSON with PARSE_JSON(SAFE_CONVERT_BYTES_TO_STRING(col)); BQ Uuid as 16-byte BYTES — TO_HEX(col); BQ UInt64 autoloads as INT64, which overflows past i64::MAX unrecoverably (cast_sql None) — map the column to decimal(20,0) via a source override; BQ naive Timestamp autoloads as TIMESTAMP (an instant — BigQuery ignores Parquet isAdjustedToUTC=false) — recover the wall-clock with DATETIME(col) after load.
§ The resolver reports DuckDB INTERVAL/INTERVAL ok, but mapping.rs still exports PG interval as ISO Utf8 — the DuckDB autoload claim itself warrants a code-side check.
Example L5 — DuckDB view over Rivet Parquet
CREATE VIEW payload_typed AS
SELECT
* REPLACE (
attrs::JSON AS attrs,
uid::UUID AS uid
)
FROM read_parquet('export.parquet');
Example L5 — BigQuery load schema snippet
-- autoload: all strings; native: declare JSON columns in load job / external table
attrs JSON,
uid STRING
CLI and manifest integration
Phase A (v0.8) — type-report extension
rivet check --type-report --target duckdb(and other targets as implemented).- Columns: existing source/Rivet/Arrow/fidelity + target native, autoload, status, note.
- DuckDB: warn only when
native != autoloadand cast is recommended (JSON, UUID). [Update: DuckDB now autoloads JSON and UUID natively — rivet writes the Parquet JSON logical type via the Arrow Json extension — so the only DuckDB divergence left isdecimal(p>38)→DOUBLE.]
Phase B — load plan artifact (optional)
rivet plan-load -c export.yaml --target duckdbemits DDL or view SQL (L5) from plannedTypeMappings — no second export.- Optional sidecar next to manifest:
type_manifest.jsonlisting L3+L4 per column (does not changeschema_fingerprint).
Phase C — Epic 14 direct load
- Warehouse writer calls same
TargetColumnSpecresolver before INSERT/COPY/load job. - File interchange unchanged unless operator opts into
exports[].target_profile(future).
Relationship to existing artifacts
| Artifact | Includes rivet.* metadata? | Includes target native type? |
|---|---|---|
| Parquet file | Yes (field KV) | No |
schema_fingerprint | No (Arrow Debug only) | No |
manifest.json | No (today) | No (today; Phase B optional) |
rivet check --type-report | Via Rivet/Arrow columns | Phase A |
ADR-0012 manifest invariants (PBM, MBS, PIT) are unchanged. Type materialization does not alter part upload order (ADR-0004).
Implementation plan
| Step | Deliverable | Notes |
|---|---|---|
| 1 | duckdb_compat() + ExportTarget::DuckDb | Mirror bq_compat; JSON/UUID/UInt64 rules |
| 2 | Refactor to resolve_target_column(RivetType, Arrow, metadata, target) | Shared by type-report |
| 3 | Type-report columns: target_type, autoload_type, cast_hint | Docs + live CLI tests |
| 4 | docs/type-mapping.md § Downstream targets | Link this ADR |
| 5 | plan-load command + optional type_manifest.json | Phase B |
| 6 | Snowflake / ClickHouse resolvers | Same matrix, per-engine limits |
| 7 | Direct warehouse load | Epic 14; reuse resolver |
Consequences
Positive
- Operators understand why Parquet shows
VARCHARfor JSON and what to run in DuckDB/BQ. - One resolver serves CLI, future load jobs, and documentation.
- DuckDB-first path validates materialization without cloud credentials.
Negative / trade-offs
- Two-type mental model (autoload vs native) until operators apply L5 SQL.
- Parquet metadata alone is insufficient for zero-touch native types — by design (T3, T5).
- Maintaining N target tables requires discipline; matrix lives in this ADR and tests.
Risks
- Resolver drift from warehouse docs — mitigate with contract tests keyed off expected_contracts.yaml + target-specific rows.
- Confusing
schema_fingerprintwith semantic schema — document clearly; semantic snapshot istype_manifest.json(Phase B), not fingerprint replacement.
References
- Rivet: type-mapping.md,
src/types/mapping.rs,src/types/target.rs,src/types/fidelity.rs - BigQuery: Standard SQL data types
- Snowflake: SQL data types
- ClickHouse: Data types
- DuckDB: Data types overview
- Sling: Columns, Templates
- Airbyte: Supported data types, Destinations V2
ADR-0015: Source Introspection is a Data-Shape Seam, Not a Trait
Status: Accepted Date: 2026-05-30
Context
Chunked-mode planning needs four facts about a source table before it can resolve the extraction strategy: the single-column integer PK (if any), the set of usable keyset keys (single-column UNIQUE NOT NULL indexes), the row estimate, and the average row width in bytes. PostgreSQL and MySQL each expose this data through their own catalog, and the plan layer needs to ask “either source” for the same shape of answer.
The current arrangement (since OPT-4 shipped, commit 40433a0):
src/source/mod.rs::TableIntrospection— shared struct holding all four facts plus the derivedauto_keyset_key()andis_usable_keyset_key()helpers.src/source/postgres/mod.rs::introspect_pg_table_for_chunking(url, tls, qualified_table) -> Result<TableIntrospection>.src/source/mysql/mod.rs::introspect_mysql_table_for_chunking(url, tls, qualified_table) -> Result<TableIntrospection>.src/source/mssql/mod.rs::introspect_mssql_table_for_chunking(url, tls, qualified_table) -> Result<TableIntrospection>(added with the SQL Server engine; probessys.*catalog views).src/plan/build.rs::resolve_chunked_strategydispatches bymatch config.source.source_typeto the right free function.
Architecture-review walks have re-suggested unifying these into a
trait Introspector with one impl per engine, citing “code drift” /
“parallel modules with no shared abstraction” between the (now three)
introspection functions. Each suggestion has reached the implementation
stage, been examined against the actual code, and been rejected for the
reasons in this ADR.
Decision
The introspection seam lives at the data shape (TableIntrospection),
not at a trait. The three per-engine functions remain free functions,
dispatched by match source_type at the one call site in plan/build.rs.
No trait Introspector is introduced. (The deletion-test rationale below
scales unchanged to N engines: the functions share a data shape, not logic.)
Why a trait would not deepen the seam
A trait Introspector { fn introspect_table(url, tls, qualified_table) -> Result<TableIntrospection>; } would add:
- the trait definition,
- one impl per engine (still hand-written, since each engine queries a different catalog with a different client crate),
- a factory function
fn introspector_for(source_type: SourceType) -> Box<dyn Introspector>— which is itself the samematchthe call site has today.
It would remove: nothing. The match doesn’t disappear; it moves up
into the factory.
The bodies share no extractable implementation logic:
| Concern | Postgres | MySQL |
|---|---|---|
| Row estimate source | pg_class.reltuples | information_schema.TABLES.TABLE_ROWS |
| Avg row width | pg_relation_size(c.oid) / reltuples | AVG_ROW_LENGTH with correct_innodb_avg_row_length overflow correction |
| Single int PK probe | pg_index JOIN pg_attribute JOIN pg_type, filtered to int2/int4/int8 | information_schema.STATISTICS filtered to INDEX_NAME='PRIMARY' + SEQ_IN_INDEX=1 + composite check |
| Keyset-key probe | pg_index.indisunique + attnotnull | information_schema.STATISTICS.NON_UNIQUE=0 + nullability join |
| Client crate | postgres | mysql |
| SQL dialect | PG ($1/$2, regclass) | MySQL (?, no regclass) |
Per the deletion test (deleting an abstraction must concentrate complexity somewhere; if nothing concentrates, it was ceremony): deleting the hypothetical trait concentrates no complexity — the two free functions remain, the shared struct remains, the dispatch match remains. The trait was pure ceremony around two functions whose only shared property is “produce the same data shape.”
The two-adapters-for-a-real-seam guideline expects the adapters to share implementation logic the seam can hide. Here the adapters share no implementation logic, only their result type — which is the actual seam, and it is already in place.
Consequences
Positive
- Adding a third engine (DuckDB, ClickHouse, etc.) means writing one
free function returning
TableIntrospectionplus onematcharm inresolve_chunked_strategy. No trait surface to satisfy; no factory to register against; no orphan-impl problem with external crates. - Bug fixes to one engine’s catalog query stay scoped to that engine.
A change to PG’s
int2/int4/int8whitelist does not have a parallel in the MySQL function (MySQL does its own type check viaarrow_convert::rivet_type_for_mysql_column); the trait would not prevent this asymmetry, and the free-function arrangement makes the asymmetry visible at the call site. - Future architecture-review walks see the doc-comment on
TableIntrospection(and this ADR) before re-suggesting the refactor.
Negative / trade-offs
- Callers cannot pass an
Introspectorparameter generically; they must accept the concreteSourceTypeenum and dispatch. In practice this is a single line inplan/build.rsand a non-issue. - The parallel shape (“two functions with identical signatures
returning the same type”) looks like duplication on a first read.
Documented at the seam in
src/source/mod.rs::TableIntrospectionso the first read shows the rationale.
Alternatives considered
trait Introspector per engine. Rejected on the deletion-test
grounds above: adds ceremony without consolidating implementation
logic.
Single function with internal match — fn introspect(source_type, url, tls, table) that internally selects PG vs MySQL. Rejected for
weaker encapsulation: it widens the dependency surface of a single
function to both engine modules, and the PG function would carry a
pub(crate) lifetime even when only MySQL is used. Current arrangement
isolates each engine module’s surface.
Move both introspection functions into source::introspect
sub-module. Considered. The functions already live in the engine
modules where their catalog queries belong; moving them to a
cross-engine sub-module would invert the locality (catalog queries are
engine-specific). Rejected as a re-arrangement without locality gain.
When this decision should be revisited
If the introspection surface grows to a third method that does share non-trivial implementation logic across engines (e.g., a normalized “column statistics” query that both engines can build on top of an existing catalog probe), the trait becomes a real deepening — the shared default method would carry the leverage. The next architecture-review walk that proposes the trait must point at the shared logic that would live behind a default impl, not at the parallel signatures alone.
Until then: this ADR exists so future agents see the prior reasoning and can short-circuit the re-suggestion.
References
src/source/mod.rs::TableIntrospection— the seam, with doc-comment pointing at this ADR.src/source/postgres/mod.rs::introspect_pg_table_for_chunkingsrc/source/mysql/mod.rs::introspect_mysql_table_for_chunkingsrc/plan/build.rs::resolve_chunked_strategy— the one call site and dispatchmatch.- Commit
40433a0— original OPT-4 keyset work that introduced the sharedTableIntrospectionstruct. - ADR-0010 — two parallel execution engines (in-process chunked vs subprocess fan-out). Note: that ADR is about execution-layer parallelism, not the planning-layer introspection seam this ADR addresses.
- ADR-0011 —
Source: SendnotSync. Note: that ADR governs theSourcetrait at the execution layer; introspection is a planning-layer concern and intentionally not on that trait.
ADR-0016: Nullability Propagation Deferred to v0.8 Phase A
Status: Accepted (deferred) Date: 2026-05-30
Context
Rivet’s source drivers (PostgreSQL, MySQL) construct a SourceColumn
per result column when building the type-mapping pipeline. The
SourceColumn::nullable field is intended to carry the source schema’s
nullability declaration so it can flow through TypeMapping →
build_arrow_field → arrow::Field and ultimately end up in the
Parquet schema’s per-column repetition (OPTIONAL for nullable,
REQUIRED for NOT NULL).
The current implementation hardcodes nullable: true at every
SQL-engine SourceColumn construction site:
src/source/postgres/arrow_convert.rs:269 SourceColumn::simple(name, native, true)
src/source/postgres/mod.rs:789 SourceColumn::simple(name, native, true)
src/source/mysql/arrow_convert.rs:271 SourceColumn::simple(name, native, true)
src/source/mysql/mod.rs:774 SourceColumn::simple(.., true)
src/source/mssql/arrow_convert.rs:133 SourceColumn::simple(name, native, true)
src/source/mssql/arrow_convert.rs:186 SourceColumn::simple(name, native, true)
[Update: the list originally named four sites across PG/MySQL; MSSQL
added two more, and MongoDB (src/source/mongo/mod.rs:379) passes
nullable=false for _id (and true for document), so not every
construction site hardcodes true — the deferral covers the SQL
engines.]
The first round of the type-roundtrip work (v0.7.8) accepted this as a
conservative default. The Gap #5 invariant audit (“nullable values must
remain nullable”) was technically satisfied — a source column that
allows NULL maps to a Parquet column that allows NULL. But the
directional invariant the audit also implies (“source NOT NULL
constraints survive the round-trip”) is not satisfied: every
column in every output Parquet file is OPTIONAL, regardless of the
source’s NOT NULL declarations.
Problem
Downstream catalog tools (BigQuery LOAD, ClickHouse file() table
function, Snowflake COPY INTO ... PATTERN, DuckDB catalog views,
generic Parquet schema viewers) read the Parquet schema to infer the
target table’s column nullability. They cannot distinguish:
- “the source column is
NOT NULLand Rivet exported it faithfully” — catalog should mark the target columnNOT NULL, - “the source column allows NULL but happened to have no NULLs in this run” — catalog must allow NULL,
- “the source column allows NULL and some rows are NULL” — catalog must allow NULL.
All three cases produce identical Parquet schemas under the current
implementation: every column marked OPTIONAL. Information that was
present in the source schema is lost at the seam.
For an extraction tool that brands itself as type-faithful (ADR-0014:
“Decimal precision/scale must not be silently degraded; timestamp
semantics must be explicit; unsupported types must fail or be
explicitly mapped”), losing source NOT NULL is an asymmetric gap
relative to those other type fidelities.
Why this is not fixed in this release
Per-column nullability is only fully resolvable for the “single-table SELECT” shape:
SELECT a, b, c FROM users WHERE …
Here every result column maps to a source column with a known
information_schema.columns.is_nullable (MySQL) or
pg_attribute.attnotnull (PostgreSQL) value. PostgreSQL’s wire protocol
makes this easy: RowDescription carries table_oid + column_attnum
per result column, directly indexable into pg_attribute.
For non-trivial query shapes the mapping is partial or absent:
| Query shape | Per-column source nullability available? |
|---|---|
SELECT cols FROM table | Yes — direct mapping |
SELECT cols FROM a JOIN b ON … (INNER JOIN) | Yes if column origins resolve uniquely |
LEFT JOIN outer side | No — outer-join columns are nullable regardless of source declaration |
SELECT col, COUNT(*), expression(...) FROM … | Only col resolvable; computed columns are not in any source catalog |
SELECT * FROM (subquery) AS x | Subquery-specific; would require recursive resolution |
WITH cte AS (…) SELECT FROM cte | CTEs need the same recursive resolution |
A partial fix (“propagate NOT NULL only when the query is a simple
single-table SELECT, fall back to nullable=true otherwise”) would be
correct but introduces a heuristic the operator cannot trivially
predict from the YAML. A full fix requires either query parsing or a
configuration knob.
The other axis is MySQL’s weaker introspection surface:
information_schema.STATISTICS carries the data, but MySQL’s wire
protocol does not give per-result-column table_oid + column_attnum
the way PostgreSQL does — driver would need to parse the query or
require an explicit table hint in the YAML.
The combined work (PG protocol-level lookup + MySQL query parsing +
operator UX for the partial-fix gap + tests across LEFT JOIN /
computed-column / CTE shapes) is estimated at 200-400 lines per engine
plus operator-facing documentation. It is the right work for the
v0.8 Phase A type-report extension already declared in
ADR-0014 (## CLI and manifest integration → Phase A), which adds
per-column type provenance to rivet check output. Nullability fits
that surface naturally — the type-report would gain a nullability
column with values from_catalog: NOT NULL, from_catalog: NULL, or
assumed: NULL (computed / LEFT JOIN / CTE).
Decision
Nullability propagation is explicitly deferred to v0.8 Phase A.
The current nullable=true hardcode at the SQL-engine
SourceColumn::simple call sites (six today — see Context) is
acknowledged as a known limitation, not a design choice.
The deferral is paper-trailed at the SourceColumn::nullable field
documentation (src/types/source_column.rs) so the next contributor
who reads the struct sees the limitation before the call sites.
Operator workaround until v0.8 Phase A
The existing exports[].columns: mechanism already accepts per-column
type overrides in the YAML (used today for explicit decimal precision:
columns: { amount: "decimal(18,2)" }). The same mechanism could be
extended to accept a nullability hint
(columns: { amount: { type: "decimal(18,2)", nullable: false } }).
This is the operator’s escape hatch for cases where the source schema
is known and the target catalog needs the constraint.
This extension is not implemented in this release — it requires
the YAML schema change and the override threading through
ColumnOverrides. Operators who need source NOT NULL constraints
in their target catalog must currently fix it downstream (e.g., add
NOT NULL in the target CREATE TABLE statement).
Trigger for revisiting
Pull this ADR out of deferred status when any of the following ships:
- v0.8 Phase A type-report extension (per ADR-0014) — direct parent work.
- A specific operator request citing a catalog-tool downstream that refuses or mis-handles the all-nullable schema.
- A query-parser dependency lands in the crate for unrelated reasons
(e.g., for
chunk_by_keyvalidation), making the LEFT JOIN / computed-column detection cheap.
Consequences
Positive (during deferral):
- Conservative
nullable=truewrite-path: any source value passes through, no falseRIVET_VALUE_TOO_NULLerrors on data that the source happens to contain. - Source-engine introspection layer stays simple — no per-query
RowDescriptionwalk or query parsing. - The SQL-engine
SourceColumn::simple(…, true)call sites are uniform, easy to audit. [Update: MongoDB’s_idsite passesfalse, so uniformity now holds across the SQL engines, not all engines.]
Negative (during deferral):
- Information loss at the Parquet schema layer for
NOT NULLsource columns. - Downstream catalog tools cannot infer target-table
NOT NULLconstraints from Rivet’s Parquet output. - Operators who need this must add constraints in the target manually.
Reversal cost:
- ~80 lines per engine for the catalog probe (PG: wire-protocol
table_oid + attnum→pg_attribute.attnotnulllookup; MySQL:information_schema.STATISTICSquery keyed on table-name + column- name when origin is resolvable). - ~50 lines for
ColumnOverridesnullability threading and YAML schema bump. - Live tests per engine: “non-null column round-trips with Parquet
repetition = REQUIRED” + “LEFT JOIN outer side staysOPTIONAL”.
References
src/types/source_column.rs::SourceColumn::nullable— field with the limitation doc and a back-pointer to this ADR.src/source/postgres/arrow_convert.rs:269,src/source/postgres/mod.rs:789,src/source/mysql/arrow_convert.rs:271,src/source/mysql/mod.rs:774,src/source/mssql/arrow_convert.rs:133and:186— the six SQL-enginenullable=truehardcode sites (src/source/mongo/mod.rs:379passesfalsefor_id).- ADR-0014 — target type materialization, including the Phase A type-report this work joins.
- The session that surfaced this gap during its invariant audit: closing commits 2cedd3a (gap #2/#3) and 73d5be8 (gaps #1/#4) shipped CI gates for the four other audit invariants; gap #5 (this one) was dismissed at the time as “design choice” — this ADR is the honest paper trail replacing that dismissal.
ADR-0017: Per-Runner Durability Ordering Map
Status: Accepted Date: 2026-05-30
Context
Eight runners produce output parts (file + manifest entry + state row + journal event) on the destination + state-store boundary:
pipeline::single::run_single_export(Snapshot, Incremental)pipeline::keyset::run_keyset(Keyset / Page)pipeline::chunked::exec::run_chunked_sequential(Chunked, single thread)pipeline::chunked::exec::run_chunked_parallel(Chunked, thread pool)pipeline::chunked::sequential_checkpoint::run_chunked_sequential_checkpoint(Checkpoint, single thread)pipeline::chunked::parallel_checkpoint::run_chunked_parallel_checkpoint(Checkpoint, worker pool)pipeline::keyset::run_keyset_parallel(Keyset, worker pool — added 2026-07)pipeline::mongo_parallel::run_mongo_parallel(Mongo, worker pool)
All eight share pipeline::commit::record_part for the ordered tail
(I2/M1 manifest + I7 file-log + counters + journal), introduced by
the commit_part seam work. The cursor + progression writes that follow
share pipeline::run_store::RunStore (ADR-0018).
But the timing of the file-log write (the I7 step inside
record_part) varies across runners. Four runners call record_part
synchronously per part inside the runner’s main loop; one runner —
run_chunked_parallel_checkpoint — writes the file-log
synchronously inside the worker (before pushing the part to a
shared Vec), then has the parent thread call record_part with
state = None during the post-scope drain (the parent drain populates
manifest_parts + counters + journal; the file-log write is already
durable from the worker).
This ADR documents the asymmetry, why it exists, and what invariants each variant satisfies.
The asymmetry
| Runner | file_log write site | manifest_parts add site | Journal event site |
|---|---|---|---|
single | inline, per-part | inline, per-part | inline, per-part |
keyset | inline, per-page | inline, per-page | inline, per-page |
chunked_sequential | inline, per-chunk | inline, per-chunk | inline, per-chunk |
chunked_parallel | post-scope drain | post-scope drain | post-scope drain |
sequential_checkpoint | inline, per-chunk | inline, per-chunk | inline, per-chunk |
parallel_checkpoint | per-chunk in worker (sync) | post-scope drain (state=None) | post-scope drain |
keyset_parallel | per-RANGE in worker (sync, txn) | post-scope drain (state=None) | post-scope drain |
mongo_parallel | post-scope drain | post-scope drain | post-scope drain |
The odd rows are chunked_parallel, parallel_checkpoint,
keyset_parallel (feat/parallel-keyset), and mongo_parallel (whose
main-thread drain calls record_part(Some(state)) post-scope — the
chunked_parallel shape; src/pipeline/mongo_parallel.rs). They are
odd for different reasons.
keyset_parallel — per-RANGE worker-sync file_log (added 2026-07)
The 7th runner. Like parallel_checkpoint it writes file_log synchronously
in the worker (so a crash-resume can rehydrate) and drains
manifest_parts + counters + journal post-scope (record_part(state=None)).
It differs on granularity and atomicity: the worker-sync write is
per-RANGE, not per-chunk — a range’s parts + its keyset_range.done=1
flip go in ONE transaction (commit_keyset_range), the atomic
checkpoint boundary (see dev/parallel_keyset/design_iter2.md). Because an
incomplete range writes NO file_log rows, the resume rehydrate pulls only
done ranges with no filtering. This sidesteps ADR-0017’s per-chunk
StateStore::open smell — the reconnect amortizes over a whole range, not
every part — but it is the SAME *_at_ref reconnect pattern (see the smell
section; a shared with_ref helper would deepen all four *_at_ref sites).
chunked_parallel — three writes coalesced post-scope
Background: this runner has no chunk_task persistence (it is the
non-resumable parallel engine; resumability is parallel_checkpoint’s
job). All three writes (file_log + manifest_parts + journal) move to a
post-scope drain because:
- The worker has
&mut RunSummaryaccess via sharedagg_*atomics + aMutex<Vec<(PartRecord, chunk_index)>>, butsummary.journalis notSend + Syncfor ordered append. - The post-scope parent has the
&mut summaryborrow, can drain the sharedVec, and callsrecord_part(Some(state), …)once per collected part.
Effect: if the process crashes between scope-join and drain-end, the file is durable at the destination but file_log, manifest_parts, and journal have no entry for that chunk. This is the standard “crash after destination write, before manifest” window (ADR-0001 I2 → I3): the file is recoverable from the destination listing, the manifest is reconstructed from the file_log on resume.
Crash window is the scope-join to drain-end interval — typically microseconds (the drain is a tight CPU loop over an in-memory Vec). The window in practice is dominated by the destination write, not by this drain.
parallel_checkpoint — file_log split from manifest_parts
Background: this runner does have chunk_task persistence and is the
resumable parallel engine. Each chunk’s success / failure flips a
chunk_task row, and a crash mid-run drops back into a “resume from
chunk_task state” code path.
Live test live_chunked_recovery.rs::parallel_chunked_crash_after_chunk_complete_resume_finishes_with_no_duplicates
(C3) panics the parent process after the worker has marked its
chunk_task row as completed. The resume code must rebuild the
manifest from the per-chunk durable file_log rows — there is no
in-memory RunSummary to drain, the prior process is gone.
If parallel_checkpoint wrote file_log only in the post-scope drain
(like chunked_parallel), a crash at this fault point would leave
chunk_task.status = 'completed' but file_log empty for that chunk.
On resume, the M8 manifest-reconcile path
(pipeline::chunked::resume_m8) would see the chunk_task as done but
have no file_log entry to feed back into manifest_parts. The C3 test
detects this directly: it asserts post-resume file_log and
manifest_parts are coherent.
The migration commit (e9b0796) initially moved file_log writes to the
post-scope drain (matching chunked_parallel’s shape). C3 failed
immediately. The fix: write file_log synchronously per chunk in
the worker (via StateStore::open_at_ref(&state_ref) — see “Known
performance smell” below; the earlier StateStore::open(&config_path_w)
variant was removed because rivet apply dispatches the runner with an
empty config_path, so StateStore::open("") resolved to a stray
./.rivet_state.db and silently stranded the durable-part rows),
push the PartRecord to the shared Vec,
and have the parent drain call record_part(state=None, …) so the
manifest_parts + counters + journal half runs once without
double-writing the file_log.
Effect: per-chunk durability of file_log survives any crash. The
crash window for manifest_parts is the same scope-join-to-drain-end
microsecond interval as chunked_parallel’s, but the file_log half
that’s actually needed for resume is already durable.
Decision
The asymmetry is kept because each side optimizes for its runner’s resume semantics:
chunked_parallelhas no resume — the only consumer of file_log during this run is the post-run report. Coalescing all three writes into the drain is correct and simpler.parallel_checkpointhas resume — the resume path reads file_log directly without rebuilding from in-memory state. Per-chunk file_log durability is load-bearing for C3-class crashes.
The other four runners are inline per-part because they are single-threaded — there is no worker/parent split forcing the question.
Known performance smell: per-chunk StateStore::open
The parallel_checkpoint worker opens a fresh StateStore connection
per chunk just to call record_durable_part. StateStore::open on
SQLite takes ~1-5 ms (cold) — for a 1000-chunk run that amortizes to
~1-5 seconds of overhead.
This is not fixed in this release. The clean fix is a
record_durable_part_at_ref(&StateRef, …) helper in
state::file_log that uses the shared StateRef::Sqlite(path)
without re-opening — matching the surviving *_at_ref pattern
(claim_next_chunk_task_at_ref; complete_chunk_task /
fail_chunk_task are now plain methods invoked after
StateStore::open_at_ref). ~50 lines of state-crate work.
Tracked as follow-up; this ADR exists so future readers see the smell was conscious and addressable, not a hidden footgun.
Consequences
Positive
- Each runner’s crash-window semantics are explicit and matched to its resume contract.
- The eight runners share the maximum possible code (
commit::record_partbody) — the asymmetry is at the caller layer, not inrecord_partitself. - C3 at-least-once durability under worker-crash is preserved for the resumable parallel engine without forcing the non-resumable one to pay the per-chunk-open cost.
Negative
- Two runners have non-obvious file_log timing. New contributors who
read
chunked_parallelfirst might assume the same pattern applies toparallel_checkpoint, or vice versa. This ADR is the short-circuit. - The
StateStore::openper chunk inparallel_checkpointis a known performance smell, not fixed in this release.
Amendment 2026-09-24 — the drain is one module
The four parallel runners (plain chunked, parallel checkpoint, parallel keyset,
parallel Mongo) no longer write their own post-join drain. Workers publish parts,
observations, committed checksums and failures to pipeline::fan_in::FanIn, and
FanIn::finish drains them on the parent in one fixed order: governor log,
observations, every durable part through commit::record_part, committed
checksums, then the bail. The asymmetry this ADR keeps is now the file_log
argument of finish — None where the worker already wrote file_log (parallel
checkpoint; parallel keyset on a checkpoint run), Some(state) where the drain
writes it (plain chunked, parallel Mongo, non-checkpoint keyset). The timing is
unchanged; it is stated at one call site per runner instead of implied by a loop.
Measured reason, not a refactor for its own sake: three of the four drains had already diverged — observations fed below the bail in both chunked runners (the ledger’s contract is above it), inline copies of the governor guards in keyset, and a panicking Mongo worker handing back nothing it had written. Work distribution (spawner, pool, per-range) and the reads (ADR-0028) stay per runner.
References
src/pipeline/commit.rs— the sharedrecord_partbody that runs in all eight runners.src/pipeline/run_store.rs— cursor + progression ordering at the next layer (see ADR-0018).src/pipeline/chunked/exec.rs—chunked_parallelrunner with post-scope drain.src/pipeline/chunked/parallel_checkpoint.rs— split-write runner with worker-sync file_log + post-scope drain for the rest.tests/live_chunked_recovery.rs::parallel_chunked_crash_after_chunk_complete_resume_finishes_with_no_duplicates(C3) — the test that pins per-chunk file_log durability for the resumable engine.- ADR-0001 — state invariants I1-I8; this ADR specializes the I2 → I3 crash window per runner.
- ADR-0010 — two parallel engines (in-process chunked vs subprocess fan-out); this ADR is about a different parallelism axis (chunked workers within one process).
ADR-0018: Builder Facades for Runner-Level Invariant Ordering
Status: Accepted Date: 2026-05-30
Context
ADR-0001 defines eight state-update invariants (I1-I8) that govern the ordering of writes a runner makes around each part it commits. ADR-0008 PG2 defines a separate ordering invariant for the cursor + schema + progression tail. ADR-0012 M1 defines the manifest-parts contract on top.
Before the session that produced this ADR, those orderings were held by
convention at every call site. Each of the (at that point) five
runners — single, keyset, chunked/exec::run_chunked_sequential,
chunked/exec::run_chunked_parallel, chunked/sequential_checkpoint,
plus the now-added chunked/parallel_checkpoint — hand-wrote the
per-part write block (I1 finalize → dest.write → I2/M1 manifest add →
I7 file-log → counters → journal). They also hand-wrote the
post-finalize cursor + progression block. Drift accumulated:
keysetnever bumpedfiles_committedand had no fault hooks.parallel_checkpointnever populatedsummary.manifest_partsat all — the cloud manifest M1 contract was silently empty for everyparallel>1 + chunk_checkpoint:truerun. Documented in commite9b0796.parallel_checkpointopened a freshStateStoreconnection per chunk just to writefile_log. Performance smell, also documented.single’s incremental block (cursor + progression) and chunkedrecord_chunked_commitdisagreed on per-write failure semantics in their comments (and in one case, in their code).
The fix shipped over four commits (034fa64, 1db8eba, bb27336,
e9b0796 for commit::record_part; 58c2c5d for RunStore). This
ADR documents the architectural pattern those commits picked and why.
Decision
Two builder facades own the two ordered-write groups:
pipeline::commit::record_part — per-part commit ordering
Two-seam split keyed on the parallel-engine fork:
commit::write_part_file(dest, tmp_path, rows, file_name) -> Result<PartRecord>— ADR-0001 I1 (finalize) +dest.write+ ADR-0012 M3 fingerprint. Worker-safe: takes no shared run state, can run off-thread.commit::record_part(plan, summary, state, &PartRecord, kind) -> ()— ADR-0001 I2 fault hook + counters (bytes_written,files_produced,files_committed) + ADR-0012 M1manifest_parts.push+ journal event (variant chosen byPartKind:RunEvent::FileWrittenforFile,RunEvent::ChunkCompletedforChunk;PagereusesChunkCompletedfor journal-on-disk back-compat — there is no separateKeysetPageWrittenvariant) + ADR-0001 I7state.record_file(warn-on-fail) + I3 fault hook. Parent-only: touches&mut summaryandOption<&StateStore>.
Sequential runners call both inline per part; the parallel engine
calls write_part_file in workers and pushes PartRecords through a
shared Mutex<Vec<…>>, then the parent calls record_part on each
during a post-scope drain (see ADR-0017 for why one variant of this
splits further).
PartKind is a closed enum (File { part_index } for snapshot;
Chunk { chunk_index } for chunked / checkpoint; Page { page_index }
for keyset). The journal-event mapping is internal to record_part,
keeping the per-call-site signature uniform.
pipeline::run_store::RunStore — post-finalize cursor + progression
Builder over the two ordered post-finalize writes:
#![allow(unused)]
fn main() {
RunStore::finalize(state, plan, summary)
.with_cursor(last_val) // I3 — fatal on error
.with_progression(Progression::Incremental {…}) // PG2 — warn-on-fail
.commit()?;
}commit() writes cursor first (fatal on error, returns directly
without attempting the progression write — a half-finalized run would
log a misleading progression boundary), then dispatches
Progression::Incremental to state.record_committed_incremental or
Progression::Chunked to chunked::record_chunked_commit (which
walks chunk_task to pick the highest completed chunk_index — see
ADR-0008 PG2). The after_cursor_commit test fault hook fires inside
the facade so every runner inherits it.
Scope locked at cursor + progression. Schema (with drift policy)
stays in single.rs::run_single_export because schema-drift detection
- Continue/Warn/Fail policy is a runner-level state machine that
does not generalize across modes. Metric writes
(
state.record_metric) stay injob.rsbecause they belong on the Coordinator layer (ADR-0003 L4), not on the runner-level Persistence layer (L3) the facade addresses.
Update (2026-06-18, ADR-0021): the schema-drift carve-out above was wrong. Adding
on_schema_driftto the chunked modes (ADR-0021) showed the Continue/Warn/Fail policy does generalize — what differs between modes is only the column source: single mode resolves columns post-write from the sink’s data-derived Arrow schema; chunked resolves them pre-chunk from a scan-freetype_mappingsprobe sofailaborts before any chunk writes. That difference is exactly one adapter each over a shared core, so schema-drift became the third runner-write facade,pipeline::schema_drift(check_from_sink_schema/check_from_type_mappingsover a privatecheck_and_persist), alongsidecommit::record_partandRunStore. The deletion test confirms its depth: inlining it back would re-duplicate the detect → policy → store state machine across single mode plus the four chunked Detect arms.
Update (2026-07, feat/parallel-keyset): a 7th runner landed —
keyset_parallel(N row-percentile-range workers, per-range crash-recovery; see ADR-0017’s new row). It re-confirmed the standing gap: the facades make the per-part / cursor / drift logic live once, but calling them is still per-runner convention, and the completeness ledger (runner-coverage-matrix.yaml) models 4 runners for ~8 loops — so a runner that owns its loop can still forget a facade (iteration 1 of this branch shippedkeyset_parallelwithout the drift gate; a human caught it, not a guard). The fix extendscheck_post_run_invariants(already the structural guard for the M1manifest_partsgap) to the drift + Form-B facades: each leaves a telltale onRunSummarywhen it runs (schema_changed = Some(_);column_checksumspopulated or..._incompleteset), and astate_backedsuccess that committed parts with either telltale ABSENT panics in debug/test. This makes “you called the facade” machine-checked for the two write-groups the M1 assert didn’t cover — the runner-bypass class becomes RED-by-construction, not a matrix cell a reviewer maintains by hand. It does NOT reopen facade-vs-trait; the facades stay, only their invocation is now verified.
Why “builder” instead of one method with Option args
Three shapes were considered:
| Shape | Tradeoff |
|---|---|
| Builder (chosen) | Callers chain only what they have. Chunked runners with no cursor skip with_cursor; snapshot runs skip both with_* and commit() is a no-op. Ordering enforced inside commit() regardless of chain order. |
Single method + Option-struct | One call-site, all writes visible. But chunked runners write Writes { cursor: None, progression: Some(…) } — noisy. |
| Type-state | Compiler-enforced ordering. Overkill for two optional writes; idiomatic Rust does not lean on this for this scale. |
| Multiple methods on a stateful handle | Ordering becomes “the order you call methods in” — convention-at-call-site, just with a different surface. Defeats the point. |
Builder is the balance: variable writes fit cleanly, ordering rule lives once in the impl, ceremony is bounded.
Why “facade” not “trait”
Neither commit::record_part nor RunStore is a trait. The runners
share an implementation pattern (call the facade in the right
place with the right args), not an interface contract. A trait would
require a Run-level abstraction the runners can swap out at runtime —
no such abstraction exists or is needed. The facade is a free function
(for commit_part) or a builder struct (for RunStore); callers
invoke it directly.
This matches ADR-0015’s “data-shape seam vs trait” reasoning at a different layer: the seam value comes from concentrating implementation logic, not from substitutability.
Trade-offs
Positive
- Locality: ordering rules for I1→I3 and PG2 live in one implementation each. Per-write failure semantics (fatal vs warn-on-fail) is in the signature of the builder methods, not in comments at every call site.
- Leverage: six runners (after the OPT-4 keyset and the parallel_checkpoint additions) share one body each. New runners inherit the contract by construction.
- Drift prevention: the M1 gap that parallel_checkpoint had
(silently empty
manifest_parts) is structurally impossible under the facade —record_partalways appends tomanifest_partswhen called. Documented as the retroactive guard provided by thecfg!(debug_assertions)coherence check inpipeline::finalize::finalize_manifest. - Fault-hook centralization:
after_file_write,after_manifest_update,after_cursor_committest fault points fire once per facade, not once per runner-specific re-implementation of the hooks.
Negative
- The runner-write surface is now three facades, not one:
commit::record_part(per-part),RunStore(post-finalize), andschema_drift(pre-chunk / post-write — added by ADR-0021). Metrics stay above on the Coordinator layer. A new contributor must learn where each ordered-write group lives instead of finding them all in one place. - Builder-with-fluent-chain may feel unidiomatic in Rust where most ordered writes are direct function calls. ADR-0017 explains the per-runner asymmetry that motivated the chain.
- Test surface includes both seam-level unit tests (in
commit.rsandrun_store.rs) and runner-level live tests (the existinglive_chunked_recovery,live_crash_recoverysuites). New runners need both layers of coverage.
When this should be revisited
- If a fourth ordered-write group emerges at the runner level (e.g.,
per-run lineage tracking, audit log of source queries) that does not
fit cursor/progression or per-part: extend
RunStorewith a thirdwith_*method rather than building a third facade. (Schema-drift, added later as its own facade per ADR-0021, is not a counter-example to this rule: it is a detect → policy → store decision keyed on column-source, run pre-chunk or post-write — not a post-finalize ordered write that fitsRunStore’s cursor/progression shape. A true post-finalize fourth write should still extendRunStore.) - If a runner needs to dispatch between different per-part commit
strategies at runtime (today every runner uses the same
write_part_file→record_part): re-evaluate the facade-vs-trait choice. Until then, free functions are correct.
References
src/pipeline/commit.rs—write_part_file,record_part,PartKinddefinitions; module doc covers the in-step ordering rationale.src/pipeline/run_store.rs—RunStore,Progression; module doc covers per-write failure model.src/pipeline/summary.rs::RunSummary::check_post_run_invariants— runtime debug_assert that catches a runner bypassing the facade.- ADR-0001 — state invariants I1-I8.
- ADR-0008 — export progression, PG2 ordering.
- ADR-0012 — cloud manifest contract, M1 / M3.
- ADR-0015 — data-shape seam vs trait (parallel reasoning at the source-introspection layer).
- ADR-0017 — per-runner durability ordering map (when the facade is called sync per-part vs in a post-scope drain).
- ADR-0019 — Governor extraction (similar deepening pattern at a different layer).
- Session commits:
034fa64(extract commit),1db8eba(chunked migration),bb27336(sequential_checkpoint migration),e9b0796(parallel_checkpoint M1 gap fix),58c2c5d(RunStore).
Amendment 2026-09-26: the invariant is RED in debug and at the release gate
The coherence check runs in every build. A debug or test build panics. The release binary logs
run-integrity invariant violated at WARN and still exits 0, so a user’s run is never failed
by it. The release oracle fails the gate on any occurrence of that line in any gated command’s
output (dev/release_oracle/core.py, verify_no_invariant_violations). The drift telltale is
not enforced on --resume runs.
ADR-0019: Governor as Extracted Policy with Injectable PressureSource
Status: Accepted Date: 2026-05-30
Context
The OPT-2 adaptive concurrency governor — the loop that samples source
write-pressure (pg_stat_bgwriter.checkpoints_req on PostgreSQL,
Innodb_log_waits on MySQL) and resizes the worker semaphore on
chunked + parallel > 1 runs — shipped originally (commit 141bf33)
as a 44-line inline closure inside std::thread::scope in
pipeline::chunked::exec::run_chunked_parallel. The decision policy
(tuning::next_parallel, tuning::GovernorState) was a separate pure
module from day one; the loop body wrapping it was not.
Live coverage was the only way to exercise governor behaviour under
pressure (tests/live/live_governor.rs):
governor_activates_and_run_completes— verifies the governor arms and the run finishes.governor_backs_off_under_concurrent_write_pressure(commitc8a4150) — drives the closed loop with a background CHECKPOINT writer; takes 2-4 s wall and depends on a live Postgres + tightRIVET_GOVERNOR_INTERVAL_MSenv override.governor_does_not_deadlock_when_chunks_fail— regression for thethread::scopedeadlock fixed in16fc662.
Issues with the inline-closure shape:
- The loop body was not callable without a
Box<dyn Source>monitor and a&AtomicUsizeforfinished— both require either a live database or non-trivial shared-state plumbing in any test. - Behaviour under pressure could be observed only with multi-second
wall-clock tests, which masked timing-sensitive bugs (the deadlock
fix in
16fc662was missed for ~four hours of staring at the live test before the regression test was structured to catch it deterministically). - The
RIVET_GOVERNOR_INTERVAL_MSenv override lived inline as alet sample_ms = std::env::var(…).ok()…unwrap_or(GOVERNOR_SAMPLE_INTERVAL_MS), with the poll-interval clamp scattered separately. Two tunables, one ad-hoc reads.
Decision
Extract the loop body into tuning::Governor (in
src/tuning/adaptive.rs, re-exported as crate::tuning::Governor) and
the pressure dependency into a narrow tuning::adaptive::PressureSource
trait (not re-exported). The runner-side binding (resize
semaphore + log + record off-thread decision) stays where it is — the
extraction is the loop policy, not the runner-specific side effects.
[Update 2026-08: the runner-side binding has since moved too — into the
separate shared wiring module src/pipeline/governor.rs
(GovernorHarness, commit ab0b6d7), used by both the chunked and
keyset parallel runners. pipeline::governor is a different thing from
tuning::Governor, the loop policy this ADR extracts.]
Governor struct surface
#![allow(unused)]
fn main() {
pub struct Governor {
state: GovernorState, // existing pure decision state
sample_interval: Duration, // RIVET_GOVERNOR_INTERVAL_MS or default
poll_interval: Duration, // clamped to sample_interval
}
impl Governor {
pub fn new(start, floor, ceiling) -> Self; // production: reads env
#[cfg(test)]
pub fn with_intervals(start, floor, ceiling, sample, poll) -> Self;
pub fn tick(&mut self, sample: Option<u64>) -> Option<(usize, usize)>;
pub fn run<S, Stop, Decide>(
&mut self,
source: &mut S,
stop: Stop,
mut on_decision: Decide,
) where
S: PressureSource + ?Sized,
Stop: Fn() -> bool,
Decide: FnMut(usize, usize);
}
}tick is the pure decision step (delegates to GovernorState::observe).
run is the loop: poll → check stop → sample → tick → callback. The
runner calls run(&mut monitor, || finished.load() >= total, |from, to| { semaphore.resize(to); log; …}).
PressureSource trait
#![allow(unused)]
fn main() {
pub trait PressureSource: Send {
fn sample_pressure(&mut self) -> Option<u64>;
}
impl PressureSource for Box<dyn crate::source::Source> {
fn sample_pressure(&mut self) -> Option<u64> {
crate::source::Source::sample_pressure(self.as_mut())
}
}
}Send because the runner spawns the governor on its own thread inside
thread::scope. The blanket impl lets the production runner pass its
already-built monitor connection directly; tests pass a VecSource
that hands out canned samples.
Why PressureSource lives in tuning:: not source::
The Source trait (in src/source/mod.rs) is the full extraction
contract: export(query, sink), query_scalar, type_mappings, +
sample_pressure. It is L2 / L3 per ADR-0003 — a vendor-bound type
implemented once per engine.
PressureSource is what the governor needs, not what an engine
provides. It is one method, narrower than Source, with a different
lifecycle (the governor owns the monitor connection separately from
the worker pool’s connections; see run_chunked_parallel’s
governor_monitor: Option<Box<dyn Source>>).
Putting PressureSource in tuning:: keeps the dependency direction
correct: tuning::adaptive defines the trait, source::* types that
impl Source get the blanket impl for free, and the governor never
needs to depend on the full Source surface. ADR-0011 (Source:
Send not Sync) is preserved — PressureSource: Send matches and
the blanket impl is compatible.
Why a struct, not just functions
Governor owns three runtime-coupled pieces:
GovernorState(mutated across ticks)sample_intervalandpoll_interval(related: poll must be ≤ sample, and both come from the same env-var resolution path)- The next-sample deadline (
last_sample: Instant) — internal torun, not exposed
Bundling them makes the “what to fake, what to inject” boundary
obvious: PressureSource is the dependency, the on_decision
callback is the runner-side effect, the rest is policy.
Test surface
Unit tests (in src/tuning/adaptive.rs::tests), driven on a fake
VecSource:
governor_tick_mirrors_governor_state_observe— pinstickas a faithful surface for the pure decision; catches a future drift between the struct’stickand the underlyingGovernorState::observe.governor_run_emits_decisions_for_every_rising_sample_until_stop— drives the loop on canned rising samples, asserts the exact decision sequence ((6, 5), (5, 4), (4, 3), (3, 2)) reaches the callback. Stop predicate keys on the sample counter (via sharedArc<AtomicUsize>), not the decision counter — the first sample only sets the baseline (no decision), so keying on decisions deadlocks the loop. This shape was found and fixed during implementation of this ADR’s work; the test now documents the failure mode it survived.governor_run_stops_promptly_within_one_poll_quantum— regression cover for the16fc662deadlock-class bug: the stop predicate must exit the loop within one poll interval, not be deferred to the next full sample interval.
The live tests stay as they are — they cover the production wiring (env var resolution, real source connection, thread-scope teardown), which the unit tests cannot exercise.
Consequences
Positive
- Governor policy is exercisable in microseconds on a fake source, without a live database.
- The deadlock class of bugs (
16fc662) has a unit-level regression cover that fires deterministically, not as a 30-s wall-clock watchdog test. - The
RIVET_GOVERNOR_INTERVAL_MSenv-var resolution + the poll/sample clamp lives in one place (Governor::new). Tests useGovernor::with_intervalsto set explicit values without mutating process-global env state. - The runner-side closure in
run_chunked_parallelshrinks from 44 lines to a 14-line callback that does only resize + log + push to off-thread decision log. [Update: that callback was later extracted intosrc/pipeline/governor.rs::GovernorHarness::spawn_into(commitab0b6d7), shared by the chunked and keyset parallel runners.]
Negative
PressureSourceis a new trait operators don’t write (only Rivet internals implement it). The trait exists for testability, not external extension. Per LANGUAGE.md, “one adapter = hypothetical seam, two adapters = real seam” — here the two adapters are the productionBox<dyn Source>blanket impl and the testVecSource. Real seam by the second-adapter rule, but the “real” adapter is always test-side; some readers may find this thin.- Indirection: the inline closure was one place; now there’s
Governor+PressureSource+ the callback. New contributors who want to understand “what happens when pressure rises” trace one extra hop throughtuning::adaptive.
When to revisit
- If a second loop-level governor concept ships (e.g., a memory-budget
governor, a destination-backpressure governor), unify the loop shape
across them — the
run(source, stop, on_decision)pattern generalizes cleanly. - If
PressureSourcegains a second non-test impl (e.g., a synthetic pressure source for chaos testing in production), promote the trait to a more visible location (the governor loop andPressureSourceare now consumed by both parallel runners — chunked,src/pipeline/chunked/exec.rs, and keyset,src/pipeline/keyset.rs— through the dedicated shared wiring modulesrc/pipeline/governor.rs(GovernorHarness::arm/spawn_into/drain_into); the trait itself still lives insrc/tuning/adaptive.rs).
Update 2026-08-13 — the governor gets its own pressure signal
The extraction preserved a coupling this ADR did not name: the governor
sampled Source::sample_pressure — the SAME counter the adaptive batch loop
uses. When that counter was later re-pointed at own-read spill proxies
(MySQL Created_tmp_disk_tables for the batch loop’s benefit; MSSQL
Workfiles/Worktables Created, which — correction — only the governor ever
consumed: MSSQL’s batch loop has no pressure sampling), the governor
silently inherited a signal its own workload inflates. On keyset exports (pages spill by design) it read its own
exhaust as “pressure rising”, shed to the floor, and never recovered —
measured in a production pool run as 2–2.7× per-export slowdowns, +1h48m
makespan, on a source with no foreign load. The fix separates the signals:
Source::sample_governor_pressure (write/redo counters a read-only export
cannot move — PG checkpoints_req, MySQL Innodb_log_waits, MSSQL Log Flush Waits/sec) feeds the governor; the batch loop keeps the spill
counters. Sheds now log at WARN (an invisible deliberate slowdown is the
info-level trap the sparse-chunk rule already names).
References
src/tuning/adaptive.rs—Governor,PressureSource,tick,run, with unit tests at the bottom of the module.src/tuning/mod.rs— re-exportsGovernoronly (not the trait or the constants — those are internal).src/pipeline/chunked/exec.rs::run_chunked_parallel— call site; the runner-side binding (resize + log + off-thread decision push) was extracted intosrc/pipeline/governor.rs::GovernorHarness::spawn_into(commitab0b6d7), shared by the chunked and keyset parallel runners, so the runner now only callsGovernorHarness::arm/spawn_into/drain_into.tests/live/live_governor.rs— the four live tests that cover production wiring (the original three pluskeyset_governor_backs_off_under_concurrent_write_pressure, added when the governor was shared with the keyset runner).- ADR-0011 —
Source: Send not Sync.PressureSource: Sendmatches. - ADR-0017 — durability ordering map; the governor’s worker is one of the parallel-engine workers covered there.
- ADR-0018 — Builder facades for runner-invariant ordering; the Governor extraction is a separate deepening at the policy-loop layer.
- Session commits:
141bf33(original inline closure),16fc662(deadlock fix),c8a4150(back-off live test),c7cb7f3(this ADR’s extraction work).
ADR-0020: PostgreSQL UUID-PK Tables — Chunking Asymmetry vs MySQL
Status: Accepted (partial: layer 2 closed; layer 1 deferred) Date: 2026-05-30
Context
Production tables with non-integer primary keys (most commonly UUID) are
the canonical case where rivet’s range-chunked execution path
(SELECT … WHERE id BETWEEN low AND high) does not apply: there is no
total ordering on UUID values that maps cleanly to integer ranges. OPT-4
shipped keyset (seek) pagination for exactly this case
(WHERE id > '<last>' ORDER BY id LIMIT n), which works on any
single-column, NOT NULL, UNIQUE key regardless of underlying type.
A live-test sweep added in this session
(tests/live/live_keyset.rs::keyset_pg_uuid_pk_via_explicit_chunk_by_key_roundtrips_full_set
and friends) surfaced two distinct layers of why PG UUID-PK
chunking was not working end-to-end:
Layer 1 — Planner: PG does not auto-keyset on non-int PK
src/plan/build.rs::resolve_chunked_strategy deliberately scopes the
auto-keyset fallback to MySQL only:
#![allow(unused)]
fn main() {
if config.source.source_type == crate::config::SourceType::Mysql
&& let Some(key) = introspection.auto_keyset_key()
{
// … auto-select Keyset strategy
return Ok(ExtractionStrategy::Keyset(KeysetPlan { … }));
}
anyhow::bail!("no safe shape … use mode: full");
}The rationale in the comment:
“MySQL has no server-side cursor, so a non-int-PK table has no safe range-chunk shape… PG keeps refusing — its
DECLARE CURSORsnapshot is already bounded, somode: fullis the safe answer there.”
This is partially true. PG DECLARE CURSOR bounds client-side RAM
(rows do not materialise into the client all at once), which is the
property that makes mode: full “safe” in the OOM sense. It does not
bound:
- Wall time of the long-open query: a single cursor over a 100M-row UUID-PK table holds a transaction open for tens of minutes — every network blip, every server restart, every long-running operator session dies on that snapshot.
- Server-side resource hold: an open cursor pins a transaction
snapshot, blocking vacuum / freeze on the underlying tuples; on a
busy OLTP source this lengthens
xminhorizon and can spook DBAs. - Network latency cost on hand-offs: long-running session over a bouncer / proxy layer is more likely to die mid-fetch than many short keyset pages would be.
So mode: full is RAM-safe but not durability-safe for the large
UUID-PK table the operator most needs chunking for.
Layer 2 — Sink runtime: FixedSizeBinary(16) was unsupported
Even when an operator opted in explicitly via
chunk_by_key: <uuid_col> (the documented escape hatch from layer 1),
the keyset runtime failed at page 0:
export 'X': keyset could not read the 'id' value from the last row
of page 0 (NULL or unsupported type) — cannot advance safely.
The key must be NOT NULL and one of: integer, float, string,
timestamp, date.
src/pipeline/sink/cursor.rs::extract_last_cursor_value had arms for
Int{16,32,64}, Float64, Utf8, Timestamp(µs), and Date32. PG
uuid maps to Arrow FixedSizeBinary(16) (per ADR-0014 §“UUID”:
parquet-rs emits native LogicalType::Uuid via the arrow.uuid
extension type, and the 16-byte canonical encoding is the inter-engine
contract). With no FixedSizeBinary(16) arm, the helper returned
None, the keyset runner bailed with “unsupported type”, and even the
explicit-key path was dead.
Decision
Layer 2 (this commit): close the sink-runtime gap
Add a DataType::FixedSizeBinary(16) arm to
extract_last_cursor_value that decodes the 16 bytes into the
canonical xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx form. The keyset query
builder’s PG path (cursor_rhs(SourceType::Postgres, …)) already emits
E'<value>' literals that PG implicitly casts to the column’s type, so
no separate UUID-cast logic is needed in the query builder — the
server-side cast id > E'<uuid>' resolves to id > '<uuid>'::uuid
because id’s type is known.
Update the error-message supported-types list to include uuid. Add
two unit tests (cursor_fixed_size_binary_16_decodes_to_canonical_uuid_string,
cursor_fixed_size_binary_wrong_length_returns_none — defensive
against a non-16 array landing where 16 was expected) and a live
round-trip test
(keyset_pg_uuid_pk_via_explicit_chunk_by_key_roundtrips_full_set)
that proves the full operator path works.
Layer 1 (deferred): planner auto-resolution stays MySQL-only
Do not flip the if SourceType::Mysql guard in
resolve_chunked_strategy to also auto-keyset PG. Reason: this is a
behaviour-changing default that affects every PG-UUID-PK export run by
every existing config, and the comment’s “DECLARE CURSOR is bounded”
rationale, while incomplete, is not wrong for small-to-medium
tables. An operator who knows their PG UUID table is small can prefer
the simpler mode: full path; an operator who knows it is huge has the
escape hatch (chunk_by_key: <col>) and now (layer 2 closed) it works.
Promote layer 1 to a decision after a real operator request, not on the strength of “we technically can”.
Operator UX as of this ADR
| Source | PK type | Supported paths |
|---|---|---|
| PG | bigint / int PK | mode: chunked auto-selects range chunking ✓ |
| PG | UUID PK | mode: full (snapshot) ✓ mode: chunked + explicit chunk_by_key: <col> ✓ (since this ADR) mode: chunked without explicit key — bails with “no safe shape” actionable error ✗ |
| PG | TEXT / VARCHAR unique key | Same as UUID — explicit chunk_by_key: ✓ |
| MySQL | bigint / int PK | mode: chunked auto-selects range chunking ✓ |
| MySQL | CHAR(36) UUID PK | mode: chunked auto-selects keyset on the UUID column (OPT-4) ✓ |
| MySQL | VARCHAR unique PK | Same — auto-keyset ✓ |
The PG row has the largest column-spread: this ADR documents why and which path to use when.
Consequences
Positive
- The PG UUID-PK chunking path is now functional end-to-end via the
explicit
chunk_by_key:option. Operators with 100M-row UUID tables can opt in and avoid the long-cursormode: fullrisk. - The sink seam’s supported-types list is correct: live error messages match the actual code arms.
- Layer 1’s planner asymmetry is now documented, not implicit. A future operator request to flip the default can be evaluated against this paper trail.
Negative
- Operators who write configs against a UUID-PK PG table without
reading this ADR will hit the “no safe shape” actionable error and
need to choose between
mode: fullandchunk_by_key:explicitly. The error message points at the choice, but it is an extra step versus MySQL’s auto-resolution. - Layer 1 remains an inconsistency between engines — the rivet invariant of “same YAML, same outcome on either engine” does not hold for the UUID-PK case.
Trigger for revisiting layer 1
Open this ADR back up to “Proposed” when any of the following holds:
- An operator reports a real production case where
mode: fullover PGDECLARE CURSORhit a wall-time or vacuum-horizon failure on a large UUID-PK table. - A second non-int PG keyset request lands (e.g.,
TEXTPK or composite key — once two real cases exist, the inconsistency becomes harder to defend on “small table assumption” grounds alone). - The MySQL keyset path acquires non-trivial behaviour the PG path lacks (e.g., explicit timestamp keyset, hash-partitioned source) — keeping the two engines symmetric becomes the cheaper option.
References
src/pipeline/sink/cursor.rs::extract_last_cursor_value— theFixedSizeBinary(16)arm + the two new unit tests.src/pipeline/keyset.rs:1195-1198— error message with the updated supported-types list (addsuuid).src/plan/build.rs::chunked_strategy_from_introspectionlines ~705-733 (the split-out decision half ofresolve_chunked_strategy) — theif SourceType::Mysqlguard that constrains layer 1.src/source/query.rs::cursor_rhs— theE'…'literal-with-cast pattern that makes the PG keyset-WHERE path UUID-aware without separate cast logic.tests/live/live_keyset.rs— four live tests covering the four paths in the operator-UX table above:keyset_varchar_pk_roundtrips_full_keyset_across_pages(MySQL)keyset_mysql_uuid_pk_roundtrips_full_keyset_across_pagessnapshot_pg_uuid_pk_roundtrips_full_uuid_set(PG,mode: full)keyset_pg_uuid_pk_via_explicit_chunk_by_key_roundtrips_full_set(PG, explicitchunk_by_key:— closes layer 2 of the gap).
- ADR-0014 — target type materialization (PG
uuid→FixedSizeBinary(16)+arrow.uuidextension type). - ADR-0016 — nullability propagation deferred (related precedent: documents an asymmetric type-faithfulness gap with a deferred trigger).
- ADR-0017 — per-runner durability ordering map (similar shape: acknowledged asymmetry with explicit operator-facing UX).
ADR-0021: Chunked Schema-Drift Detection Runs Pre-Chunk
Status: Accepted Date: 2026-06-18
Context
rivet detects column-level schema drift (added / removed / retyped columns)
against a per-export baseline in export_schema
(state::detect_schema_change + store_schema), driven by
on_schema_drift: warn|continue|fail. Until now this ran only in single
(non-chunked) mode (pipeline::single); the call site’s own comment noted the
state store “is only populated by the drift-detect path below, and not at all in
chunked mode.”
A pilot re-ran a 655k-row table 4× over two days in chunked mode and got no
column-level snapshot at all — export_schema stayed empty, rivet state showed
nothing, and drift could never be detected on later runs. Chunked is the default
for large tables, so the most-exposed exports were exactly the ones without drift
coverage.
Naively replicating the single-mode flow in chunked is wrong for two reasons:
- Timing /
failsemantics. Single detects drift from the sink’s resolved schema andfailaborts before writing. In chunked, by the time a chunk sink resolves a schema the chunk is already written (and parallel modes run many chunks at once) — a post-writefailcannot prevent the corrupt-shaped output it exists to stop. - Statelessness. The non-checkpoint executors (
chunked::exec) are deliberately stateless (noStateStore), so they cannotstore_schemafrom inside the worker loop at all.
Decision
Detect drift once, pre-chunk — in each chunked run function right after chunk
boundaries are computed and before any chunk executes — from a schema
resolved via Source::type_mappings (a metadata-only query; no data scan).
type_mappings → build_arrow_field → arrow_schema_to_columns yields the
same canonical SchemaColumn format single mode derives from the sink, so the
baselines are comparable.
fail then aborts before the first chunk writes — matching single’s intent;
warn / continue store-or-update the baseline. The logic lives in
pipeline::schema_drift as one deep core (check_and_persist: detect → policy
→ store) behind two thin column-source adapters — check_from_sink_schema
(post-write, sink schema: used by the single, keyset, and parallel-Mongo
runners) and check_from_type_mappings (chunked,
pre-chunk, type_mappings schema). The four chunked Detect arms reach the
chunked adapter through one shared preamble, prepare_chunk_plan (compute chunk
ranges → run the pre-chunk drift check), rather than re-implementing
detect-then-check per runner. This makes schema_drift the third runner-write
facade alongside commit::record_part and RunStore, superseding ADR-0018’s
note that drift “does not generalize across modes” (see that ADR’s 2026-06-18
update).
Consequences
- All chunked modes (sequential / parallel, checkpoint / non-checkpoint) gain the
column-level drift parity single has;
export_schemaandrivet stateare populated for chunked exports. - One extra metadata round-trip per chunked Detect run (zero-row
type_mappings) — negligible against the chunk scans, and itself source-friendly. - Cross-mode caveat. A baseline stored by single (data-derived sink schema)
and one stored by chunked (
type_mappingsschema) can differ for types rivet infers from data rather than the catalog (e.g. a decimal scale that is a placeholder intype_mappingsuntil a value is observed). Within one mode this is consistent; switching an export between single and chunked may log a one-time drift that self-heals on the next run. Acceptable — documented here so a future contributor does not chase a phantom. - Resume /
Precomputedchunk sources skip the pre-check (drift was already evaluated on the original Detect run that planned the chunks).
Amendment 2026-09-26: resume and apply run the pre-chunk check too
Superseded in part: resume and precomputed (rivet apply) chunk sources now run the pre-chunk
drift check as well (check_drift_only, check_drift_only_fresh), because the drift this
guards against happens between the plan or the crash and the resume or the apply. The only
skip is a precomputed plan with no ranges.
ADR-0022: Inter-Batch Throttle Paces by Rows Pulled, Not Per Batch
Status: Accepted Date: 2026-06-22
Context
Every per-engine export loop calls AdaptiveBatchController::throttle() after
emitting a batch, to pace the source (“be gentle”). The balanced profile sets
throttle_ms: 50, safe 500, fast 0. Until now throttle() was a flat
std::thread::sleep(throttle_ms) — a fixed sleep per batch.
That makes the throttle’s total cost batch_count × throttle_ms, and
batch_count is not a stable property of the data: PostgreSQL caps FETCH N
under work_mem × 0.7 to avoid a pgsql_tmp/ spill, so a wide table is read
in many small batches. On content_items (1.93 M rows, ~20 wide text/jsonb
columns, default 4 MB work_mem) the FETCH is capped to ~420 rows → ~4 560
batches → ~228 s of thread::sleep, i.e. 74 % of wall-clock (confirmed by
a sample profile: the main thread is overwhelmingly in thread::sleep, not in
the row→Arrow→Parquet work).
The measured payoff of that 228 s of pacing, read from rivet’s own export_harm
counters, was ~0: with throttle_ms: 50 vs 0 the source returned the same
pg_tup_returned (1.938 M vs 1.932 M), read the same pg_blks_read (153 104 vs
153 040), and spilled zero temp files — identical cumulative harm, output
byte-identical. Worse, the throttled run held the cursor’s MVCC snapshot 6×
longer (270 s vs 42 s), which on a busy OLTP source blocks vacuum and widens
replication lag — the opposite of gentleness. Re-measured by the cross-tool
harness (dev/bench/smoke.py): dropping the balanced 50 ms/batch throttle
(tuning.profile: fast) buys +24 % rows/s with no worse harm — see
docs/bench/report.html.
The throttle was targeting the wrong variable. Cumulative source harm tracks the
query (a full scan), and a sensible rate limit tracks rows (or bytes) per
second — neither tracks batch count, which work_mem controls.
Decision
Make the throttle row-proportional: scale throttle_ms by the fraction of a
full configured-size batch the emitted batch represents, computed in
microseconds so small batches don’t truncate to zero.
sleep_µs = throttle_ms × 1000 × rows_in_batch / configured_batch_size
Total throttle over a run becomes throttle_ms × total_rows / configured —
independent of how many batches the row source was split into. throttle()
now takes the batch’s row count; all three engines pass it (row_count /
batch.num_rows() / buf.len()). The arithmetic lives in a pure
throttle_sleep_us() so it is unit-tested without timing.
Calibration is preserved, not invented: a full configured-size batch (the
narrow-table case, where the FETCH returns batch_size rows) still pauses
exactly throttle_ms — that path is unchanged. Only batches that work_mem
forced below the configured size now pause proportionally less.
We keep throttle_ms (a duration) as the config knob rather than switching to a
fraction or a rows/sec cap: it stays backward-compatible, the profile defaults
(0 / 50 / 500) keep their meaning for the common (full-batch) case, and the fix
is a one-line semantic change at the point of use.
Consequences
balancedon wide tables stops paying ~6× wall-clock for no gentleness.content_itemsfull export: ~270 s → ~52 s (≈ 42 s work + ~9.6 s throttle), output byte-identical,export_harmunchanged. This is a MINOR behaviour change:balanced/saferuns on wide tables finish faster (less idle sleep) for the same source pressure; narrow-table runs are unchanged.- The throttle is now a genuine rate limit (sleep ∝ rows pulled), so it bounds the source’s instantaneous read rate — its one defensible benefit, on a contended source — without the snapshot-hold inflation.
- Microsecond granularity means a sub-200-row FETCH still pauses (e.g. 500 µs for
100 rows) instead of the integer-ms
floorsilently dropping the throttle. The OS may round a sub-ms sleep up to its timer granularity, which only errs toward more throttle (conservative). - Bytes would be more harm-proportional than rows (wide rows cost the source
more per row), but
configuredis a row count and the memory cap already bounds batch bytes; row-proportional is the minimal intent-preserving change. Revisit if a future workload shows row-count pacing materially mis-tracking byte-level source load.
References
docs/bench/report.html— the cross-tool harness that re-measures the throttle’s cost.- ADR-0019 — the governor (adaptive concurrency); this is the per-batch pacing knob, a separate lever.
ADR-0023: The CDC NDJSON and file drivers stay separate (no ChangeSink trait)
Status: Accepted Date: 2026-06-23
Context
CDC has two drivers over the ChangeStream seam:
source::cdc::run()— the NDJSON driver forrivet cdcwithout--output: pulls changes, filters by--table, prints one JSON object per change to stdout, saves the resume checkpoint on a commit boundary.source::cdc::sink::run_to_files()— the typed-file driver forrivet cdc --outputand everymode: cdcrun: buffers, rolls a part at a commit-boundary + threshold, and runs the durable sequence flush → checkpoint → ack (roll_all, with per-tableTableSinkstate, insrc/source/cdc/sink.rs), then writes aRunManifest.
Each architecture pass over CDC flags these two as a duplication and proposes a
single drive(stream, sink) loop with a ChangeSink trait (an NdjsonSink and a
FileSink adapter). One pass even reported it as a bug — “the NDJSON driver
forgot to ack.”
Decision
Keep the two drivers separate. Do not introduce a ChangeSink trait to merge
their loops.
The shared assembly — open the stream (permission/TLS gate), resolve the typed
schema, build the SinkConfig — is already deduped behind one seam,
cdc::run_capture (the CdcCapture assembler), which both the CLI --output
path and the mode: cdc run call. Only the NDJSON driver remains its own loop.
Consequences / reasoning
-
The “missing ack” is not a bug.
ackadvances a consume-on-read source (a PostgreSQL logical slot). The durability rule (ADR-0017 family) is: advance only after a durable write. NDJSON goes to stdout, which is not a durable sink — the downstream consumer owns durability — so advancing the slot would be premature (at-most-once). The NDJSON driver correctly does notack; it saves the checkpoint file (MySQL resume) and lets PostgreSQL re-read from the slot. So the durability logic is correctly file-only, not duplicated. -
The two loop bodies share almost nothing. NDJSON:
to_json+println+ checkpoint-on-commit. File: buffer + byte/row rollover policy +roll_all(flush → checkpoint → ack) + manifest. The only common code is the ~5-line outer skeleton (while next_change { table-filter; <body>; max_events }). -
That skeleton can’t be cleanly extracted as an iterator — the file driver calls
stream.ack()inside the loop, so an iterator that owned the stream would conflict (borrow) with the ack. The only way to share the loop is the heavyChangeSinktrait, to dedupe ~5 lines. -
A
ChangeSinkseam whose two adapters share only a 5-line loop is shallow (the interface is as complex as the shared implementation; near-zero leverage). The deletion test agrees: delete the trait and ~5 trivial lines reappear in two places — complexity does not concentrate.
Re-open if a third output sink appears (e.g. a streaming/Kafka or a
distinct CSV-stream sink) that genuinely shares the commit-boundary + checkpoint
machinery — two adapters made run_capture a real seam; three sinks sharing
durability would make the loop one too. Until then, the duplication is 5 lines and
the seam would be shallow.
Amendment 2026-08-27: the file driver’s transaction buffer has no relief valve
run_to_files() rolls a part at a commit boundary plus a threshold. The
commit-boundary half is load-bearing and stays: should_roll requires
committed (src/source/cdc/sink.rs:106-109), which is what keeps a part from
splitting a source transaction and what makes the flush → checkpoint → ack
sequence atomic per transaction.
The consequence is that the thresholds — rollover, rollover_memory_bytes —
can only take effect AT a commit boundary. A single transaction larger than
memory has nothing to relieve it: it is buffered whole, in RAM, and there is no
spill path in the sink. A bulk UPDATE on a large table is one transaction, so
the failure mode is an OOM kill mid-capture. It is recoverable (the slot was
never acked) and it is also unrecoverable in practice: every retry reproduces
it, so the export cannot progress, and to the operator it is indistinguishable
from a crash.
Decision (proposed). Buffer beyond a threshold to disk, keyed by
transaction. The atomicity invariant is untouched — the part still closes only
at the commit boundary; only the BYTES in between are allowed to leave RAM. The
threshold is a tuning knob with a protective default, merged with is_some()
like its siblings, so a bare profile cannot clobber it to “unbounded” (the
config-clobber rule in the process rules).
Primary prior art. PostgreSQL does exactly this on the server side:
logical_decoding_work_mem bounds the reorder buffer and spills a transaction
past it to disk, precisely because a transaction’s size is not something the
consumer gets to choose. PostgreSQL 14 offers a second, larger answer — the
decoder can stream an in-progress transaction to the client before its commit —
which is worth evaluating against a spill rather than assuming; the spill keeps
the commit-boundary invariant unchanged, streaming does not.
RED-proof before Accepted. A transaction an order of magnitude past the memory bound, captured under a hard RSS ceiling: complete and atomic (all rows in one part, none split across a checkpoint), peak RSS flat. The mutant is the spill threshold set to infinity — the test must OOM or go RED. Per the fixture rule in the process rules the transaction must exceed the bound by enough to force more than one spill, or the spill’s own accumulation arithmetic is untested by construction.
Amendment 2026-08-27: a resume must prove the checkpoint belongs to THIS server
Both drivers save a resume checkpoint on a commit boundary, and the MySQL
checkpoint is {"file": …, "pos": …} and nothing else — the comparable key is
the binlog ordinal plus offset (src/source/cdc/validate.rs:39-52). No server
identity, no GTID set.
A binlog coordinate is meaningless on a different server and plausible on all of
them. Restore a replica, fail over, point a config at a clone, or copy a
checkpoint between environments, and binlog.000042 / 1096 names a real
position on the new server that has nothing to do with the captured one. rivet
resumes from it and reports success.
This is the only member of the 2026-08-27 CDC amendment set with no partial
mitigation anywhere. The other engines are covered by construction: a
PostgreSQL slot is server-side and cannot be carried to another server; SQL
Server floors at fn_cdc_get_min_lsn (over-reads, never skips); MongoDB’s
resume token is rejected by a server that does not recognise it. MySQL alone
accepts a foreign coordinate silently — the same engine that the process rules already
singles out as having no server-side anchor at all.
Decision (proposed). The checkpoint carries the source’s lineage identity, and resume refuses when it does not match. On MySQL that is the server UUID plus the executed GTID set at checkpoint time, with resume permitted only when the checkpoint’s GTID set is contained in the server’s current history. The refusal is loud and names the escape (a fresh full capture); it is never a silent re-anchor. Every engine’s checkpoint states which lineage identity it carries, including the ones whose answer is “the server enforces it” — so an omission is a recorded decision rather than a gap nobody asked about.
Primary prior art. MySQL supplies both primitives directly:
@@GLOBAL.server_uuid identifies the server, and the built-in
GTID_SUBSET(subset, set) answers exactly the containment question against
@@GLOBAL.gtid_executed / @@GLOBAL.gtid_purged. No third-party technique is
involved; this is the vendor’s own answer to “is this position from my history”.
RED-proof before Accepted. Capture against one server, then resume that
checkpoint against a second server seeded differently: the run must FAIL with
the lineage error, not capture. The mutant is the containment check removed. It
must be a real two-server fixture — the stand already runs
rivet-mysql-primary-1 and rivet-mysql-replica-1 — not a hand-edited
checkpoint field, or the test grades its own forgery instead of the product’s
check (the fabricated-input class in the process rules). And per the exit-status rule,
assert the specific error, not merely a non-zero exit.
ADR-0024: Migrate PostgreSQL CDC from test_decoding to pgoutput
Status: accepted (roadmap) — not scheduled; criteria below gate the start.
Context
The PostgreSQL CDC adapter polls a logical slot through the test_decoding
output plugin and parses its human-readable text rendering back into typed
values (src/source/postgres/cdc.rs). The 2026-07 reliability campaign found
27 defects across the CDC surface; 6 of them existed only because of this
text hop — each one a case of the rendering carrying less, or
differently-shaped, information than the wire value:
- UUID rendered as 36-char text → nulled by the 16-byte builder.
bytearendered as\x-hex → carried as text instead of bytes.TIMErendered as text the timestamp-prefix check missed → nulled.INTERVALrendered as PG prose (“1 year 2 mons”) vs batch’s ISO 8601.- Arrays rendered as the
{…}literal → text column instead ofList. timestamptzrendered in the polling session’s timezone → the offset was dropped, corrupting every value by the zone delta at any non-UTC session, and silently nulling at negative offsets (finding #24).
Each was fixed with a parser; the class remains: any session state that
shapes the rendering (timezone, DateStyle, bytea_output,
extra_float_digits) is a latent parity bug, discovered only when a
deployment’s session differs from the test stack’s.
pgoutput — the logical replication protocol’s native output plugin — emits
binary tuple data with per-column type OIDs, no session-dependent
rendering at all. The entire bug class is unrepresentable.
Why not now
pgoutputrequires the streaming replication protocol (START_REPLICATION, keepalive/feedback messages), not plain SQL polling. The syncpostgrescrate rivet uses does not speak it; the ecosystem crates for it were judged immature at the original design point, and the poll model (pg_logical_slot_peek_changes) deliberately reuses the existing dependency + the peek→flush→ack at-least-once seam.- It needs a
PUBLICATIONobject per captured table set — a new server-side resource with its own lifecycle (validation, doctor checks, drop-on-teardown). - The text-parse fixes above are live-pinned (full-type matrix, non-UTC session tests, hostile-value tests), so the remaining risk is bounded to renderings not yet enumerated, at session states not yet tested.
Decision
Migrate when ANY of these fires:
- A seventh text-rendering defect class surfaces (
DateStyle,bytea_output, locale-dependent anything) — i.e. the pin set proves insufficient again. - CDC throughput on a hot table becomes parse-bound (profile first: the text parse is per-cell; pgoutput decode is per-tuple binary).
- A maintained, audit-clean streaming-replication crate reaches maturity (re-evaluate every dependency-refresh cycle).
Migration shape: a second ChangeStream impl (PgOutputStream) behind the
same trait + the same commit/ack seam; test_decoding stays as the fallback
until the live matrix + non-UTC + hostile suites pass against both, then
becomes the compatibility path for one release before removal. The per-engine
anchor-model contract is unchanged — PG still pins server-side at slot creation
(the slot is still the anchor); the contract is documented in the
ensure_anchor doc comment (src/source/cdc/mod.rs).
Consequences
- Until migration, every new PG type mapping MUST add its
test_decodingrendering to the parser AND a matrix row (existing process rule). - The non-UTC session test (
pg_cdc_non_utc_database_timezone_matches_batch) is the canary for this ADR — it fails first if a new session-shaped rendering appears.
Amendment 2026-08-24: a SECOND text class — identity, not values
The six defects above are all about the rendering of a value. A hostile
verification pass found a distinct class the pin set never covered: the rendering
of an identity. test_decoding names relations as TEXT, and every routing
decision compares that text byte-exact, so the same hop corrupts which table a
change belongs to rather than what it contains.
Four measured this session, each a silent loss past an advancing slot:
- Partitioned parent.
test_decodingnames the PARTITION a row landed in. A config naming the logical parent captured 0 of 2 rows, reportedstatus: success, advanced the slot, and the corrected re-run recovered nothing (the WAL was already freed). - A folded twin. The schema probe interpolates the config into
SELECT * FROM {table}(PostgreSQL FOLDS it); the router compares byte-exact. With"MixedCase"andmixedcaseboth present, rows were written under the WRONG table’s schema — the real column absent entirely, exit 0. - A 3-part name.
to_regclassacceptsdb.schema.table;table_matchessplits on the first dot. Resolves, never routes. - TRUNCATE. Arrives as a line of prose naming a comma-separated LIST of relations, which had to be re-parsed (twice — the first fix anchored on the wrong separator and matched nothing).
pgoutput makes all four unrepresentable for the same structural reason the
value class disappears: it carries a relation OID plus a Relation message,
not a name to parse, and TRUNCATE is a typed message carrying an ARRAY of
relation OIDs rather than text. Partition identity is a publication-level
setting — publish_via_partition_root, which Debezium 3.2 exposes as
publish.via.partition.root — and it does not exist for test_decoding at all,
because publications are a pgoutput concept.
External corroboration worth recording: Debezium supports only decoderbufs
and pgoutput — test_decoding is not a supported plugin, and PostgreSQL’s
own docs call it “meant for testing that replication works rather than for
building robust production apps”. The guards this session added are the correct
minimum FOR test_decoding (they turn each silent loss into a loud refusal),
but each is a parser standing in for a mechanism the protocol would provide.
Effect on the decision
Trigger 1 is widened: it now fires on a seventh text-rendering defect class or
a text-IDENTITY defect class. The identity class has now fired — four
instances in one day — so by the ADR’s own terms this is no longer “not
scheduled” but a candidate whose gate has been met. The blockers in “Why not
now” (the sync postgres crate does not speak streaming replication; a
PUBLICATION is a new server-side resource with its own lifecycle) are unchanged
and still real; what has changed is the cost of NOT migrating, which is now
measured rather than projected.
Recommended next step, and deliberately scoped smaller than the migration: a
spike that answers (a) which streaming-replication crate is audit-clean today,
and (b) whether a PUBLICATION can be made optional — capture without DDL rights
was the original reason for this plugin, and if pgoutput cannot preserve it,
the migration is a dual-mode adapter rather than a replacement.
What the rest of the ecosystem does (surveyed 2026-08-24)
Checked because “are we reinventing the wheel” is the right question to ask before building the seventh parser. Answer: on the plugin choice, yes.
- Debezium supports
decoderbufsandpgoutputonly.test_decodingis not a supported plugin at all. - PeerDB takes the parent table name and nothing else — “you don’t need to
specify the names of each partition” — via a publication with
publish_via_partition_root(PG 13-16; on PG 12, a publication FOR ALL TABLES). - Sequin’s plugin guide states test_decoding’s “output format is not designed for production parsing” and calls it “mainly useful for understanding how logical decoding works or for quick debugging”.
- PostgreSQL’s own docs: “meant for testing that replication works rather than for building robust production apps”.
Two design answers worth stealing regardless of which way this ADR goes:
- TRUNCATE is a MODE, not a verdict. Debezium’s
truncate.handling.modedefaults toskipand can be set toinclude. rivet now REFUSES, which is right for a file/warehouse sink (there is no consumer to interpret a truncate event, and the divergence is permanent) — but it is a stricter answer than the ecosystem’s, and the difference should be a documented choice rather than an accident of what we happened to implement. - Partition drop is documented, not detected. PeerDB explicitly does NOT
propagate a dropped partition: “we don’t delete data matching that partition.”
That is the same class as the
SWITCH PARTITIONfinding this session left open on SQL Server — rows leaving the source with no events. The mature answer is a stated contract, not a detector, and our ledger should record it that way rather than carrying it as an unfilled gap forever.
ADR-0025: The CDC paged refill loop stays inlined per adapter
Status: Accepted Date: 2026-07-06
Context
After the 0.16.7 bounded-peek fix, the two poll-model CDC adapters —
source::postgres::cdc::PgChangeStream and source::mssql::cdc::MssqlChangeStream
— carry a byte-for-byte identical next_change():
#![allow(unused)]
fn main() {
while self.pending.is_empty() && !self.exhausted {
if let Err(e) = self.fill() { return Some(Err(e)); }
}
self.pending.pop_front().map(Ok)
}plus the same supporting state: pending: VecDeque<ChangeEvent>, exhausted: bool,
and a batch_limit clamped from the peek bound. Only fill() is genuinely
per-engine (PostgreSQL frames transactions + frontier-dedups a non-consuming
peek; SQL Server windows the change table by LSN and advances an internal
cursor). MySQL is the odd one out — it blocks on the binlog rather than paging,
so it shares none of this skeleton.
An architecture pass flags this as an un-extracted “polled paged stream” seam and
proposes a shared driver — e.g. a PolledPagedStream { fill(&mut self) } the two
adapters delegate to, or a ChangeStream default method.
Decision
Keep the loop inlined in each adapter. Do not extract a shared paged-stream driver.
Consequences
- A
ChangeStreamdefault method is wrong: MySQL (blocking binlog) and MongoDB (tailable change stream) implementChangeStreambut do not page, so a shared defaultnext_changewould be incorrect for two of the four adapters (2-of-4, not 4-of-4). PG and MSSQL remain the only poll-paged pair. - A free-function / wrapper extraction fights the borrow checker. The loop must
hold
&mut self.pendingand callself.fill()(also&mut self) — a borrow conflict. The only way through is an accessor trait (fn pending(&mut self) -> &mut VecDeque; fn exhausted(&self) -> bool; fn fill(&mut self)) with a blanketnext_change— which is more boilerplate than the five lines and three fields it removes, and pushes three trivial accessors into the interface of both adapters. - Deletion test: extracting the loop concentrates one identical five-liner. The win is small (locality, not leverage) and the abstraction’s cost exceeds it.
- The one thing worth encoding — that the PostgreSQL peek must be ≥ the part
rollover or it starves — is captured instead by
PeekBound(the sink buildsPeekBound::Sized(rollover), NDJSON isPeekBound::Unbounded), so a peek that undershoots the rollover is unrepresentable. That is the real correctness seam; the refill loop’s duplication is not.
If a fourth poll adapter appears, or the two fill() bodies converge, reopen this.
Amendment (2026-07-17)
The consequence bullet above — “a peek that undershoots the rollover is
unrepresentable” — was falsified by the open-bound work:
pg_logical_slot_peek_changes’ upto_nchanges counts the BEGIN/COMMIT marker
rows too, so PeekBound::Sized(rollover) yielded fewer DATA rows than the
sink’s ack boundary per peek, the refill re-read the same window, and a bounded
run exhausted with the backlog only partially drained (RED:
roast_pg_until_current_open_bound_two_runs_lose_nothing — two runs captured
4 of ~600 ids at rollover 5).
PeekBound stays the correctness seam, carrying the sink’s ACK CADENCE (the
rollover) — one ack’s worth of WAL per peek.
Amendment (2026-07-19)
An ultracode review found the 2026-07-17 ×3 peek escalation only partly
closed the gap: it covered the captured-marker ratio (a single-row transaction
is 3 wire rows for 1 change) but NOT an uncaptured-table transaction or an
empty/DDL span, whose wire:capture ratio is unbounded — a span larger than the
escalated window still starved the slot and the run still exhausted before the
open bound (RED: roast_pg_cdc_reaches_open_bound_past_a_large_uncaptured_ transaction — a 200-row uncaptured transaction ahead of the captured backlog
made a run capture zero in-bound rows at rollover 5).
The real seam is the sink re-drain loop ([sink::run_to_files]), not the
peek budget: after each drain pass it flushes + acks the consumed span
(advancing a consume-on-read slot past uncaptured/empty WAL, whose commit
boundary is recorded before the routing filter), then re-peeks the fresh WAL
beyond it, until a pass yields nothing. So the ×3 escalation is REMOVED — the
peek is a flat 1× rollover (drain RSS back to O(rollover)) and the adapter’s
ack/release_empty_frontier clear exhausted so the next pass slides
forward. The decision this ADR records — no shared refill driver, the loop
inlined per adapter — still stands; the re-drain loop lives in the shared sink,
above the adapters, and non-PG engines (whose read cursor advances on its own)
fall straight through it.
Amendment 2026-08-27: the bounded drain’s boundary is approximate, and PostgreSQL can make it exact
PeekBound encodes the one thing this ADR found worth encoding — a peek that
undershoots the rollover starves. The bound that ends a until_current run is a
separate quantity and it is weaker than it reads.
On PostgreSQL the open-time snapshot is pg_current_wal_lsn(): the WAL head of
the whole database, which is not a position in this slot’s decoded stream. So
the boundary is approximate on both sides. It can sit past the last commit this
slot will ever decode — the run then waits for traffic that never routes to it,
which is the starvation class the sink’s re-drain loop had to be built for — and
it can be reached by WAL this slot never sees. Every fix so far made the drain
more persistent; none made the boundary exact.
Decision (proposed). Where the engine can write an ordered marker INTO the log the reader is already decoding, end the stream on that marker rather than on a head snapshot: write a run-unique nonce at open, stop when the nonce is decoded. The boundary then comes from the same ordering as the data instead of from a different counter. Where an engine has no such primitive, the open-time snapshot stays.
The per-engine honesty rule this ADR’s neighbours already carry applies without softening: each engine’s bound is probed by DISABLING it and observing whether termination actually depends on it, and one engine’s result is never generalized to another. That mistake has been made twice on this exact question.
Primary prior art. pg_logical_emit_message(transactional, prefix, content)
is a documented PostgreSQL function (9.6+) whose stated purpose is to place an
application-defined record into the WAL for logical-decoding consumers; a
non-transactional message is decoded in WAL order, which is the property the
bound needs. The general shape — write a marker, then use its position in the
log as the boundary — is the watermark technique from Netflix’s DBLog paper.
Sequencing. This lands AFTER the pgoutput migration (ADR-0031), not
before: the marker is decoded by the same reader that migration replaces, and
building it twice is the avoidable cost.
RED-proof before Accepted. A paced writer whose traffic does not route to
the captured table, running throughout the bounded run: the run terminates at
its marker rather than chasing the head. The mutant is the marker check replaced
by the head snapshot — the termination test goes RED while the two-run union
test (..._until_current_open_bound_two_runs_lose_nothing) stays green, since
the old behaviour deferred rather than dropped. A test that cannot tell those
two apart is measuring persistence, not the bound.
ADR-0026: First-party extension seam (amends ADR-0002)
Status: Accepted
Date: 2026-07
Amends: ADR-0002 — CLI Product vs Library
Context: A private, source-available companion crate — rivet-pro (BSL 1.1, separate repo) — now builds the paid tier (warehouse load, whole-database discovery, continuous CDC) on top of the OSS engine. It links the rivet library and depends on a small set of already-pub items. ADR-0002 declares the library “not a stable public API” and (Consequence #4 / Future library path) prescribes extracting a separate rivet-engine crate if a stable embedding surface is ever needed. This ADR decides what to do now that there is exactly one, first-party embedding consumer.
Decision
Name a minimal, stability-tracked first-party extension seam. Defer the full rivet-engine extraction until a non-first-party (external) consumer appears.
The seam is the exact set of library items rivet-pro depends on. It stays pub, and a change to the shape of any item below is a deliberate act: update rivet-pro in lockstep and record it in CHANGELOG.md under a Breaking (extension seam) line.
The seam (v0.16.x)
| Item | Path |
|---|---|
TypeMapping, RivetType, TimeUnit, TypeFidelity, SourceColumn | rivet::types |
ExportTarget (+ variants DuckDb/BigQuery/Snowflake/ClickHouse) | rivet::types::target |
ExportTarget::resolve_table(&[TypeMapping]) -> Vec<TargetColumnSpec> | rivet::types::target |
ExportTarget::resolve_column(TargetInput) -> TargetColumnSpec | rivet::types::target |
TargetColumnSpec, TargetInput, TargetStatus | rivet::types::target |
AdcUserTokenLoader, try_authorized_user_loader() | rivet::google_auth |
The ADC loader is on the seam for a reason worth stating: reqsign’s token
loader resolves service account → impersonated → external account → VM
metadata and has no authorized_user arm, so any native Google client
must supply one or it authenticates in CI and fails on a developer laptop.
rivet-pro wrote a second copy of this exchange before the seam existed, and
got three things wrong that this implementation had already learned — it
surfaced the token endpoint’s error body (Google echoes the submitted
client_id/client_secret back in some failure modes), it kept the secrets
in un-zeroed Strings, and it pinned an invented lifetime when expires_in
was absent. Exposing the loader is what makes “never hand-roll a second auth
path” true across BOTH repos instead of only inside this one.
The loader was WIDENED (0.24.x) to mint from a service_account key file too —
the RFC 7523 jwt-bearer grant, RS256-signed in process — so a consumer pointing
GOOGLE_APPLICATION_CREDENTIALS at a key file gets its token from this seam
rather than from a gcloud subprocess. The seam items are UNCHANGED
(AdcUserTokenLoader keeps its now-misleading name precisely because renaming
it to describe a widening would break a consumer for nothing); two additive
methods, credential_kind() and principal(), name the resolved identity for
logs. external_account / workload identity still returns Ok(None): it needs
an STS exchange rivet does not model, and a half-implemented subset would be
worse than the documented fallback.
Everything else in the library keeps the ADR-0002 posture: pub only for the test harness, no stability guarantee.
The CLI superset uses the process boundary, not a Rust API
rivet-pro ships a superset rivet binary (OSS subcommands + load/discover/daemon). It composes them at the argv/process boundary: unknown subcommands are delegated to the OSS rivet binary (already a stable product contract — config YAML + exit-code taxonomy + manifest). The cli module is deliberately binary-only (declared in main.rs, absent from lib.rs; its dispatch reaches crate::init, also binary-only). Pulling cli into the library to expose Commands/dispatch would violate ADR-0002’s minimal-library principle and freeze the entire command surface. We do not do that.
Rationale
- One consumer ≠ a public API. A full
rivet-engineextraction (separate crate, two manifests, re-export churn) is the right move for external consumers with independent release cadence. With a single first-party consumer we own both sides, so a named + tested subset delivers the stability guarantee at a fraction of the cost. - Smallest seam. Every
pubitem on the seam is a compatibility commitment. The list is exactly whatrivet-prouses today — resolution only.Destinationpromotion (a likely next seam) is deferred until a Pro feature needs it, then added here with the same discipline. - One-way dependency.
rivet-prodepends onrivet; the OSS tree must never depend onrivet-pro— otherwise the MIT binary can’t build without the private crate and paid code leaks into an MIT distribution.
Enforcement
- Seam-stability canary —
tests/offline/extension_seam.rscompile-locks every signature above. If it fails to build, an item on the seam changed: updaterivet-proand add theBreaking (extension seam)CHANGELOG line — do not just edit the test to compile. - Dependency-direction guard — the CI
boundaryjob fails ifsrc/orCargo.tomlreferencesrivet-pro/rivet_pro.
Consequences
- The seam table is the contract. Widen it only by adding a row here + a canary line, never silently.
rivet-pro’s own CI (dual-checkout, builds against OSSmain) is a second, cross-repo canary.- Trigger to revisit: the day a second, external consumer wants to embed the engine, extract
rivet-engineper ADR-0002’s Future library path and move this seam into its semver’d surface.
ADR-0027: A structured read-relation on the export request seam
Status: Accepted Date: 2026-07 Relates to: ADR-0011 (Source trait), ADR-0020 (catalog-hint query)
Context
Source::export receives an ExportRequest whose query is an
already-materialized SQL string (resolve_query turns a table: orders
shortcut into SELECT * FROM orders). This is the right currency for the three
SQL engines. It is the wrong currency for a document store: MongoDB has no
SQL, so the Mongo adapter was forced to un-parse the SQL back into intent —
collection_from_query stripped SELECT * FROM to recover the collection
name, reinventing what sql::strip_select_star_from already does for the
PostgreSQL catalog-hint path (ADR-0020). The reconcile count added a second
un-parser (last_from_identifier) for SELECT COUNT(*) FROM (SELECT * FROM <coll>) …. Intent → serialise to SQL → parse SQL back to intent, in two places.
The architecture review flagged this (candidate A): the seam leaks “SQL is the universal read currency”, and every non-SQL adapter pays to undo it.
Decision
Carry the bare source relation structurally on ExportRequest, alongside the
SQL string — additive, not a replacement.
ExportRequest gains base_relation: Option<&str> — the [schema.]table
identifier when the export is a table: shortcut, None for a hand-written
query: or any filtered/wrapped form. It is computed once, inside the
unwrapped/wrapped constructors, via the existing
sql::strip_select_star_from — so every runner populates it for free with no
call-site churn.
- SQL engines ignore
base_relationand runqueryexactly as before — zero behavioural change, zero risk. - The document adapter reads
request.base_relationdirectly: aSomeis the collection to scan; aNoneis an actionable “MongoDB needs atable:shortcut” error.collection_from_queryis deleted.
Rationale
- Delete a reinvention.
collection_from_queryduplicatedstrip_select_star_from. The relation is now extracted once, by the shared helper, at request construction — not re-derived per non-SQL adapter. - Additive = low-risk. No SQL-engine signature or behaviour changes; the new field is optional and SQL engines never read it. This is deliberately not the full “reshape the seam” refactor — that would touch all three engines for a larger, riskier change. We take the honest slice that removes the batch-path un-parser now.
- One consumer today, real seam tomorrow. MongoDB is the first non-SQL
adapter;
base_relationis the seam the next one (or Mongo CDC’s schema resolve, which also buildsSELECT * FROM {table}) reads instead of parsing.
Consequences
- The reconcile row count still un-parses SQL (
last_from_identifier), becauseSource::query_scalarreceives a bare SQL string with no structured counterpart. Giving the reconcile count a typed request is the remaining tail of this ADR — deferred until it earns its churn (it touches thequery_scalarseam across all engines). base_relationis populated for SQL engines too. A future step could let the PostgreSQL catalog-hint path read it instead of re-parsingcatalog_hint_query— folding another SQL un-parse into the same seam. Not done here.