Last updated: 2026-07-09.
Concepts
A one-page glossary of the terms Rivet uses everywhere — run_id, cursor, chunk, manifest, journal, progression. Read it once, then come back when a doc / CLI output references a term you’ve forgotten.
If you want the binding execution semantics (what’s at-least-once, what survives a crash, what doesn’t), see semantics.md. This page is the orientation; that one is the contract.
Two top-level objects
| Term | What it is | Where it lives | How to see it |
|---|---|---|---|
| Export | A named entry in rivet.yaml — a query + cursor / chunk strategy + destination triple. One config file can have many exports. | exports[]: array in the YAML. | rivet check lists them; rivet plan resolves them; rivet run extracts them. |
| Run | One invocation of rivet run. Produces zero or more files per export. Has a unique run_id. A single run can extract one or many exports. | The state DB (run_journal, export_metrics) + the per-run report artifacts .rivet/runs/<run_id>/summary.{json,md}. | rivet metrics --last N · rivet journal --export NAME. |
The same export can be extracted by many runs over time. Each run gets its own run_id; the export’s cumulative state (cursor, chunks done, files written) accretes across runs.
How the data is sliced
| Term | What it is | Used by |
|---|---|---|
| Mode | The extraction strategy: full (re-export everything), incremental (only rows newer than the last cursor), chunked (split a big table into N range chunks), time_window (rolling N-day window), cdc (change data capture — inserts/updates/deletes captured to Parquet/CSV files from the source’s replication log, resuming from the last committed log position each run). | One per export. See modes/. |
| Batch | One FETCH worth of rows materialised as an Arrow RecordBatch. Streamed and discarded — never accumulated in memory. Controlled by tuning.batch_size (rows) or tuning.batch_size_memory_mb (memory budget). | Every mode. The batch_size setting is what protects your source DB from a single huge fetch. |
| Chunk | A row-range slice of a chunked export (e.g. id BETWEEN 0 AND 50000). Each chunk runs as its own SQL SELECT and produces its own output file. Has a checkpoint row in the state DB so a crashed chunked run can --resume without re-exporting completed chunks. | Only mode: chunked. |
| Cursor | The last extracted value for incremental exports (a number, timestamp, or composite tuple). Next run starts from > cursor. | Only mode: incremental and the after-the-fact cursor recorded by mode: chunked runs. |
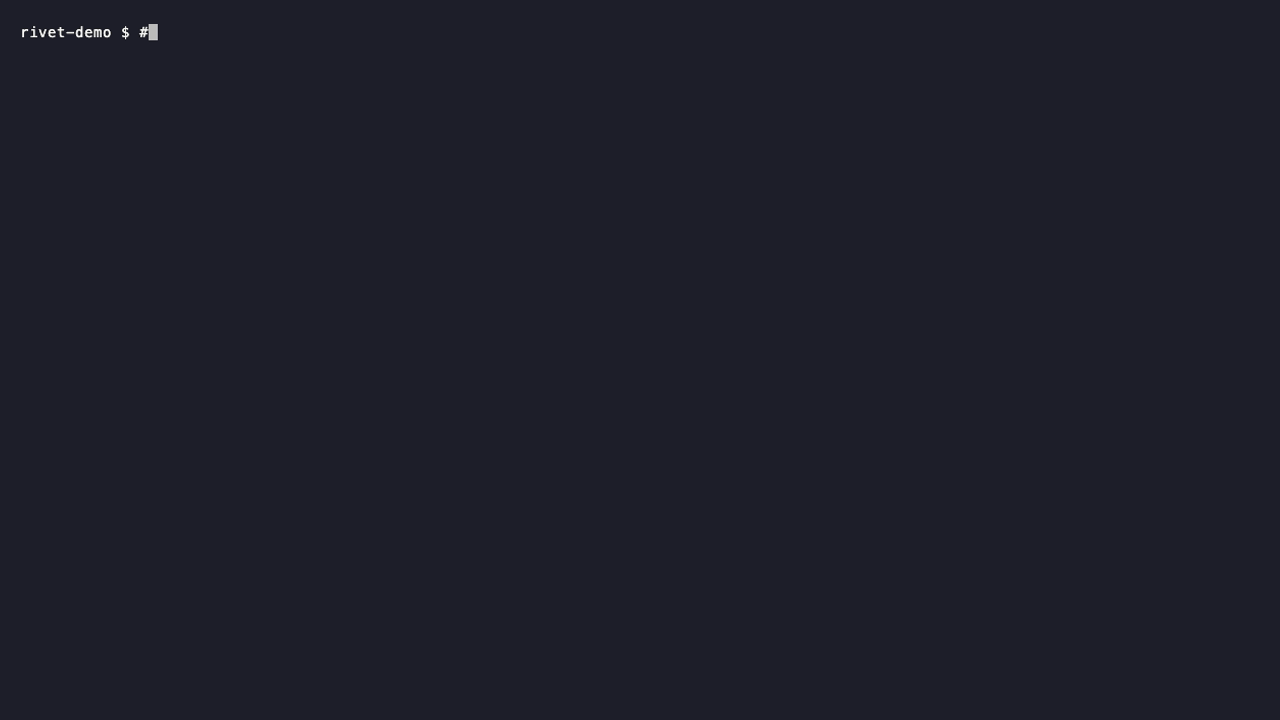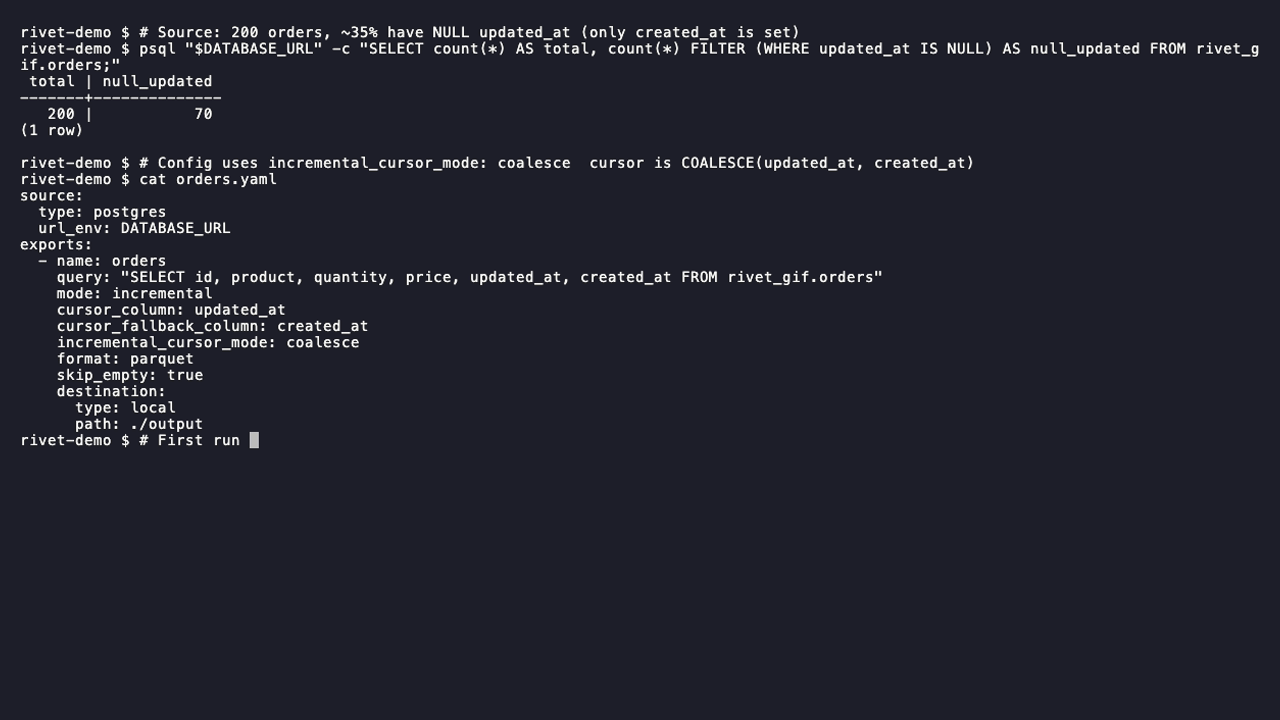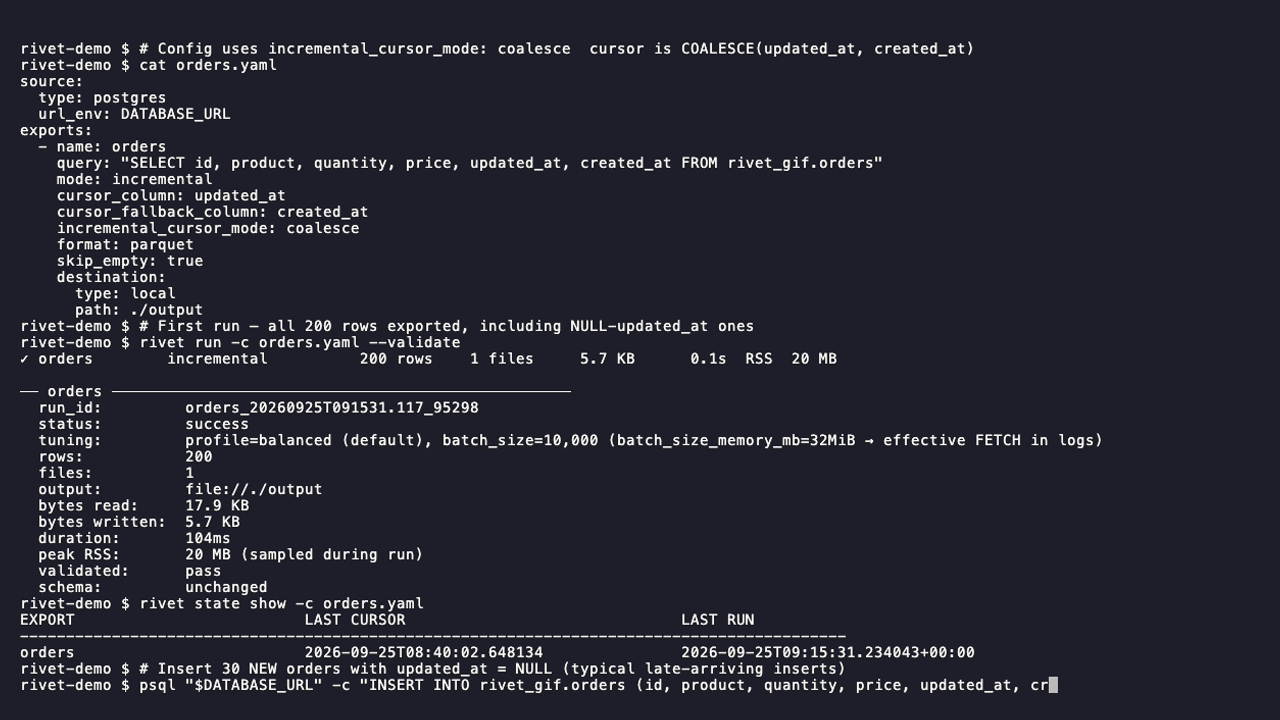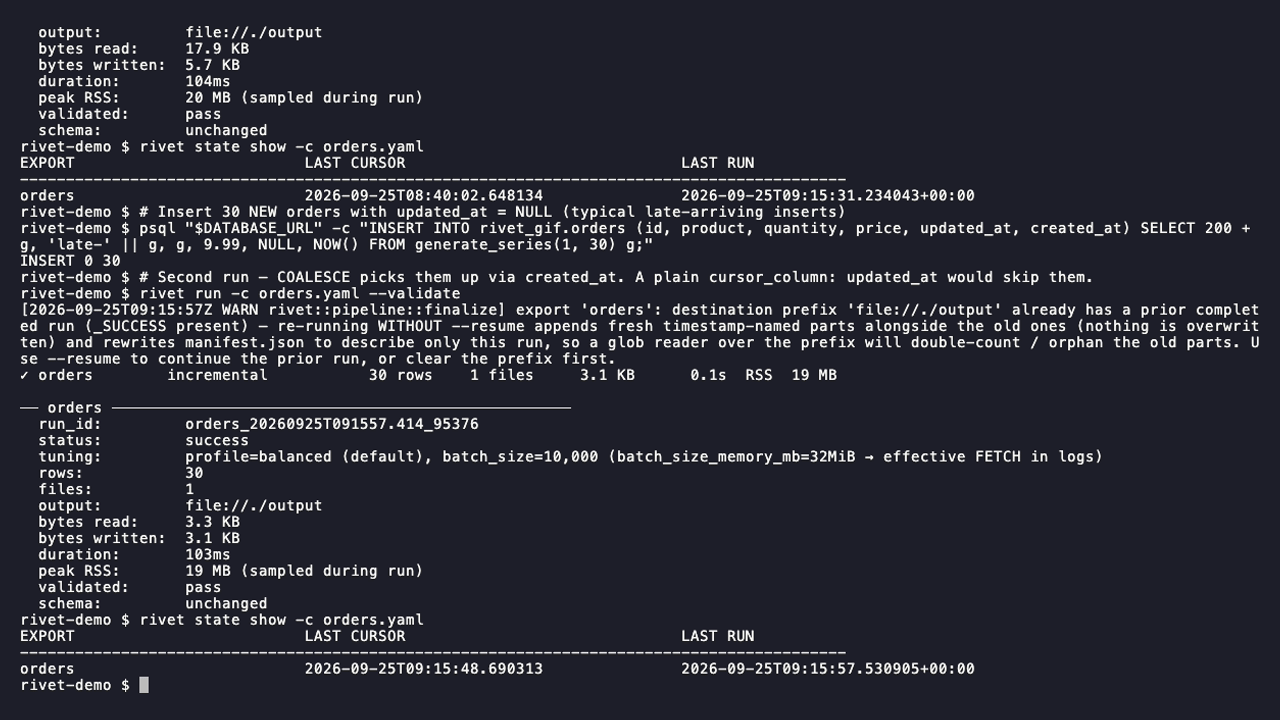
| Composite cursor | A COALESCE(primary, fallback) cursor — for tables where the primary column (e.g. updated_at) is nullable for some rows and a fallback (e.g. created_at) carries those rows forward. Stored as a single scalar; demoed in coalesce-cursor.gif; contract in ADR-0007. | Set incremental_cursor_mode: coalesce + cursor_fallback_column. See modes/incremental-coalesce.md. |
What’s recorded after each run
| Term | What it is | Table in .rivet_state.db | CLI |
|---|---|---|---|
| File log | The per-export ledger of files actually written — file name, row count, bytes, format, compression. Authoritative answer to “what files did this export produce?” Renamed from file_manifest in schema v8; the Manifest term now names the per-output-prefix manifest.json cloud-output contract that ships today (written alongside _SUCCESS in each destination prefix; carries per-part content_fingerprint for idempotent downstream loads). | file_log | rivet state files --export NAME |
| Metrics | One row per run per export — run_id, status, rows, bytes, duration, peak RSS, retries, validation / reconcile result. Authoritative answer to “how did this export perform over time?” | export_metrics | rivet metrics --export NAME --last N |
| Journal | Per-run event stream — every chunk start / complete / fail, every retry, every quality-gate decision, the first-line error text. Authoritative answer to “what happened during this specific run?” | run_journal table (one JSON document per run in the state DB) | rivet journal -c rivet.yaml --export NAME --run-id ID |
| Progression | The committed / verified boundary per export — for chunked, the highest contiguous chunk index that fully succeeded; for incremental, the high-water cursor value that has been reconciled. Advisory only (operator-readable; nothing in the pipeline depends on it). | export_progression | rivet state progression |
| Chunk checkpoint | Per-chunk row in the state DB tracking status (pending · running · completed · failed), attempt count, and first-line error. Only populated when chunk_checkpoint: true is set. | chunk_run + chunk_task | rivet state chunks --export NAME |
The decisive write order across these (which write happens before which) is the State Update Invariants in ADR-0001 — the I1-I7 sequence. The user-facing summary of “what happens if the process dies between I3 and I4” is in semantics.md § Crash semantics.
Two flags that are easy to confuse
| Flag | What it does | Cost |
|---|---|---|
--validate | Reads the output Parquet / CSV file back from disk after writing it. Asserts the row count in the file equals the row count Rivet thought it wrote. Catches silent writer bugs and partial writes. | One extra pass over the just-written file. Cheap. |
--reconcile | Runs SELECT COUNT(*) against the source query and compares with the total row count exported. Catches discrepancies between “what the cursor / chunk loop saw” and “what the source actually has”. | One extra COUNT(*) query per export. On a multi-million-row table this can take longer than the export itself. Worth it for first runs and weekly audits. |
Both are off by default; both add one line to the run summary. For chunked exports the dedicated per-partition reconcile + targeted repair workflow lives in rivet reconcile / rivet repair — see reference/cli.md § rivet reconcile and ADR-0009. The CLI flag --reconcile is the cheaper aggregate-only version.
Plan / apply (auditable execution)
| Term | What it is |
|---|---|
| Plan artifact | A sealed JSON document produced by rivet plan. Captures the resolved config, query fingerprints, preflight diagnostics, computed chunk boundaries, and cursor snapshots at planning time. Plaintext password: and scheme://user:pass@ userinfo are stripped at write time (ADR-0005 PA9); env / file references are preserved so the apply environment can re-resolve them. |
| Apply | rivet apply plan.json executes exactly the pre-computed plan. Refuses to run if the config has changed, if the cursor has advanced since plan time, or if the plan is older than 24 h (without --force). Designed for CI/CD review-then-execute workflows. |
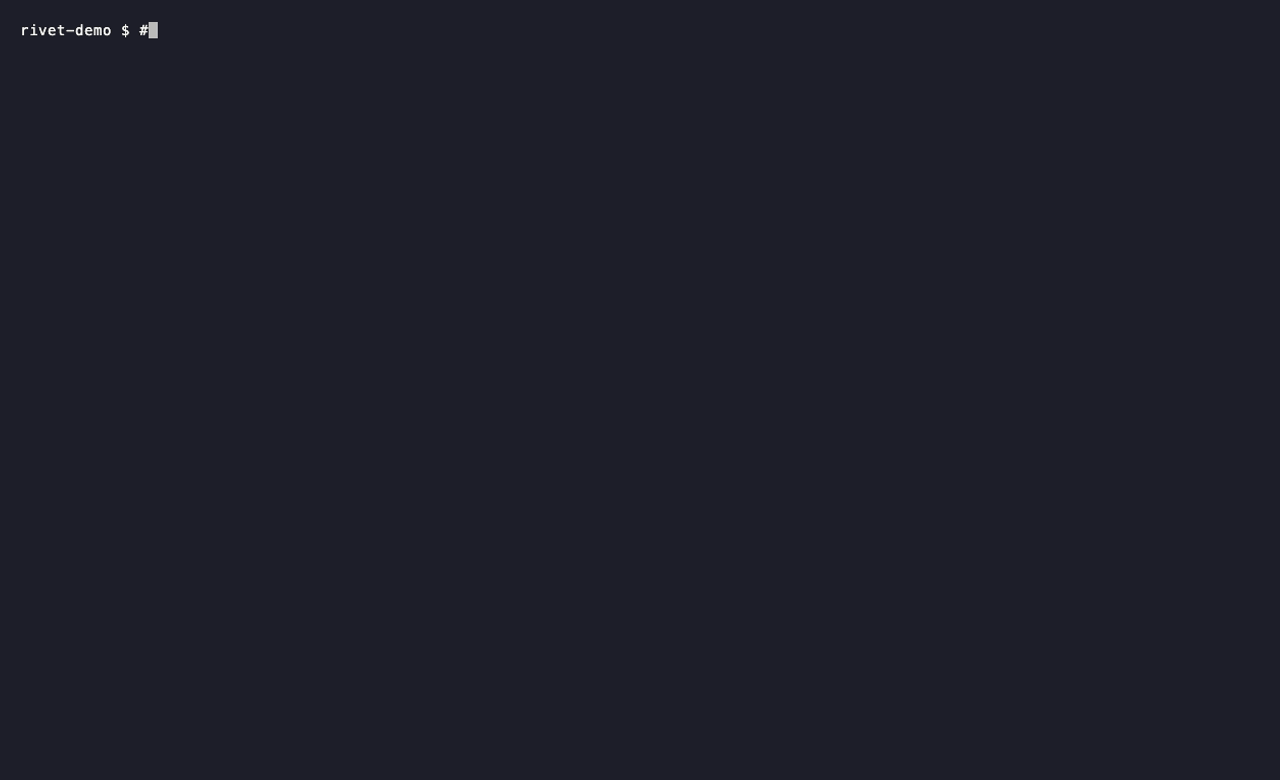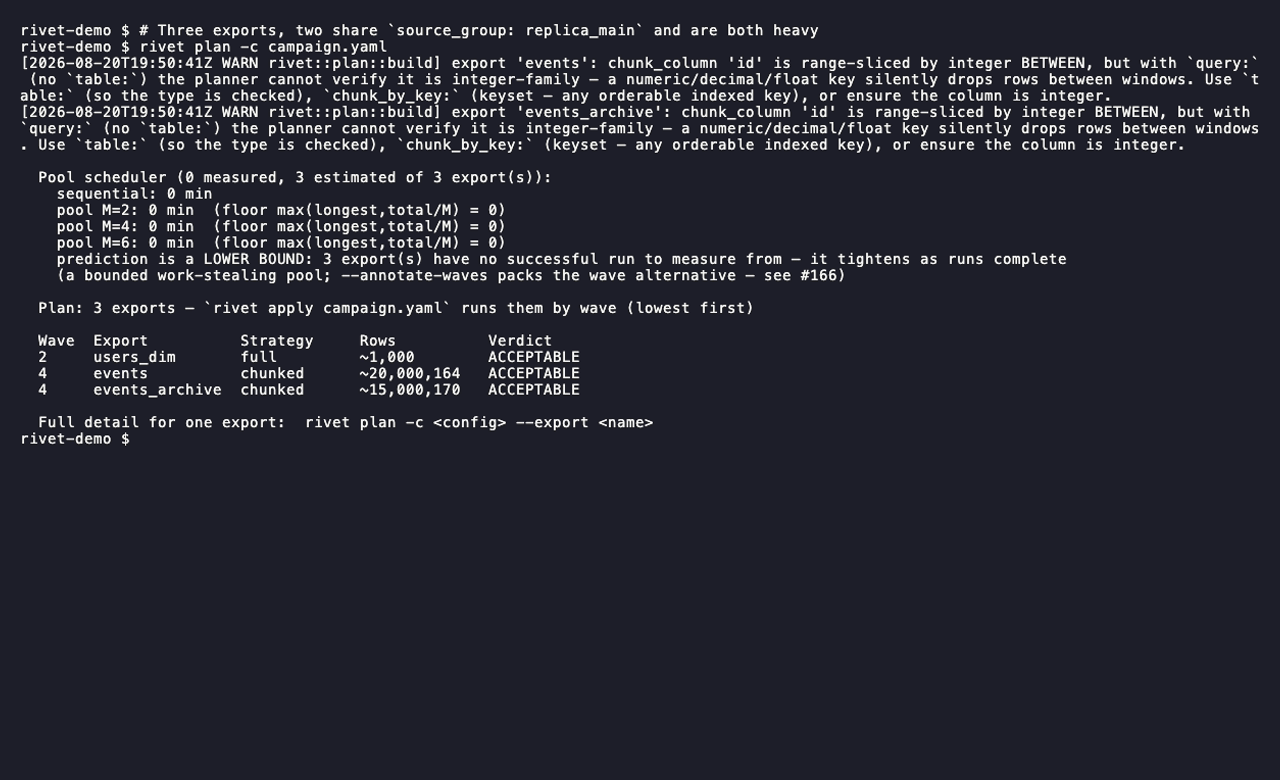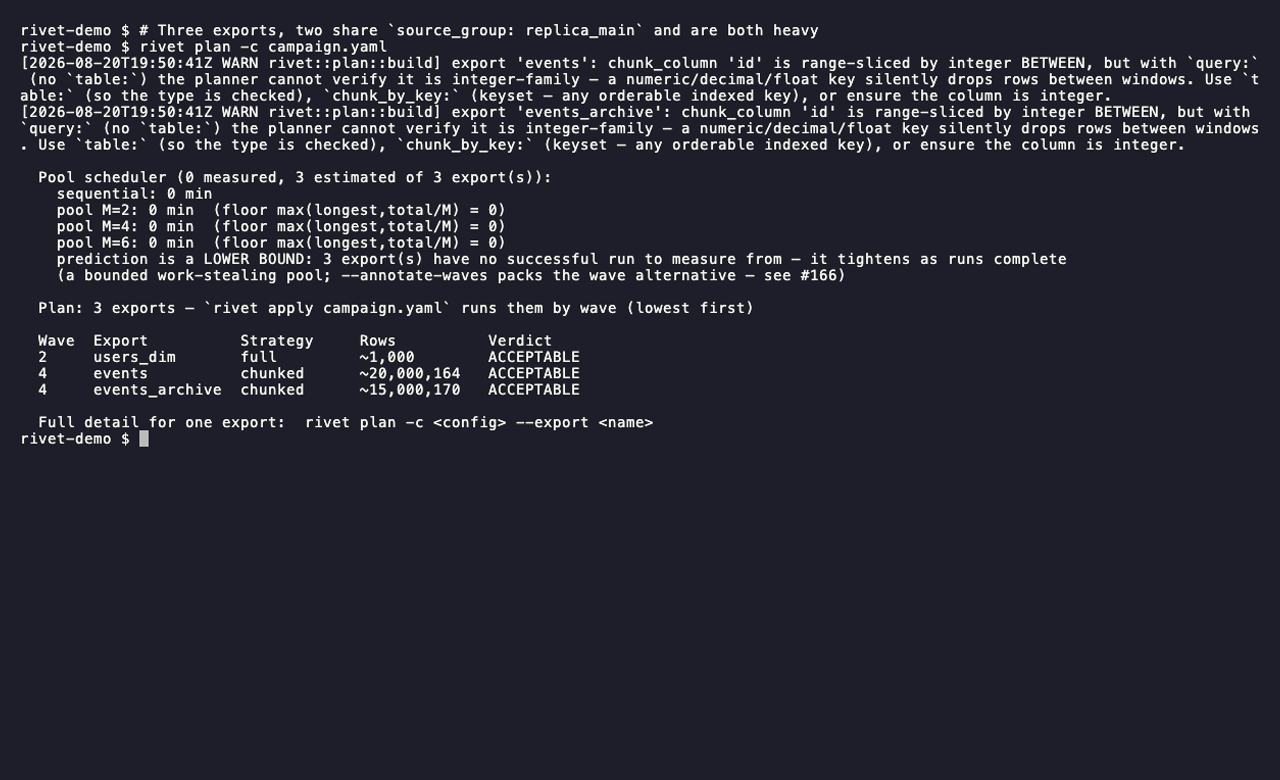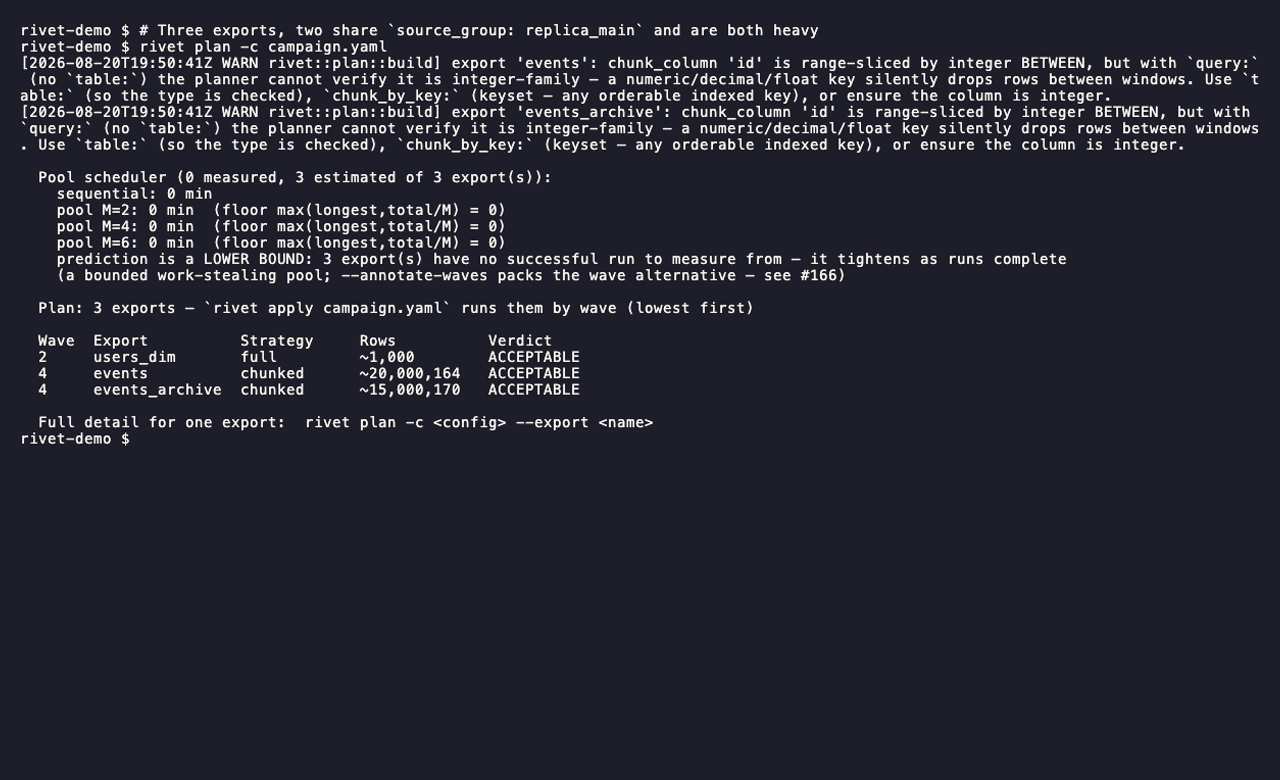
| Campaign / waves | When rivet plan is run on a multi-export config, the artifact embeds a CampaignRecommendation — exports sorted by an advisory priority score, grouped into execution waves, plus source_group warnings when several heavy exports share a replica (e.g. isolate_on_source: true). The priority score and grouping are advisory (ADR-0006), but Rivet can execute the waves itself: rivet apply <config>.yaml runs the exports wave-by-wave in ascending wave: order (optionally with --parallel-export-processes and --resume), or — with --pool N (optionally --split) — as a wave-less work-stealing pool (longest-first LPT scheduling) that replaces the wave barriers entirely and does not honor wave: tiers; an external scheduler (Airflow / cron / GH Actions) is optional. Demoed in plan-campaign.gif. |
You can stick with rivet run for everything; plan/apply is only there when you want a pre-execution review object that survives in a PR or a CI artifact.
Source-aware connections
| Term | What it is |
|---|---|
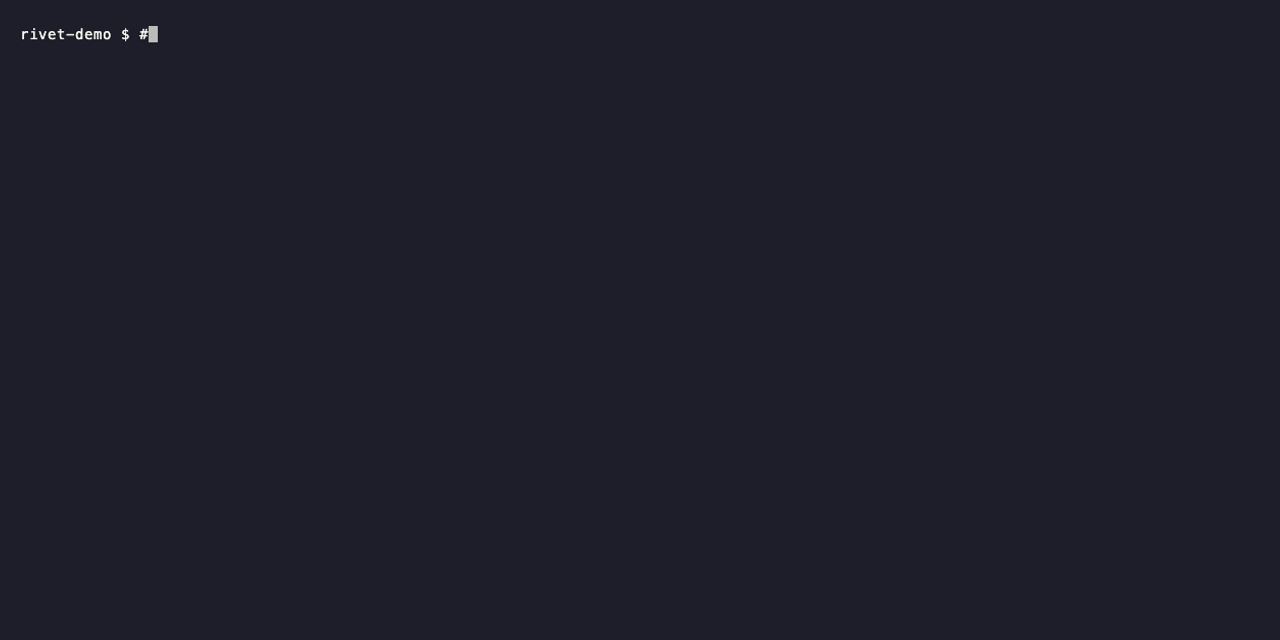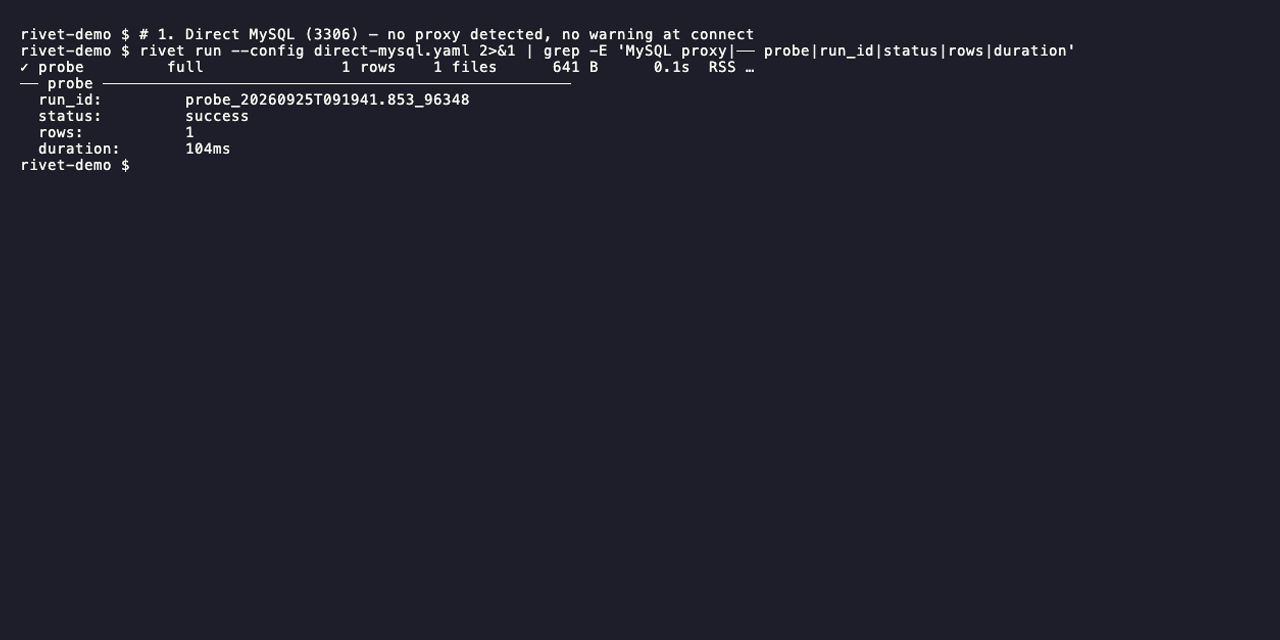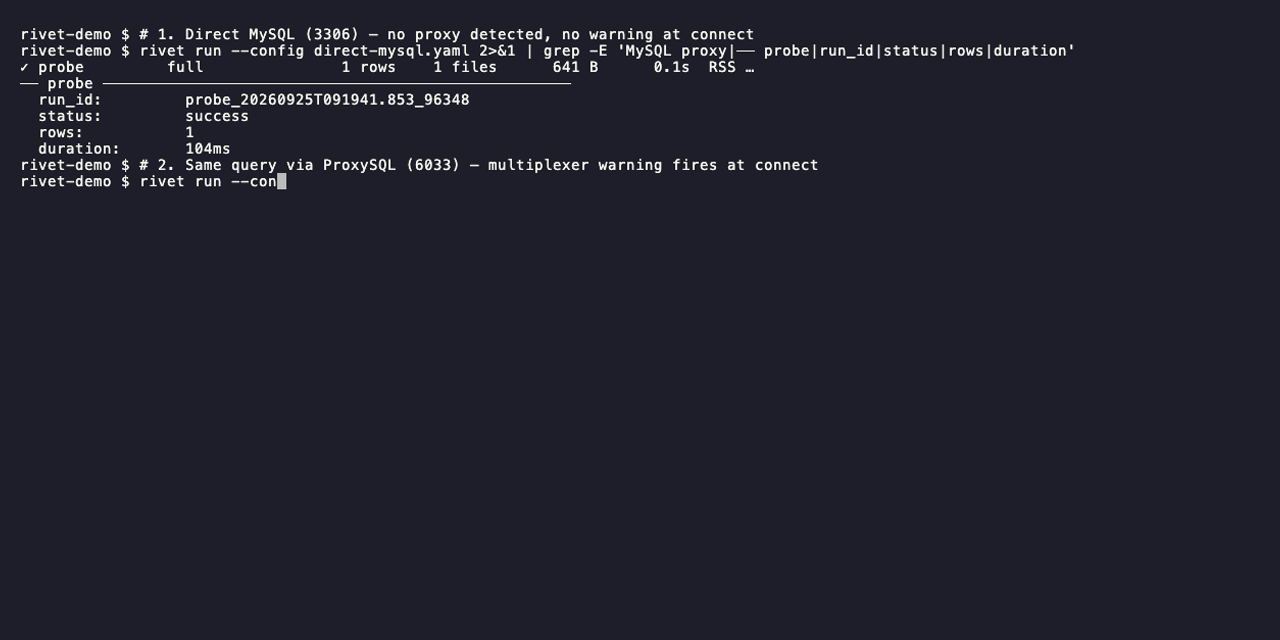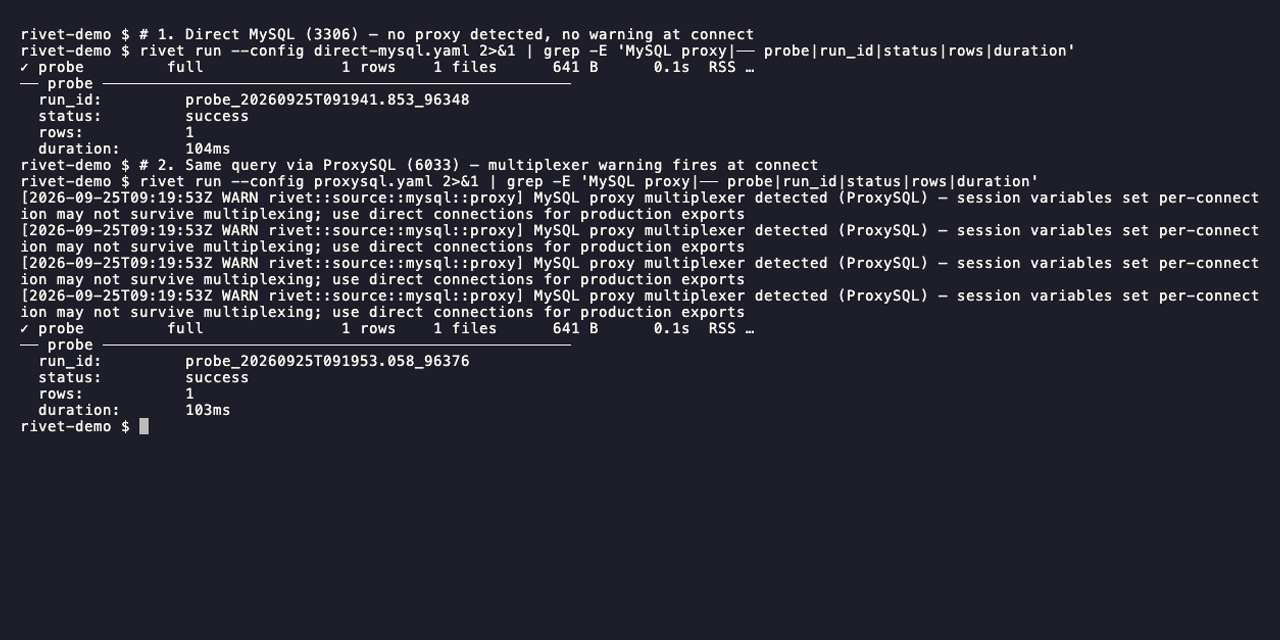
| Pool detector | At connect time Rivet probes for connection pooling and warns about subtle failure modes. PG: a PID-flip probe (pg_backend_pid() twice) flags pgBouncer / Odyssey in transaction mode — LISTEN/NOTIFY and advisory locks won’t survive. MySQL: a 4-signal classifier (PROXYSQL INTERNAL SESSION accepted · @@version_comment banner · @@proxy_version presence · CONNECTION_ID() drift) distinguishes Direct / ProxySql / MaxScale / Multiplexed. SQL Server: @@SPID drift across two consecutive queries on one connection flags a transaction-mode multiplexer (Multiplexed); SERVERPROPERTY('EngineEdition') of 5 / 8 (or an Azure @@VERSION banner) flags the AzureGateway fronting Azure SQL DB / Managed Instance. All Postgres tuning uses SET LOCAL inside an RAII-guarded BEGIN…COMMIT so session state is never leaked into the pool. Demo: pool-detect.gif. |
| MCP server | A separate binary, rivet-mcp, that speaks Model Context Protocol over stdin/stdout. Exposes read-only DB introspection tools (pg_stat_activity, checkpoint pressure, pg_stat_statements I/O, MySQL processlist, pgBouncer diagnostics) to MCP clients like Claude Desktop and Claude Code. Read-only — no DDL, no writes. Source: src/bin/rivet-mcp.rs + src/mcp.rs. |
Where each concept is exercised in the code
If you want to track a concept from this glossary back to the implementation:
Sourcetrait +ExportRequest—src/source/mod.rs- Cursor / incremental —
src/source/query.rs(predicate builder) +src/state/cursor.rs - Chunked / checkpoint —
src/pipeline/chunked/{mod, sequential_checkpoint, parallel_checkpoint}.rs+src/state/checkpoint.rs - File log + Metrics —
src/state/{file_log, metrics}.rs - Journal —
src/journal.rs(top-level) +src/state/journal_store.rs - Progression —
src/state/progression.rs(ADR-0008) - Validate / reconcile (CLI) —
src/pipeline/{validate, reconcile_cmd}.rs - Plan / apply —
src/pipeline/{plan_cmd, apply_cmd}.rs+src/plan/
Where to go next
- getting-started.md — the 5-minute install + first export, if you skipped it
- semantics.md — the binding execution contract (what’s at-least-once, what survives crashes)
- modes/ — when to pick
fullvsincrementalvschunkedvstime_windowvscdc - adr/ — every contract in this glossary has a numbered ADR with the rationale